The chipseq template follows a standard nf-core/chipseq run from reads to a consensus peak set per antibody:
- Overview: the run in four key figures, live findings and four figures, each linked to the tab that explains it
- Data & QC: the MultiQC report, with the enrichment panels that say whether a ChIP worked, then the deepTools and Picard (or preseq) tables behind those curves
- Peak calls: MACS3 peaks per library, where HOMER places them relative to genes, and one genomic region across libraries
- Comparison: one consensus peak set per antibody, which libraries agree on an interval, and where they sit on the DESeq2 QC of its counts
One MultiQC parquet per run, in one of two places
The 2.1.0 release pins MultiQC 1.23, which writes no parquet, and Depictio
reads only multiqc.parquet (MultiQC 1.31 and later). The template therefore
accepts it in two places, and a tree must hold exactly one:
multiqc/<narrow_peak|broad_peak>/multiqc_data/multiqc.parquet, written by the
run itself when a parquet-era MultiQC is swapped in, and
multiqc/multiqc_data/multiqc.parquet, written by the reprocess step over a
1.23 run:
The tiles are bound to the report the pipeline writes with its own
multiqc_config, which files a tool under several module ids
(samtools-1 for the merged unfiltered libraries, mlib_deeptools for the
fingerprint). A reprocessed report merges each tool under one id: on it the
import drops the percent-mapped tile, and the fingerprint is read from its
twin tile on deepTools, which holds the same slot.
Narrow or broad, both read
recipes/peaks.py reads whichever of *_peaks.narrowPeak and
*_peaks.broadPeak the run wrote, with the matching catalog reader. A broad
region has no summit, so its centre stands in for one and every tile bound to
summit keeps working. No glob names an aligner either, so bwa, bowtie2,
chromap and STAR runs land in the same collections.
No DESeq2 differential binding
nf-core/chipseq 2.0.0 removed the differential binding analysis, so this template has no Differential binding tab. What the pipeline still runs is a DESeq2 sample QC on the consensus counts of each antibody, its PCA and its sample distances, and the Consensus tab reads both in its Sample space section.
Quick start
The results directory is the only thing you have to pass. The hub of the dashboard is
the samplesheet the run validated, pipeline_info/samplesheet.valid.csv,
which a template-local recipe collapses into one row per merged library (the
ChIPs and their input controls alike) with its antibody, replicate, role and
condition. Three variables are optional: --var METADATA_FILE=<table> for a
design table whose GROUP_COL becomes the condition (the sample group
otherwise), --var PRESEQ_RAN=true for a run made with --skip_preseq false,
and --var GENOME=<assembly> for a run on a UCSC assembly.
depictio config nextflow --install     # once per machine
nextflow run nf-core/chipseq -profile docker --outdir results
No depictio ingest, and no template named: the pipeline ingests its own
output directory when it finishes and resolves this template from its own
manifest. See Nextflow trigger.
Reference
The template reads the validated samplesheet, the MultiQC report, the deepTools
fingerprint and profile tables, the Picard MarkDuplicates metrics, the MACS3 peak
calls and their HOMER annotation, the per-antibody consensus matrices and the
DESeq2 QC tables, plus an optional design table. 58 of its 106 components carry a
use: catalog reference, so a tile says where its panel comes from.
The CLI sets no variable from chipseq's params.json, so the route flag is passed
by hand: a run made with --skip_preseq false needs --var PRESEQ_RAN=true. The
preseq card and filter then take the slots the Picard duplication card and filter
hold on the Signal tab; without the variable both cards are kept and the strip
wraps to a second row. GENOME is empty by default, which lays the Locus axis out
from the contigs the calls carry and suits any reference, a custom FASTA
included.
Self-adapting layout
The dashboard adapts to whatever the run actually produced: components bound to pruned or unparsed data collections are hidden, tabs left with no real visualizations are dropped entirely, and the remaining components are re-packed so there are no empty rows.
Template variables
Variables you provide when running the template: DATA_ROOT is the results directory given to depictio ingest, the others are set with --var NAME=value:
| Variable | Required | Description |
|---|---|---|
DATA_ROOT |
✓ | The chipseq --outdir (one directory per aligner, fastqc/, trimgalore/, multiqc/, pipeline_info/), with the MultiQC parquet under multiqc/narrow_peak/multiqc_data/ or multiqc/broad_peak/multiqc_data/, or multiqc/multiqc_data/ for a reprocessed run. |
METADATA_FILE |
— | Optional design table (TSV): merged-library id (or sample group) in METADATA_ID_COL, one column per factor. GROUP_COL becomes the condition column of the design hub; the other factors are carried as extra columns. |
METADATA_ID_COL |
— | Design table id column. Auto-detected as the first column. |
GROUP_COL |
— | Design table factor the run compares, carried as the condition column. Auto-detected as the first factor column of METADATA_FILE. |
GENOME |
— | UCSC assembly the run was aligned to (hg38, hg19, mm10, ...). Sets the genome axis of the Locus tab from that assembly; left empty, the axis is built from the contigs of the peak calls, which suits any reference. |
PRESEQ_RAN |
— | Set to true for a run made with --skip_preseq false. The Signal tab then counts distinct fragments with preseq instead of reading the Picard duplication rate in the same slot. |
Auto-detected (set from the run's metadata / params.json; the route flags drive Conditional routes below): GROUP_COL_DISPLAY, ANNOTATION_COLS
Data collections
19 data collections — 14 required 5 optional · 13 direct 6 derived.
Origin tells you whether a collection is real pipeline data or a reshape of it: direct = a pipeline output (scanned, or a recipe that reads raw files); derived = a recipe that reshapes one or more direct collections into the layout a visualization needs (no new measurement). Reads shows what produces it: a recipe .py transform, whose name links to its source on GitHub, or a raw file scanned off disk. (A direct collection can still have a recipe — one that merely parses/cleans the raw file; derived means the recipe reshapes another collection.)
| Tag | Origin | Type | Reads | Status |
|---|---|---|---|---|
metadata |
direct | Table | file {METADATA_FILE} |
optional |
design |
derived | Table | recipe nf-core/chipseq/design_factors.py |
required |
samplesheet |
direct | Table | file samplesheet.valid.csv$ |
required |
multiqc_data |
direct |  MultiQC |
file (?:.*/)?multiqc(?:/[^/]+)?/multiqc_data/multiqc.parquet$ |
required |
preseq_ccurve_raw |
direct | Table | file .*.lc_extrap.txt$ |
optional |
preseq_complexity_curve |
derived | Table | recipe preseq/complexity_curve.py |
optional |
deeptools_fingerprint_metrics |
direct | Table | recipe deeptools/fingerprint_metrics.py |
required |
deeptools_plot_profile |
direct | Table | recipe deeptools/plot_profile.py |
required |
picard_markduplicates_metrics_raw |
direct | Table | file .*.MarkDuplicates.metrics.txt$ |
required |
picard_markduplicates_metrics |
derived | Table | recipe picard/markduplicates_metrics.py |
required |
macs2_peaks |
direct | Table | recipe nf-core/chipseq/peaks.py |
required |
macs2_peak_summary |
direct | Table | recipe macs2/peak_summary.py |
required |
homer_annotated_peaks |
direct | Table | recipe homer/annotate_peaks.py |
required |
homer_tss_distance_profile |
derived | Table | recipe homer/tss_distance_profile.py |
required |
macs2_summit_profile |
derived | Table | recipe macs2/summit_profile.py |
required |
macs2_consensus_boolean |
direct | Table | recipe macs2/consensus_boolean.py |
required |
macs2_consensus_fc |
direct | Table | recipe macs2/consensus_fc.py |
required |
deseq2_qc_pca |
derived | Table | recipe nf-core/chipseq/deseq2_qc_pca.py |
optional |
deseq2_qc_sample_dists |
direct | Table | recipe deseq2/qc_sample_dists.py |
optional |
Conditional routes
Rows are data collections; columns are the variables you set or params.json flags auto-detected from the run. Each filled cell is the effect of setting that variable; an empty cell means that variable leaves the collection unchanged. (16 collections are unaffected by any variable — present on every run.)
+ included− removed⇄ repointed
| Data collection | METADATA_FILE |
PRESEQ_RAN |
|---|---|---|
metadata |
+ | |
picard_markduplicates_metrics_raw |
− | |
picard_markduplicates_metrics |
− |
Cross-DC links
22 links — selecting a value in the source collection filters the target. The join column is shown after the source.
| Source · column | Target | Filters | |
|---|---|---|---|
design · sample_id |
→ | multiqc_data |
Filter the MultiQC panels by the samples picked on the design sheet |
design · sample_id |
→ | macs2_peaks |
Filter the peak table by the samples picked on the design sheet |
design · sample_id |
→ | macs2_peak_summary |
Filter the peak QC summary by the samples picked on the design sheet |
design · sample_id |
→ | homer_annotated_peaks |
Filter the peak annotation by the samples picked on the design sheet |
macs2_peaks · peak_id |
→ | homer_annotated_peaks |
Carry a peak selected on the MACS3 panels over to its HOMER annotation |
homer_annotated_peaks · peak_id |
→ | macs2_peaks |
Carry a peak selected in the annotation table back to the MACS3 panels |
macs2_consensus_boolean · peak_id |
→ | macs2_consensus_fc |
Carry a consensus interval selected on the overlap panels over to the signal heatmap |
macs2_consensus_fc · peak_id |
→ | macs2_consensus_boolean |
Carry a consensus interval selected on the signal heatmap back to the overlap panels |
design · sample_id |
→ | preseq_complexity_curve |
Filter the complexity curves by the samples picked on the design sheet |
design · sample_id |
→ | deeptools_fingerprint_metrics |
Filter the fingerprint metrics by the samples picked on the design sheet |
design · sample_id |
→ | deeptools_plot_profile |
Filter the metagene profiles by the samples picked on the design sheet |
design · sample_id |
→ | homer_tss_distance_profile |
Filter the TSS distance profiles by the samples picked on the design sheet |
design · sample_id |
→ | macs2_summit_profile |
Filter the summit-centred profiles by the samples picked on the design sheet |
design · sample_id |
→ | picard_markduplicates_metrics |
Filter the duplication metrics by the libraries picked on the design sheet |
macs2_peaks · chr |
→ | macs2_consensus_boolean |
A region brushed or typed on the peak navigator narrows the consensus intervals |
macs2_peaks · chr |
→ | homer_annotated_peaks |
A region brushed or typed on the peak navigator narrows the HOMER annotation track |
samplesheet · sample |
→ | multiqc_data |
Filter the read-level MultiQC panels by the sequencing libraries picked in the left panel |
design · antibody |
→ | macs2_consensus_boolean |
Narrow the consensus overlap panels to the antibody picked in the left panel |
design · antibody |
→ | macs2_consensus_fc |
Narrow the consensus signal heatmap to the antibody picked in the left panel |
design · sample_id |
→ | deseq2_qc_pca |
Filter the count-matrix PCA by the libraries picked in the left panel |
design · antibody |
→ | deseq2_qc_pca |
Narrow the count-matrix PCA to the antibody picked in the left panel |
design · sample_id |
→ | deseq2_qc_sample_dists |
Filter the sample distance matrix by the libraries picked in the left panel |
Recipes
Each recipe reshapes raw pipeline output into a tidy table. The name links to its source; Output lists the validated OUTPUT_SCHEMA columns.
| Recipe | Transforms | Output |
|---|---|---|
deeptools/fingerprint_metrics.py |
Per-sample deepTools fingerprint metrics, one row per library. | sample, auc, synthetic_auc, auc_ratio, x_intercept, synthetic_x_intercept, elbow_point, synthetic_elbow_point, synthetic_js_distance |
deeptools/plot_profile.py |
deepTools metagene profile in long form, one row per sample and bin. | sample, group, bin, bin_label, signal |
deseq2/qc_sample_dists.py |
The DESeq2 QC sample-distance matrix the pipeline already computed. | sample |
homer/annotate_peaks.py |
Tidy HOMER annotatePeaks.pl output into a per-peak annotation table. |
sample, peak_id, chr, start, end, strand, peak_score, annotation_class, annotation, distance_to_tss, nearest_promoter_id, gene_name, gene_type |
homer/tss_distance_profile.py |
Where each sample's peaks sit relative to the nearest TSS, pre-binned. | sample, distance_to_tss, peak_count, fraction |
macs2/consensus_boolean.py |
Consensus peak x sample presence matrix from MACS2 consensus boolean tables. | peak_id, consensus_set, interval_id, chr, start, end, num_peaks, num_samples |
macs2/consensus_fc.py |
Fold-enrichment matrix of the strongest MACS2 consensus peaks. | peak_id, consensus_set, interval_id, chr, region, support |
macs2/peak_summary.py |
Per-sample MACS2 peak QC: call count, FRiP score and peak-metric spreads. | sample, num_peaks, frip_score, width_median, width_mean, width_max, fold_enrichment_median, fold_enrichment_mean, neg_log10_qvalue_median, neg_log10_pvalue_median |
macs2/summit_profile.py |
Summit-centred aggregate of the MACS2 peak calls, one curve per sample. | sample, offset_bp, n_summits, peak_footprint, neighbour_summit_density |
nf-core/chipseq/deseq2_qc_pca.py |
DESeq2 QC principal components per antibody, with each library's condition. | sample_id, consensus_set, dim_1, dim_2, dim_1_percent, dim_2_percent |
nf-core/chipseq/design_factors.py |
One row per merged library of a chipseq 2.x run, with its factors as columns. | sample_id, role, is_control, antibody, condition, replicate, control_id |
nf-core/chipseq/peaks.py |
MACS3 peak calls of either peak type, in one tidy table. | sample, peak_id, chr, start, end, width, summit, score, fold_enrichment, neg_log10_pvalue, neg_log10_qvalue, peak_type |
picard/markduplicates_metrics.py |
Duplication metrics from a Picard MarkDuplicates report. | sample, library, unpaired_reads_examined, read_pairs_examined, unmapped_reads, unpaired_read_duplicates, read_pair_duplicates, read_pair_optical_duplicates, duplicate_reads, reads_after_dedup, percent_duplication, estimated_library_size |
preseq/complexity_curve.py |
Library complexity curve with its confidence ribbon, one row per read depth. | sample, total_reads, expected_distinct, lower_ci, upper_ci, ci_width |
Dashboard tabs
One dashboard: the Overview, then six child tabs in three groups, read as a funnel from library quality to the regions the replicates agree on. Each tab below carries the same icon and colour the dashboard gives it, so the page and the app read alike.
| Group | Tabs |
|---|---|
| Data & QC | MultiQC, Signal |
| Peak calls | Peaks, Annotation, Locus |
| Comparison | Consensus |
Each child tab opens with a short intro and a strip of four cards, then at most
three open sections; tables and details follow, collapsed. The persistent Sample
filters (condition, antibody, library, replicate, role) sit in the left panel and
narrow every tab through the project links; QC thresholds (FRiP, peaks called)
sit collapsed under them. The Sample sheet and Reference tables (the per-ChIP
peak QC) are pinned, collapsed, to the bottom of every child tab. The hub column is
always called condition: the GROUP_COL column of the design table when one is
given, the sample name without its replicate suffix otherwise, so the dashboard
reads the same with or without the table. The consensus sets have no library
column: the antibody reaches them, through a prefix link on the set name.
Protein-DNA binding, from library quality to the regions the replicates agree on.
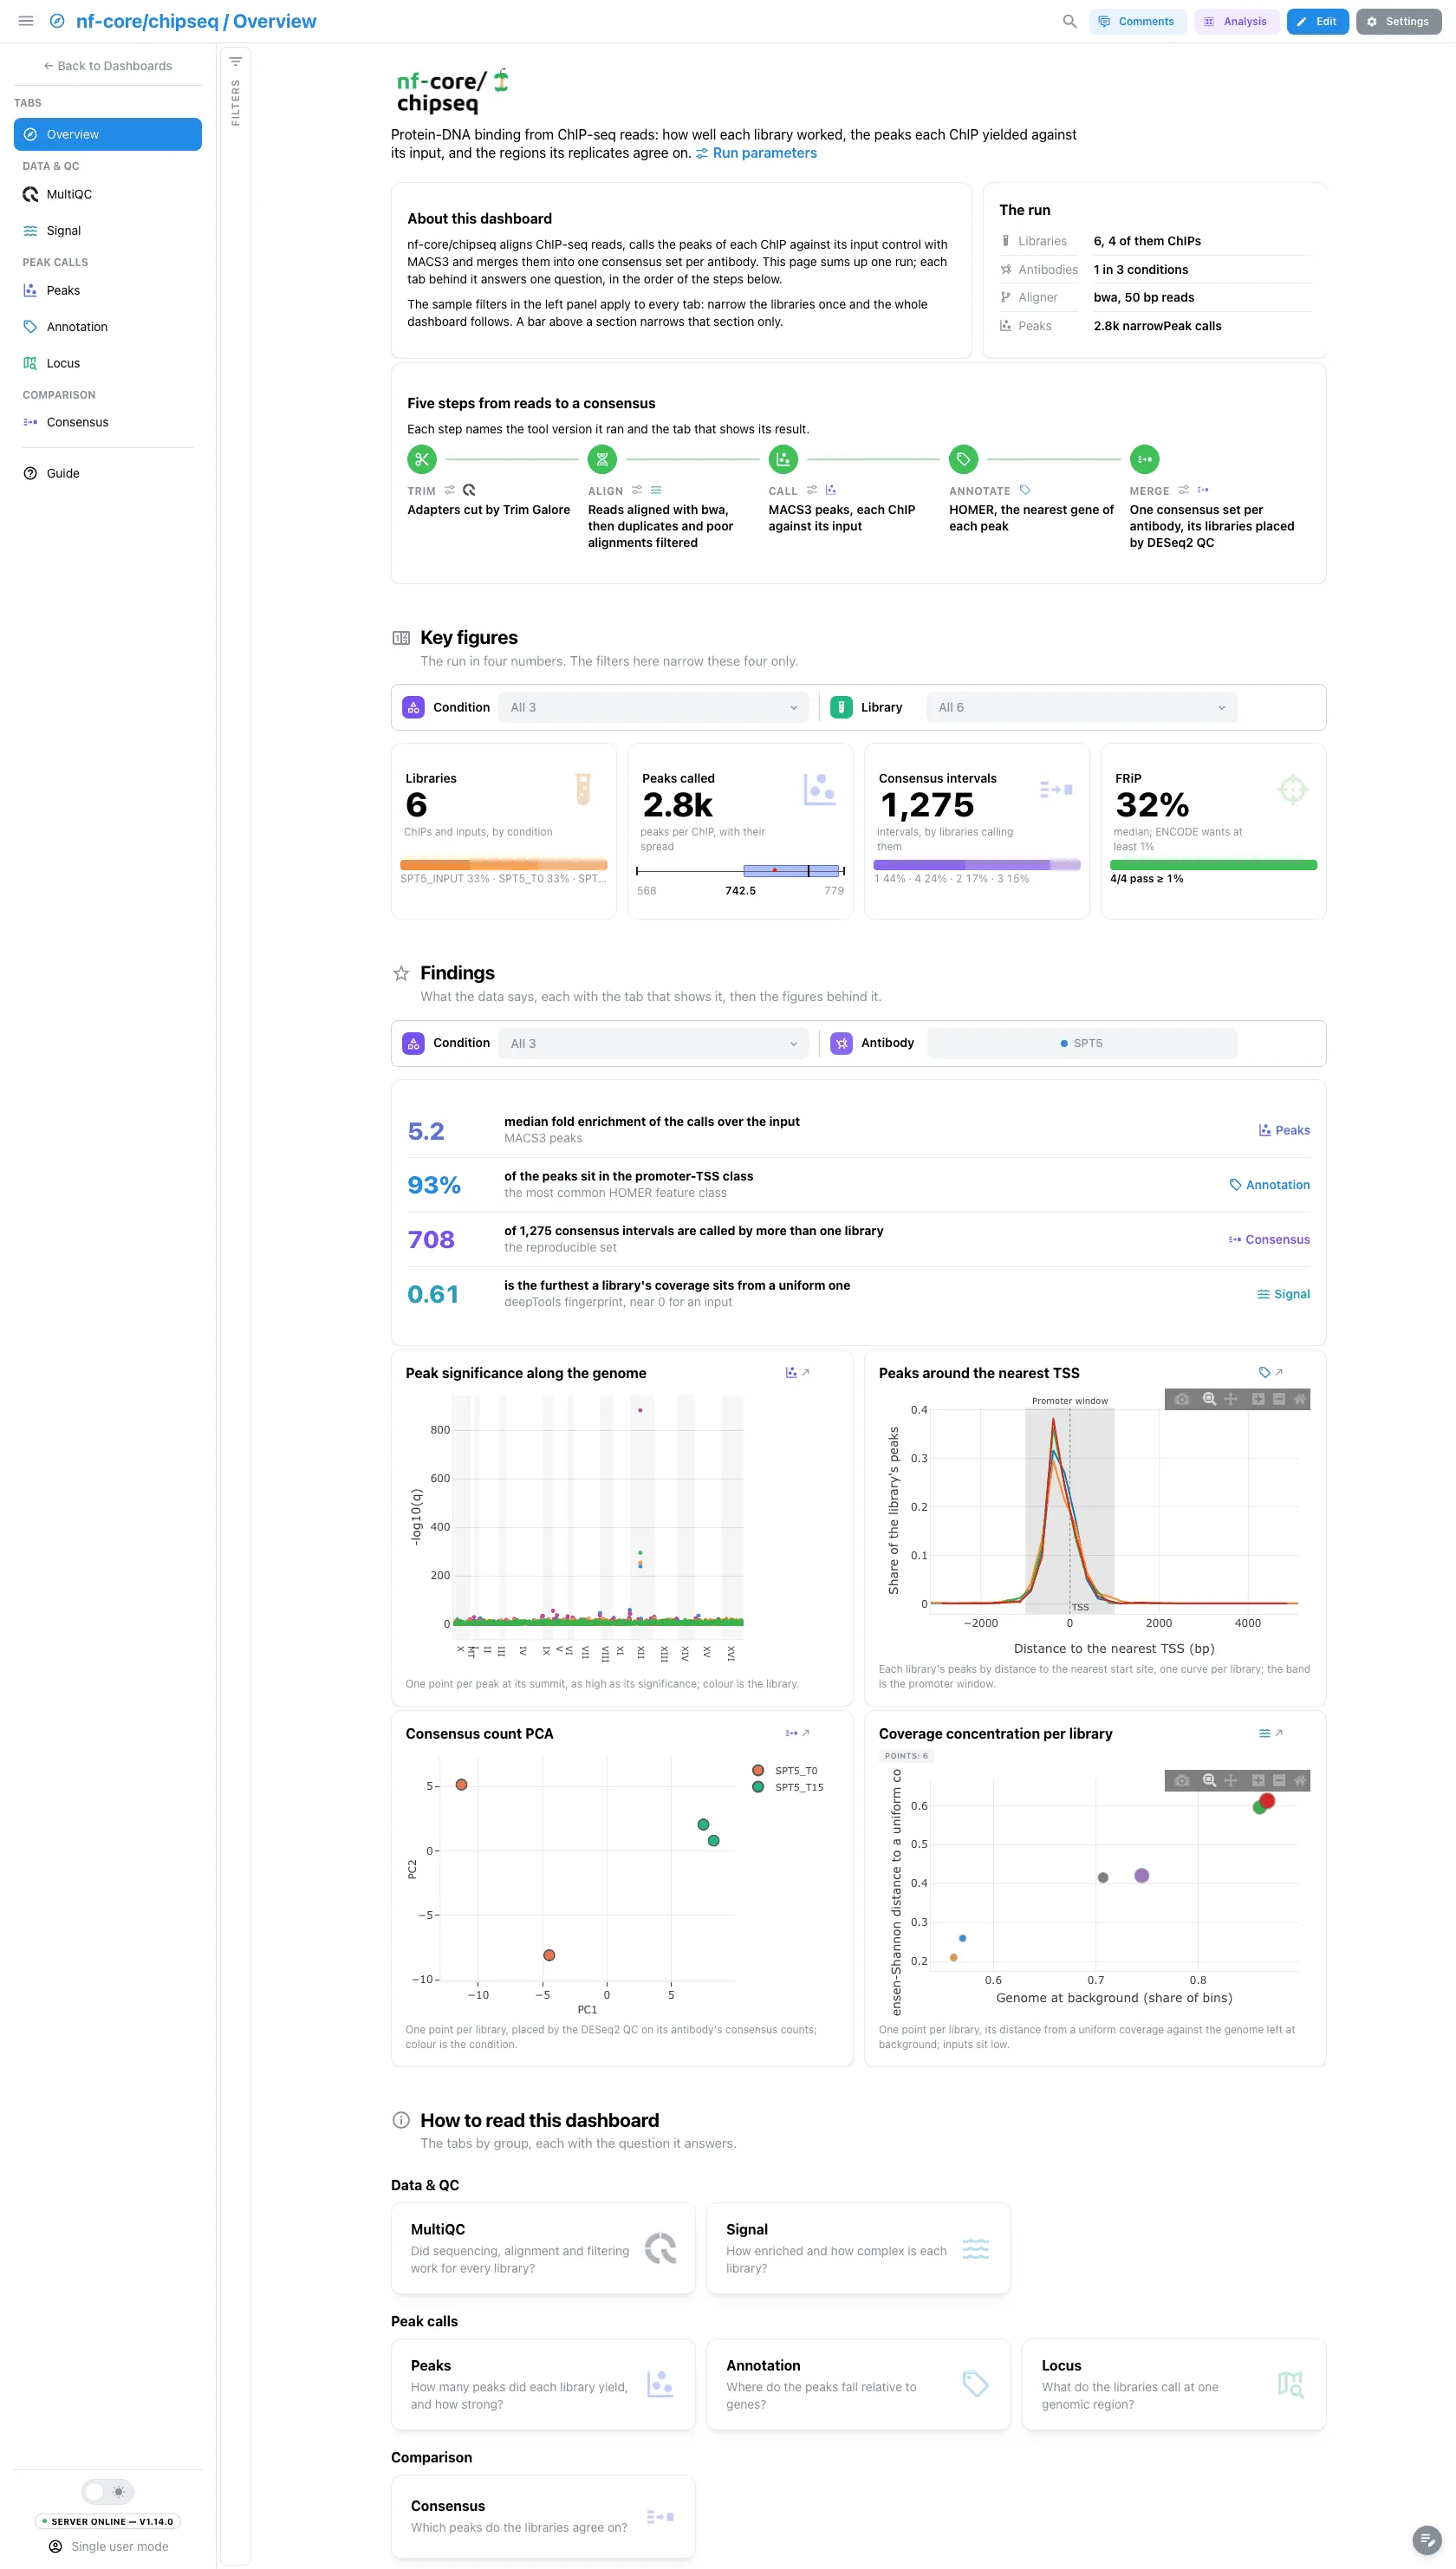
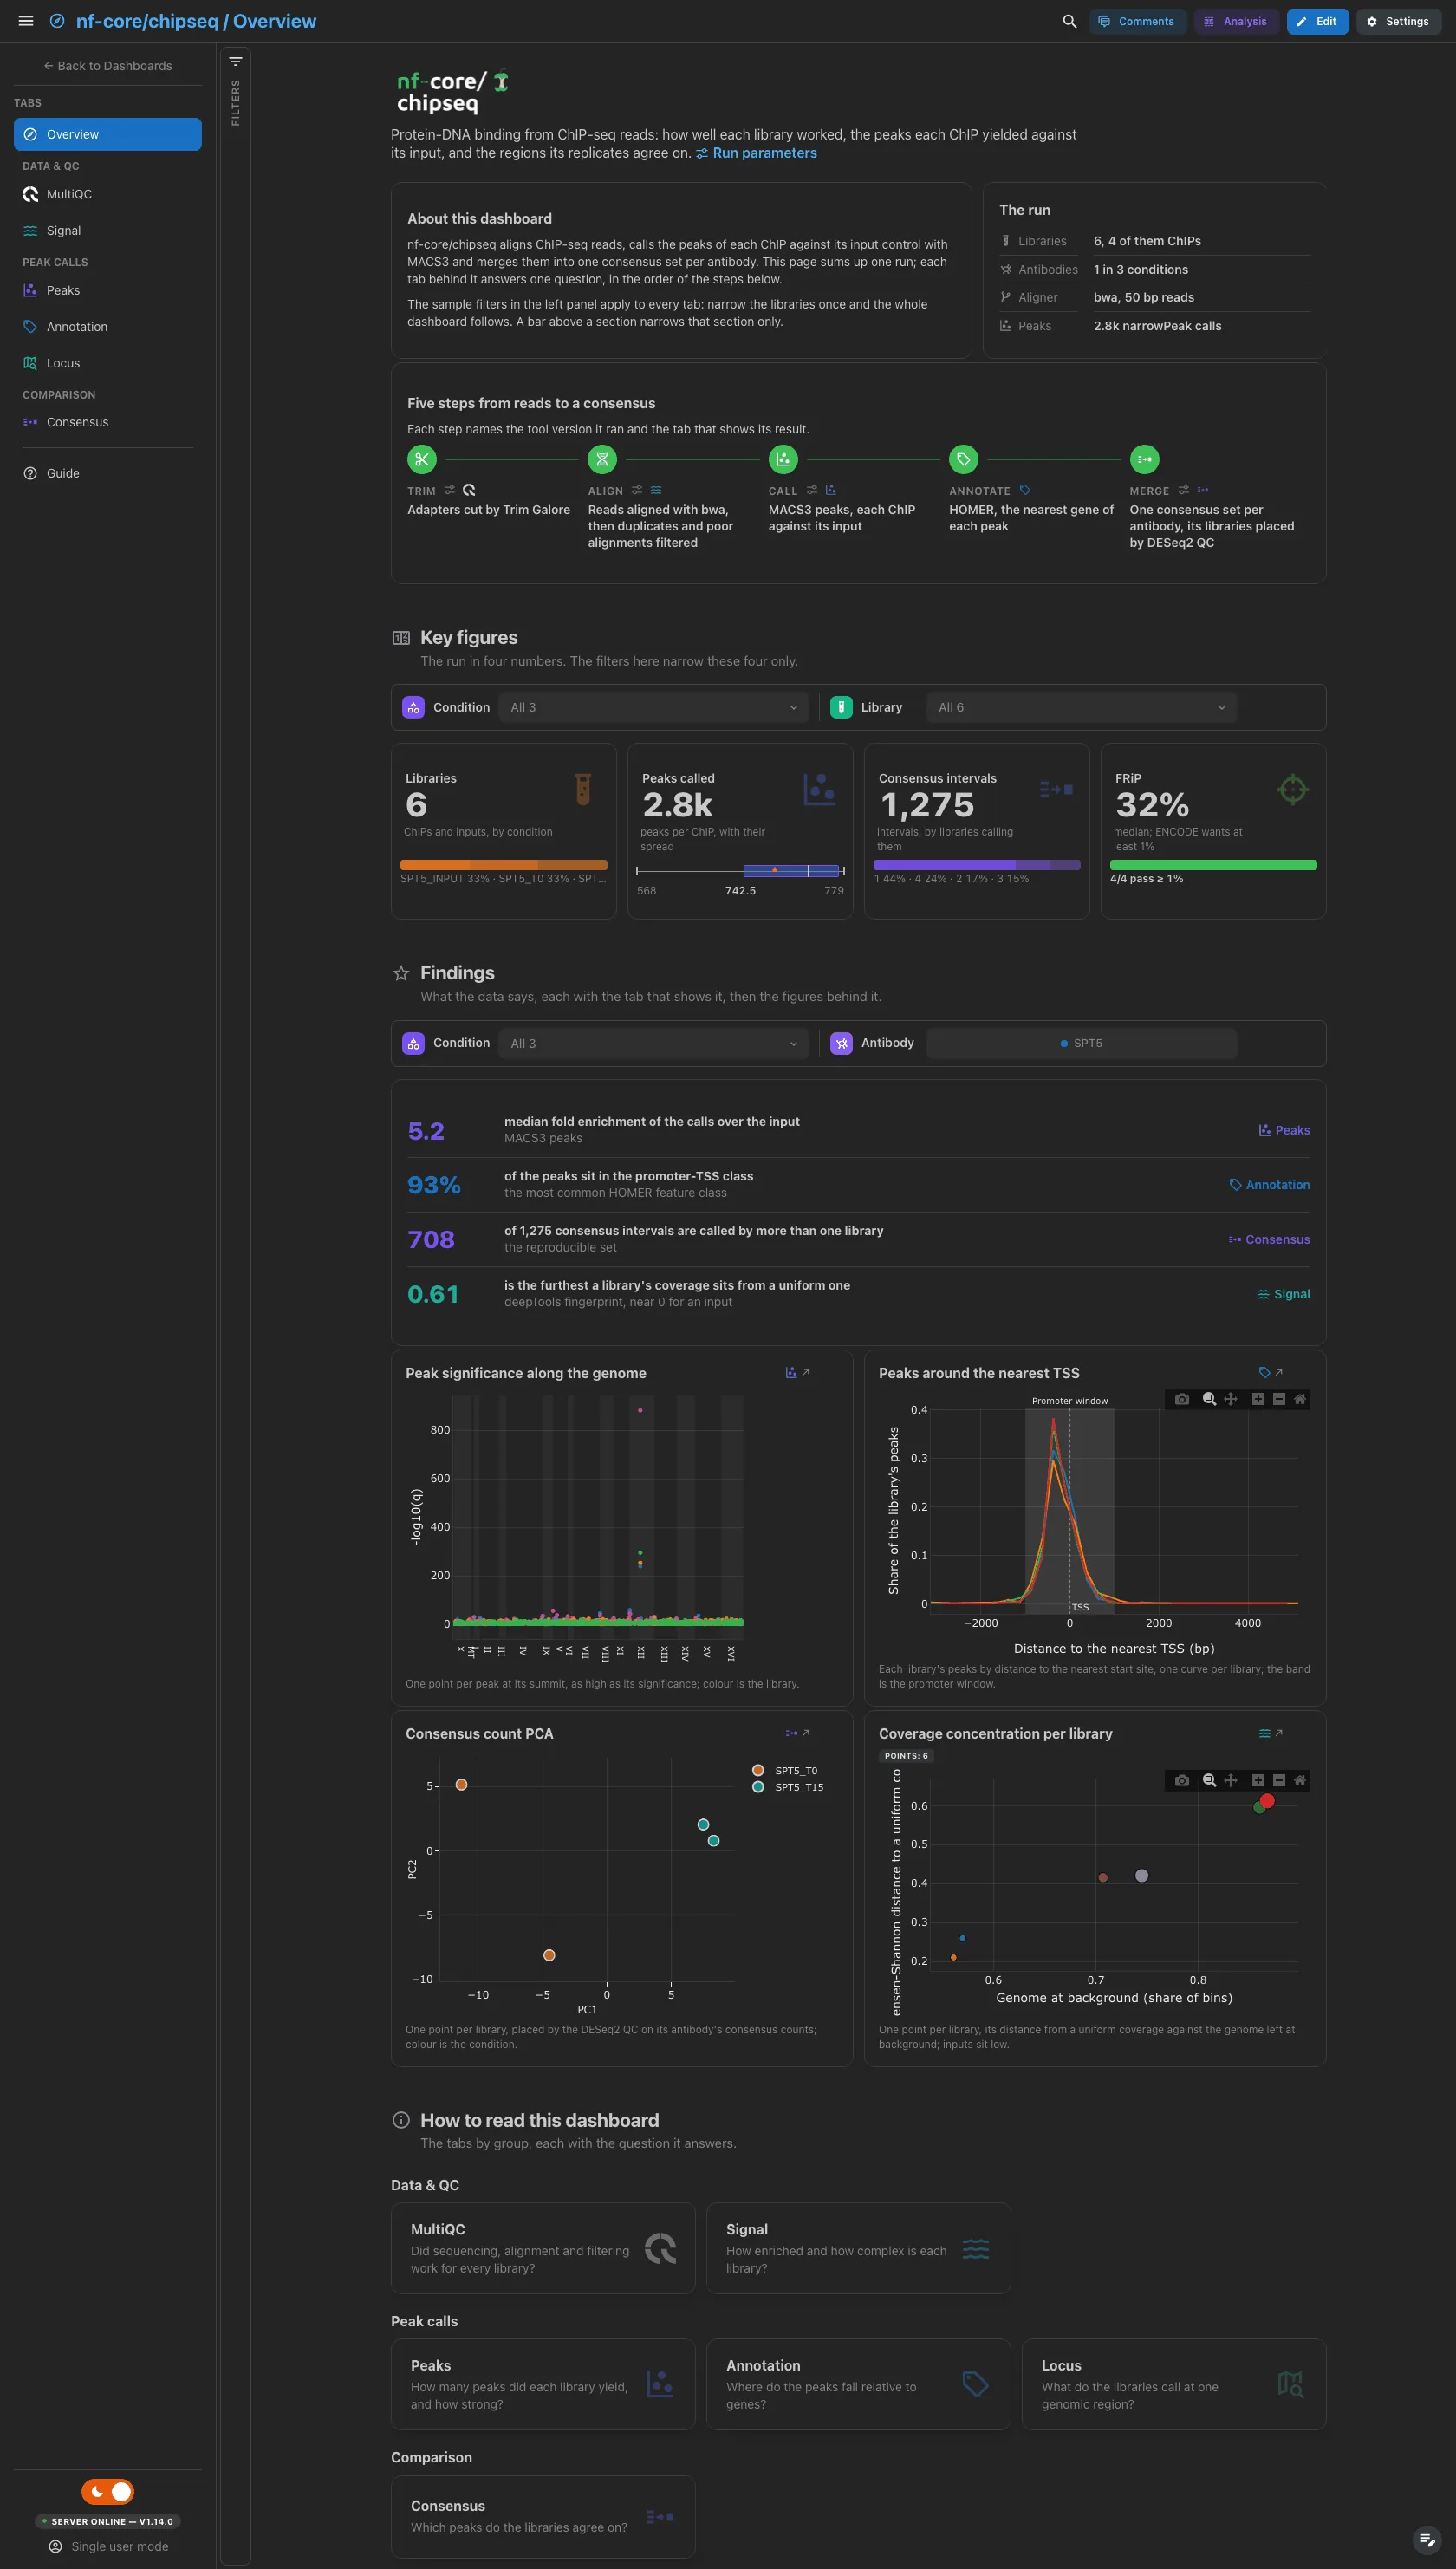
A short hero links the run parameters: 2.x writes a params.json and a
software versions file, and the dialog lists both. About this dashboard says
how the two filter levels work, The run lists the libraries and ChIPs, the
antibodies and conditions, the aligner and read length and the peaks called
with their type, and Pipeline walks the five steps from trimming to the
consensus merge, each linked to its tool version or settings and its tab. The
findings are live values: they follow the filters, and a route that lacks their
data drops them. The PCA of the consensus counts takes the figure slot a
volcano would hold: with no contrast to test, whether the libraries group by
condition is the comparison 2.x still draws.
Filters and components
Filters · the left panel starts collapsed. Key figures has its own filter bar (condition and library), and so does Findings (condition and antibody): each narrows its own section only.
| Section | What it holds |
|---|---|
| Top | Hero, About this dashboard, The run, Pipeline |
| Key figures | 4 headline cards: libraries, peaks called, consensus intervals, FRiP |
| Findings | Live result rows, then 4 figures: the peak significance along the genome, the peaks around the nearest start site, the DESeq2 QC PCA of the consensus counts and the fingerprint scatter |
| How to read this dashboard | The tabs by group, each with its question |
Data & QC · Did sequencing, alignment and filtering work for every library?
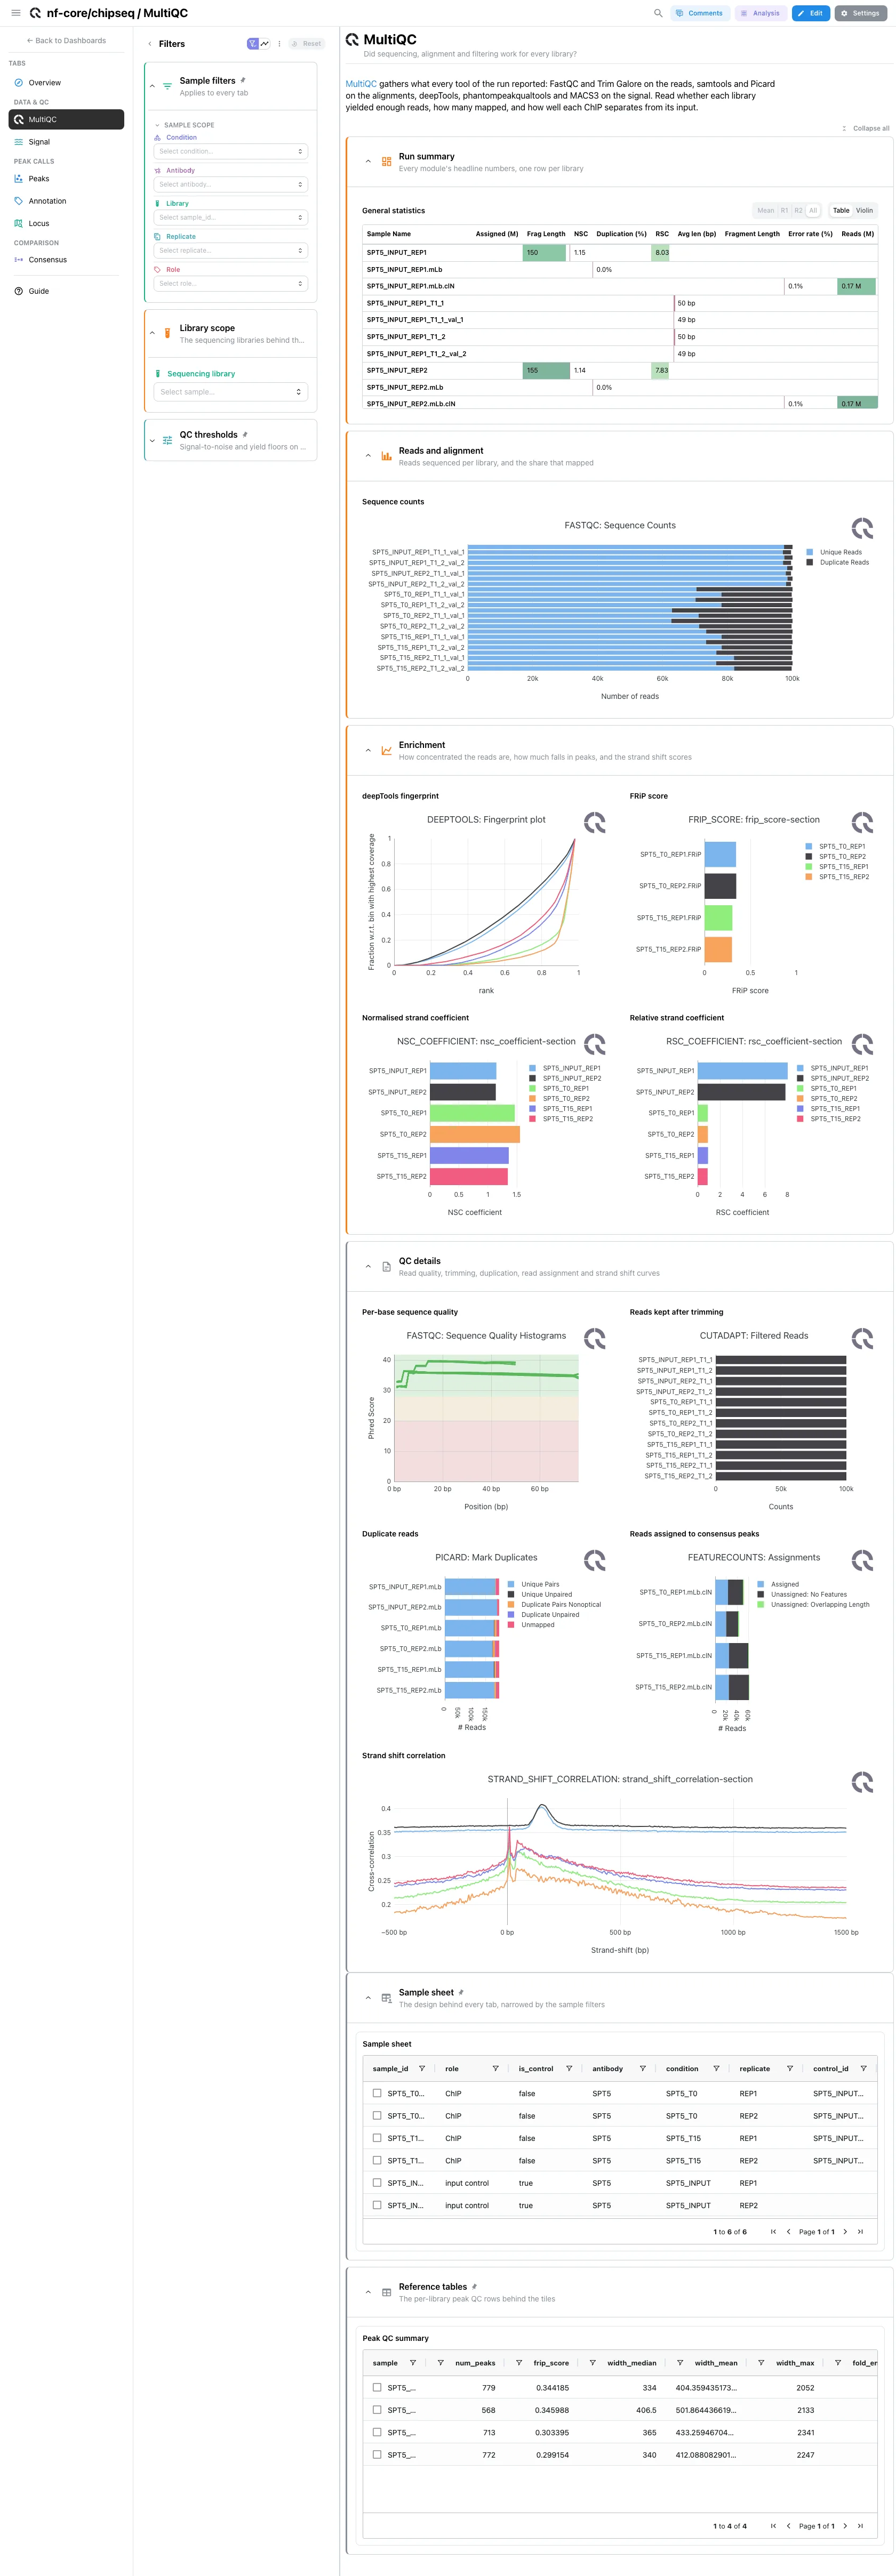
MultiQC panels only. Open: general statistics, FastQC sequence counts beside
samtools percent mapped on the unfiltered merged libraries, then the enrichment
panels that say whether a ChIP worked: the deepTools fingerprint, the FRiP
scores and the NSC and RSC strand coefficients. Per-base quality, Trim Galore
kept reads, Picard duplicates, featureCounts assignments and the strand shift
correlation curve are collapsed. A reprocessed report has no samtools-1, so
that tile drops and FastQC takes the row.
Filters and components
Filters · Sequencing library on samplesheet, in its own Library
scope group: the read-level panels are keyed on the sequencing library,
a finer grain than the merged library every other tab works in.
| Section | What it holds |
|---|---|
| Run summary | 1 MultiQC panel |
| Reads and alignment | 2 MultiQC panels |
| Enrichment | 4 MultiQC panels (the fingerprint has one tile per report, on one slot) |
| QC details (collapsed) | 5 MultiQC panels |
Data & QC · How enriched and how complex is each library?
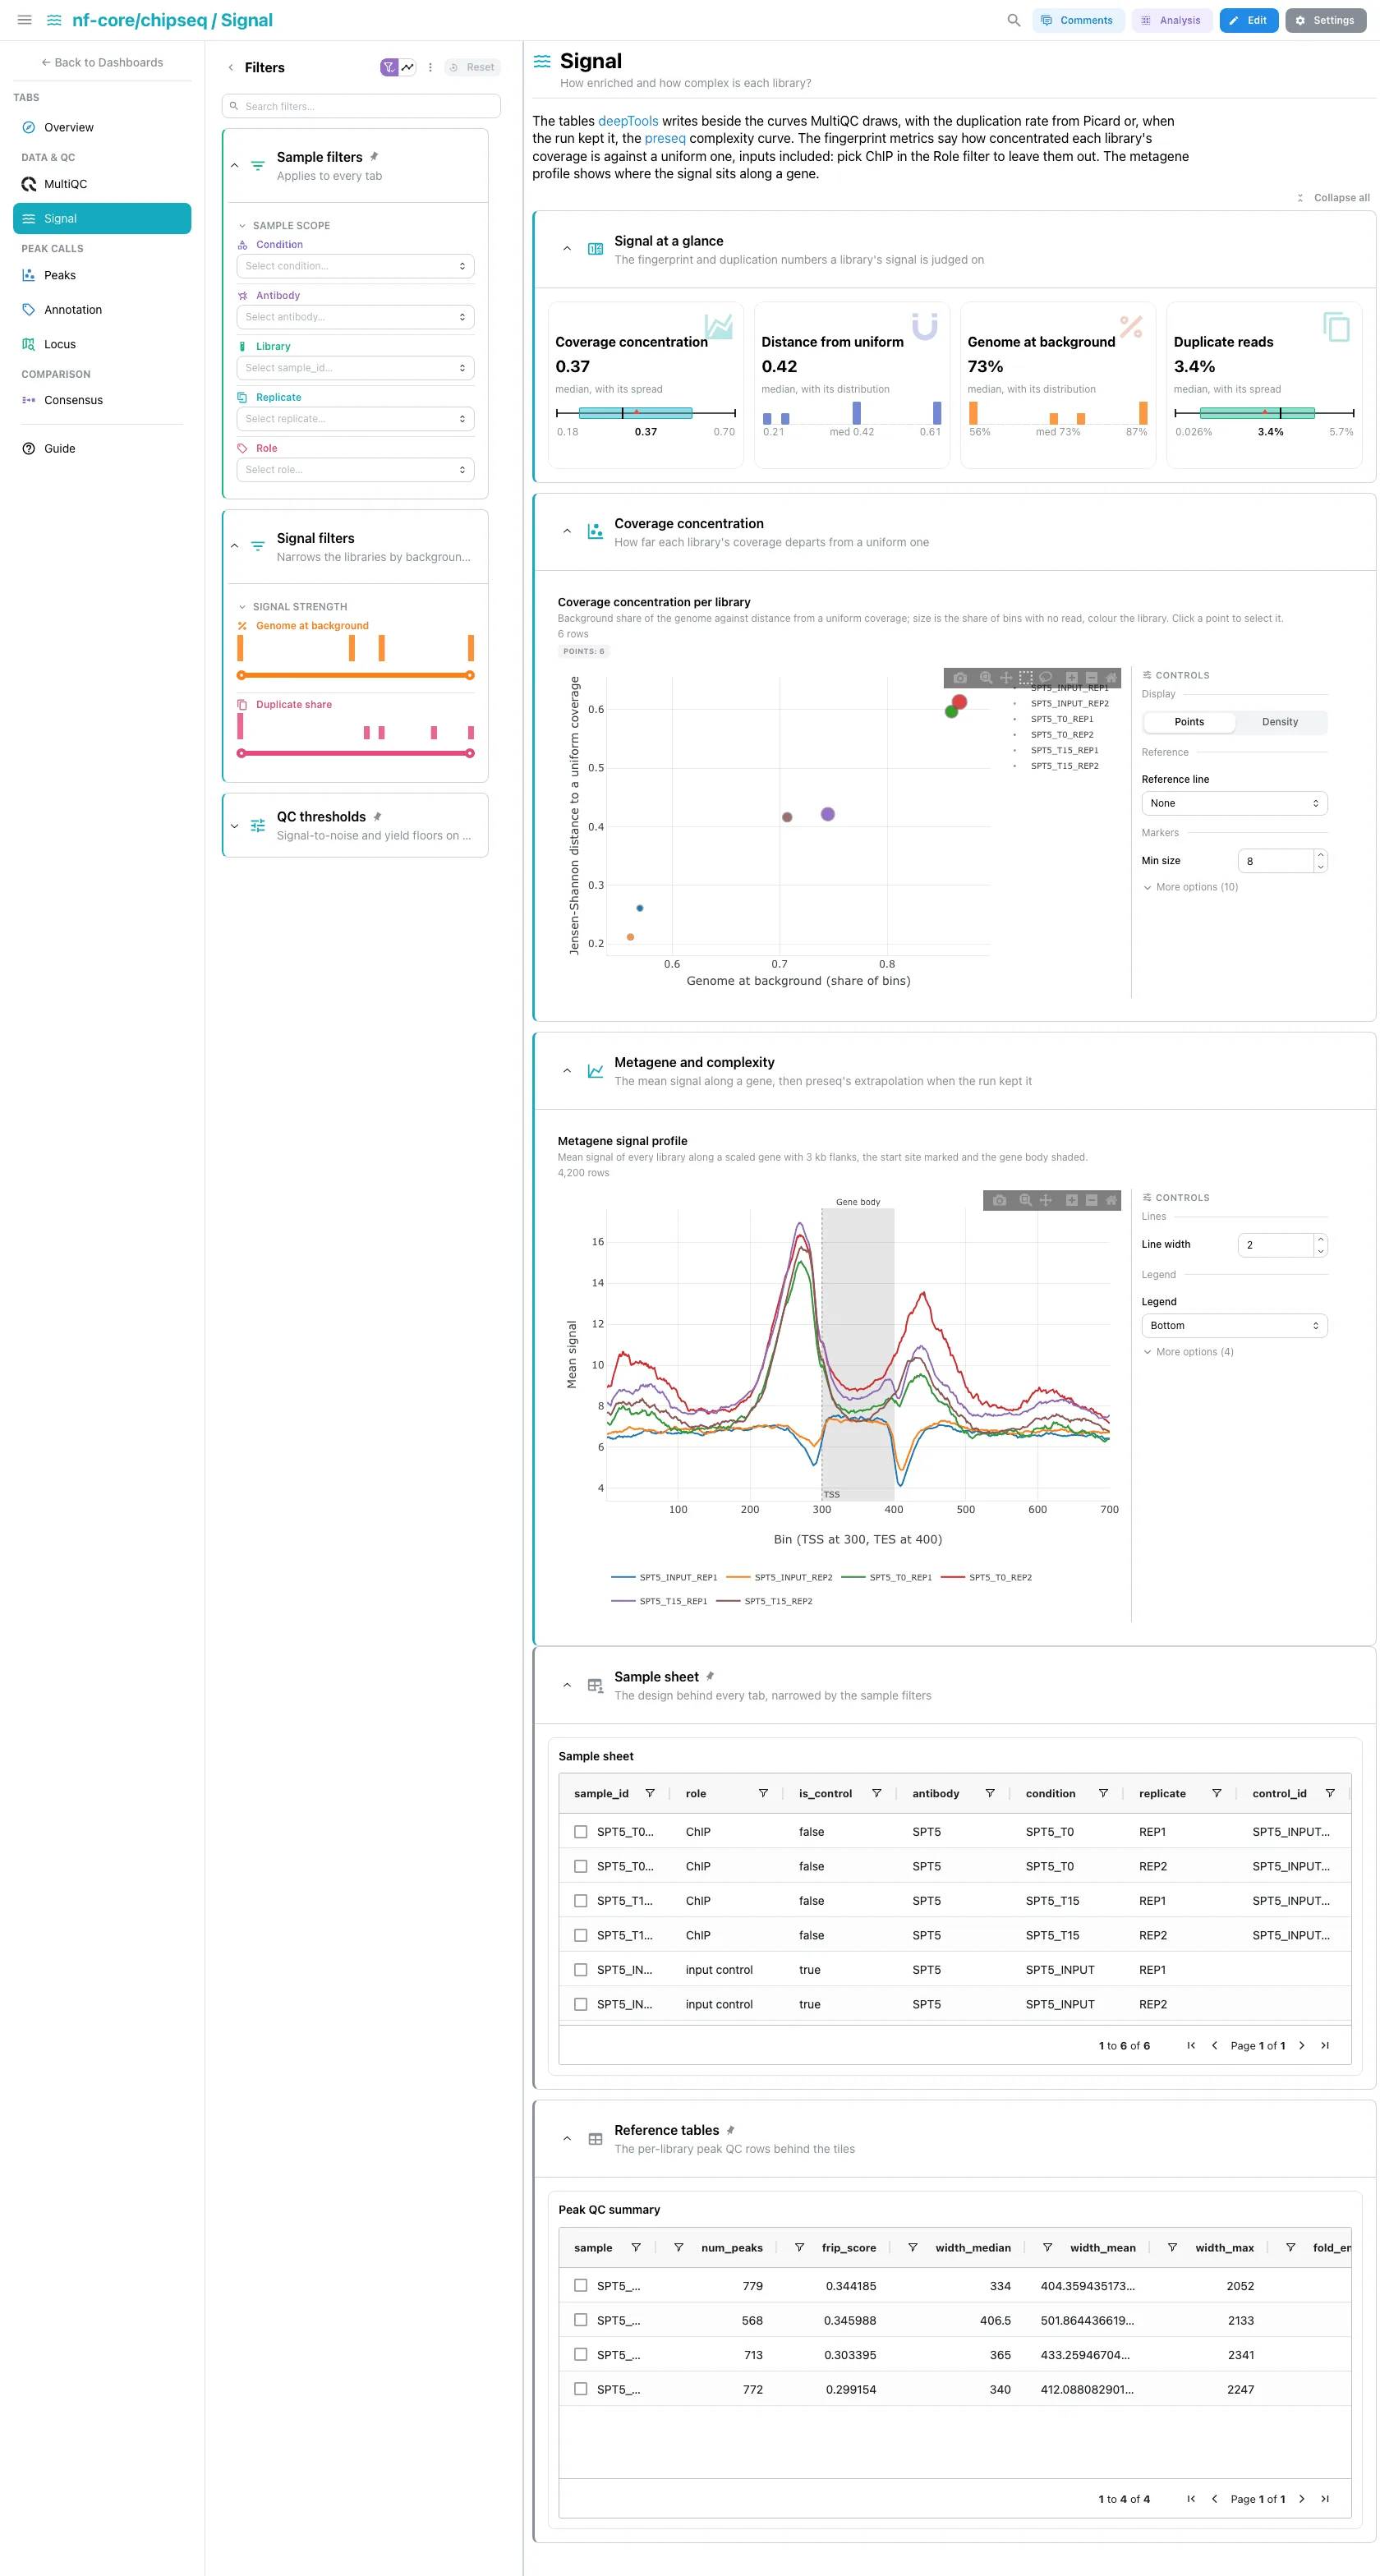
The tables deepTools writes beside the curves MultiQC draws. 2.x runs plotFingerprint without a JSD sample, so every fingerprint reading is against a uniform library rather than the input, and the inputs are rows of their own: the Role filter leaves them out. The coverage concentration, the distance from a uniform coverage, the genome left at background and, in one slot, the duplicate share Picard flags or, on a preseq run, the distinct fragments preseq expects. Then the fingerprint scatter, and the metagene profile with the start site marked and the gene body shaded, above the preseq complexity curves when the run kept preseq.
Filters and components
Filters · a Genome at background range on
deeptools_fingerprint_metrics, plus a Duplicate share range on
picard_markduplicates_metrics or, on a preseq run, an Extrapolated
depth range on preseq_complexity_curve.
| Section | What it holds |
|---|---|
| Signal at a glance | 4 cards (the fourth is Picard's duplicate share or preseq's distinct fragments) |
| Coverage concentration | 1 advanced visualization |
| Metagene and complexity | 1 advanced visualization, plus the complexity curves on a preseq run |
The complexity curve needs preseq
A default 2.x run skips preseq, so its collections are optional and the
curves drop. A run made with --skip_preseq false keeps them; pass
--var PRESEQ_RAN=true with it so the preseq card takes the Picard slot
alone.
Peak calls · How many peaks did each library yield, and how strong?
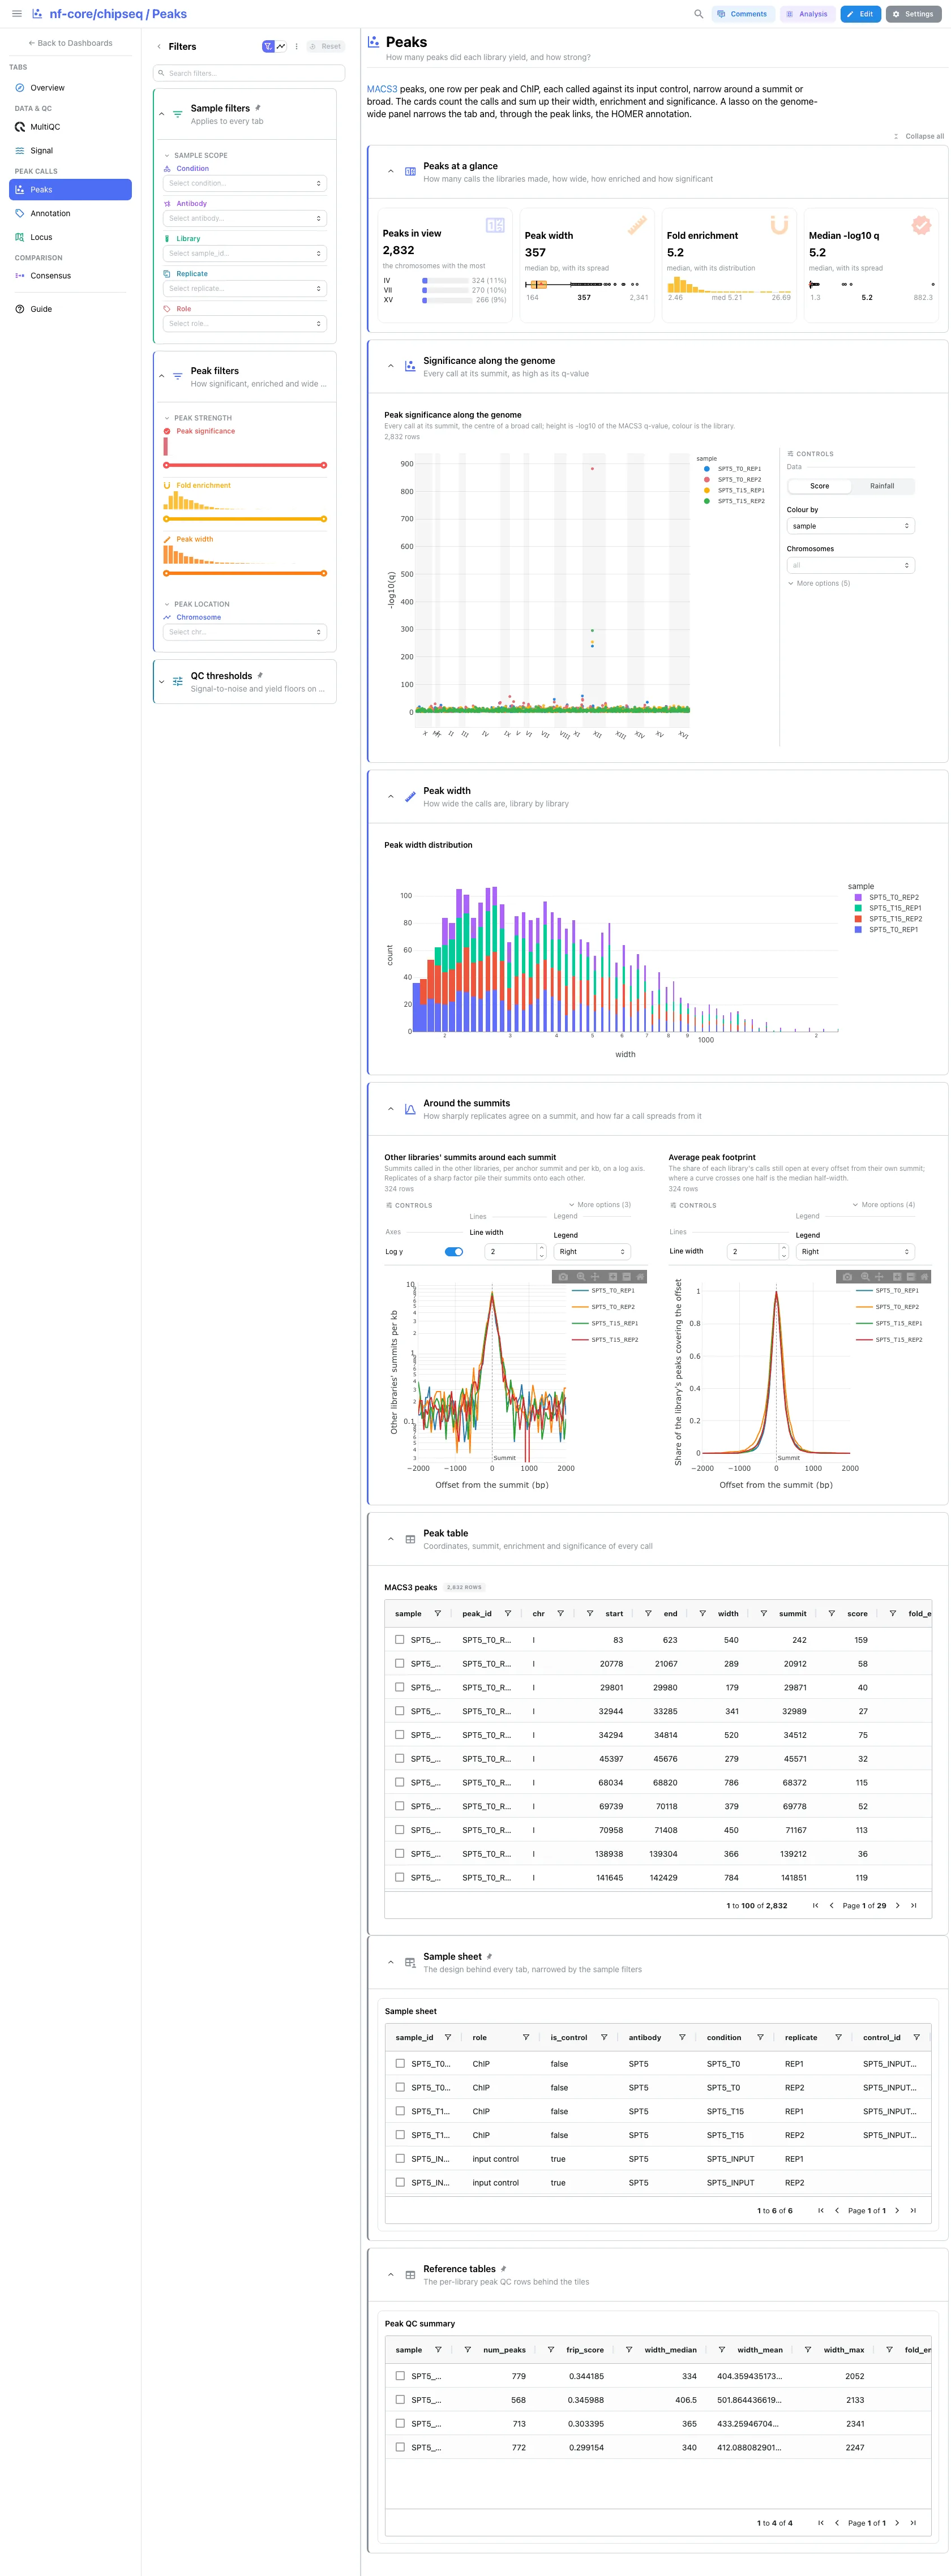
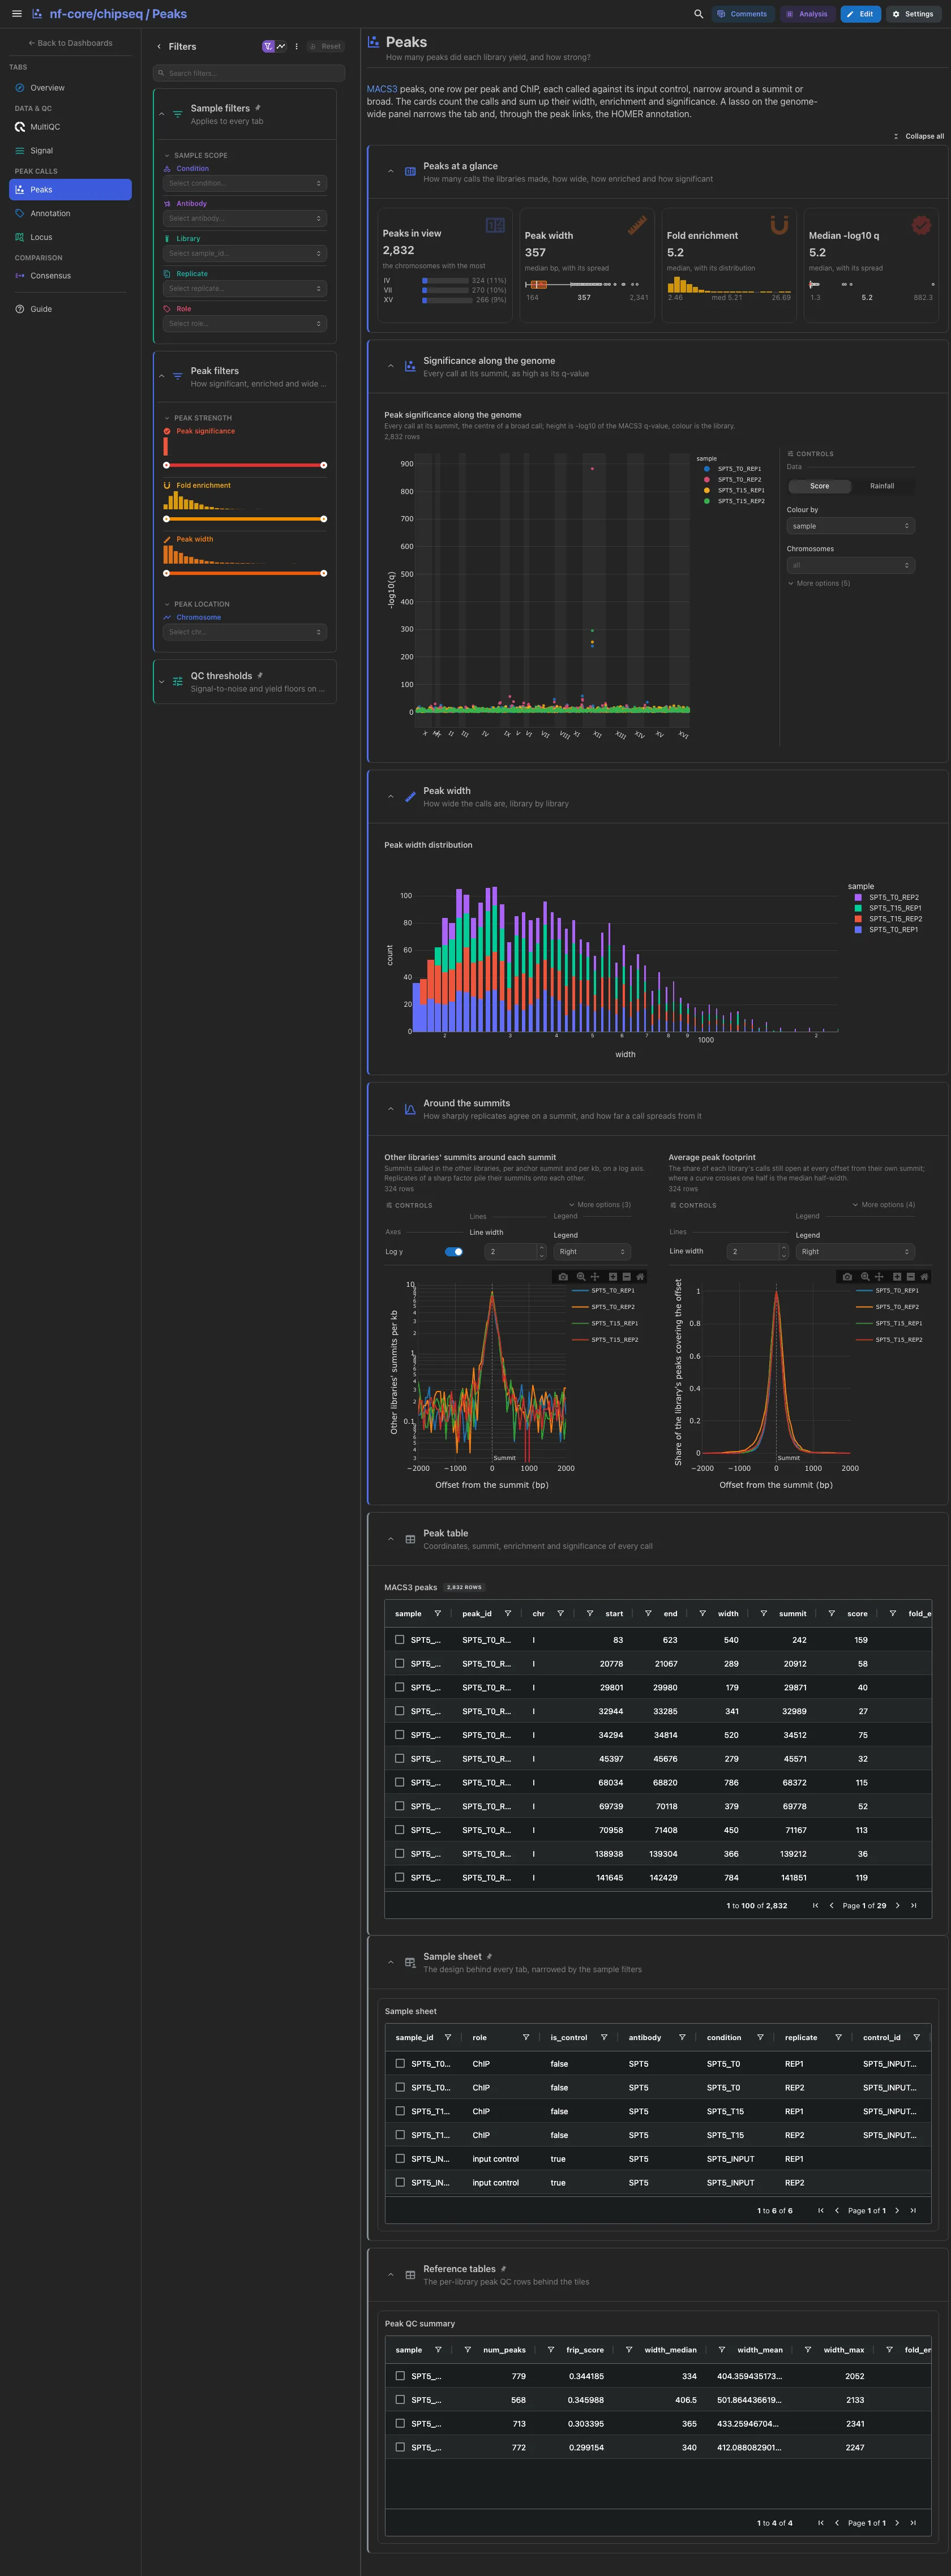
MACS3 peaks, one row per peak and ChIP, each called against its input. The
peaks in view, their width, their fold enrichment and the median -log10(q).
Then the significance along the genome, where a lasso narrows the tab and,
through the peak links, the HOMER annotation, and the width distribution on a
log axis, which separates a sharp factor from a broad mark. The two summit
profiles close the tab: the other libraries' summits around each summit
(replicates of a sharp factor pile up) beside the average footprint of a call.
Neither is a read coverage, since the recipe aggregates the calls themselves; on
a broadPeak run the summit is the centre of the region.
Filters and components
Filters · Peak significance, Fold enrichment and Peak width
ranges, and Chromosome, all on macs2_peaks.
| Section | What it holds |
|---|---|
| Peaks at a glance | 4 cards |
| Significance along the genome | 1 advanced visualization |
| Peak width | 1 histogram |
| Around the summits | 2 advanced visualizations |
| Peak table (collapsed) | MACS3 peaks |
Peak calls · Where do the peaks fall relative to genes?
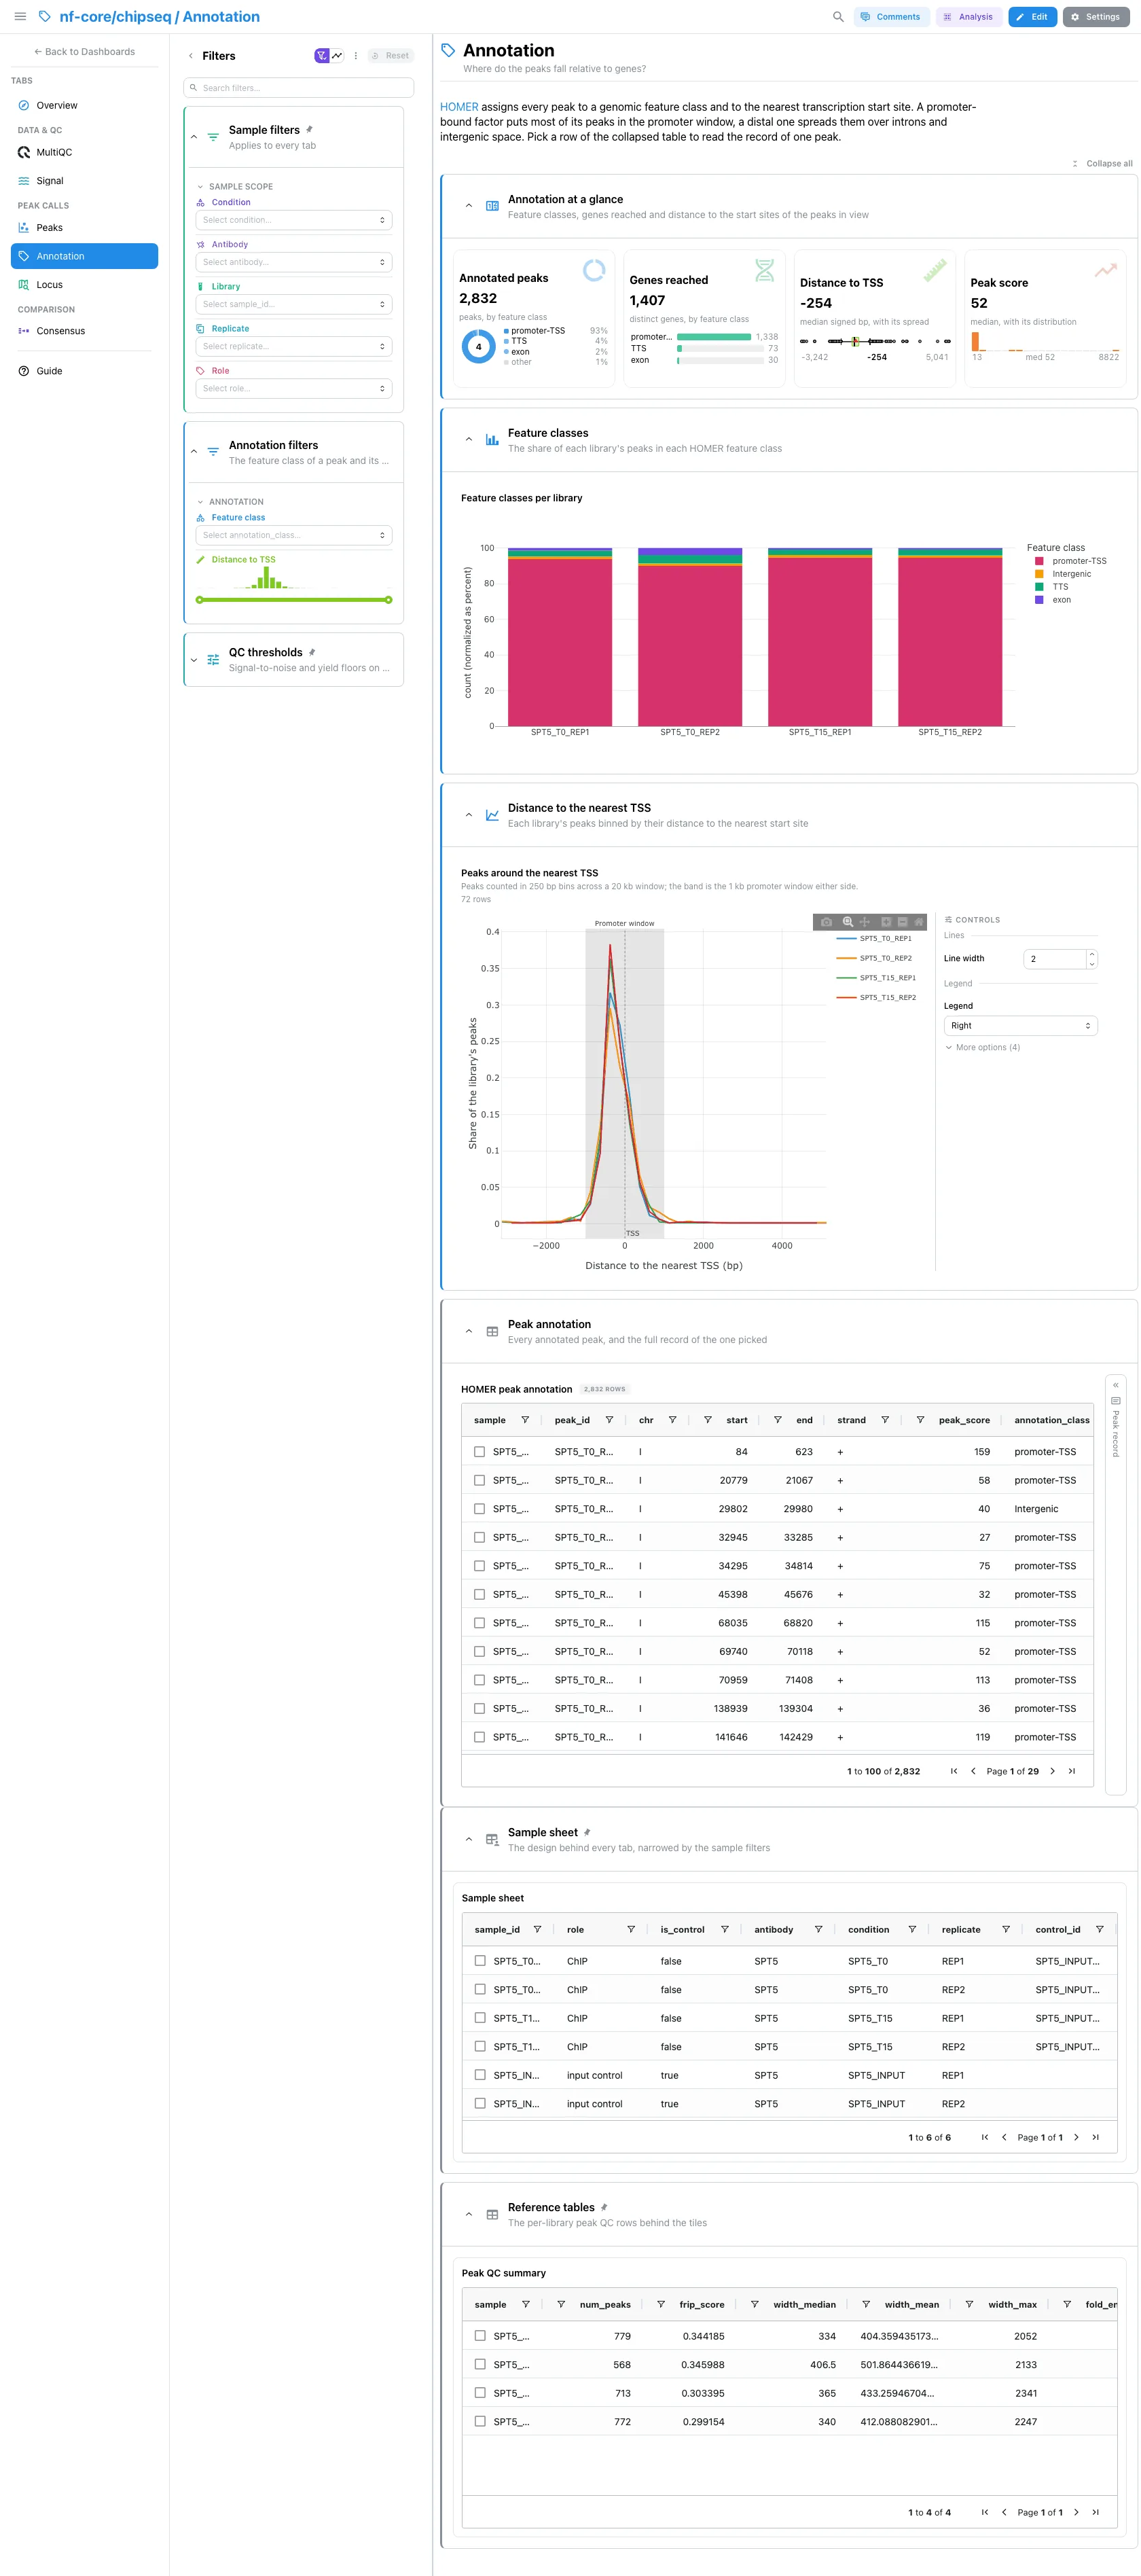
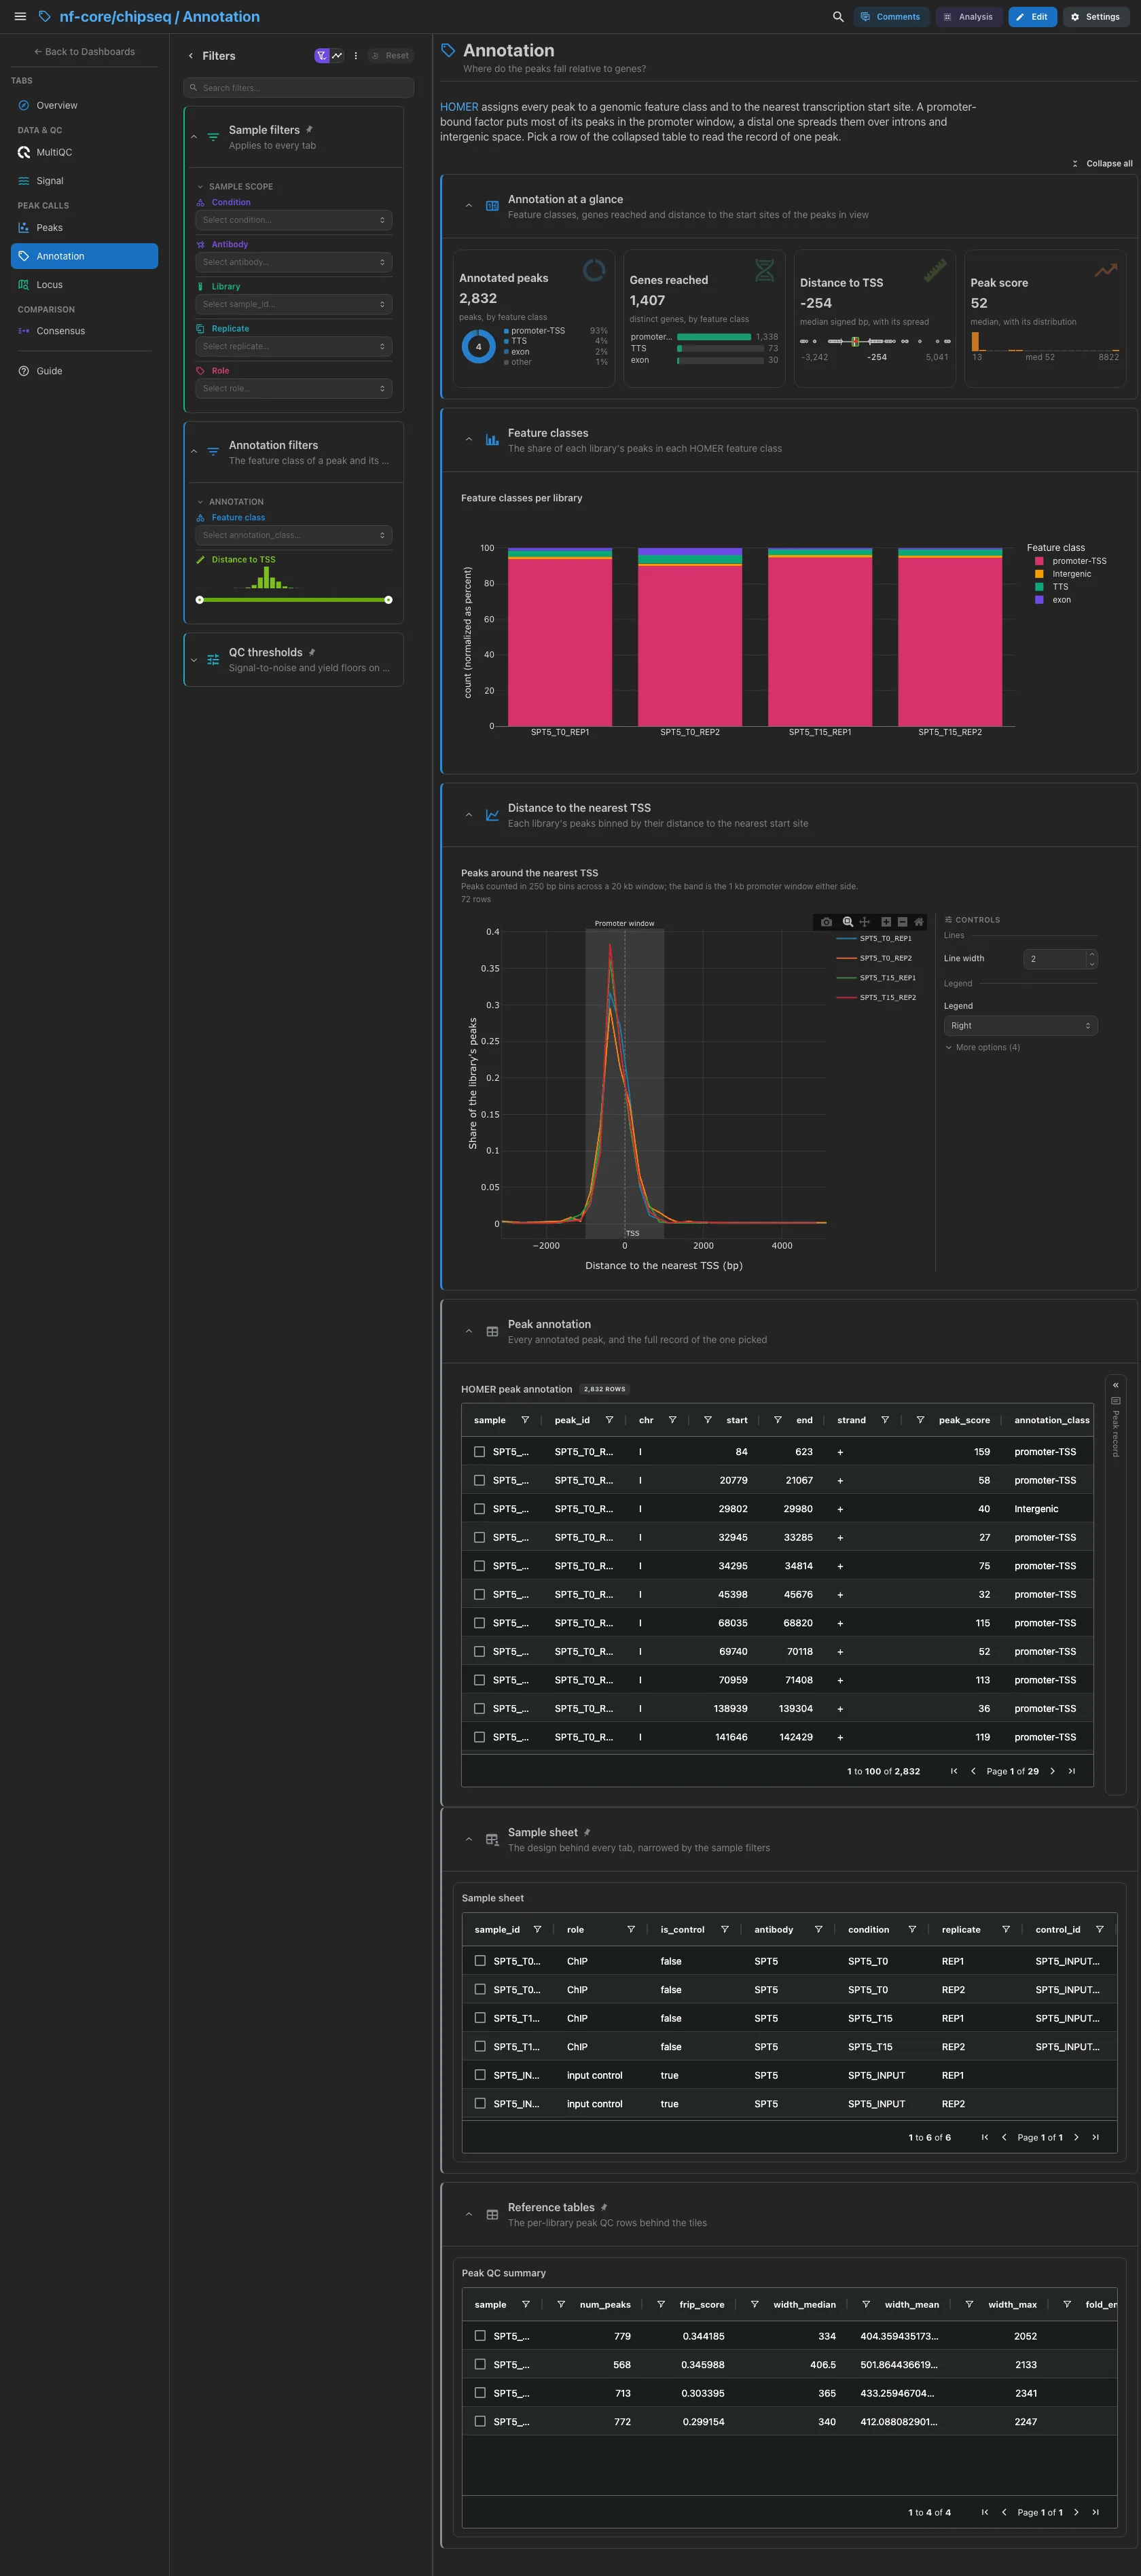
HOMER assigns every peak to a feature class and to the nearest start site. The annotated peaks by feature class, the genes reached, the distance to the nearest start site and the peak score. Then the feature classes per library as 100% bars, and the peaks around the nearest start site with the promoter window shaded: a promoter-bound factor puts most of its peaks there, a distal one spreads them over introns and intergenic space. The collapsed HOMER table has a peak record card beside it, which waits for a picked row.
Filters and components
Filters · Feature class and a Distance to TSS range on
homer_annotated_peaks.
| Section | What it holds |
|---|---|
| Annotation at a glance | 4 cards |
| Feature classes | 1 histogram |
| Distance to the nearest TSS | 1 advanced visualization |
| Peak annotation (collapsed) | HOMER peak annotation + a peak record card |
Peak calls · What do the libraries call at one genomic region?
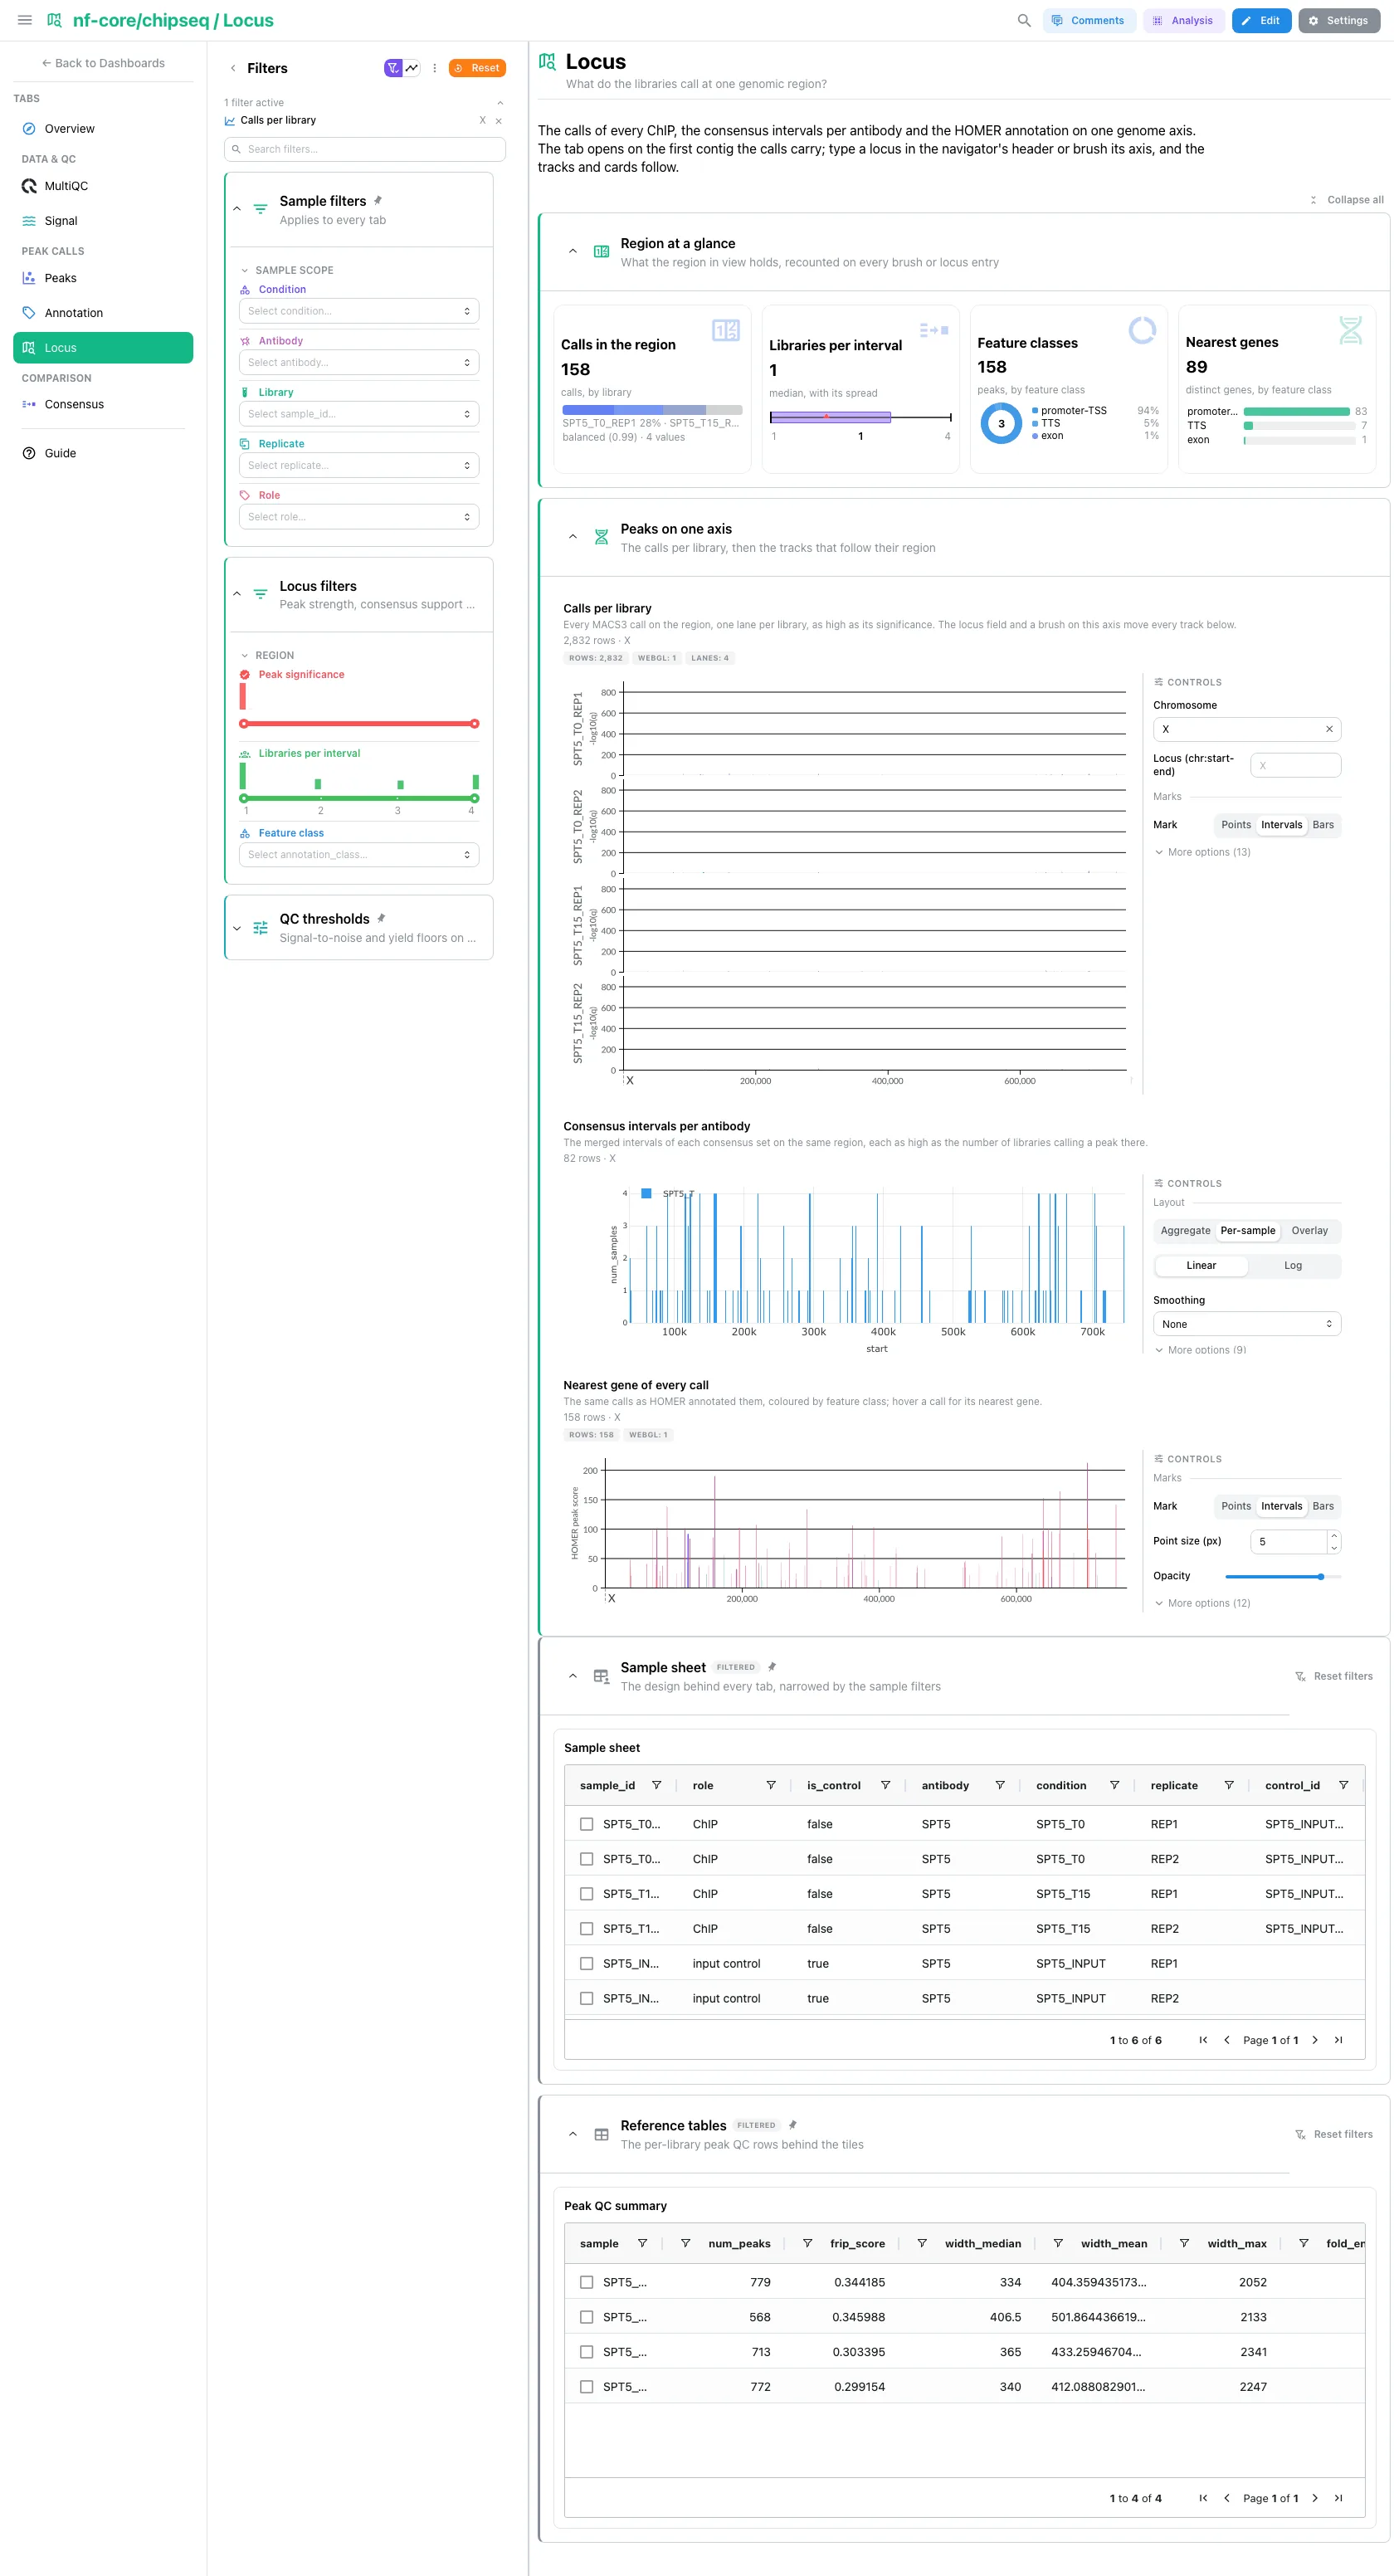
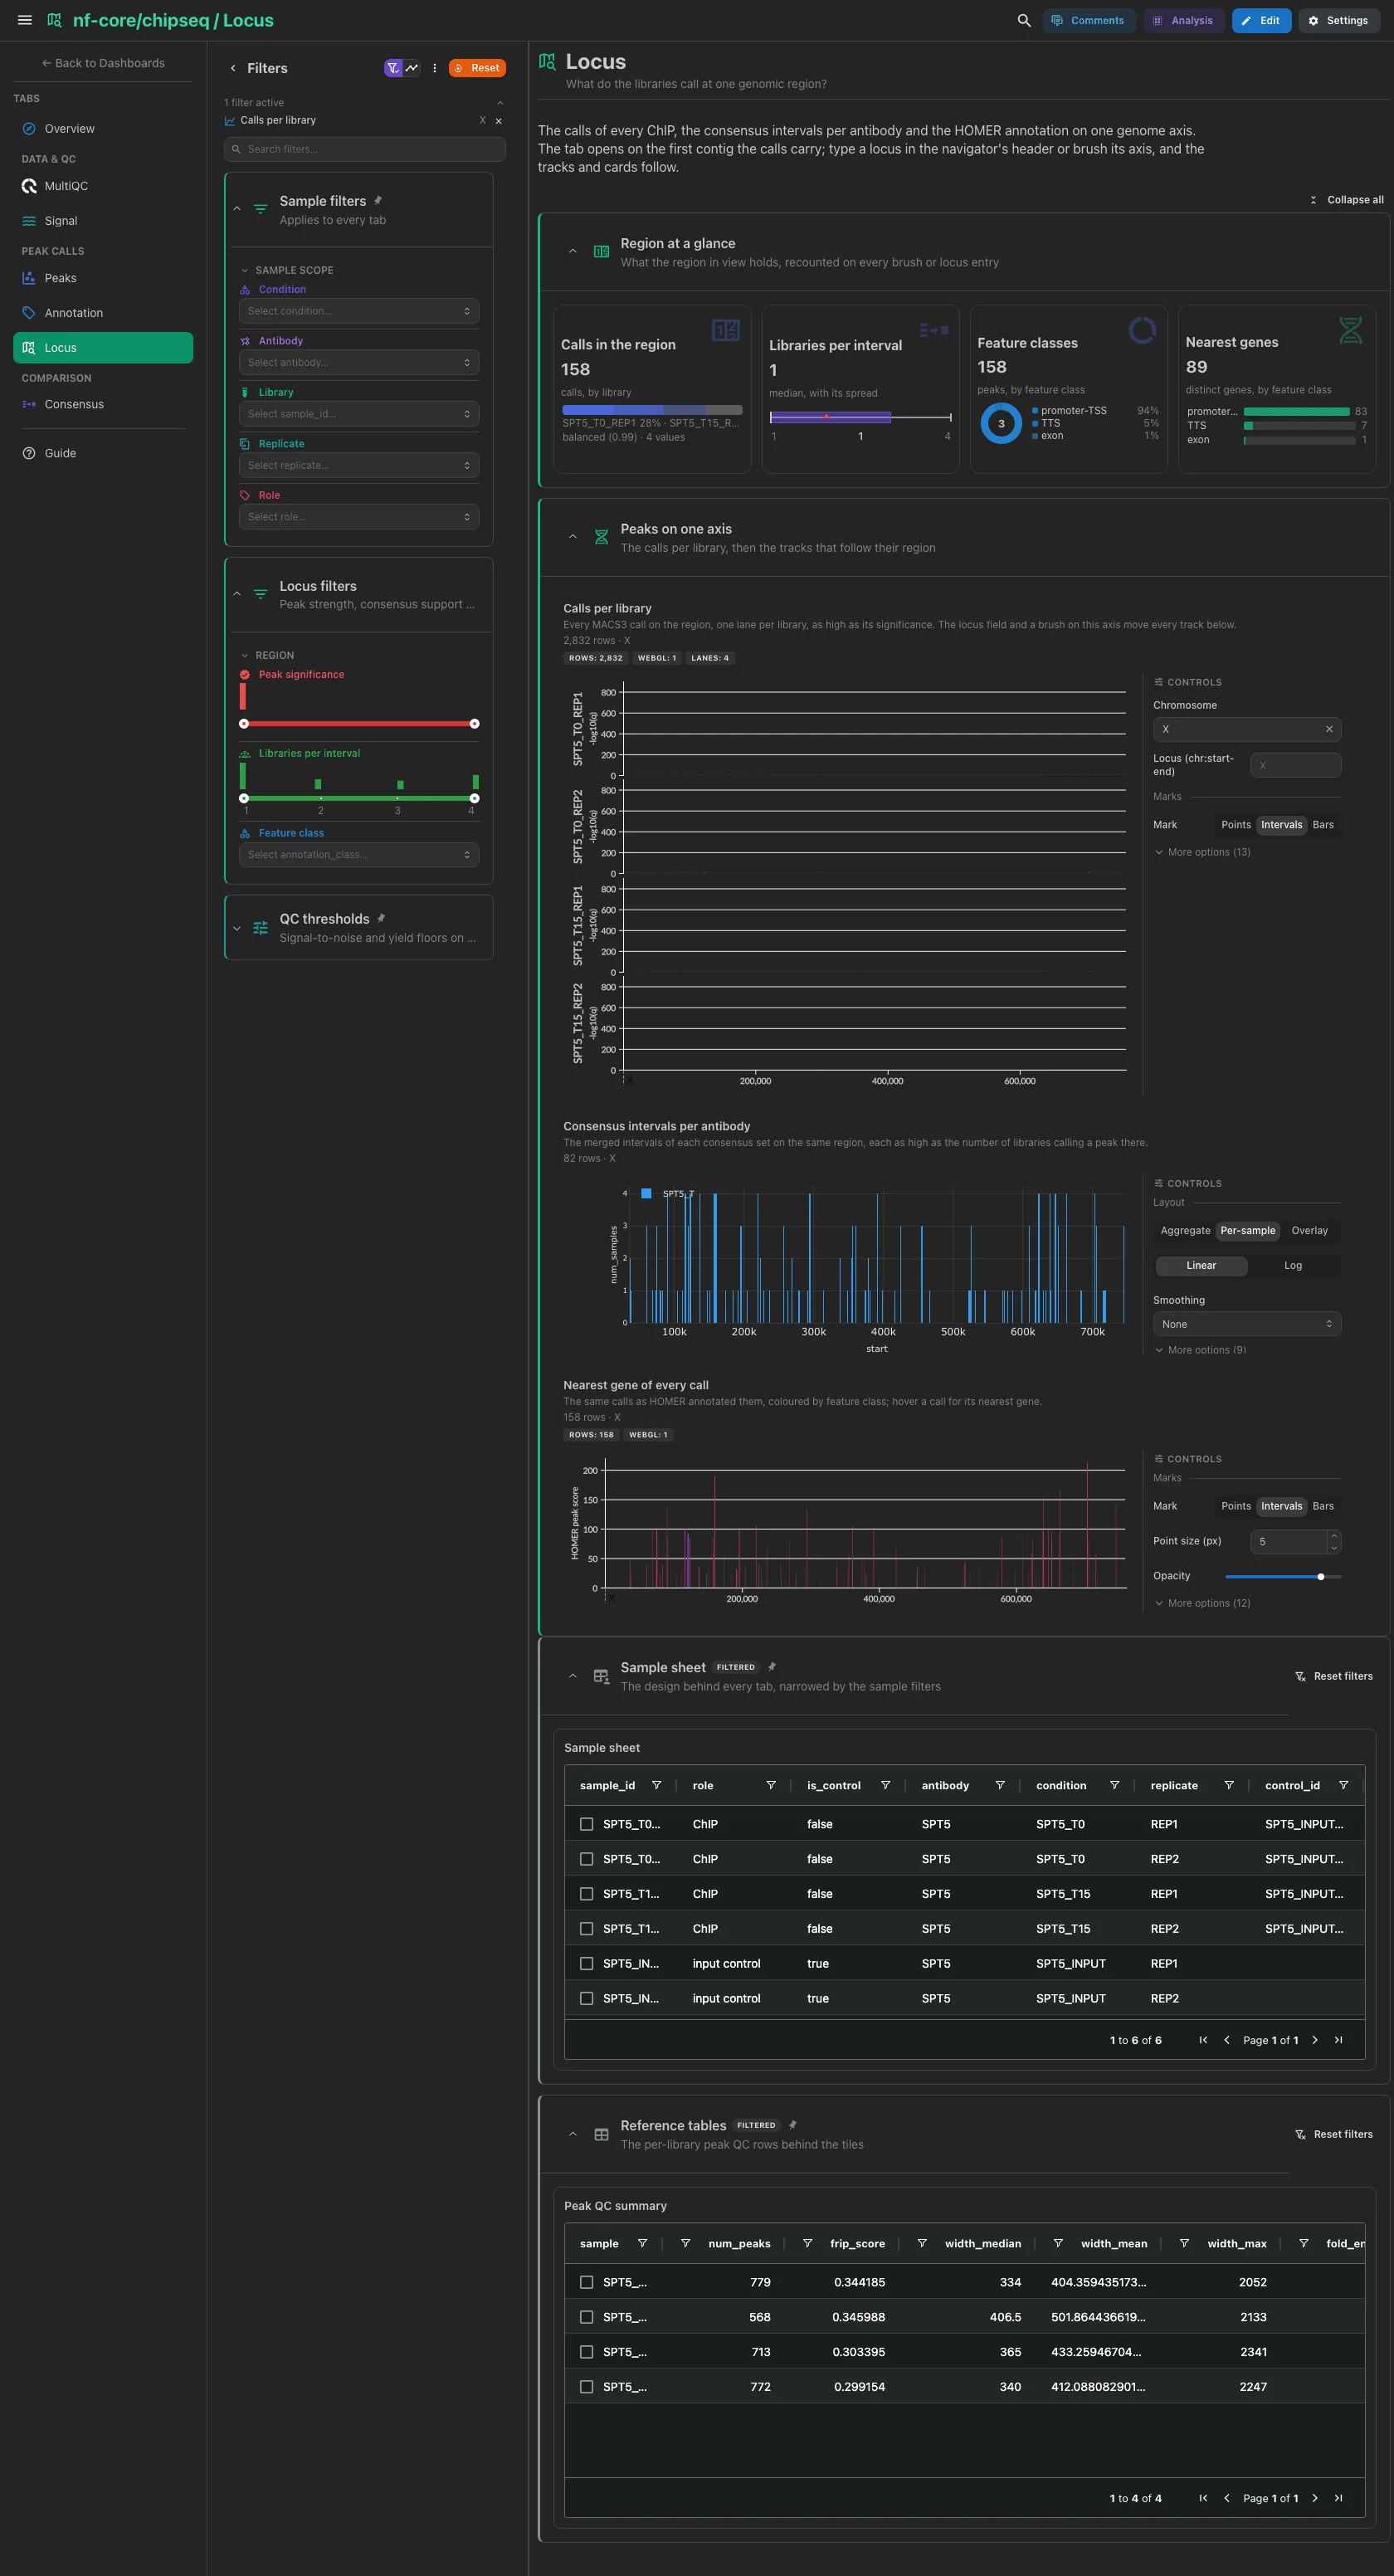
Three collections on one genome axis. The cards count what the region in view
holds and follow it as the tracks do. The navigator draws the calls, one lane
per library, and opens on the first contig the calls carry: type a locus in its
header or brush its axis, and the consensus intervals (one lane per consensus
set) and the HOMER annotation (coloured by feature class) follow. The HOMER
track stands in for a gene lane, so the locus field takes coordinates, not gene
symbols. With GENOME left empty the axis is laid out from the contigs of the
calls; a UCSC assembly name uses its built-in axis.
Filters and components
Filters · Peak significance on macs2_peaks, Libraries per
interval on macs2_consensus_boolean and Feature class on
homer_annotated_peaks.
| Section | What it holds |
|---|---|
| Region at a glance | 4 cards |
| Peaks on one axis | 3 advanced visualizations |
Comparison · Which peaks do the libraries agree on?
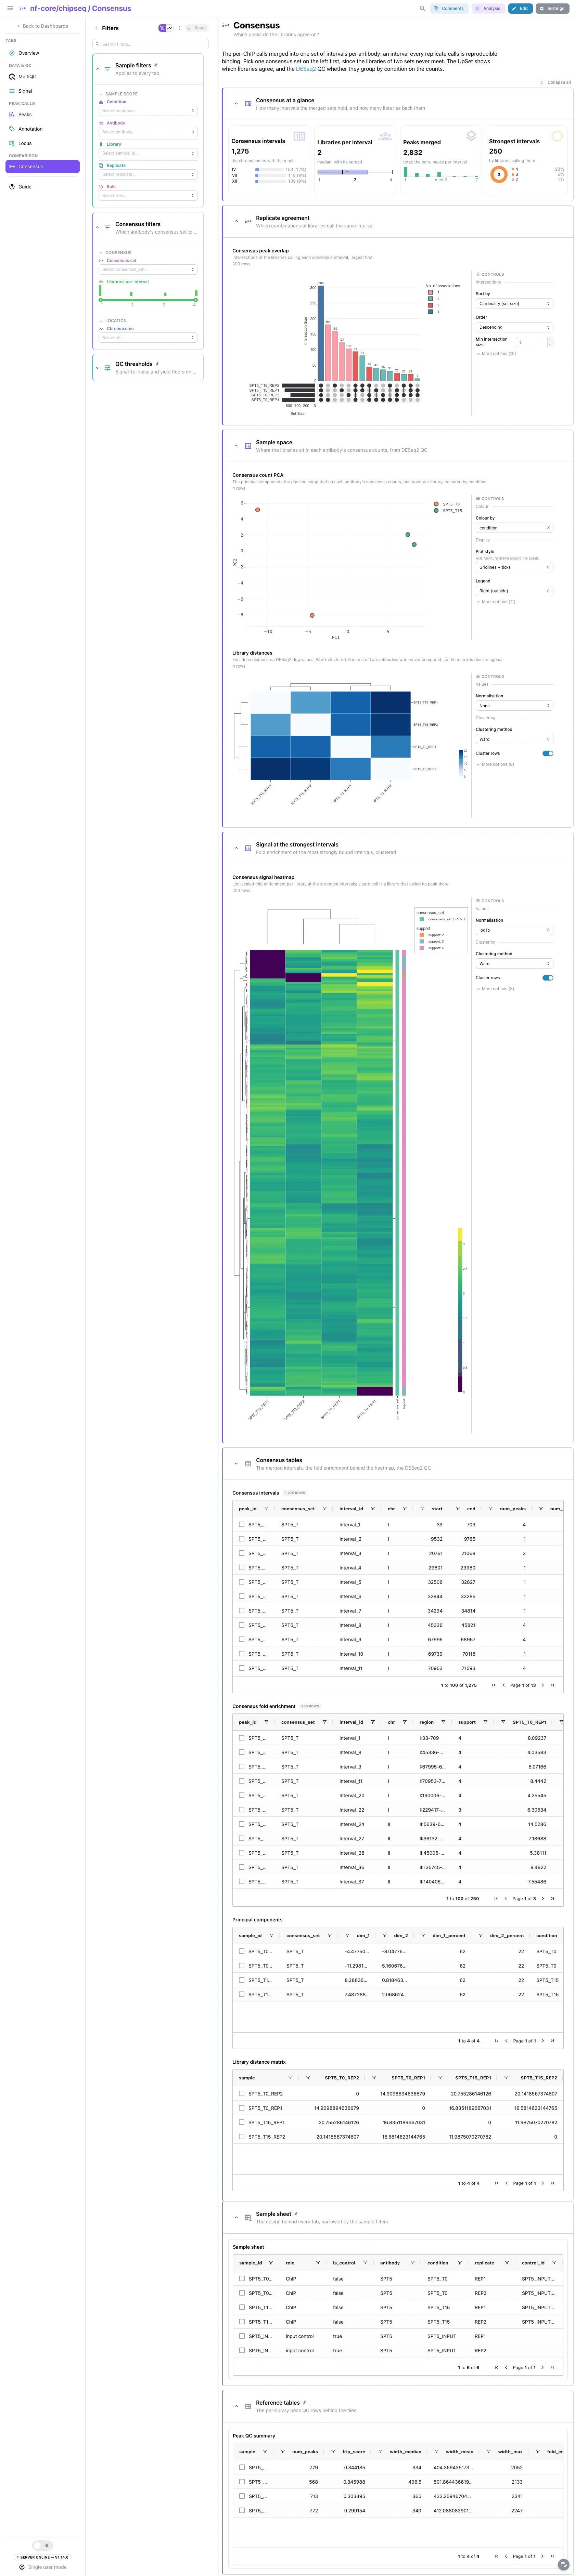
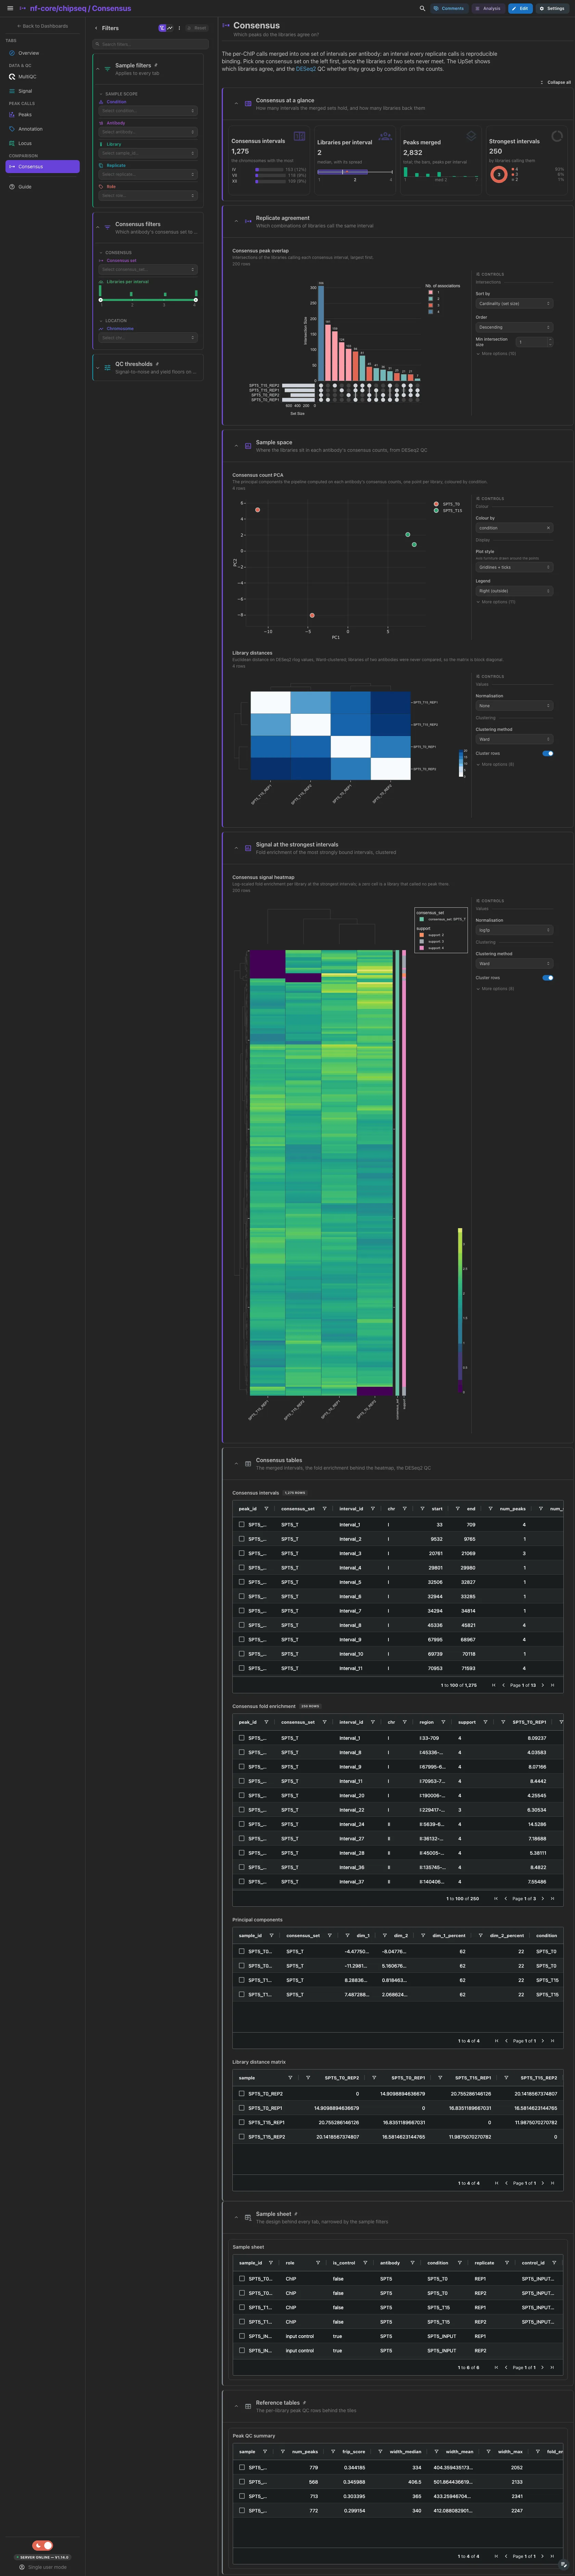
The per-ChIP calls merged into one set of intervals per antibody. The consensus intervals, the libraries per interval, the peaks merged and the support of the strongest intervals. Then the UpSet of the libraries calling each interval, and the sample space: the PCA the pipeline's DESeq2 QC computed on each antibody's consensus counts, coloured by condition, above the library distance heatmap. The fold-enrichment heatmap over the strongest intervals of each set sits folded below them.
Filters and components
Filters · Consensus set, a Libraries per interval range and
Chromosome, all on macs2_consensus_boolean.
| Section | What it holds |
|---|---|
| Consensus at a glance | 4 cards |
| Replicate agreement | 1 advanced visualization (UpSet) |
| Sample space | 2 advanced visualizations |
| Signal at the strongest intervals (collapsed) | 1 advanced visualization |
| Consensus tables (collapsed) | Consensus intervals, Consensus fold enrichment, Principal components, Library distance matrix |
Pick one consensus set first
chipseq writes one count matrix, and so one PCA and one distance matrix,
per antibody, and the libraries of two sets never meet. The UpSet
combinations, the PCA and the distance matrix only mean something once a
single Consensus set is selected. --skip_deseq2_qc writes neither QC
table: the Sample space section, its two tables and the Overview PCA then
drop.
Running the pipeline
Depictio reads the output of nf-core/chipseq, it does not run the pipeline. Run the pipeline first:
nextflow run nf-core/chipseq -r 2.1.0 \
  --input samplesheet.csv \
  --genome GRCh37 \
  --narrow_peak -profile docker
Then point Depictio at the results, regenerating the MultiQC report first if the run kept the release's MultiQC 1.23:
python -m depictio.dev_scripts.multiqc_reprocess --src results/ --dest results/
depictio ingest results/ --template nf-core/chipseq/latest --var GENOME=hg19
GENOME is optional: without it the Locus axis is built from the contigs of the
calls. GRCh37 is the iGenomes name of the UCSC hg19 assembly.
See nf-co.re/chipseq/usage for full pipeline documentation.
Required data structure
Point depictio ingest at the directory holding the pipeline output. Depictio scans
recursively and matches on file name, so the aligner directory and the peak-type
directory can differ from the tree below.
<DATA_ROOT>/
├── pipeline_info/
│   ├── samplesheet.valid.csv                      # the hub: one row per library
│   ├── params_<timestamp>.json                    # provenance
│   └── nf_core_chipseq_software_mqc_versions.yml
├── multiqc/narrow_peak/multiqc_data/
│   └── multiqc.parquet                            # or multiqc/multiqc_data/ after a reprocess
├── fastqc/zips/*_fastqc.zip                       # raw MultiQC inputs
├── trimgalore/{fastqc/zips,logs}/
└── bwa/merged_library/
    ├── samtools_stats/*.sorted.bam.{stats,flagstat,idxstats}
    ├── picard_metrics/*.{MarkDuplicates.metrics.txt,CollectMultipleMetrics.*}
    ├── phantompeakqualtools/*.spp.out
    ├── deepTools/
    │   ├── plotFingerprint/*.plotFingerprint.{qcmetrics,raw}.txt
    │   └── plotProfile/*.plotProfile.tab
    └── macs3/narrow_peak/
        ├── *_peaks.narrowPeak                     # or *_peaks.broadPeak
        ├── *_peaks.annotatePeaks.txt              # HOMER annotation
        ├── qc/*.summary.txt                       # per-sample peak QC
        └── consensus/<antibody>/
            ├── *.consensus_peaks.boolean.txt      # per-antibody consensus set
            └── deseq2/*.consensus_peaks.{pca.vals,sample.dists}.txt  # optional
Validation runs
No AWS megatest is pinned for 2.1.0: every 2.x prefix in the bucket is a
truncated sync. The template was validated on EMBL HPC runs of the release
instead (keys chipseq2-*): the test profile with --narrow_peak under each of
the four aligners (bwa, bowtie2, chromap and STAR), one antibody against its
inputs. The broadPeak route, several antibodies and the preseq route are not
covered by those runs: the broadPeak branch of recipes/peaks.py is covered by a
synthetic check only, and the preseq card, filter and curves by the offline
validation only. The megatest design (test_full) has not been run against this
layout. The screenshots above come from a test_full run of an earlier,
four-tab layout of the dashboard; the current layout has not been captured yet.
megatest.yaml lists the tables-only subset of a run the template needs, so a
usable S3 run can be pinned later without rewriting it. The wrapper below fetches
that subset, and has nothing complete to mirror until such a run exists:
Do not pass --project when ingesting: the dashboard is attached to the
project by name, so renaming it breaks a later depictio dashboard import.
Re-ingesting accumulates dashboards, so delete the project before repeating a run.
Additional resources
- nf-co.re/chipseq: official pipeline documentation
- nf-co.re/chipseq/2.1.0/results: AWS test results
- Template System Reference: YAML format, variables, conditionals
- Recipes: how to read, test, and write recipes
Authorship
 weber8thomas
Reviewing a template on your own data, or taking over a role here, is a contribution in itself: the contributing guide says what each one involves.