
The rnavar template follows an nf-core/rnavar run from the alignment to where the calls fall on the genome:
- Overview: the run in four key figures, live findings and figures, each linked to the tab that explains it
- Data & QC: the MultiQC report, how the reads aligned, spliced and deduplicated, and how deep and where they cover the genome
- Variants: the callset per sample, what the calls change in the genes (snpEff route), and a genome view of the variants replicates share, over the reads
The persistent Sample filters (the design group and the sample) sit in the left
panel and narrow every tab through the sample hub.
The design table is optional
rnavar does not publish its samplesheet, and the samplesheet has no design
column, so the design is a table you pass (METADATA_FILE: the sample id in a
sample column, every other column a factor). Without it the group filter,
the group colours and the replicate agreement fall away, and every tile keeps
working on one constant group.
The BAMs are never ingested as tables
The alignments (14 to 21 GB each on the test run) are opened only by the
genome browser, in place (TRACKS_URI) or uploaded. The numbers come from
STAR's, Picard's and samtools' reports, the VCFs and the MultiQC report.
Quick start
depictio ingest /path/to/rnavar_results \
  --template nf-core/rnavar/latest \
  --var METADATA_FILE=/path/to/design.tsv
The results directory is the only required value. METADATA_FILE is the
optional design table above.
| Variable | Default | Role |
|---|---|---|
METADATA_FILE |
unset | design table; without it the group filter, colours and splits fall away |
GROUP_COL |
first factor column of the design table | column the dashboard groups and filters samples by |
GENOME |
hg38 |
UCSC name of the assembly, which lays out the Genome tab axis and gene lane; rnavar's --genome GRCh38 is chr-prefixed, so hg38 fits, and none drops the gene lane only |
TRACKS_URI |
unset | s3:// or https:// folder holding the run's results: the browser then reads the VCFs and BAMs in place; unset, the files under the results directory are uploaded |
depictio config nextflow --install     # once per machine
nextflow run nf-core/rnavar -r 1.3.0 -profile docker --outdir results
No depictio ingest, and no template named: the pipeline ingests its own
output directory when it finishes and resolves this template from its own
manifest. See Nextflow trigger. The
trigger passes no --var, so the run has no design table.
Reference
The template reads STAR's final log and splice junctions, Picard MarkDuplicates, samtools stats and idxstats, the HaplotypeCaller VCFs, the snpEff output when the run annotated, and the native MultiQC report (no regeneration needed). rnavar writes each sample's calls twice, as called and after VariantFiltration: the template reads the filtered VCF, or the unfiltered one when the run skipped filtration, so no call is counted twice.
Self-adapting layout
The dashboard adapts to whatever the run actually produced: components bound
to pruned or unparsed data collections are hidden, tabs left with no real
visualizations are dropped entirely, and the remaining components are
re-packed so there are no empty rows. Without --tools snpeff the Annotation
tab, its pipeline step and its tile in the tab list go.
Template variables
Variables you provide when running the template: DATA_ROOT is the results directory given to depictio ingest, the others are set with --var NAME=value:
| Variable | Required | Description |
|---|---|---|
DATA_ROOT |
✓ | Root directory of one rnavar run (reports/, variant_calling/, annotation/, pipeline_info/). |
METADATA_FILE |
— | Optional design table (TSV): sample id in a column named sample (or in the first column), one column per factor such as a cell line or condition. Joined into the sample hub: enables the design filters, the group colours and the group splits. |
METADATA_ID_COL |
— | Design table sample-id column. Auto-detected as the first column; defaults to 'sample'. |
GROUP_COL |
— | Design column the dashboards group and filter samples by. Auto-detected as the first factor column of METADATA_FILE. |
GENOME |
— | UCSC name of the assembly the run was aligned to (hg38, mm10): the axis and gene lane of the Genome tab. Use none for an assembly without chr-prefixed contigs. |
TRACKS_URI |
— | s3:// or https:// folder holding the run's results (the folder DATA_ROOT mirrors), to read the genome-browser tracks (VCF, BAM) in place instead of uploading them from DATA_ROOT. |
Auto-detected (set from the run's metadata / params.json; the route flags drive Conditional routes below): GROUP_COL_DISPLAY, ANNOTATION_COLS
Data collections
28 data collections — 13 required 15 optional · 11 direct 17 derived.
Origin tells you whether a collection is real pipeline data or a reshape of it: direct = a pipeline output (scanned, or a recipe that reads raw files); derived = a recipe that reshapes one or more direct collections into the layout a visualization needs (no new measurement). Reads shows what produces it: a recipe .py transform, or a raw file scanned off disk. (A direct collection can still have a recipe — one that merely parses/cleans the raw file; derived means the recipe reshapes another collection.)
| Tag | Origin | Type | Reads | Status |
|---|---|---|---|---|
metadata |
direct | Table | file |
optional |
multiqc_data |
direct |  MultiQC |
file |
required |
star_log_final |
direct | Table | recipe |
optional |
star_junctions |
direct | Table | recipe |
optional |
picard_markduplicates_metrics_raw |
direct | Table | file |
optional |
picard_markduplicates_metrics |
derived | Table | recipe |
optional |
samtools_stats_raw |
direct | Table | file |
optional |
samtools_stats_sections |
derived | Table | recipe |
optional |
samtools_idxstats |
direct | Table | recipe |
optional |
vcf_calls_raw |
direct | Table | file |
required |
vcf_variants |
derived | Table | recipe |
required |
vcf_callset_summary |
derived | Table | recipe |
required |
vcf_substitution_spectrum |
derived | Table | recipe |
required |
vcf_filter_breakdown |
derived | Table | recipe |
required |
vcf_callset_nodesign |
derived | Table | recipe |
required |
snpeff_ann_vcf_raw |
direct | Table | file |
optional |
snpeff_ann_variants |
derived | Table | recipe |
optional |
snpeff_csv_raw |
direct | Table | file |
optional |
snpeff_csv_stats |
derived | Table | recipe |
optional |
snpeff_genes_raw |
direct | Table | file |
optional |
snpeff_genes |
derived | Table | recipe |
optional |
samples |
derived | Table | recipe |
required |
variant_windows |
derived | Table | recipe |
required |
shared_variants |
derived | Table | recipe |
required |
replicate_sharing |
derived | Table | recipe |
required |
vcf_allele_fractions |
derived | Table | recipe |
required |
sample_concordance |
derived | Table | recipe |
required |
tracks |
derived | genomic_tracks | recipe |
optional |
Conditional routes
Rows are data collections; columns are the variables you set or params.json flags auto-detected from the run. Each filled cell is the effect of setting that variable; an empty cell means that variable leaves the collection unchanged. (24 collections are unaffected by any variable — present on every run.)
+ included− removed⇄ repointed
| Data collection | METADATA_FILE |
TRACKS_URI |
|---|---|---|
metadata |
+ | |
vcf_callset_nodesign |
− | |
replicate_sharing |
+ | |
tracks |
⇄ |
Cross-DC links
26 links — selecting a value in the source collection filters the target. The join column is shown after the source.
| Source · column | Target | Filters | |
|---|---|---|---|
samples · sample |
→ | multiqc_data |
Filter every MultiQC panel by the samples picked in the left panel |
samples · sample |
→ | star_log_final |
Filter the STAR alignment summary by the samples picked in the left panel |
samples · sample |
→ | star_junctions |
Filter the splice junctions by the samples picked in the left panel |
samples · sample |
→ | picard_markduplicates_metrics |
Filter the duplication metrics by the samples picked in the left panel |
samples · sample |
→ | samtools_stats_sections |
Filter the samtools stats histograms by the samples picked in the left panel |
samples · sample |
→ | samtools_idxstats |
Filter the reads per contig by the samples picked in the left panel |
samples · sample |
→ | vcf_variants |
Filter the calls by the samples picked in the left panel |
samples · sample |
→ | vcf_callset_summary |
Filter the callset summary by the samples picked in the left panel |
samples · sample |
→ | vcf_callset_nodesign |
Filter the Ts/Tv card of a run with no design table by the samples picked in the left panel |
samples · sample |
→ | vcf_substitution_spectrum |
Filter the substitution spectrum by the samples picked in the left panel |
samples · sample |
→ | vcf_filter_breakdown |
Filter the FILTER breakdown by the samples picked in the left panel |
samples · sample |
→ | snpeff_ann_variants |
Filter the annotated calls by the samples picked in the left panel |
samples · sample |
→ | snpeff_csv_stats |
Filter the snpEff composition by the samples picked in the left panel |
samples · sample |
→ | snpeff_genes |
Filter the per-gene burden by the samples picked in the left panel |
vcf_filter_breakdown · filter_label |
→ | vcf_variants |
Carry the FILTER value picked on the Callset tab over to the calls |
snpeff_genes · gene_name |
→ | snpeff_ann_variants |
Narrow the annotated calls to the gene picked in the burden table |
variant_windows · chrom |
→ | vcf_variants |
A region typed or brushed on the variant navigator narrows the call track and the region cards |
star_log_final · sample |
→ | samples |
Carry the samples kept by the Alignment tab's STAR sliders to the hub and on to every per-sample tile |
samples · sample |
→ | tracks |
Show the genome tracks of the samples picked |
tracks · sample |
→ | samples |
Narrow the sample hub to the samples picked in the genome browser |
samples · {GROUP_COL} |
→ | replicate_sharing |
Filter the replicate agreement by the design groups picked in the left panel |
samples · {GROUP_COL} |
→ | variant_windows |
Draw only the navigator lanes of the design groups picked in the left panel |
samples · {GROUP_COL} |
→ | shared_variants |
Step the browser through the shared variants of the design groups picked in the left panel |
shared_variants · {GROUP_COL} |
→ | tracks |
Show the tracks of the design group a shared variant belongs to |
samples · sample |
→ | vcf_allele_fractions |
Filter the allele-fraction distribution by the samples picked in the left panel |
samples · sample |
→ | sample_concordance |
Filter the genotype concordance matrix by the samples picked in the left panel |
Recipes
Each recipe reshapes raw pipeline output into a tidy table. The name links to its source; Output lists the validated OUTPUT_SCHEMA columns.
| Recipe | Transforms | Output |
|---|---|---|
nf-core/rnavar/allele_fractions.py |
nf-core/rnavar allele-fraction distribution: each sample's PASS calls over the allele fraction. | sample, variant_type, depth_class, vaf_bin, vaf, calls |
nf-core/rnavar/replicate_sharing.py |
nf-core/rnavar replicate agreement: the PASS sites of a design group that every replicate calls. | samples, sites, shared_sites, shared_pct |
nf-core/rnavar/sample_concordance.py |
nf-core/rnavar genotype concordance: how alike two samples' PASS genotypes are. | sample |
nf-core/rnavar/samples.py |
nf-core/rnavar sample hub: one row per sample, from the reads to the calls. | sample, input_reads, uniquely_mapped_pct, multimapped_pct, unmapped_pct, mismatch_rate_pct, splices_annotated_pct, novel_junction_pct, duplication_pct, bases_10x_pct, mito_reads_pct, chry_reads_pct, other_contig_reads_pct, pass_calls, snvs, indels, pass_pct, filtered_pct, ts_tv, het_hom_ratio, median_dp |
nf-core/rnavar/shared_variants.py |
nf-core/rnavar shared variants: the PASS sites of each design group and how many replicates call them. | chrom, pos, end, variant_key, ref, alt, variant_type, sharing, n_calling, samples, min_dp, median_vaf, best_qual, carriers, support_score |
nf-core/rnavar/tracks.py |
Genome-browser track manifest: the HaplotypeCaller VCF and the BAM of every sample. | track_id, sample, format, uri, name, category, order |
nf-core/rnavar/variant_windows.py |
nf-core/rnavar Genome tab navigator: PASS variants in 1 Mb windows, one lane per design group. | chrom, pos, end, variants, calls, samples, snv_pct |
nf-core/rnavar/variants.py |
nf-core/rnavar variant calls: one row per call, from the filtered VCF of each sample. | sample, caller, chrom, pos, variant_key, ref, alt, variant_type, qual, filter_status, is_pass, gt, dp, vaf, stage |
picard/markduplicates_metrics.py |
Duplication metrics from a Picard MarkDuplicates report. | sample, library, unpaired_reads_examined, read_pairs_examined, unmapped_reads, unpaired_read_duplicates, read_pair_duplicates, read_pair_optical_duplicates, duplicate_reads, reads_after_dedup, percent_duplication, estimated_library_size |
samtools/idxstats.py |
Reads per contig, per sample, from samtools idxstats. |
sample, stage, contig, contig_class, length, mapped_reads, mapped_pct, reads_per_mb |
samtools/stats_sections.py |
The distribution sections of a samtools stats report, as one long table. |
sample, section, series, metric, bin, n_reads, n_bases, n_indels, n_pairs, reads_total, reads_mapped, reads_mapped_pct, bases_mapped, error_rate, identity_pct, average_length, maximum_length, average_quality, supplementary_alignments |
snpeff/ann_variants.py |
One row per annotated variant call, read from SnpEff's annotated VCF. | sample, caller, chrom, pos, variant_key, ref, alt, variant_type, qual, filter_status, is_pass, gt, dp, vaf, gene, gene_id, impact, consequence, hgvs_p, aa_pos |
snpeff/csv_stats.py |
The composition sections of SnpEff's CSV summary, melted into one long frame. | sample, caller, section, category, count, percent |
snpeff/genes.py |
Per-gene variant counts by impact class, from SnpEff's gene effect table. | sample, caller, gene_name, gene_id, biotype, n_high, n_low, n_moderate, n_modifier, n_variants, n_coding |
star/junctions.py |
Splice junctions per sample, by intron motif and annotation, from STAR's SJ.out.tab. |
sample, motif_class, motif_order, annotation, junctions, unique_reads, multimapping_reads, junctions_pct, unique_reads_pct |
star/log_final.py |
One row per sample from STAR's Log.final.out. |
sample, input_reads, avg_input_read_length, uniquely_mapped, uniquely_mapped_pct, multimapped, multimapped_pct, too_many_loci_pct, unmapped_pct, mapped_pct, avg_mapped_length, splices_total, splices_annotated, splices_annotated_pct, splices_noncanonical, splices_noncanonical_pct, mismatch_rate_pct, deletion_rate_pct, insertion_rate_pct, chimeric_pct |
vcf/callset_summary.py |
One row per callset (sample and caller): what a germline callset is judged on. | sample, caller, calls, pass_calls, pass_pct, snvs, indels, mnps, multiallelic, transitions, transversions, ts_tv, het, hom_alt, het_hom_ratio, median_qual, median_dp, median_het_vaf |
vcf/filter_breakdown.py |
How each caller's own FILTER column partitions its calls, per callset. | sample, caller, filter_label, is_pass, failed_filters, calls, calls_pct, snvs, indels |
vcf/substitution_spectrum.py |
SNV substitution spectrum per callset, folded onto the six pyrimidine classes. | sample, caller, callset, substitution_class, mutation_class, count, fraction |
Dashboard tabs
One dashboard: the Overview, then six child tabs in two groups, read as a funnel from the reads to where the calls fall on the genome. Each tab below carries the same icon and colour the dashboard gives it, so the page and the app read alike.
| Group | Tabs |
|---|---|
| Data & QC | MultiQC, Alignment, Coverage |
| Variants | Callset, Annotation, Genome |
Each child tab opens with a short intro and a strip of four cards, then at most three open sections; tables follow, collapsed. The Sample sheet is pinned, collapsed, to the bottom of every child tab.
Germline variant calling from RNA-seq, from the alignment to the annotated calls.
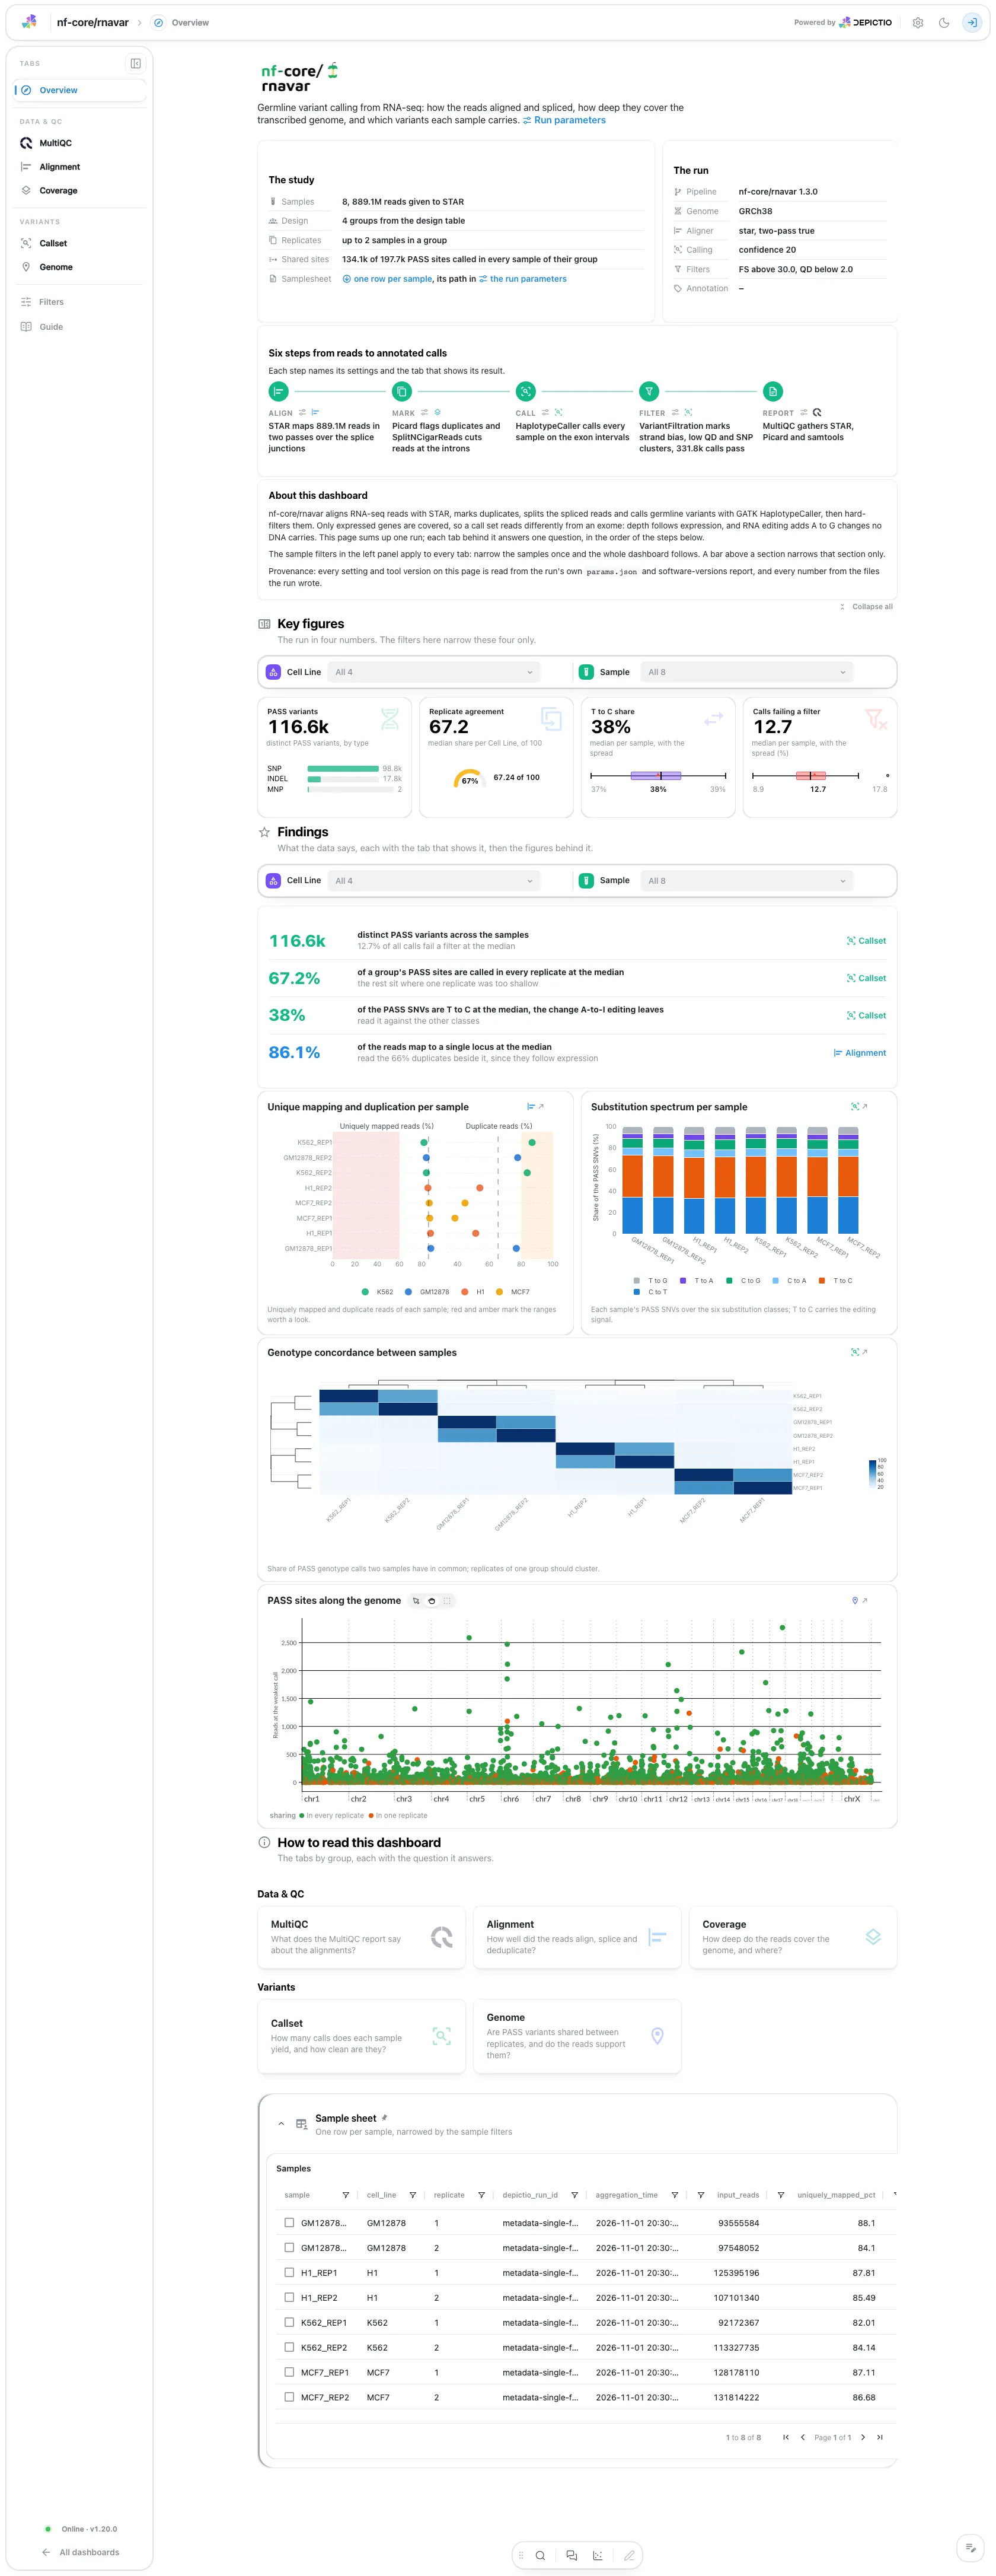
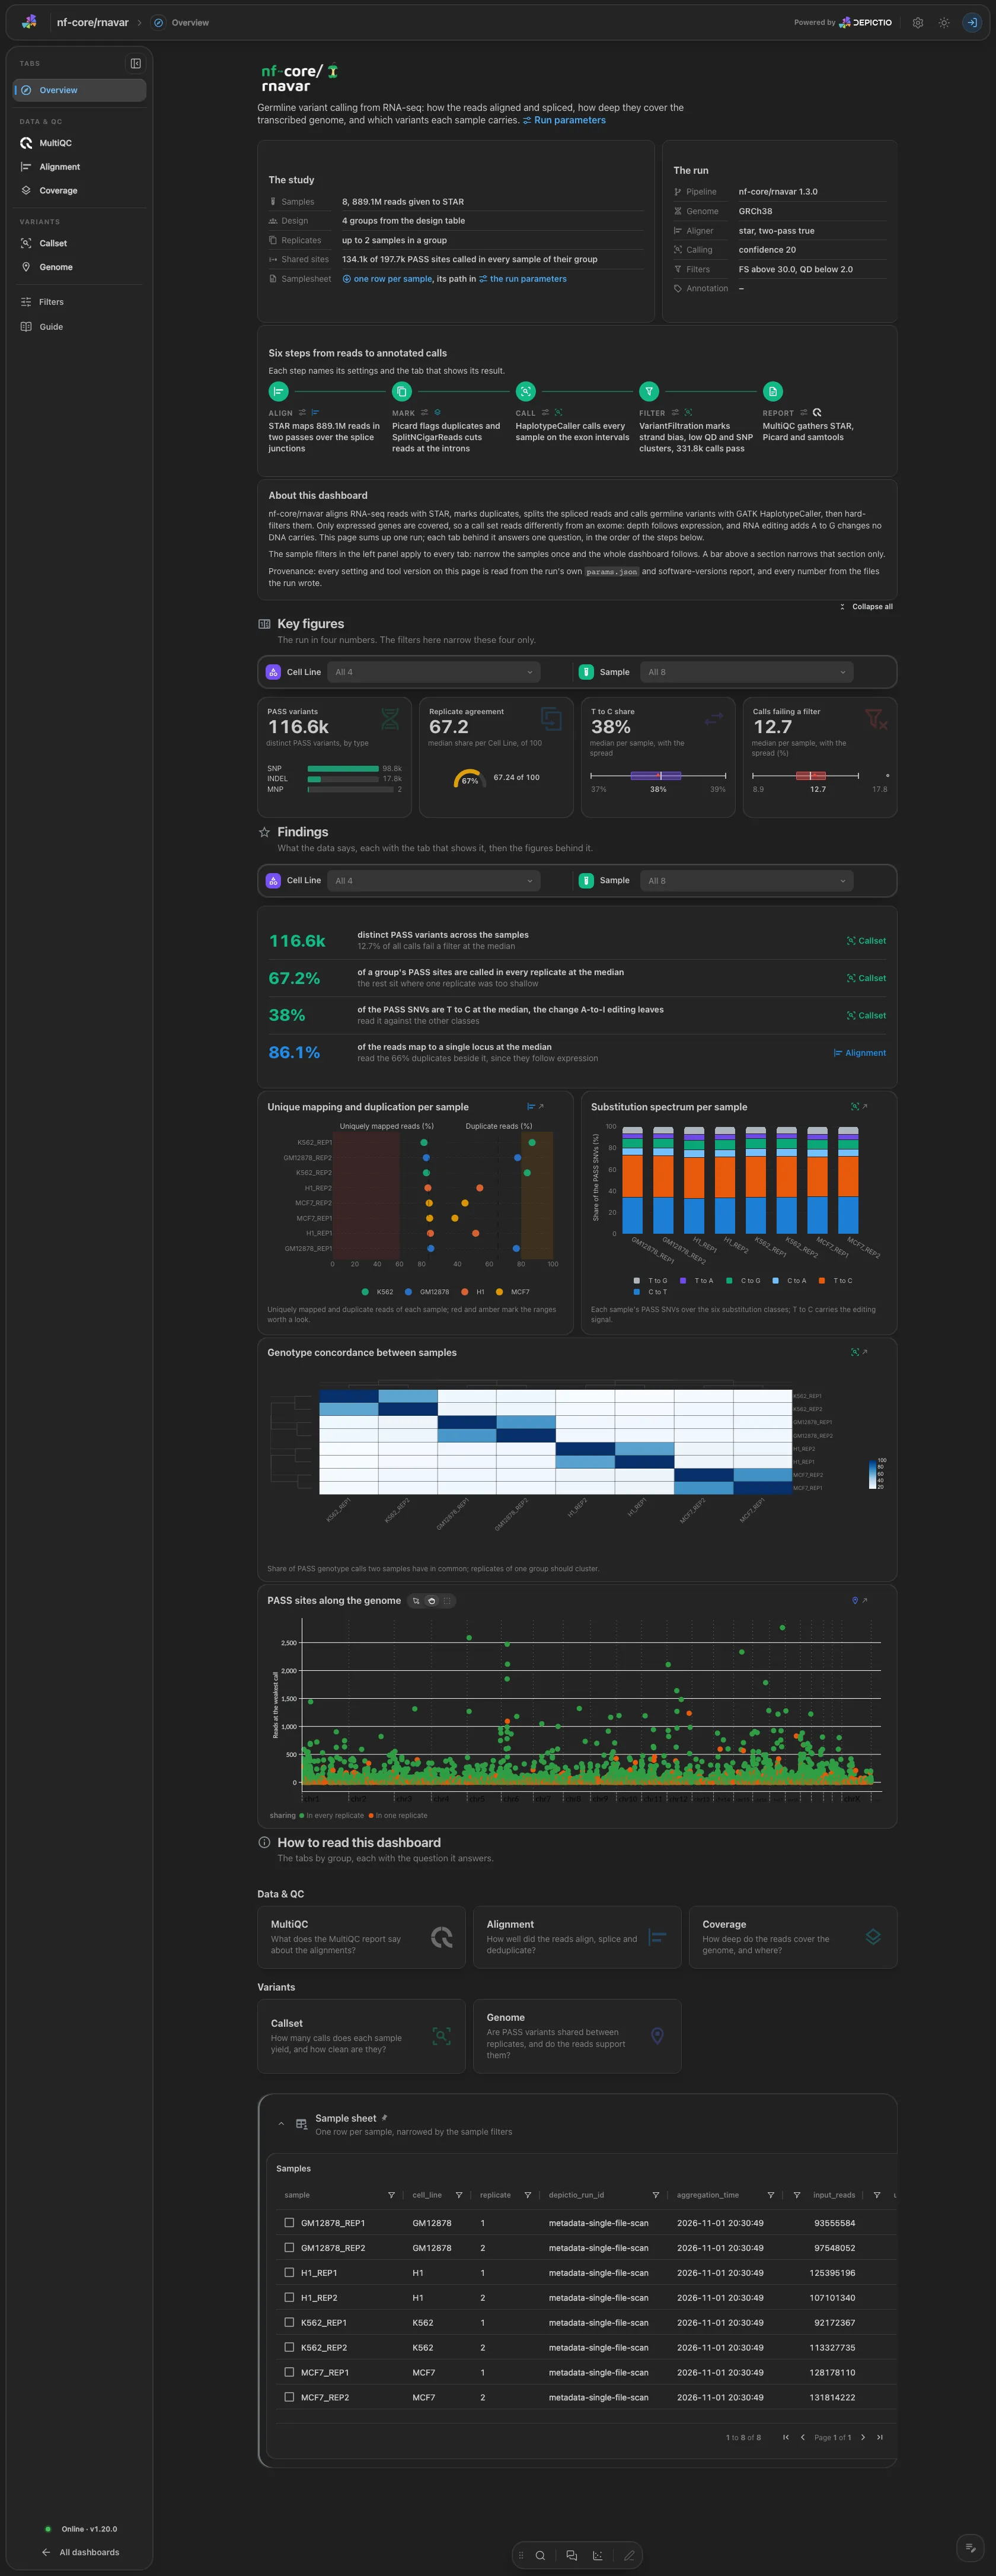
The run reads the genome, aligner, calling confidence, filter thresholds and annotation tools from the run parameters, and Pipeline walks six steps (Align, Mark, Call, Filter, Annotate, Report), each linked to its settings and its tab. Four key figures: PASS variants, replicate agreement (a Ts/Tv card without a design table), the T to C share of the PASS SNVs and the calls failing a filter. The findings are live rows plus three figures: unique mapping and duplication per sample, the substitution spectrum and the sample-by-sample genotype concordance.
Data & QC · What does the MultiQC report say about the alignments?
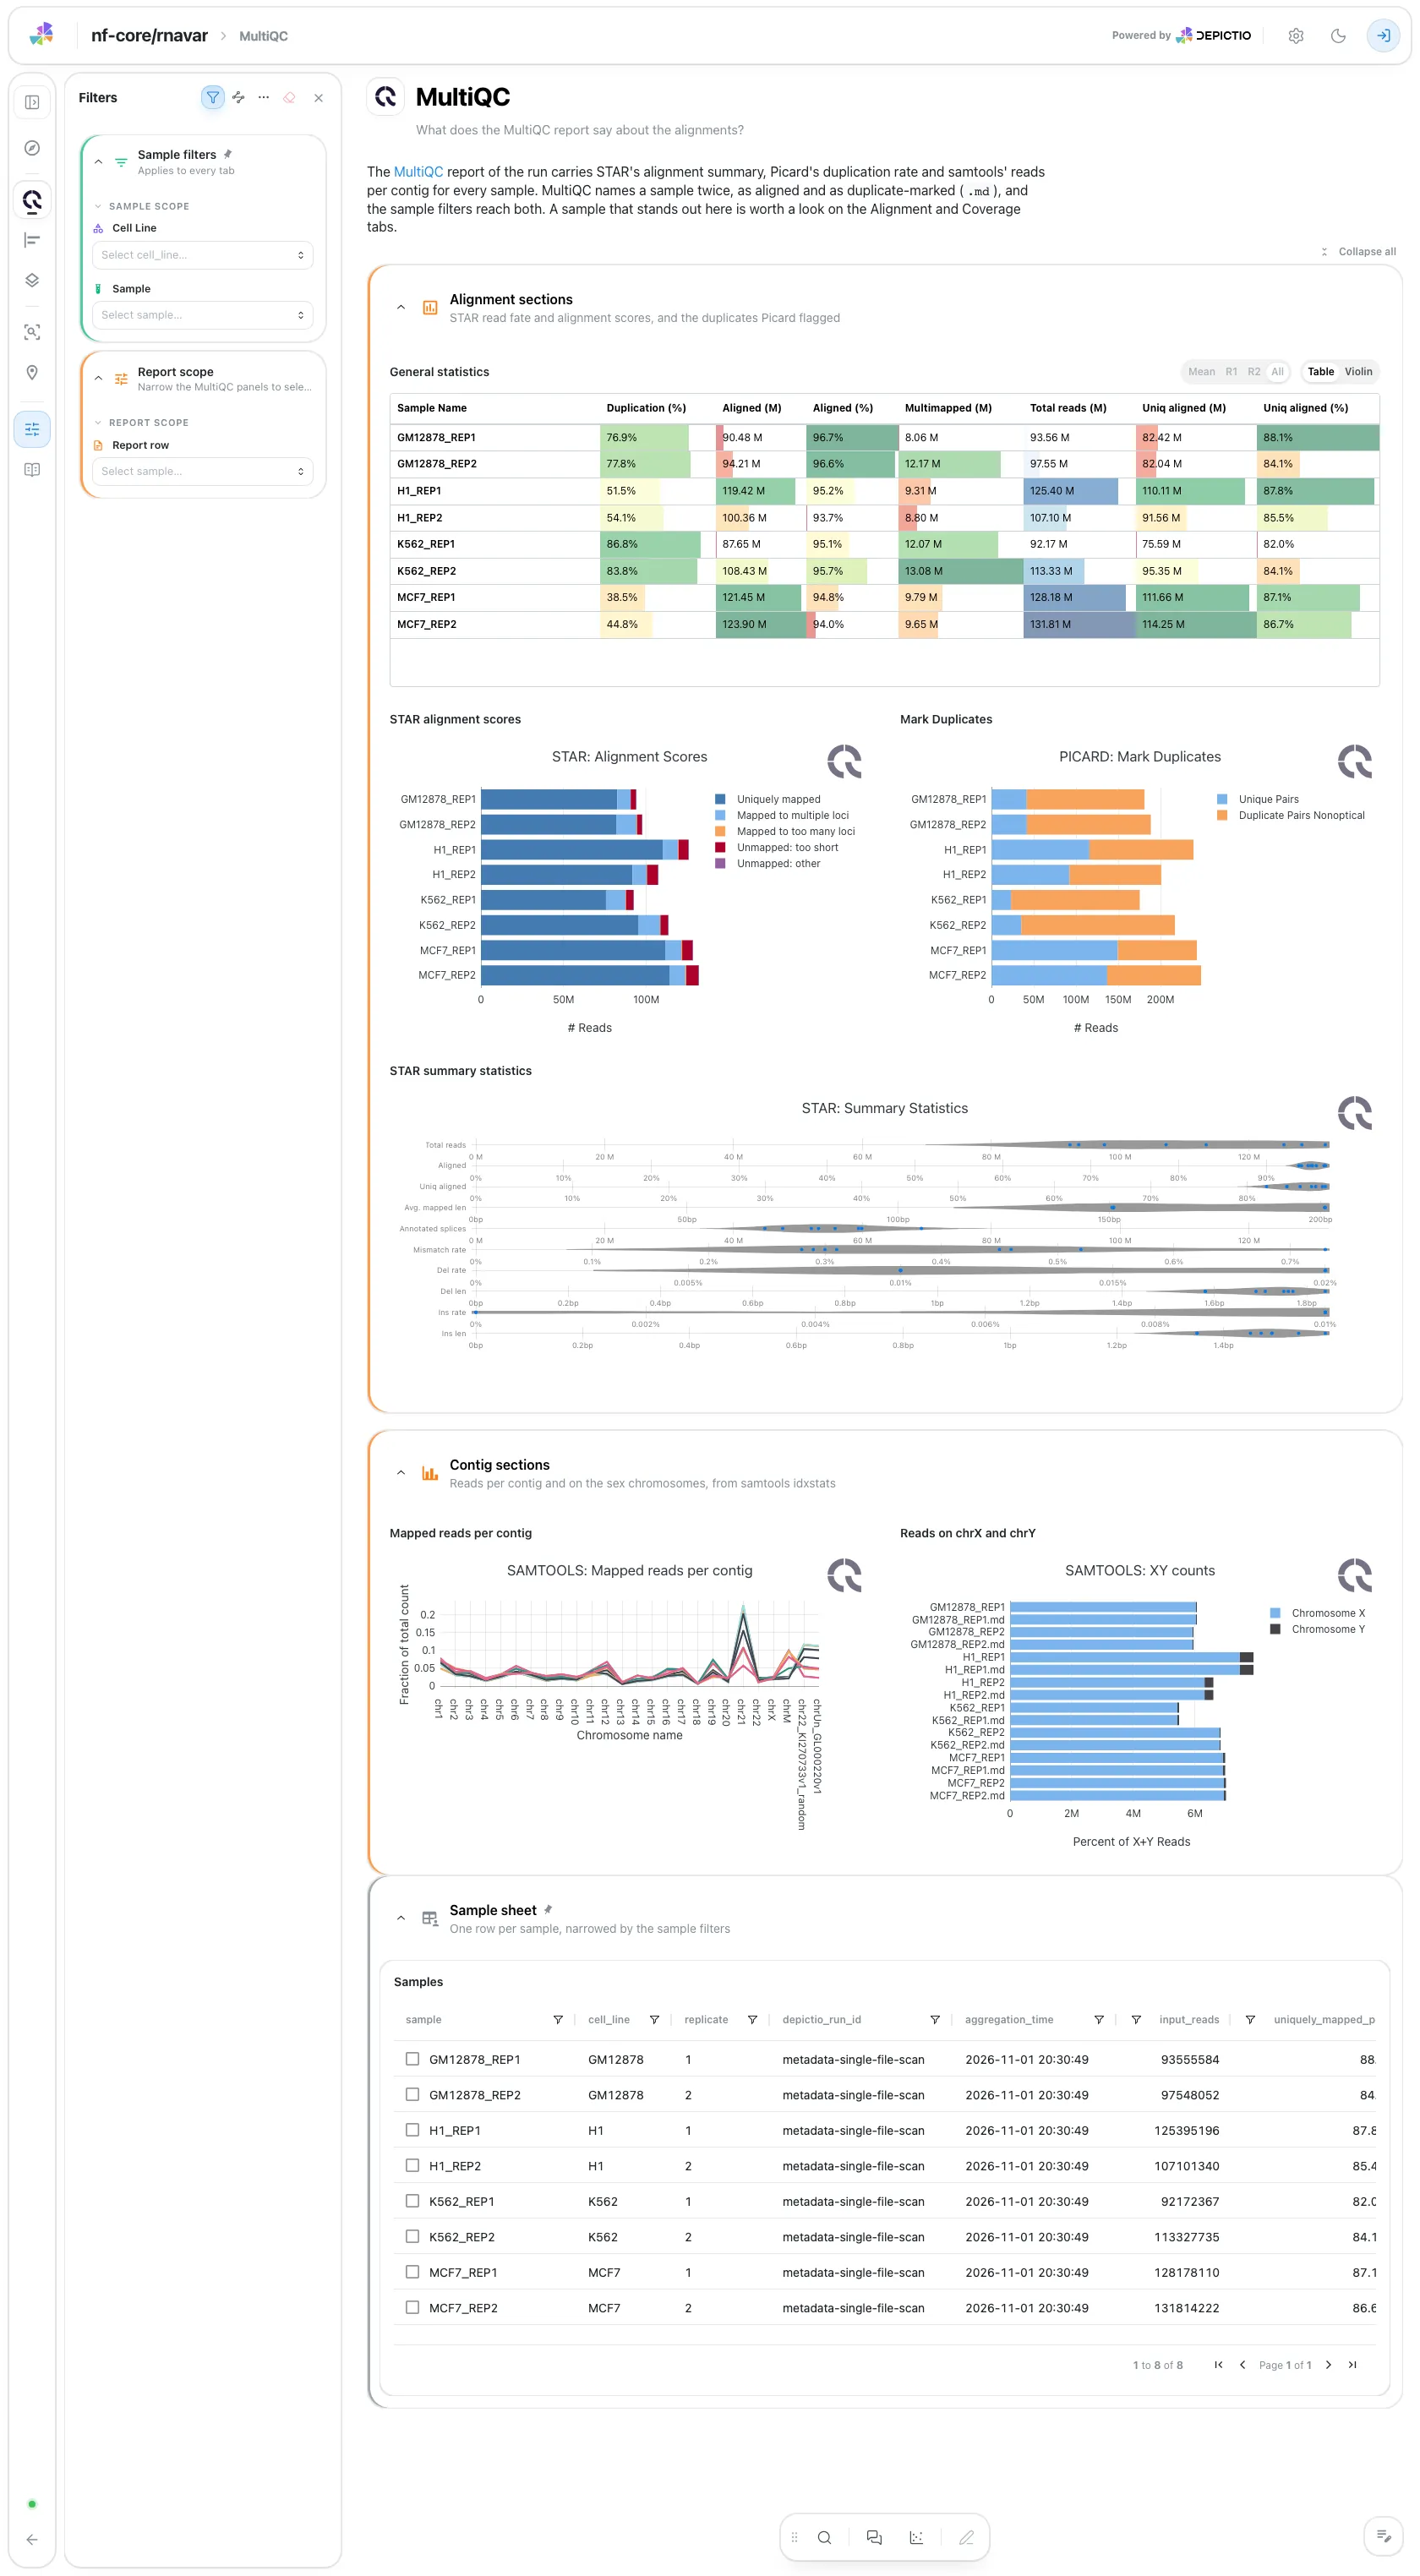
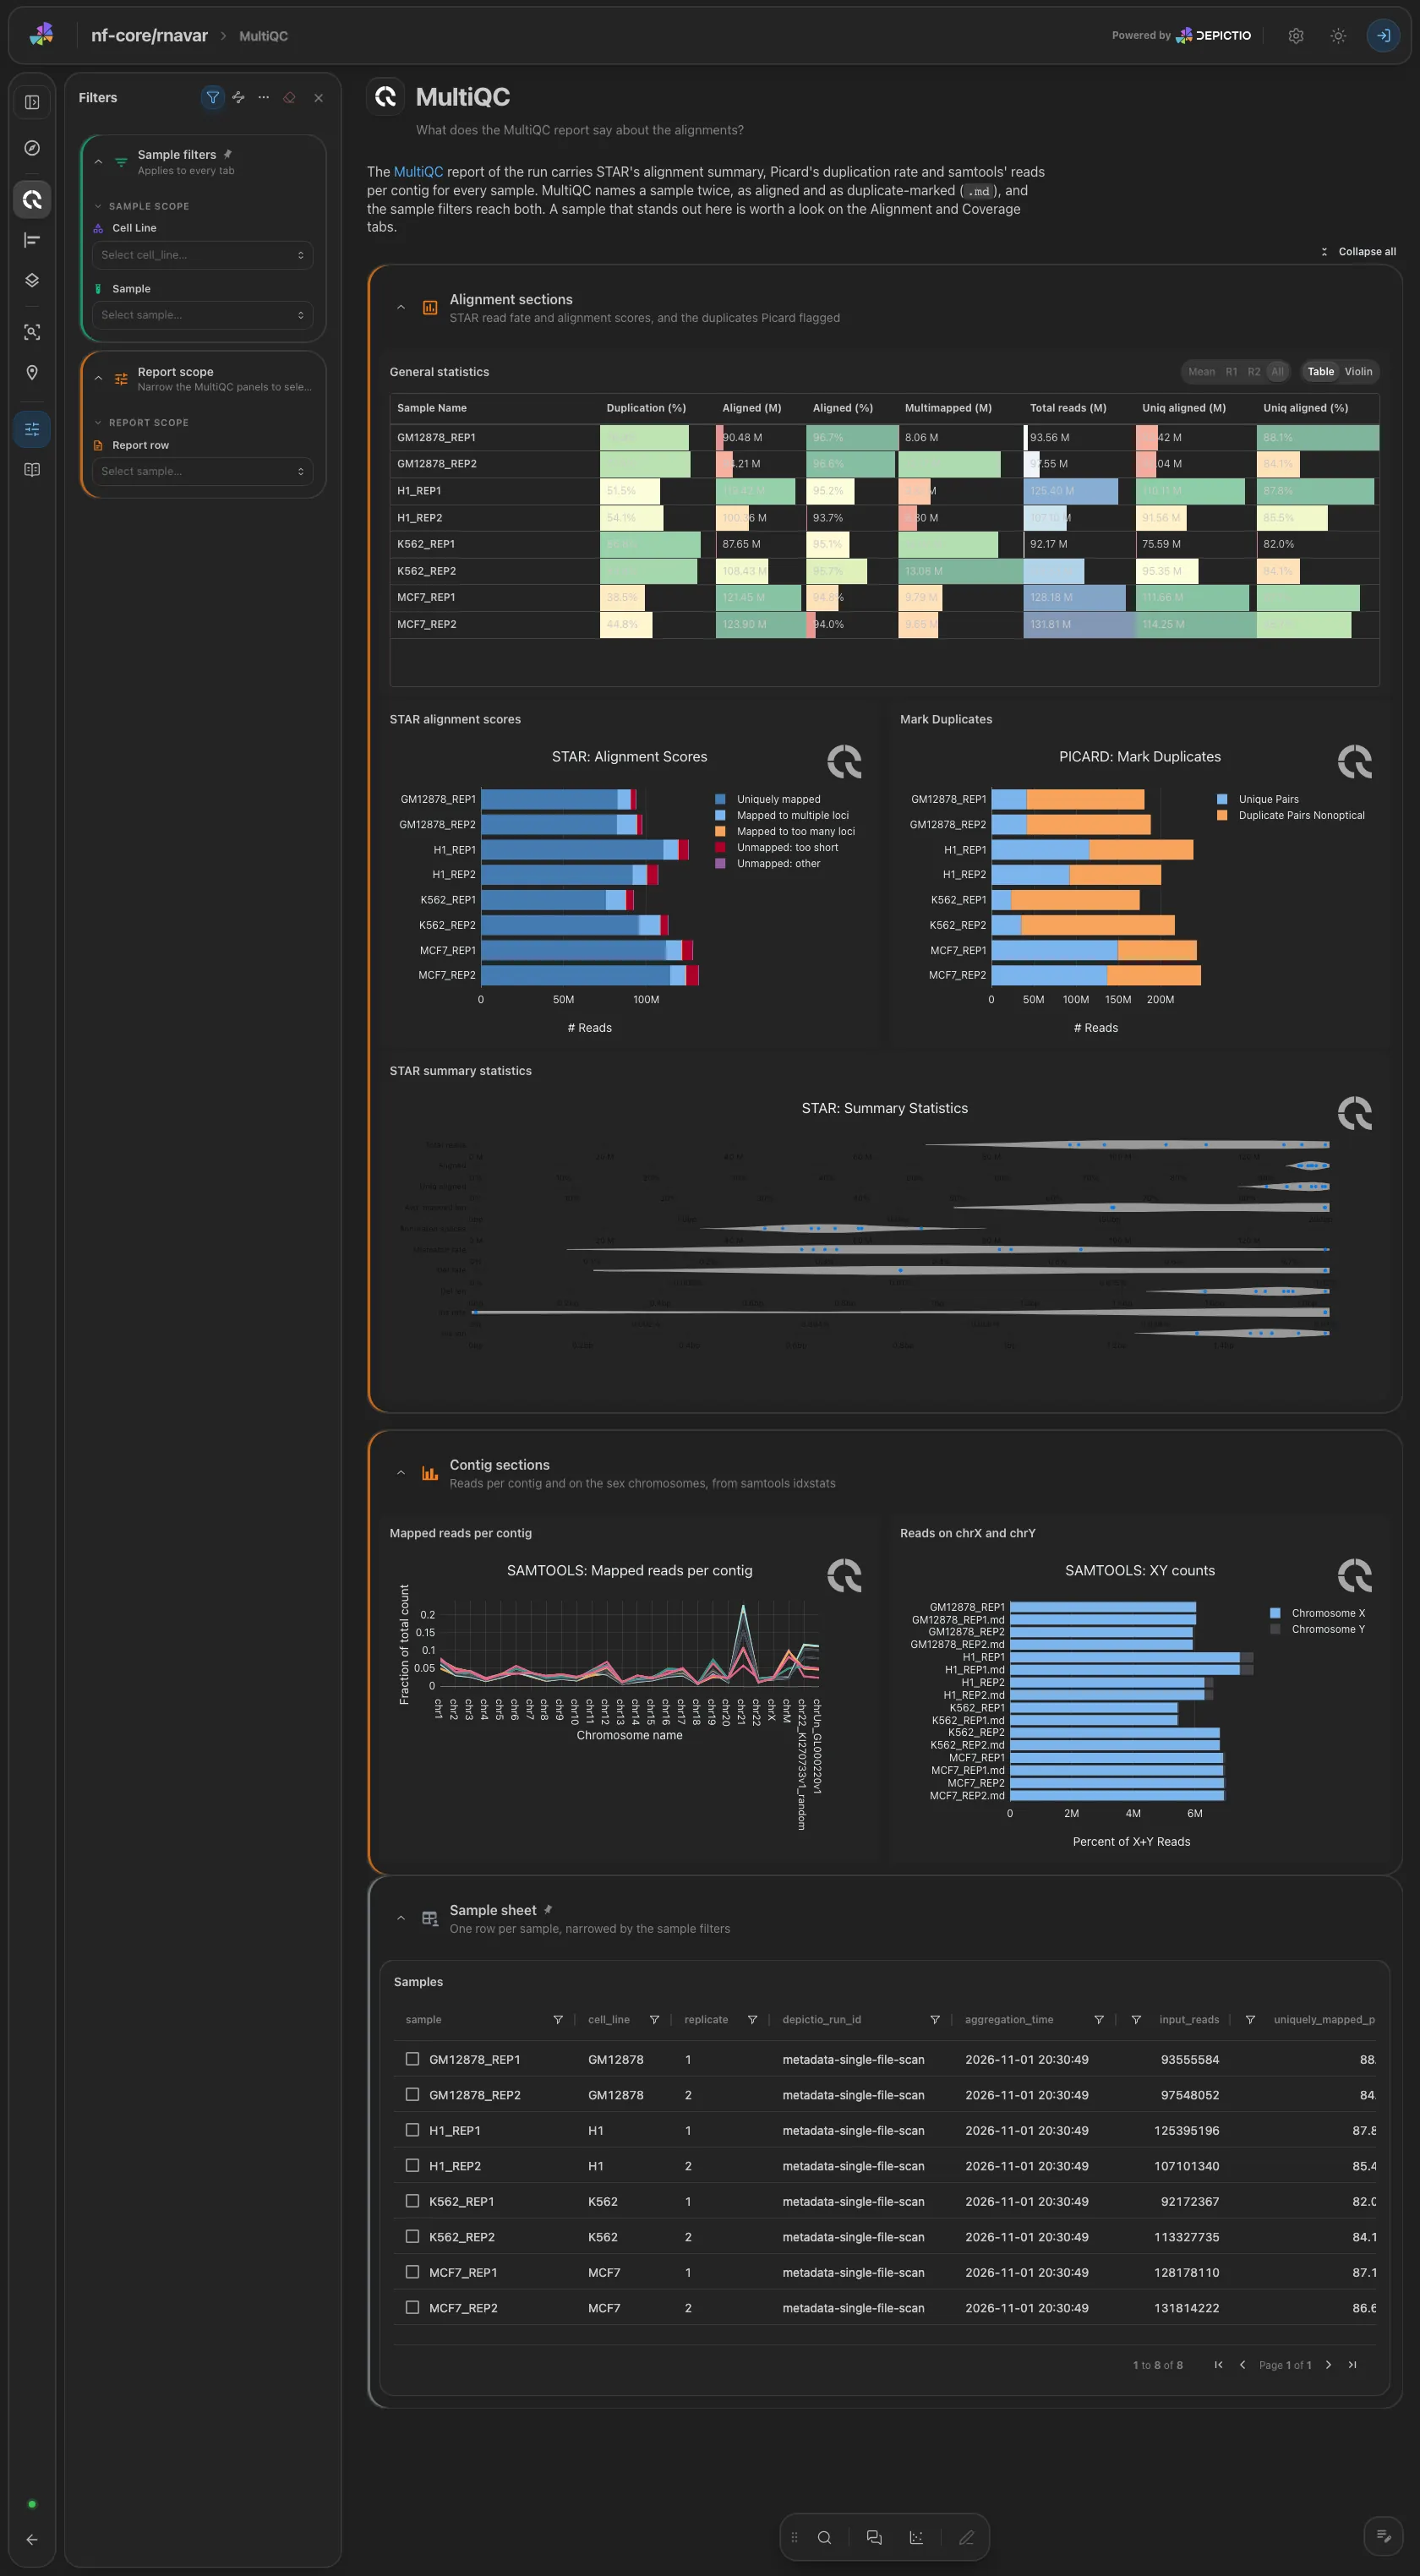
MultiQC panels only: the general statistics, then STAR's alignment scores and summary, Picard MarkDuplicates, and samtools reads per contig and XY counts.
Data & QC · How well did the reads align, splice and deduplicate?
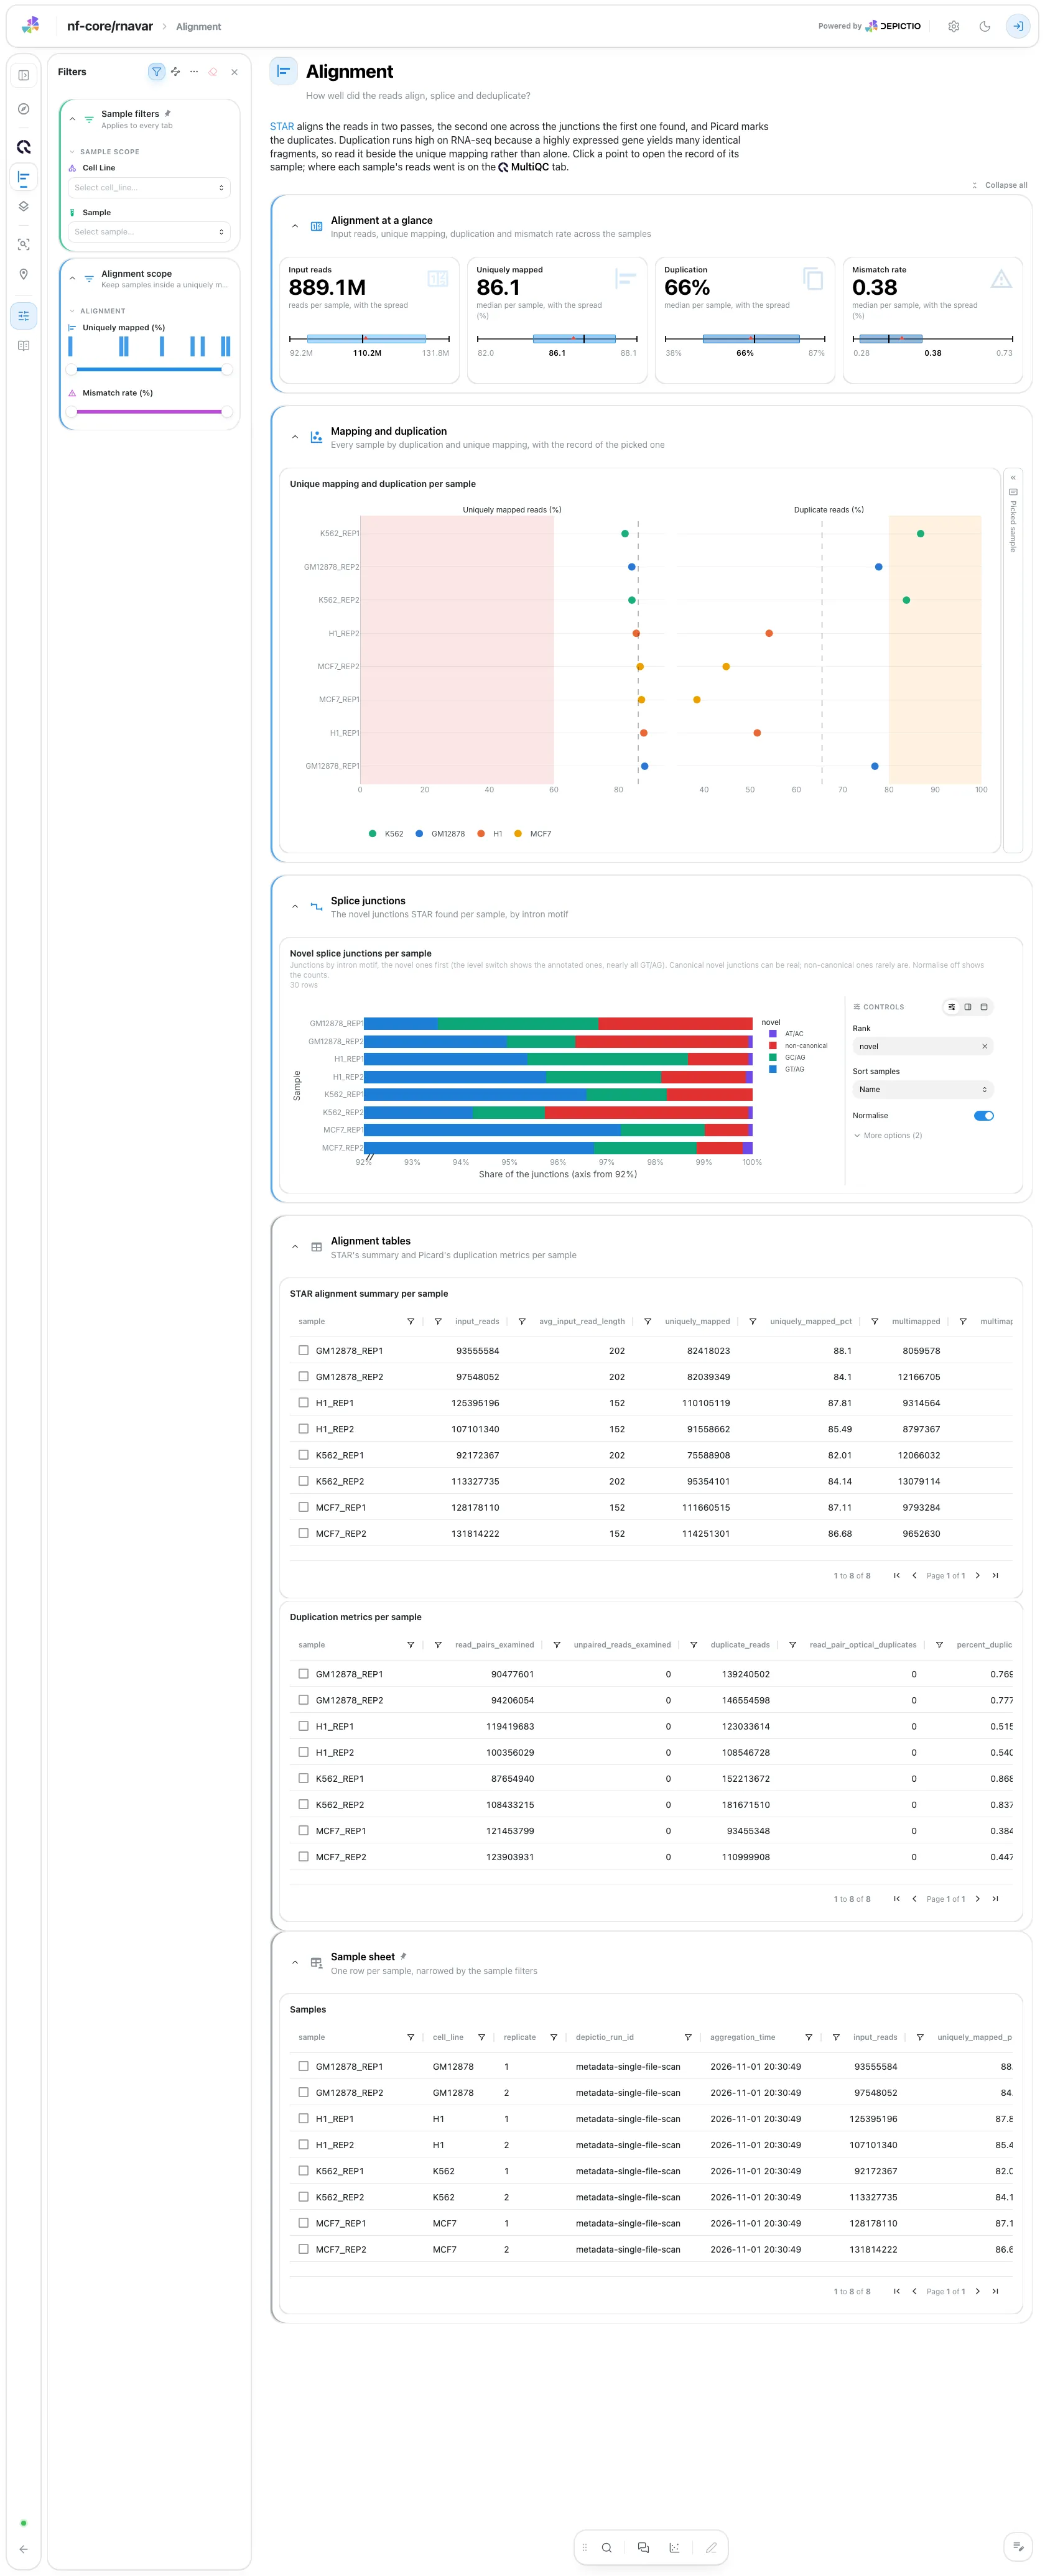
The input reads, the uniquely mapped share, duplication and the mismatch rate, each with a line on what a bad value means. Then unique mapping and duplication per sample as a sorted dot plot, the weakest sample on top, next to the record of the picked sample, and the splice junctions per sample by intron motif, novel first. The tables are collapsed.
Data & QC · How deep do the reads cover the genome, and where?
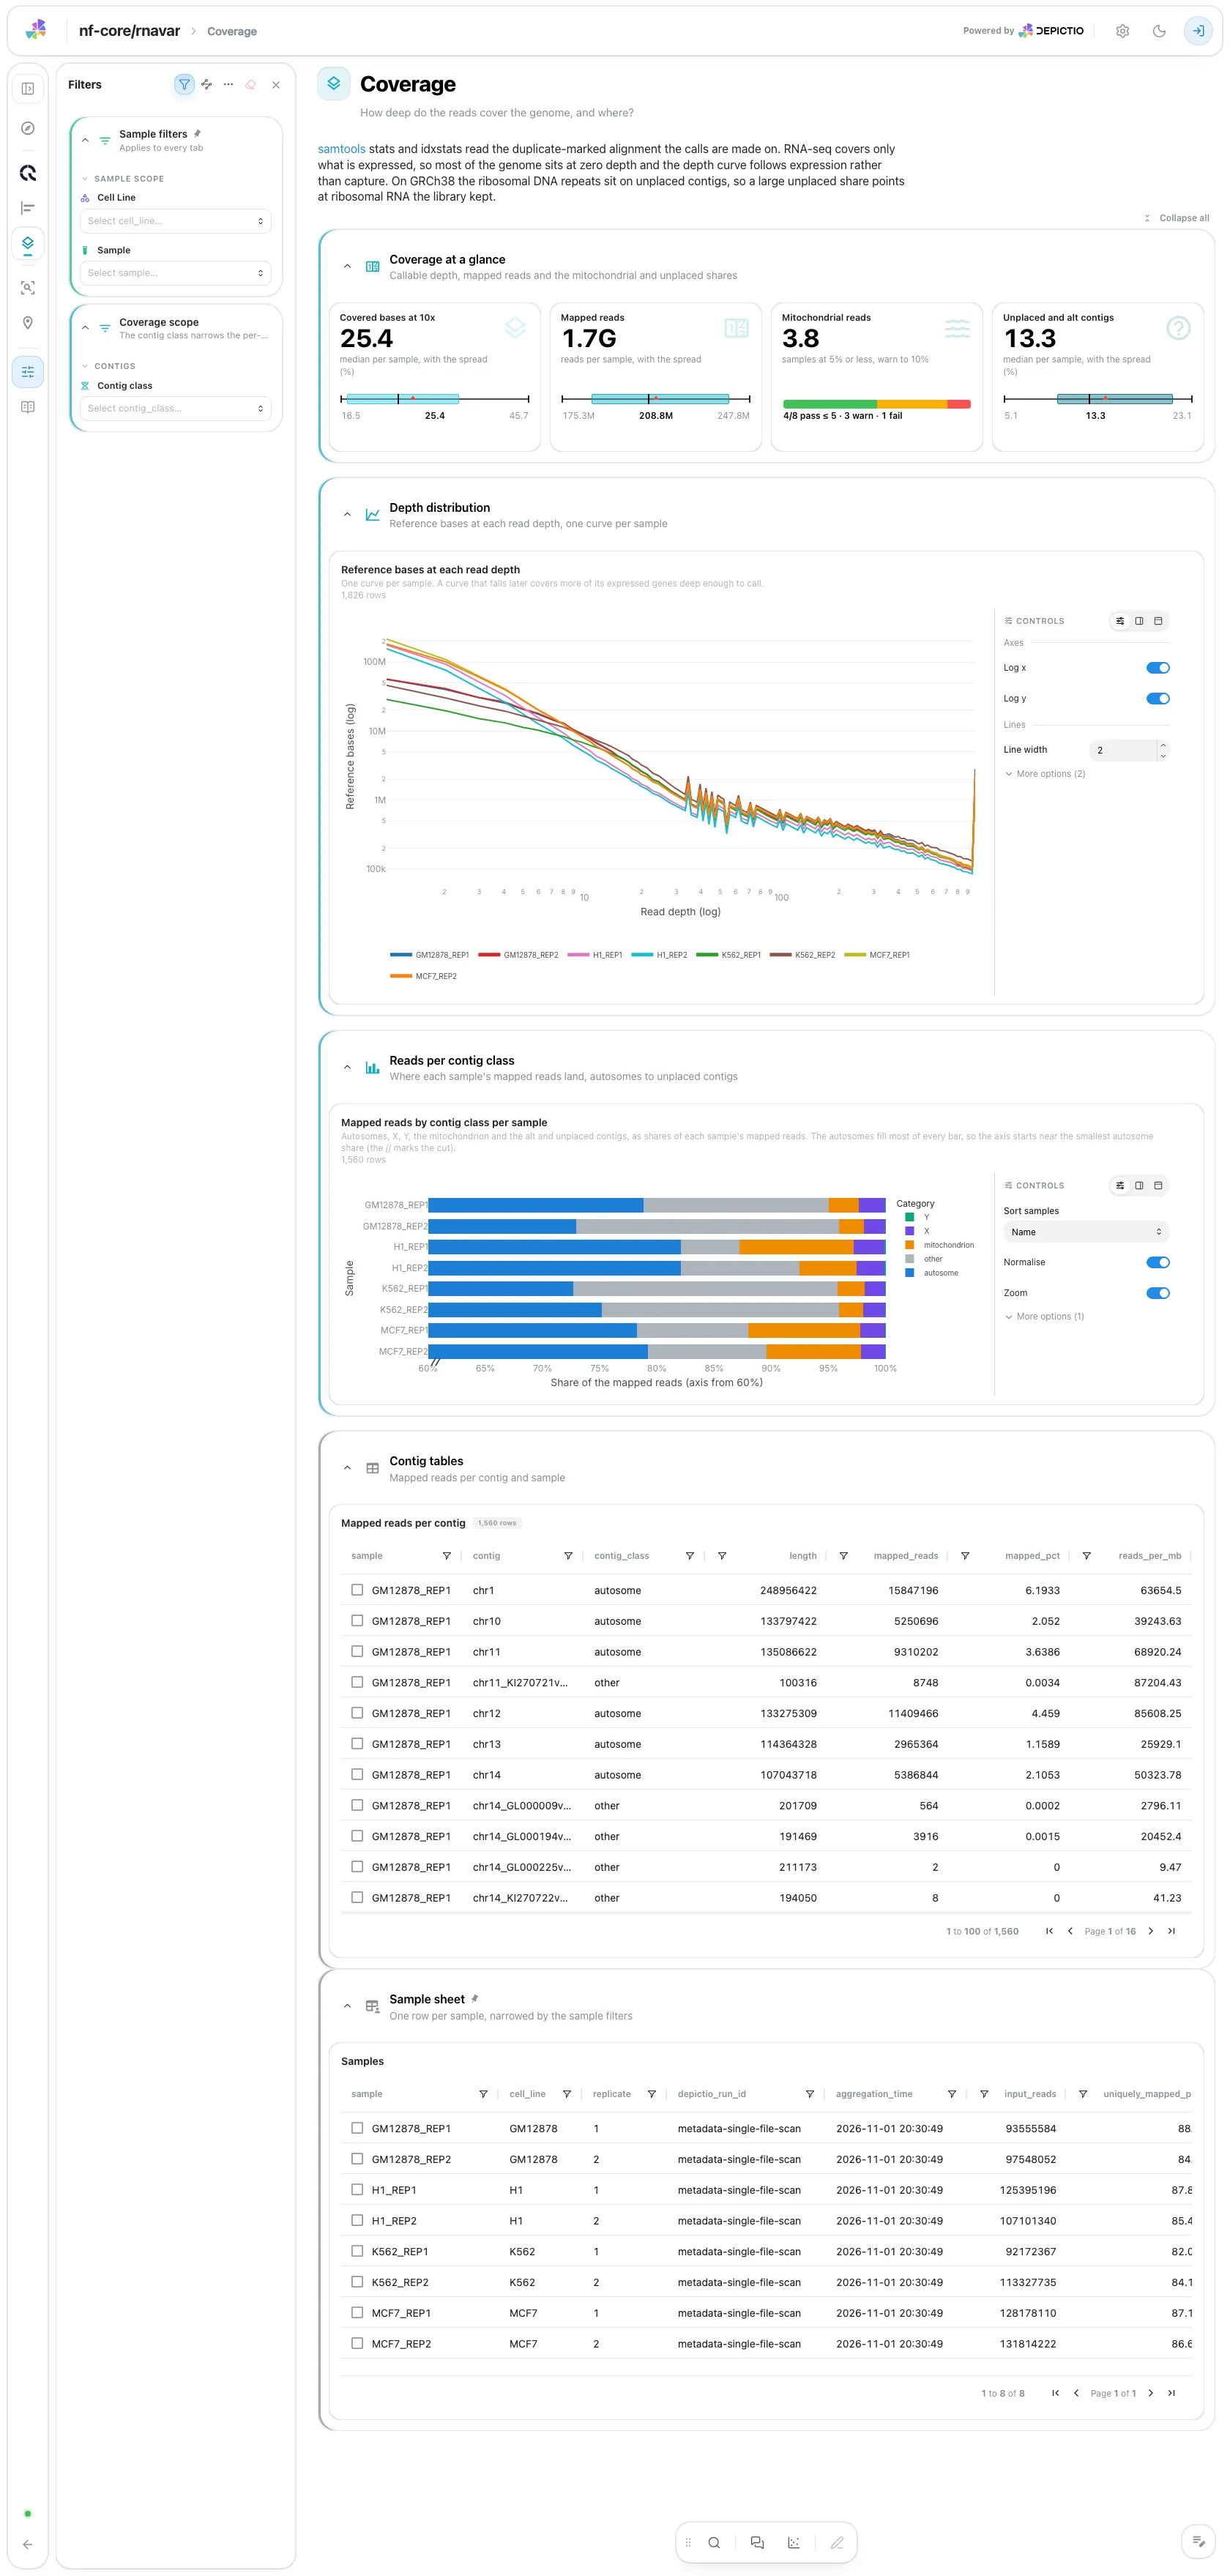
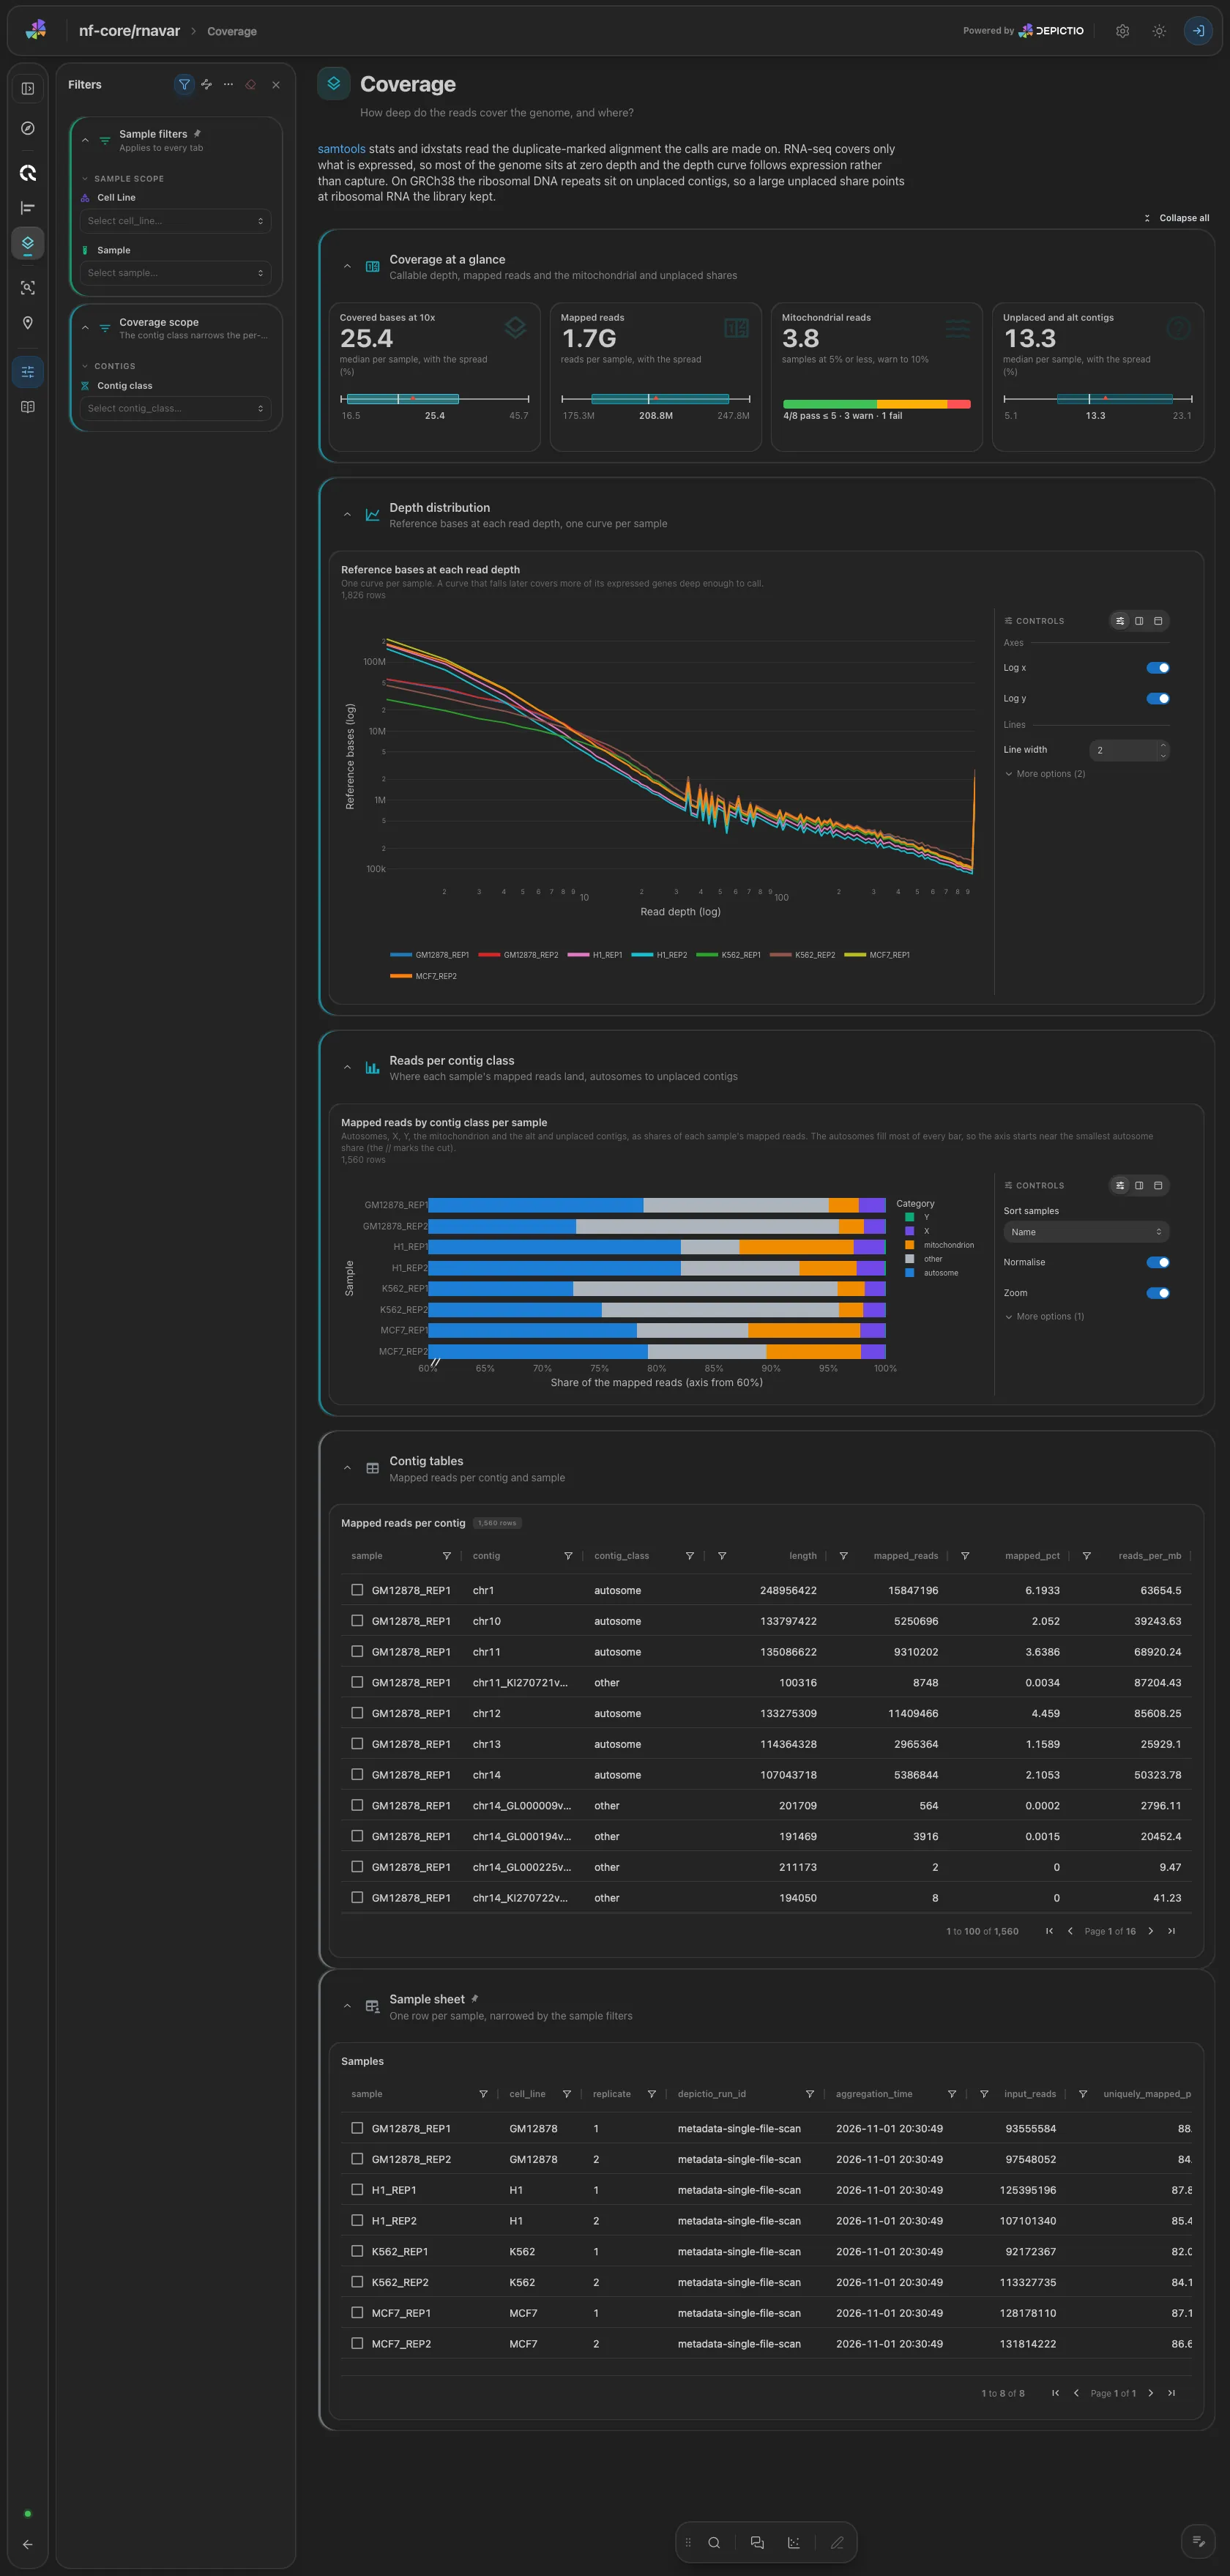
The covered bases at 10x, the mapped reads, the mitochondrial reads (a threshold at 5%) and the reads on alt and unplaced contigs. Then the depth histogram of every sample on log axes and the mapped reads by contig class. The contig table is collapsed.
Variants · How many calls does each sample yield, and how clean are they?
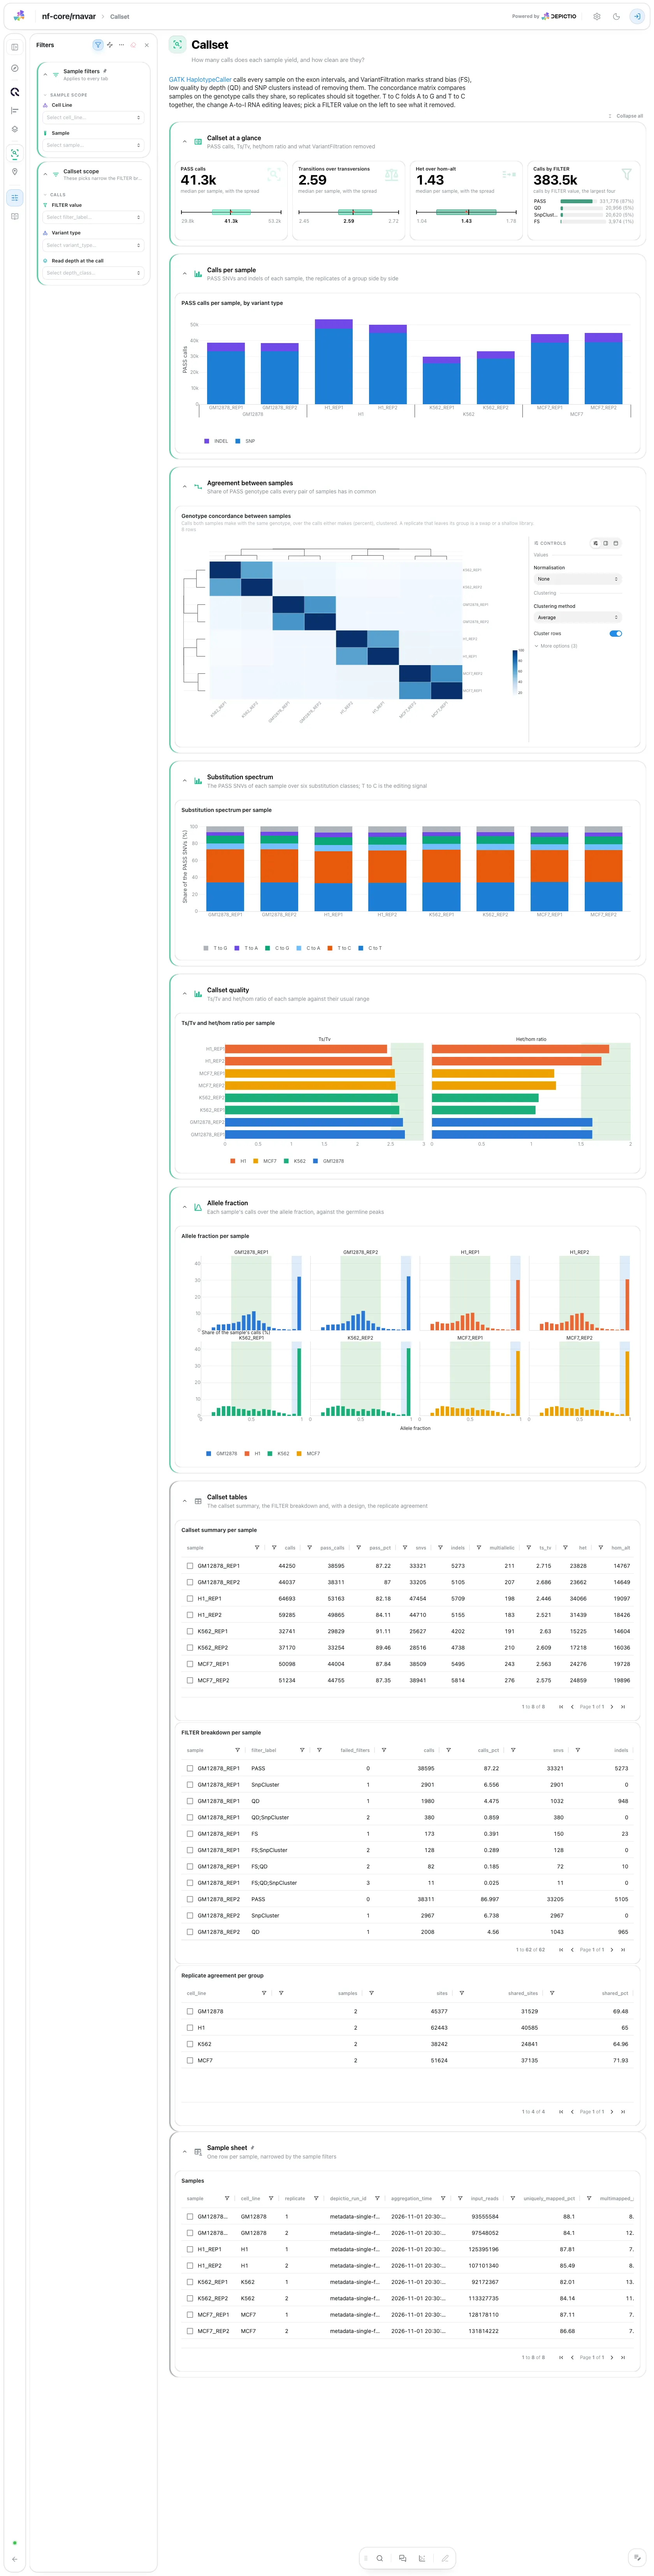
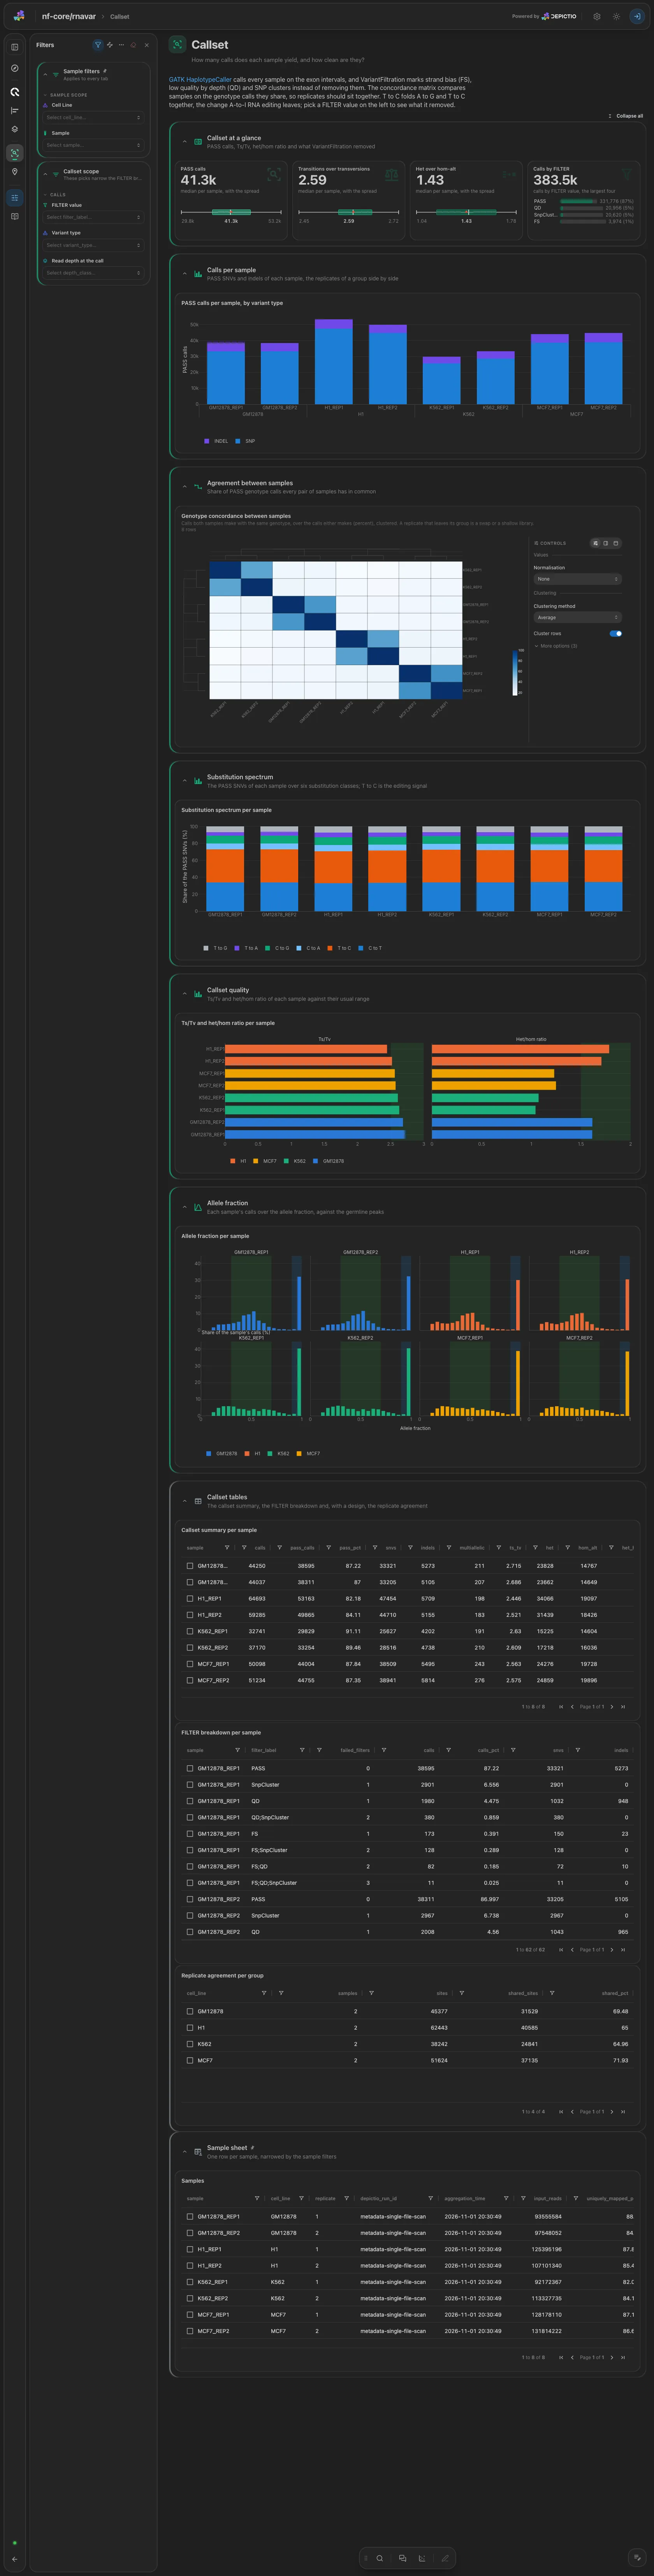
PASS calls, Ts/Tv, the het/hom ratio and the calls by FILTER value, the first two against a working range. Then the genotype concordance of every pair of samples, where replicates should sit together, the substitution spectrum per sample (T to C carries the A-to-I editing signal) and Ts/Tv and het/hom per sample with that range shaded. The allele-fraction distributions and the tables are collapsed; a FILTER value picked on the left narrows the calls.
Variants · What do the calls change in the genes they hit?
Only when the run annotated with --tools snpeff. The annotated calls by
impact, the genes hit by biotype, the HIGH impact calls and the coding allele
fraction. Then the impact classes per sample and the twelve commonest
consequence terms, coloured by impact. A gene picked in the collapsed gene
table narrows the call table.
Variants · Are PASS variants shared between replicates, and do the reads support them?
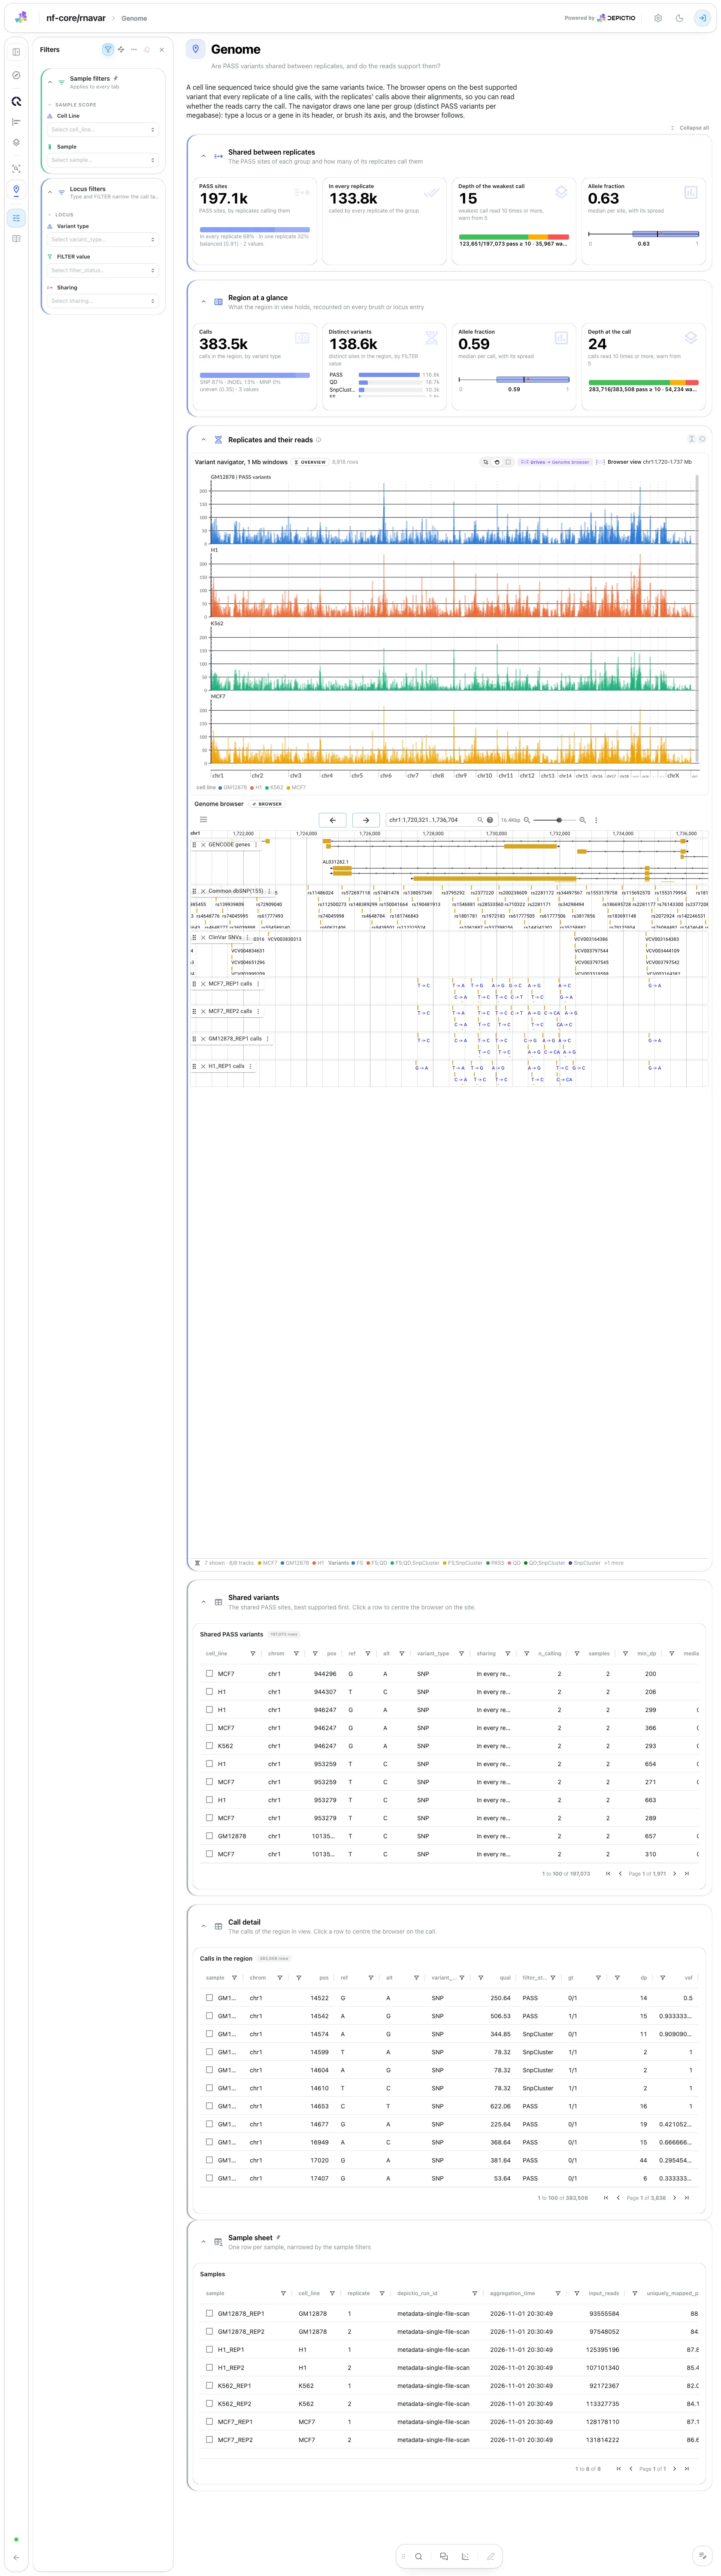
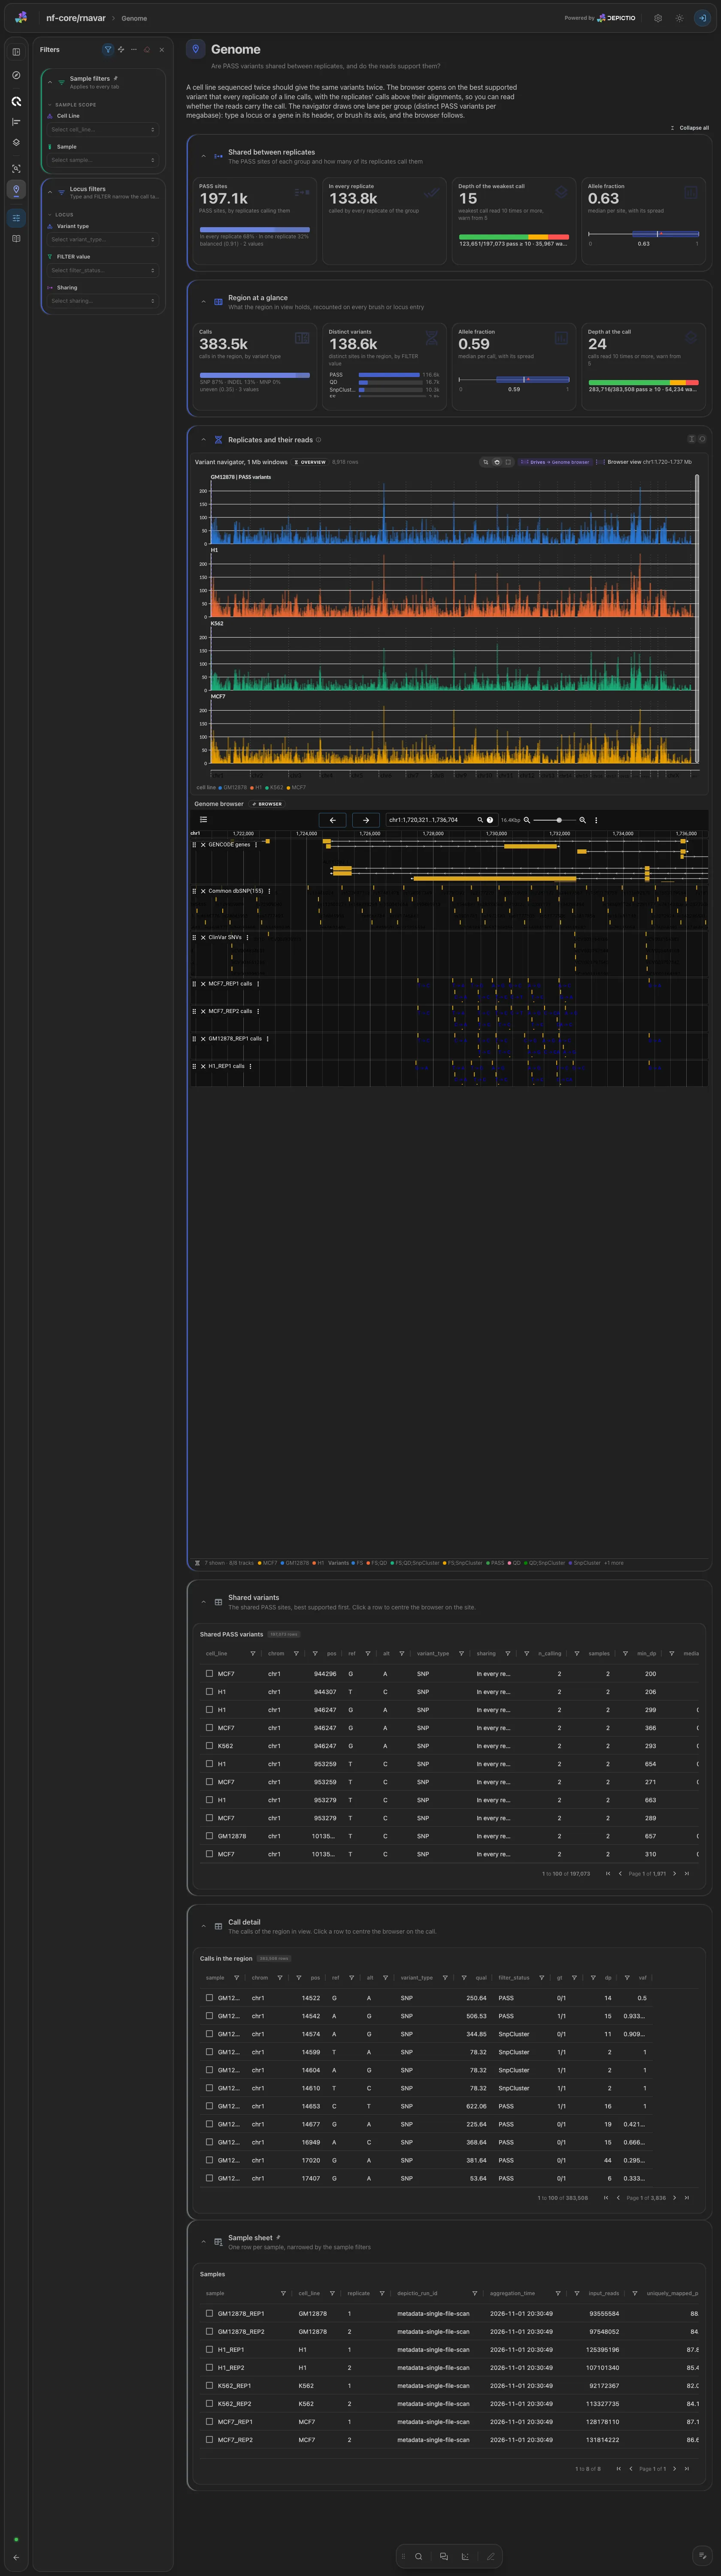
Cards on the sites replicates share and on the region in view. A navigator draws one lane per design group, each window its distinct PASS variants per megabase; a brush or a typed locus sets the region for the cards, the call table and the genome browser, which shows the replicates' VCFs and, under them, their BAMs with splice-junction arcs. It opens on the best-supported shared variant, and a stepper walks the shared sites. The UCSC tracks are hg38 only.
A pick on a sample or a design group reaches every per-sample collection and the MultiQC panels through the project links.
Running the pipeline
Depictio reads the output of nf-core/rnavar, it does not run the pipeline. Run the pipeline first:
nextflow run nf-core/rnavar -r 1.3.0 \
  --input samplesheet.csv \
  --genome GRCh38 \
  --outdir results \
  -profile docker
Add --tools snpeff for the Annotation tab. Then point Depictio at the results:
See nf-co.re/rnavar/usage for full pipeline documentation.
Required data structure
Point depictio ingest at the directory holding the pipeline output. Depictio
scans recursively and matches on file name.
<DATA_ROOT>/
├── input/sample_metadata.tsv                   # --var METADATA_FILE (optional design table)
├── pipeline_info/
├── reports/
│   ├── star/<s>/<s>.Log.final.out
│   ├── star/<s>/<s>.SJ.out.tab
│   ├── picard/<s>/<s>.md.metrics.txt
│   ├── samtools/<s>/<s>.md.{stats,idxstats}
│   ├── snpeff/<s>/*_snpEff.{csv,genes.txt}     # only with --tools snpeff
│   └── multiqc/multiqc_data/multiqc.parquet
├── variant_calling/<s>/<s>.haplotypecaller[.filtered].vcf.gz[.tbi]
├── annotation/<s>/*_snpEff.ann.vcf.gz          # only with --tools snpeff
└── preprocessing/<s>/<s>.md.bam[.bai]          # opened by the genome browser only
Validation runs
The repository ships
download_test_data.sh,
which fetches the tables-only subset of nf-core's AWS megatest run that the
template needs (no BAMs) and copies the vendored design table into input/:
bash depictio/projects/nf-core/rnavar/1.3.0/download_test_data.sh \
  /tmp/rnavar_test
depictio ingest /tmp/rnavar_test \
  --template nf-core/rnavar/latest \
  --var METADATA_FILE=/tmp/rnavar_test/input/sample_metadata.tsv
The run is
s3://nf-core-awsmegatests/rnavar/results-5e72bcb5520e00422750c978d4153b38f1fd7312/,
a complete test_full run of the 1.3.0 development version: eight samples from
cell lines with replicates, with the HaplotypeCaller VCFs and a MultiQC report.
The 1.3.0 release run is a truncated sync with no variant calls, so it is not
used. That run used no --tools, so the Annotation tab was checked on snpEff
output from the same subworkflow in a sarek megatest.
Additional resources
- nf-co.re/rnavar: official pipeline documentation
- nf-co.re/rnavar/results: AWS test results
- Template System Reference: YAML format, variables, conditionals
- Recipes: how to read, test, and write recipes
Authorship
 weber8thomas
Reviewing a template on your own data, or taking over a role here, is a contribution in itself: the contributing guide says what each one involves.