The rnafusion template follows the pipeline's own funnel, from read quality through to the protein a fusion would produce:
- Overview: the run in four key figures, live findings and four figures, each linked to the tab that explains it
- Data & QC: FastQC, fastp, STAR and Picard, out of the MultiQC report
- Fusion calls: fusion-report's ranked consensus and caller agreement, each caller's read support, and Arriba's breakpoints on the genome
- Follow-up: FusionInspector re-quantification and fusion allelic ratios, the Pfam domains each fusion protein keeps, and CTAT-splicing junctions
One row is one fusion in one sample
rnafusion writes one file per tool per sample and none of those files carries
a sample column. Every recipe the template binds reads the sample off the file
name instead, so every fusion and splicing table carries sample and the
samplesheet links to all of them: on a cohort run, the sample filter narrows
every tab. The fusion name stays the key a fusion selection fans out on,
across the consensus, the three callers and the FusionInspector tables.
Route flags are not auto-detected
rnafusion's --tools selection is not read back from params.json, so a run
that skipped a step needs the matching variable: SKIP_ARRIBA,
SKIP_STARFUSION, SKIP_FUSIONCATCHER, SKIP_FUSIONINSPECTOR,
SKIP_CTATSPLICING or SKIP_QC. Each prunes the matching data collections
and the tiles that read them.
Quick start
The results directory is the only thing you have to pass. The samplesheet is looked
for at {DATA_ROOT}/input/samplesheet.csv; pass
--var SAMPLESHEET_FILE=... to point somewhere else.
depictio config nextflow --install     # once per machine
nextflow run nf-core/rnafusion -r 4.1.3 -profile docker --outdir results
No depictio ingest, and no template named: the pipeline ingests its own
output directory when it finishes and resolves this template from its own
manifest. See Nextflow trigger.
Reference
The template reads the fusion-report consensus, the three caller tables behind
it, the FusionInspector abridged table (both the validated calls and the Pfam
domains come from that one file) and the CTAT-splicing intron scores, through
six catalog tools: fusionreport, arriba, starfusion, fusioncatcher,
fusioninspector and ctatsplicing.
Self-adapting layout
The dashboard adapts to whatever the run actually produced: components bound to pruned or unparsed data collections are hidden, tabs left with no real visualizations are dropped entirely, and the remaining components are re-packed so there are no empty rows.
Template variables
Variables you provide when running the template: DATA_ROOT is the results directory given to depictio ingest, the others are set with --var NAME=value:
| Variable | Required | Description |
|---|---|---|
DATA_ROOT |
✓ | Root directory containing rnafusion pipeline output (multiqc/, fusionreport/, arriba/, starfusion/, fusioncatcher/, fusioninspector/, ctatsplicing/) |
SAMPLESHEET_FILE |
— | Path to the run samplesheet. Defaults to {DATA_ROOT}/input/samplesheet.csv. rnafusion does not publish the samplesheet, so fetch the one params.json input points at (see megatest.yaml post_fetch_help). |
SKIP_ARRIBA |
— | Set when params.json tools does not include arriba. Prunes the Arriba data collection. |
SKIP_STARFUSION |
— | Set when params.json tools does not include starfusion. Prunes the STAR-Fusion data collection. |
SKIP_FUSIONCATCHER |
— | Set when params.json tools does not include fusioncatcher. Prunes the FusionCatcher data collection. |
SKIP_FUSIONINSPECTOR |
— | Set when the run did not validate the calls with FusionInspector. Prunes the validated-fusion and protein-domain collections. |
SKIP_CTATSPLICING |
— | Set when params.json tools does not include ctatsplicing. Prunes the splice-junction collections. |
SKIP_QC |
— | Set when the run used --skip_qc (params.json skip_qc). Prunes the MultiQC collection and the Quality control tab. |
Data collections
12 data collections — 11 required 1 optional · 12 direct 0 derived.
Origin tells you whether a collection is real pipeline data or a reshape of it: direct = a pipeline output (scanned, or a recipe that reads raw files); derived = a recipe that reshapes one or more direct collections into the layout a visualization needs (no new measurement). Reads shows what produces it: a recipe .py transform, whose name links to its source on GitHub, or a raw file scanned off disk. (A direct collection can still have a recipe — one that merely parses/cleans the raw file; derived means the recipe reshapes another collection.)
| Tag | Origin | Type | Reads | Status |
|---|---|---|---|---|
multiqc_data |
direct |  MultiQC |
file (?:.*/)?multiqc(?:/[^/]+)?/multiqc_data/multiqc.parquet$ |
required |
samplesheet |
direct | Table | file {DATA_ROOT}/input/samplesheet.csv |
required |
fusion_consensus |
direct | Table | recipe fusionreport/fusions.py |
required |
caller_evidence |
direct | Table | recipe fusionreport/caller_evidence.py |
required |
arriba_fusions |
direct | Table | recipe arriba/fusions.py |
required |
arriba_fusion_links |
direct | Table | recipe arriba/fusion_links.py |
required |
starfusion_fusions |
direct | Table | recipe starfusion/fusions.py |
required |
fusioncatcher_fusions |
direct | Table | recipe fusioncatcher/fusion_genes.py |
required |
fusioninspector_fusions |
direct | Table | recipe fusioninspector/fusions.py |
required |
fusion_protein_domains |
direct | Table | recipe fusioninspector/protein_domains.py |
required |
splice_junctions |
direct | Table | recipe ctatsplicing/introns.py |
required |
cancer_introns |
direct | Table | recipe ctatsplicing/cancer_introns.py |
optional |
Conditional routes
Rows are data collections; columns are the variables you set or params.json flags auto-detected from the run. Each filled cell is the effect of setting that variable; an empty cell means that variable leaves the collection unchanged. (2 collections are unaffected by any variable — present on every run.)
+ included− removed⇄ repointed
| Data collection | SAMPLESHEET_FILE |
SKIP_ARRIBA |
SKIP_STARFUSION |
SKIP_FUSIONCATCHER |
SKIP_FUSIONINSPECTOR |
SKIP_CTATSPLICING |
SKIP_QC |
|---|---|---|---|---|---|---|---|
multiqc_data |
− | ||||||
samplesheet |
⇄ | ||||||
arriba_fusions |
− | ||||||
arriba_fusion_links |
− | ||||||
starfusion_fusions |
− | ||||||
fusioncatcher_fusions |
− | ||||||
fusioninspector_fusions |
− | ||||||
fusion_protein_domains |
− | ||||||
splice_junctions |
− | ||||||
cancer_introns |
− |
Cross-DC links
20 links — selecting a value in the source collection filters the target. The join column is shown after the source.
| Source · column | Target | Filters | |
|---|---|---|---|
samplesheet · sample |
→ | multiqc_data |
Filter the MultiQC panels by samplesheet samples |
fusion_consensus · fusion |
→ | caller_evidence |
Filter the per-caller evidence by the selected fusions |
fusion_consensus · fusion |
→ | arriba_fusions |
Filter the Arriba calls by the selected fusions |
fusion_consensus · fusion |
→ | arriba_fusion_links |
Filter the Arriba breakpoint links by the selected fusions |
fusion_consensus · fusion |
→ | starfusion_fusions |
Filter the STAR-Fusion calls by the selected fusions |
fusion_consensus · fusion |
→ | fusioncatcher_fusions |
Filter the FusionCatcher calls by the selected fusions |
fusion_consensus · fusion |
→ | fusioninspector_fusions |
Filter the FusionInspector validation by the selected fusions |
fusion_consensus · fusion |
→ | fusion_protein_domains |
Filter the protein-domain rows by the selected fusions |
fusioninspector_fusions · fusion |
→ | fusion_protein_domains |
Filter the protein-domain rows by the validated fusion selection |
fusioninspector_fusions · fusion |
→ | caller_evidence |
Filter the per-caller evidence by the validated fusion selection |
samplesheet · sample |
→ | fusion_consensus |
Narrow fusion consensus to the selected samples |
samplesheet · sample |
→ | caller_evidence |
Narrow caller evidence to the selected samples |
samplesheet · sample |
→ | arriba_fusions |
Narrow arriba fusions to the selected samples |
samplesheet · sample |
→ | arriba_fusion_links |
Narrow arriba fusion links to the selected samples |
samplesheet · sample |
→ | starfusion_fusions |
Narrow starfusion fusions to the selected samples |
samplesheet · sample |
→ | fusioncatcher_fusions |
Narrow fusioncatcher fusions to the selected samples |
samplesheet · sample |
→ | fusioninspector_fusions |
Narrow fusioninspector fusions to the selected samples |
samplesheet · sample |
→ | fusion_protein_domains |
Narrow fusion protein domains to the selected samples |
samplesheet · sample |
→ | splice_junctions |
Narrow splice junctions to the selected samples |
samplesheet · sample |
→ | cancer_introns |
Narrow cancer introns to the selected samples |
Recipes
Each recipe reshapes raw pipeline output into a tidy table. The name links to its source; Output lists the validated OUTPUT_SCHEMA columns.
| Recipe | Transforms | Output |
|---|---|---|
arriba/fusion_links.py |
Turn Arriba's fusions.tsv into one breakpoint-pair link per fusion call. |
sample, label, chrom_a, pos_a, chrom_b, pos_b, weight, category, confidence |
arriba/fusions.py |
Tidy Arriba's fusions.tsv into one row per retained fusion call. |
sample, fusion, gene_5p, gene_3p, breakpoint_5p, breakpoint_3p, chrom_5p, chrom_3p, chrom_pair, site_5p, site_3p, fusion_type, confidence, reading_frame, split_reads, discordant_mates, supporting_reads, coverage, log_support, support_fraction, retained_protein_domains, tags |
ctatsplicing/cancer_introns.py |
Tidy the CTAT-SPLICING *.cancer.introns candidate table into one row per intron. |
sample, intron, chrom, start, end, strand, gene, gene_id, uniq_mapped, multi_mapped, score, n_tcga_cohorts, top_tcga_cohort, top_tcga_pct, n_gtex_tissues, top_gtex_tissue, top_gtex_pct, variant_name |
ctatsplicing/introns.py |
Tidy the CTAT-SPLICING *.introns splice-junction table into one row per intron. |
sample, intron, chrom, start, end, intron_length, strand, gene, gene_id, uniq_mapped, multi_mapped, total_mapped, uniq_fraction, score |
fusioncatcher/fusion_genes.py |
Tidy the FusionCatcher *.fusion-genes.txt candidate list into one row per fusion. |
sample, fusion, gene_5p, gene_3p, description, n_annotations, common_mapping_reads, spanning_pairs, spanning_unique_reads, supporting_reads, longest_anchor, finding_method, breakpoint_5p, breakpoint_3p, predicted_effect, log_support, unique_fraction |
fusioninspector/fusions.py |
Tidy the FusionInspector abridged fusion table into one row per fusion call. | sample, fusion, gene_5p, gene_3p, breakpoint_5p, breakpoint_3p, splice_type, junction_reads, spanning_frags, supporting_reads, ffpm, log_ffpm, junction_fraction, far_left, far_right, counter_fusion_left, counter_fusion_right, prot_fusion_type, large_anchor_support, cds_left_id, cds_right_id, n_domains_5p, n_domains_3p |
fusioninspector/protein_domains.py |
Unpivot the FusionInspector Pfam fields into one row per fusion protein domain. | sample, fusion, partner, domain, domain_start, domain_end, domain_length, evalue, neg_log10_evalue, prot_fusion_type |
fusionreport/caller_evidence.py |
Unpivot the per-caller evidence strings of the fusion-report consensus CSV. | sample, fusion, caller, position_5p, position_3p, supporting_reads, log_support, evidence_fraction, fii, detail |
fusionreport/fusions.py |
Turn the fusion-report consensus CSV into one tidy row per fusion. | sample, fusion, gene_5p, gene_3p, databases, n_databases, fii, explained_fii, n_tools, tool_support, rank |
starfusion/fusions.py |
Tidy STAR-Fusion's abridged prediction table into one row per fusion call. | sample, fusion, gene_5p, gene_3p, breakpoint_5p, breakpoint_3p, splice_type, junction_reads, spanning_frags, supporting_reads, ffpm, log_ffpm, junction_fraction, large_anchor_support, annotations |
Dashboard tabs
One dashboard: the Overview, then seven child tabs in three groups, read as a funnel from the reads to the proteins the fusions would make. Each tab below carries the same icon and colour the dashboard gives it, so the page and the app read alike.
| Group | Tabs |
|---|---|
| Data & QC | MultiQC |
| Fusion calls | Caller Agreement, Caller Evidence, Breakpoints |
| Follow-up | Validation, Protein Domains, Splice Junctions |
Each child tab opens with a short intro and a strip of four cards, then at most three open sections; tables and details follow, collapsed. Two persistent filter sections sit in the left panel. Sample filters (the sample, then the strandedness) narrow every tab. Fusion filters (the fusion, then the caller agreement) reach every caller table through the links on the fusion name; MultiQC and Splice Junctions carry no fusion, so they are left off those two tabs. The Sample sheet is pinned, collapsed, to the bottom of every child tab.
Gene fusions, from the reads to the callers that agree and the proteins they would make.
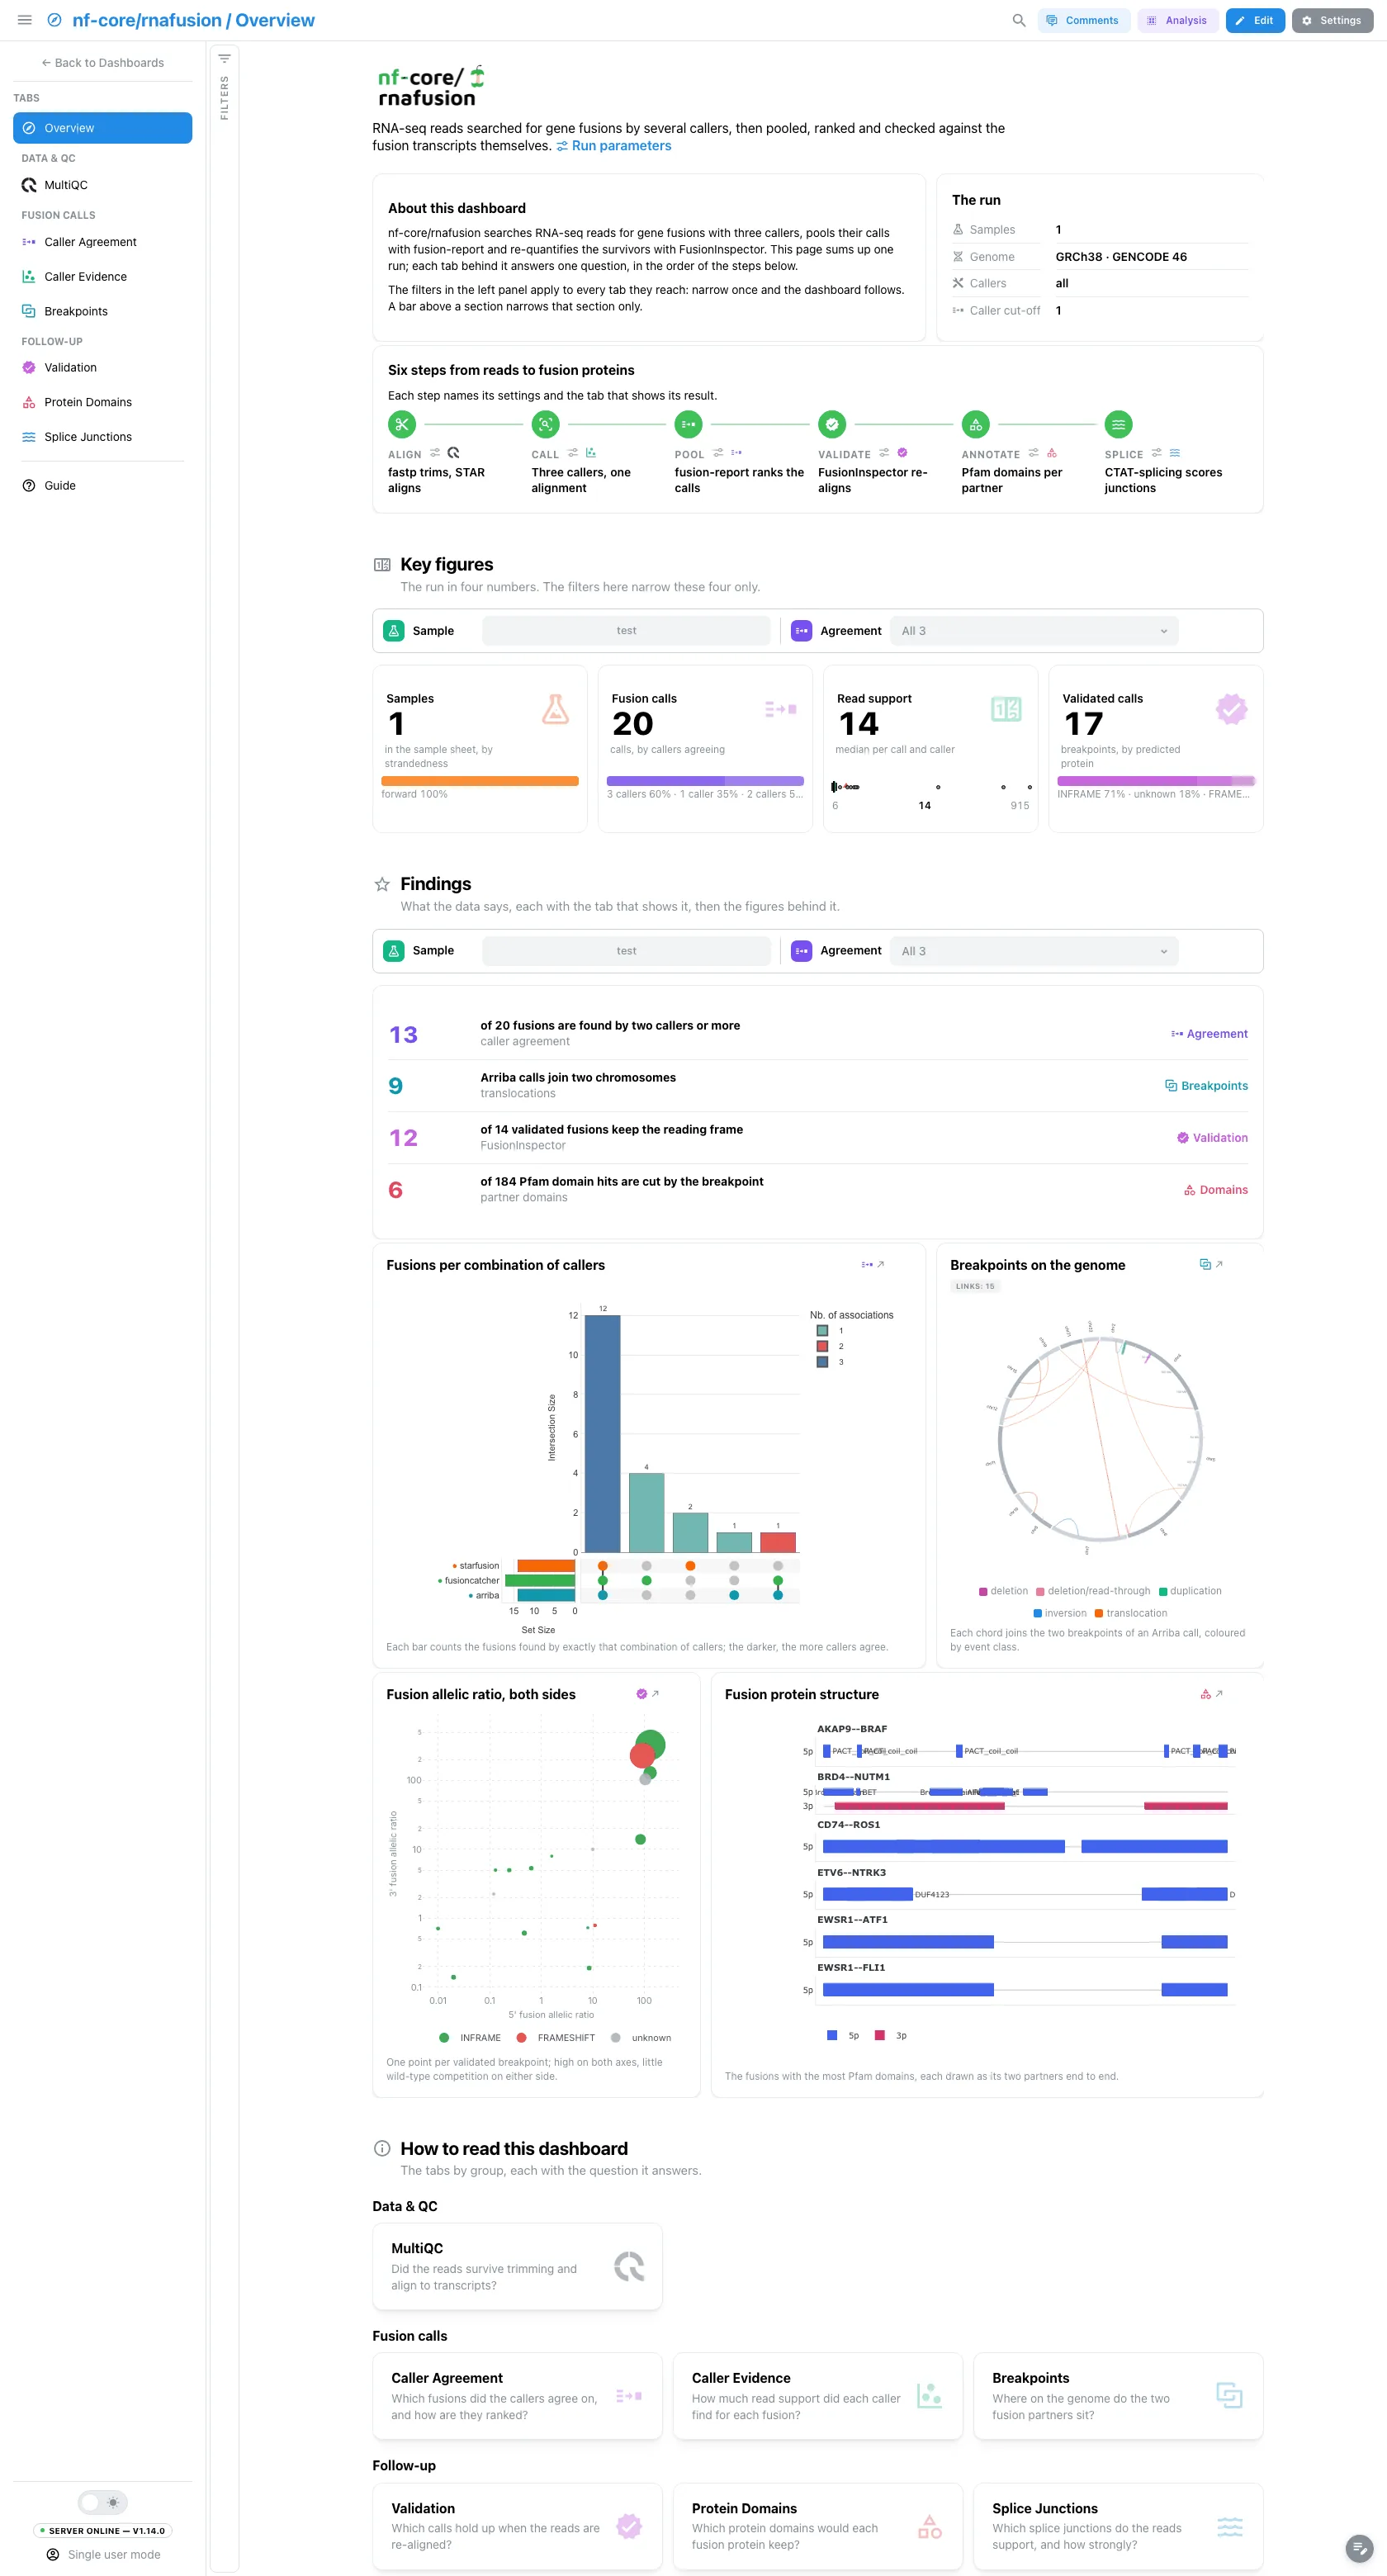
A short hero links the run parameters. About this dashboard says how to move through the tabs, The run lists the samples, the genome and GENCODE release, the callers and the caller cut-off, and Pipeline walks the six steps from alignment to splicing, each linked to its parameters and its tab. The findings are live values: they follow the filters, and a run that skipped a step drops the rows that read it.
Filters and components
Filters · the left panel starts collapsed. Key figures and Findings each have a filter bar (the sample and the caller agreement) that narrows that section only.
| Section | What it holds |
|---|---|
| Top | Hero, About this dashboard, The run, Pipeline |
| Key figures | 4 headline cards: samples, fusion calls, read support, validated calls |
| Findings | Live result rows, then 4 figures: the caller UpSet, the breakpoint chord, the fusion allelic ratio scatter and the fusion protein structure |
| How to read this dashboard | The tabs by group, each with its question |
Data & QC · Did the reads survive trimming and align to transcripts?
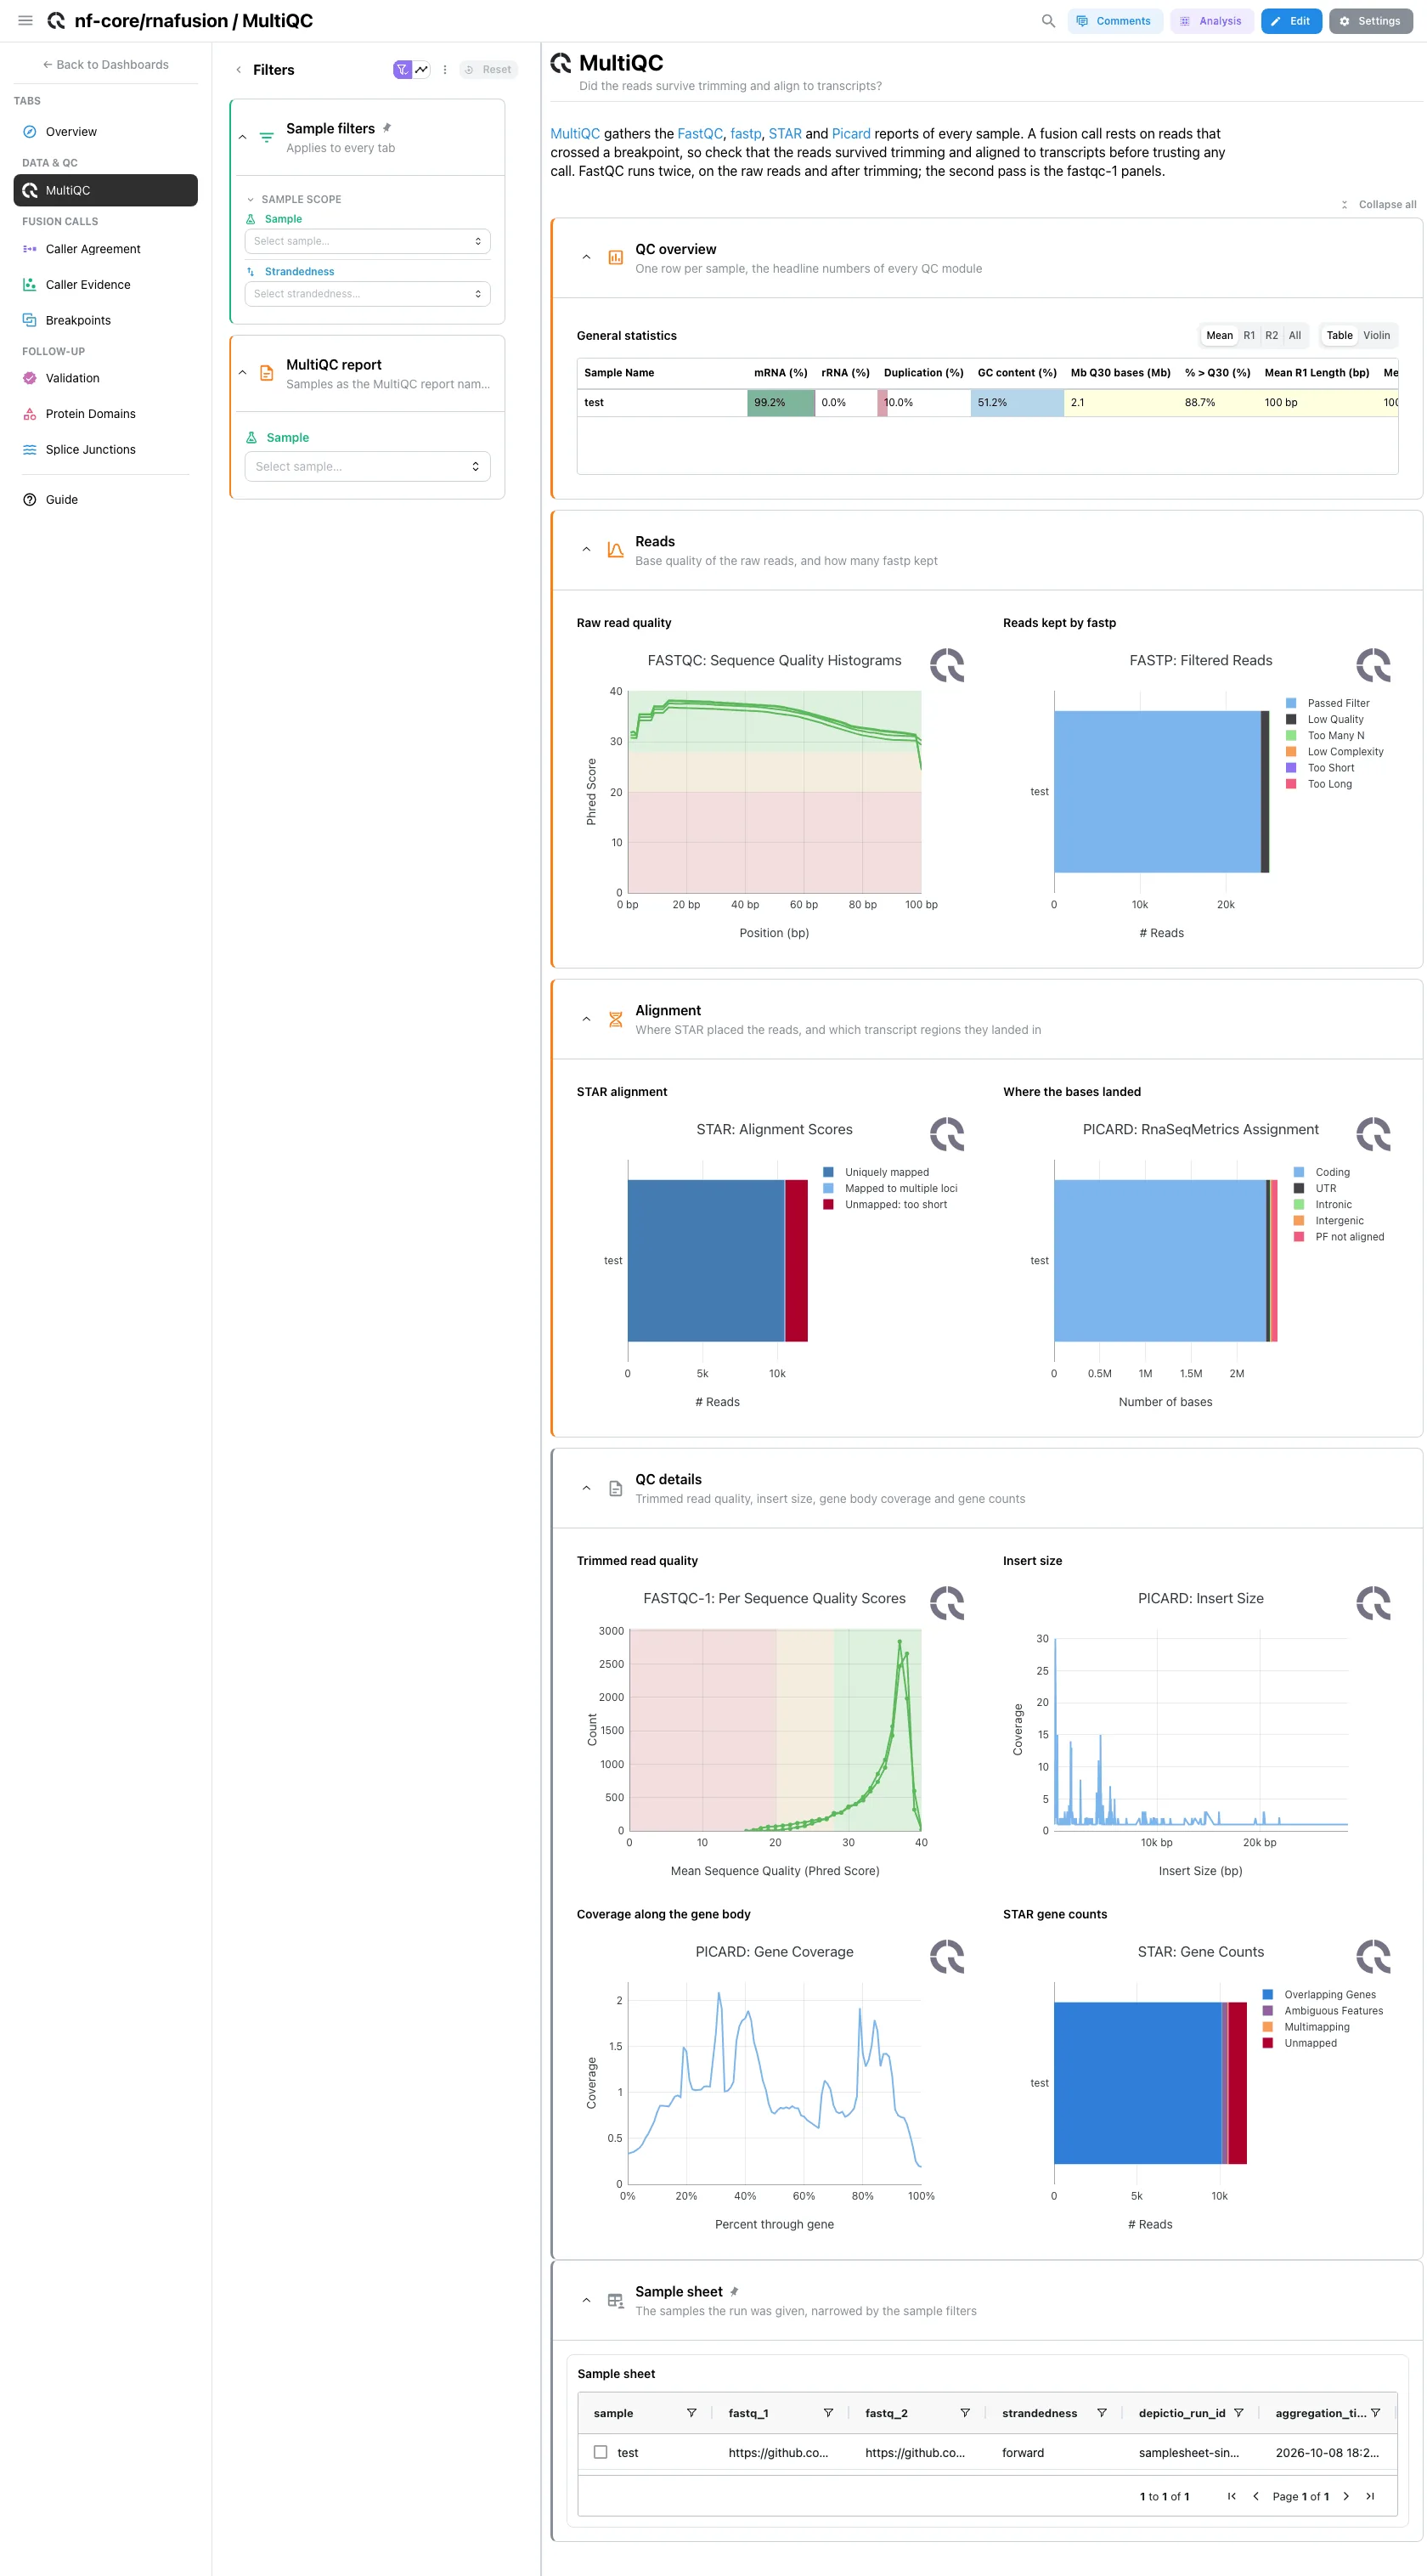
MultiQC panels only. The general statistics, the raw read quality beside the reads fastp kept, then STAR's alignment scores beside Picard's transcript region assignment. The post-trim read quality, insert size, gene body coverage and STAR gene counts are collapsed. Its sample filter reads the MultiQC report.
Filters and components
Filters · Sample, read from the MultiQC report.
| Section | What it holds |
|---|---|
| QC overview | General statistics |
| Reads | 2 MultiQC panels |
| Alignment | 2 MultiQC panels |
| QC details (collapsed) | 4 MultiQC panels |
Fusion calls · Which fusions did the callers agree on, and how are they ranked?
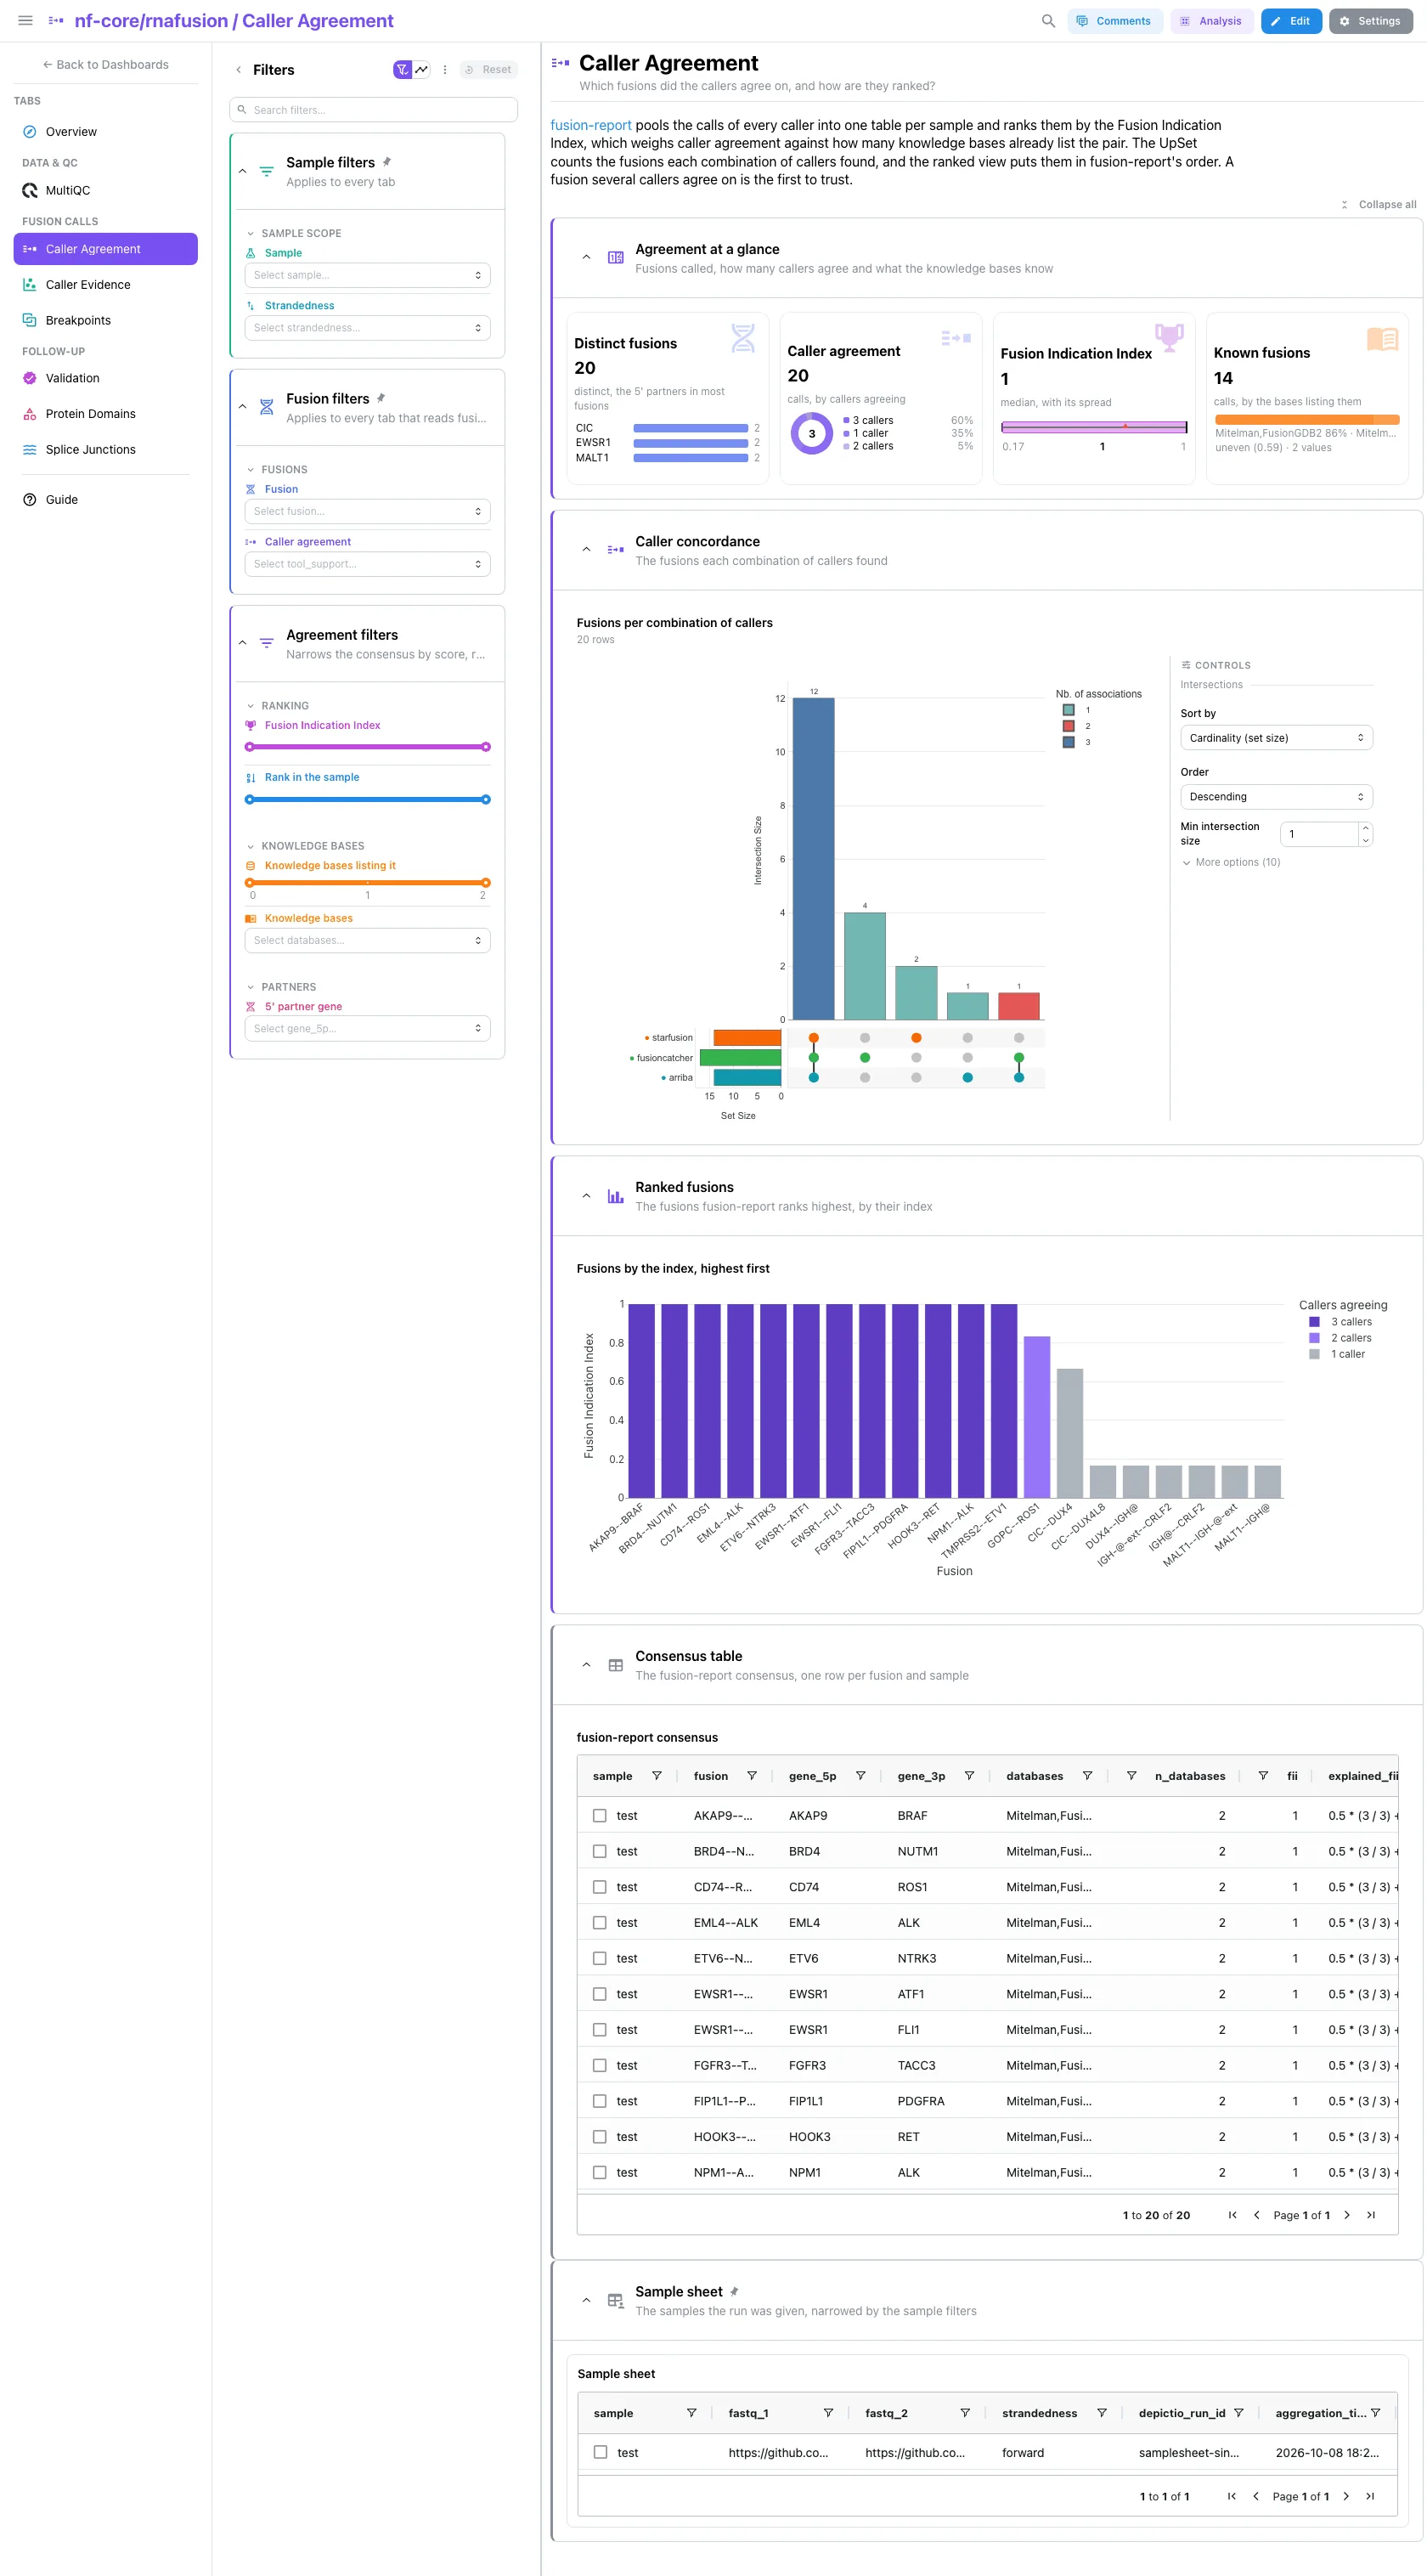
The distinct fusions ranked by 5' partner, the calls split by how many callers agree, the median Fusion Indication Index and the calls a knowledge base already lists. Then the UpSet of the fusions each combination of callers found, and the fusions fusion-report ranks highest, as bars of their index. The consensus table is collapsed.
Filters and components
Filters · Fusion Indication Index, Rank in the sample and
Knowledge bases listing it ranges, Knowledge bases and
5' partner gene, all on fusion_consensus.
| Section | What it holds |
|---|---|
| Agreement at a glance | 4 cards |
| Caller concordance | 1 advanced visualization |
| Ranked fusions | Fusions by the index, highest first |
| Consensus table (collapsed) | fusion-report consensus |
Fusion calls · How much read support did each caller find for each fusion?
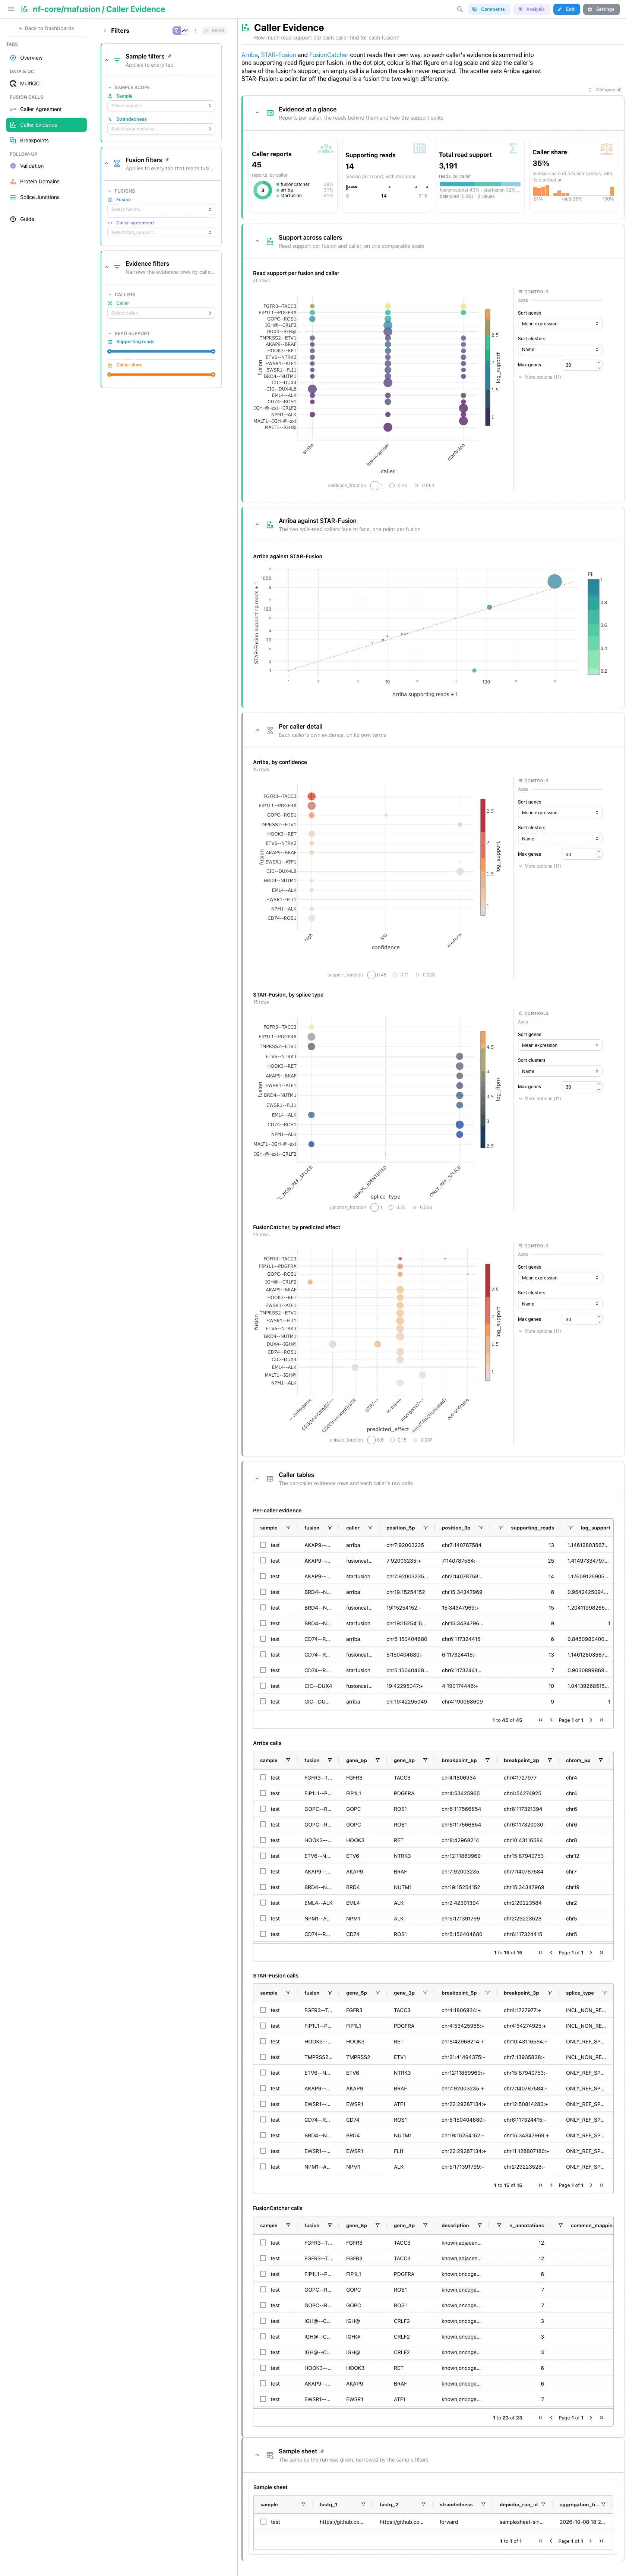
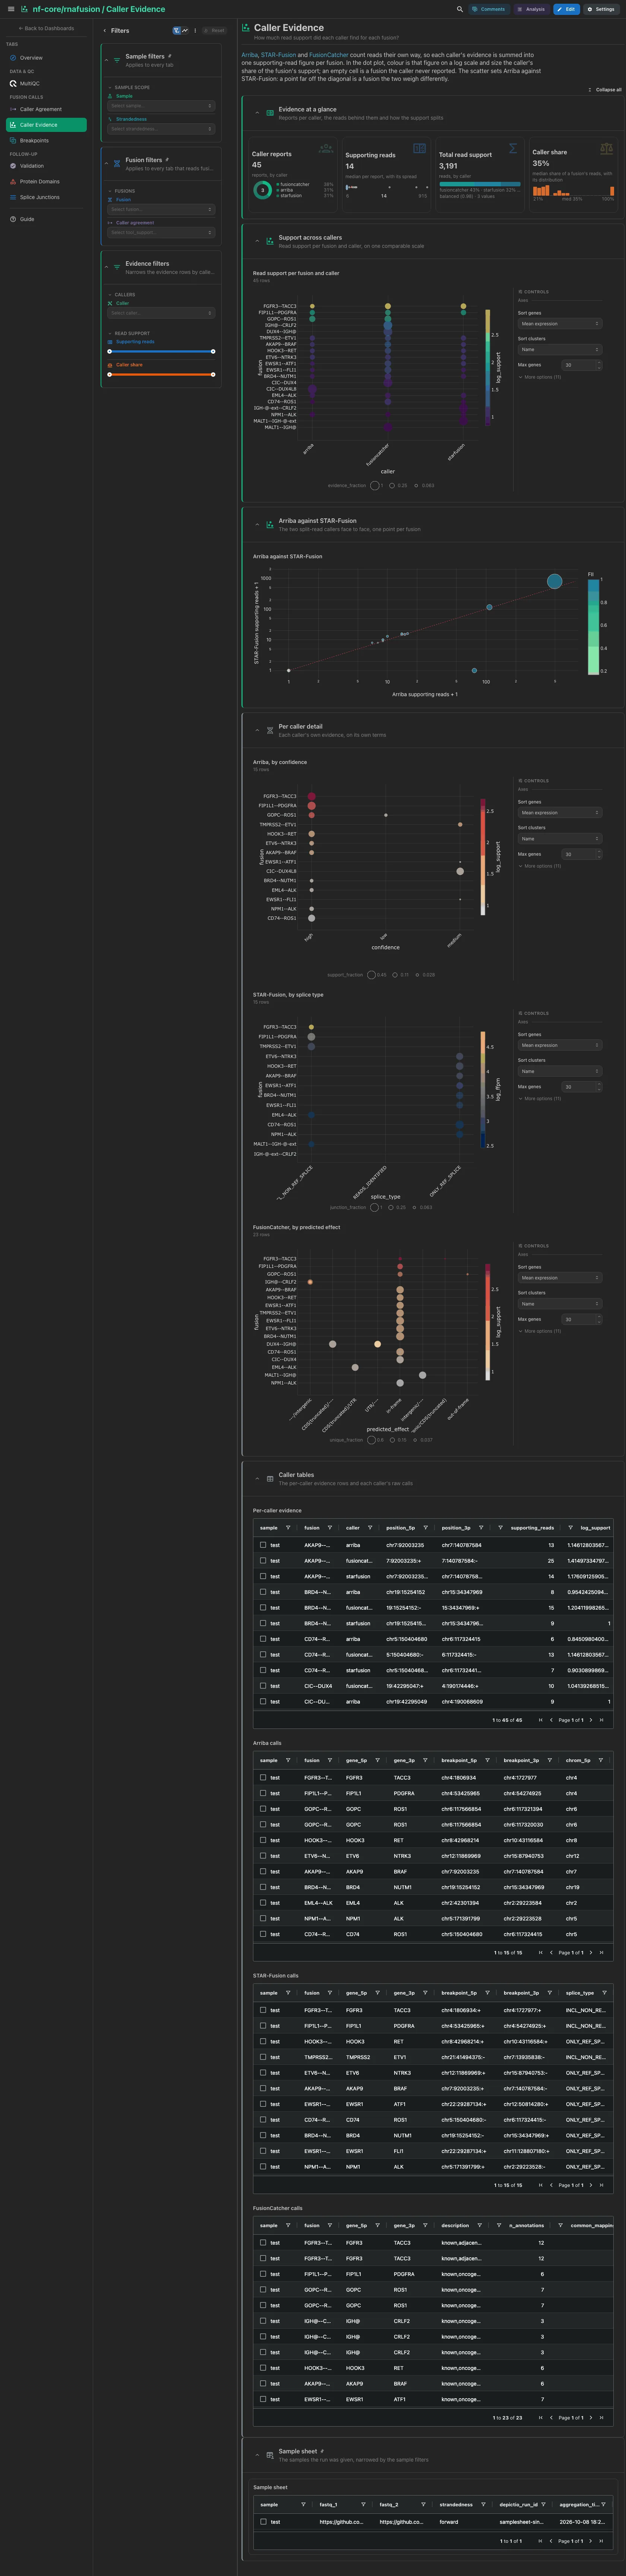
The caller reports by caller, their median read support, the total support per caller and the share of a fusion's reads one caller accounts for. Then the dot plot of read support per fusion and caller, and Arriba against STAR-Fusion on log axes, one point per fusion and sample. Each caller's own dot plot, on its own terms, and the caller tables are collapsed.
Filters and components
Filters · Caller, plus Supporting reads and Caller share
ranges, all on caller_evidence.
| Section | What it holds |
|---|---|
| Evidence at a glance | 4 cards |
| Support across callers | 1 advanced visualization |
| Arriba against STAR-Fusion | Arriba against STAR-Fusion |
| Per caller detail (collapsed) | 3 advanced visualizations, one per caller |
| Caller tables (collapsed) | Per-caller evidence, Arriba calls, STAR-Fusion calls, FusionCatcher calls |
Fusion calls · Where on the genome do the two fusion partners sit?
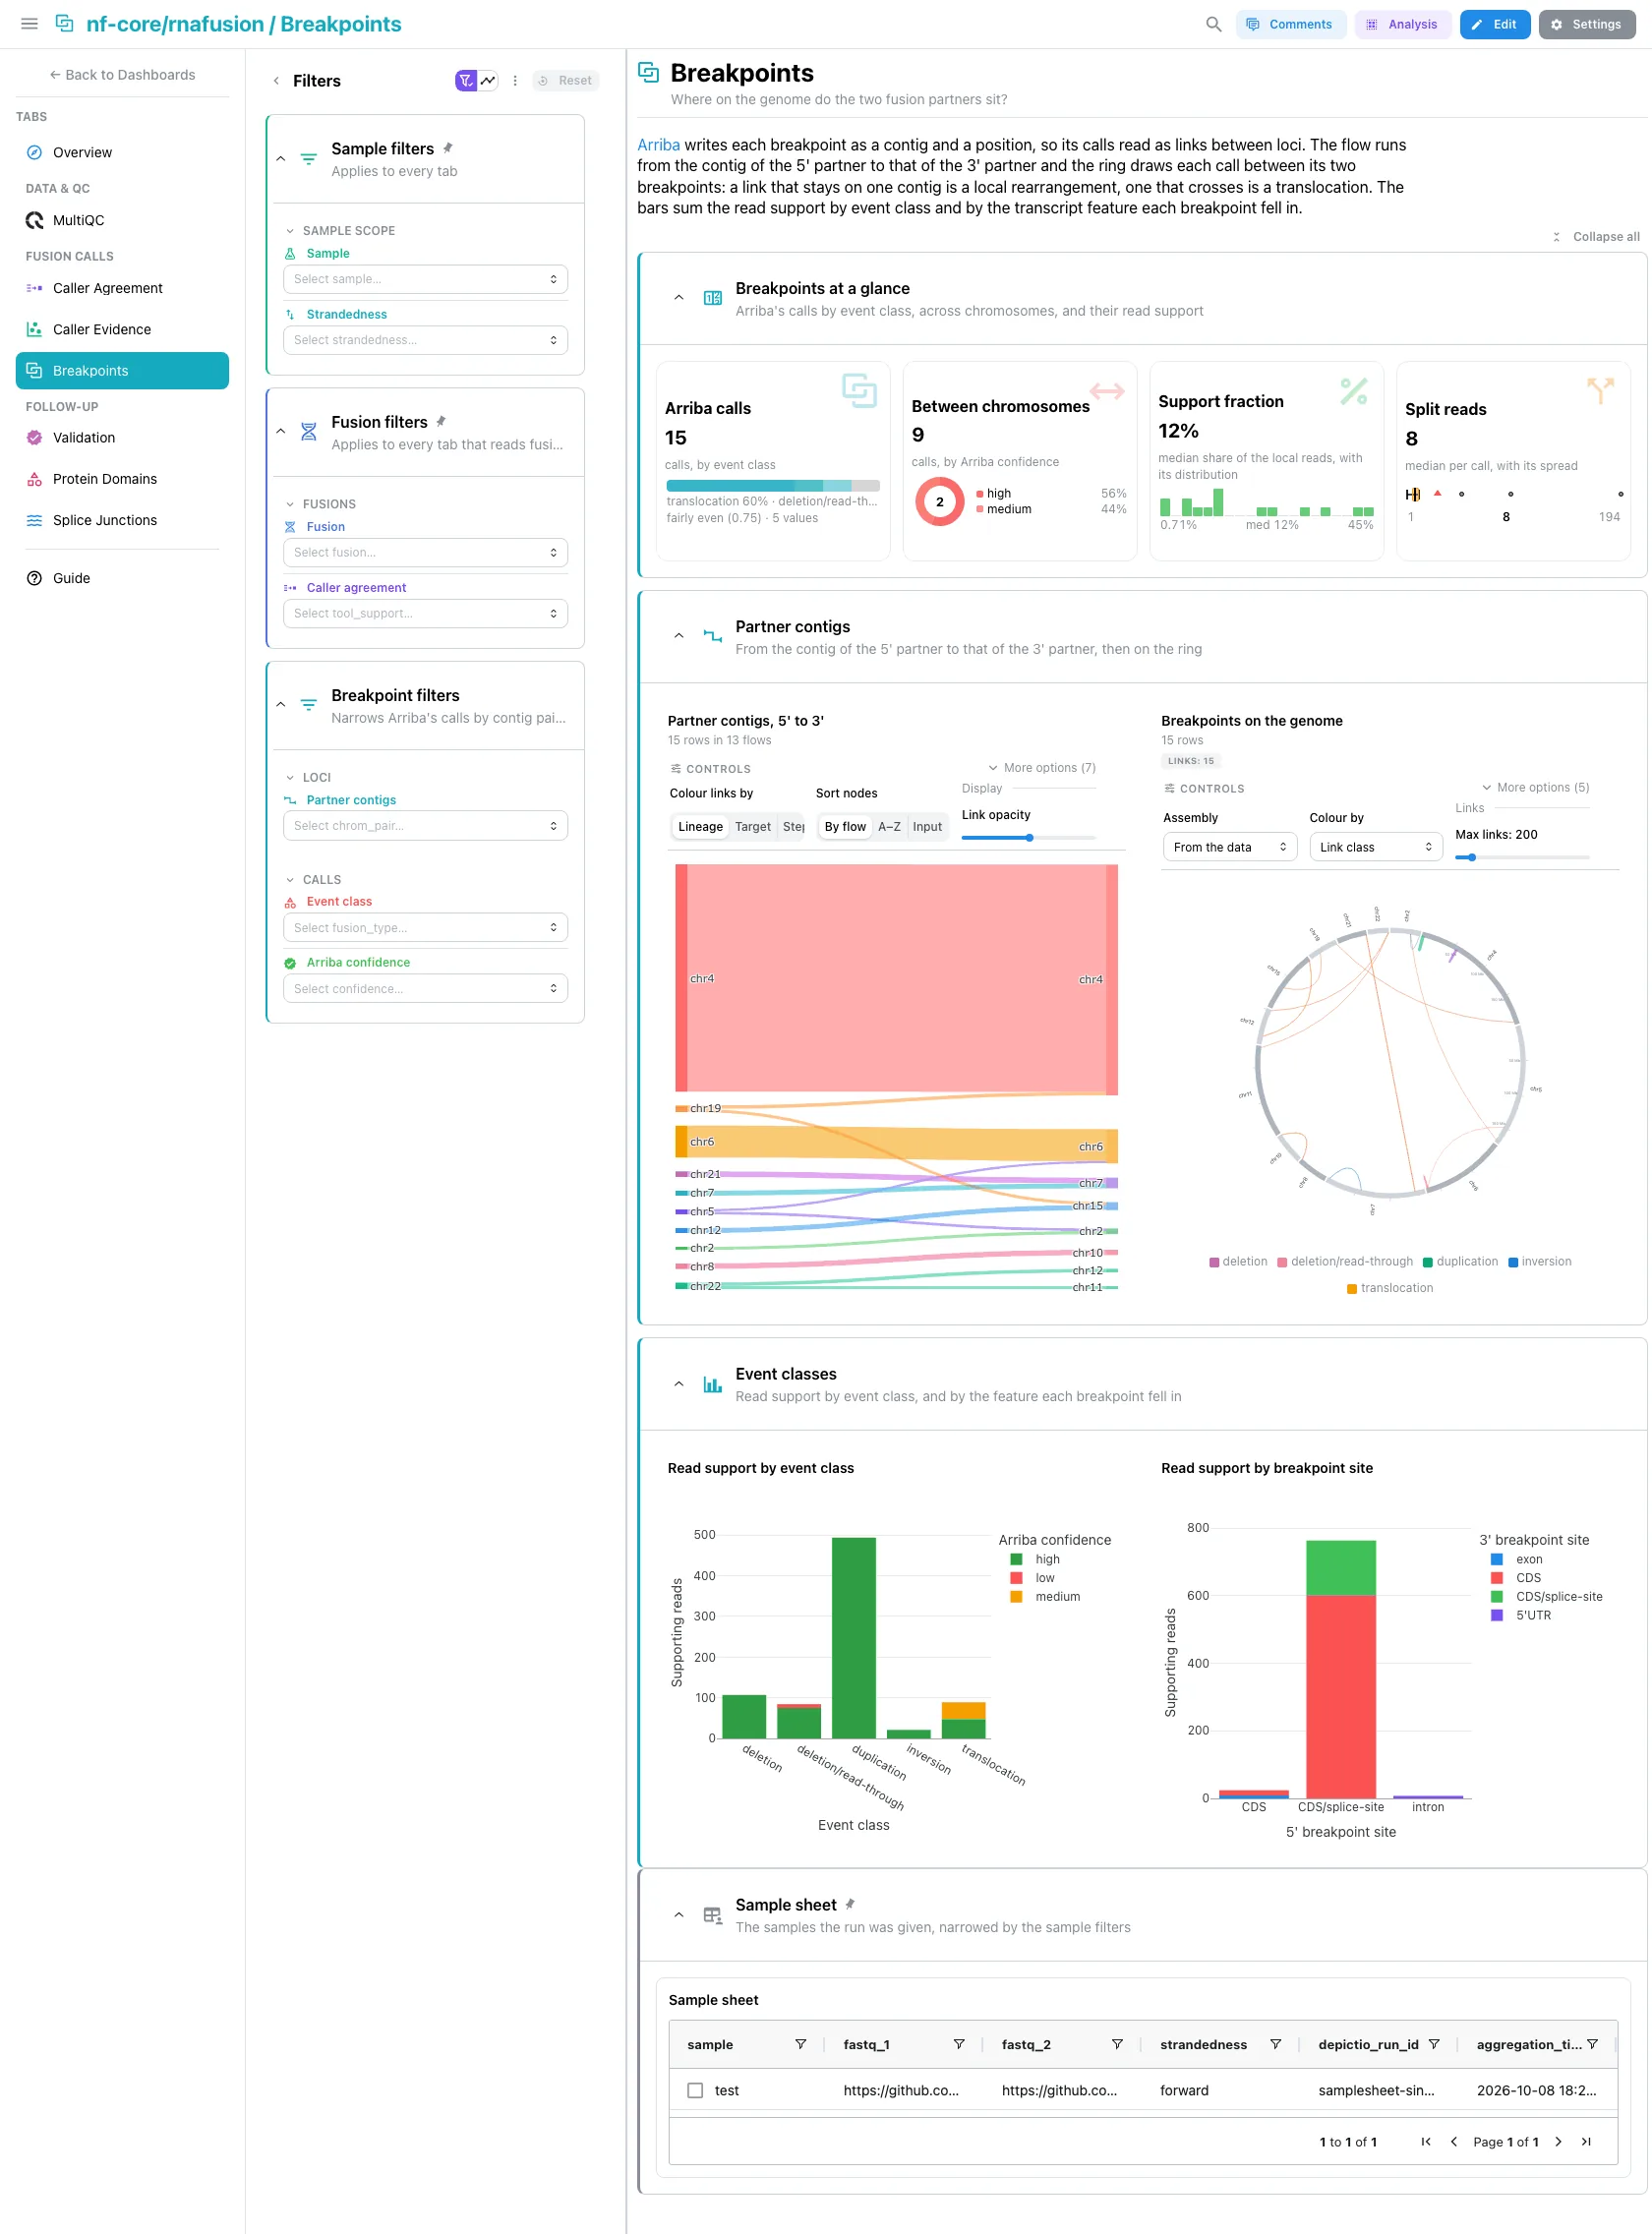
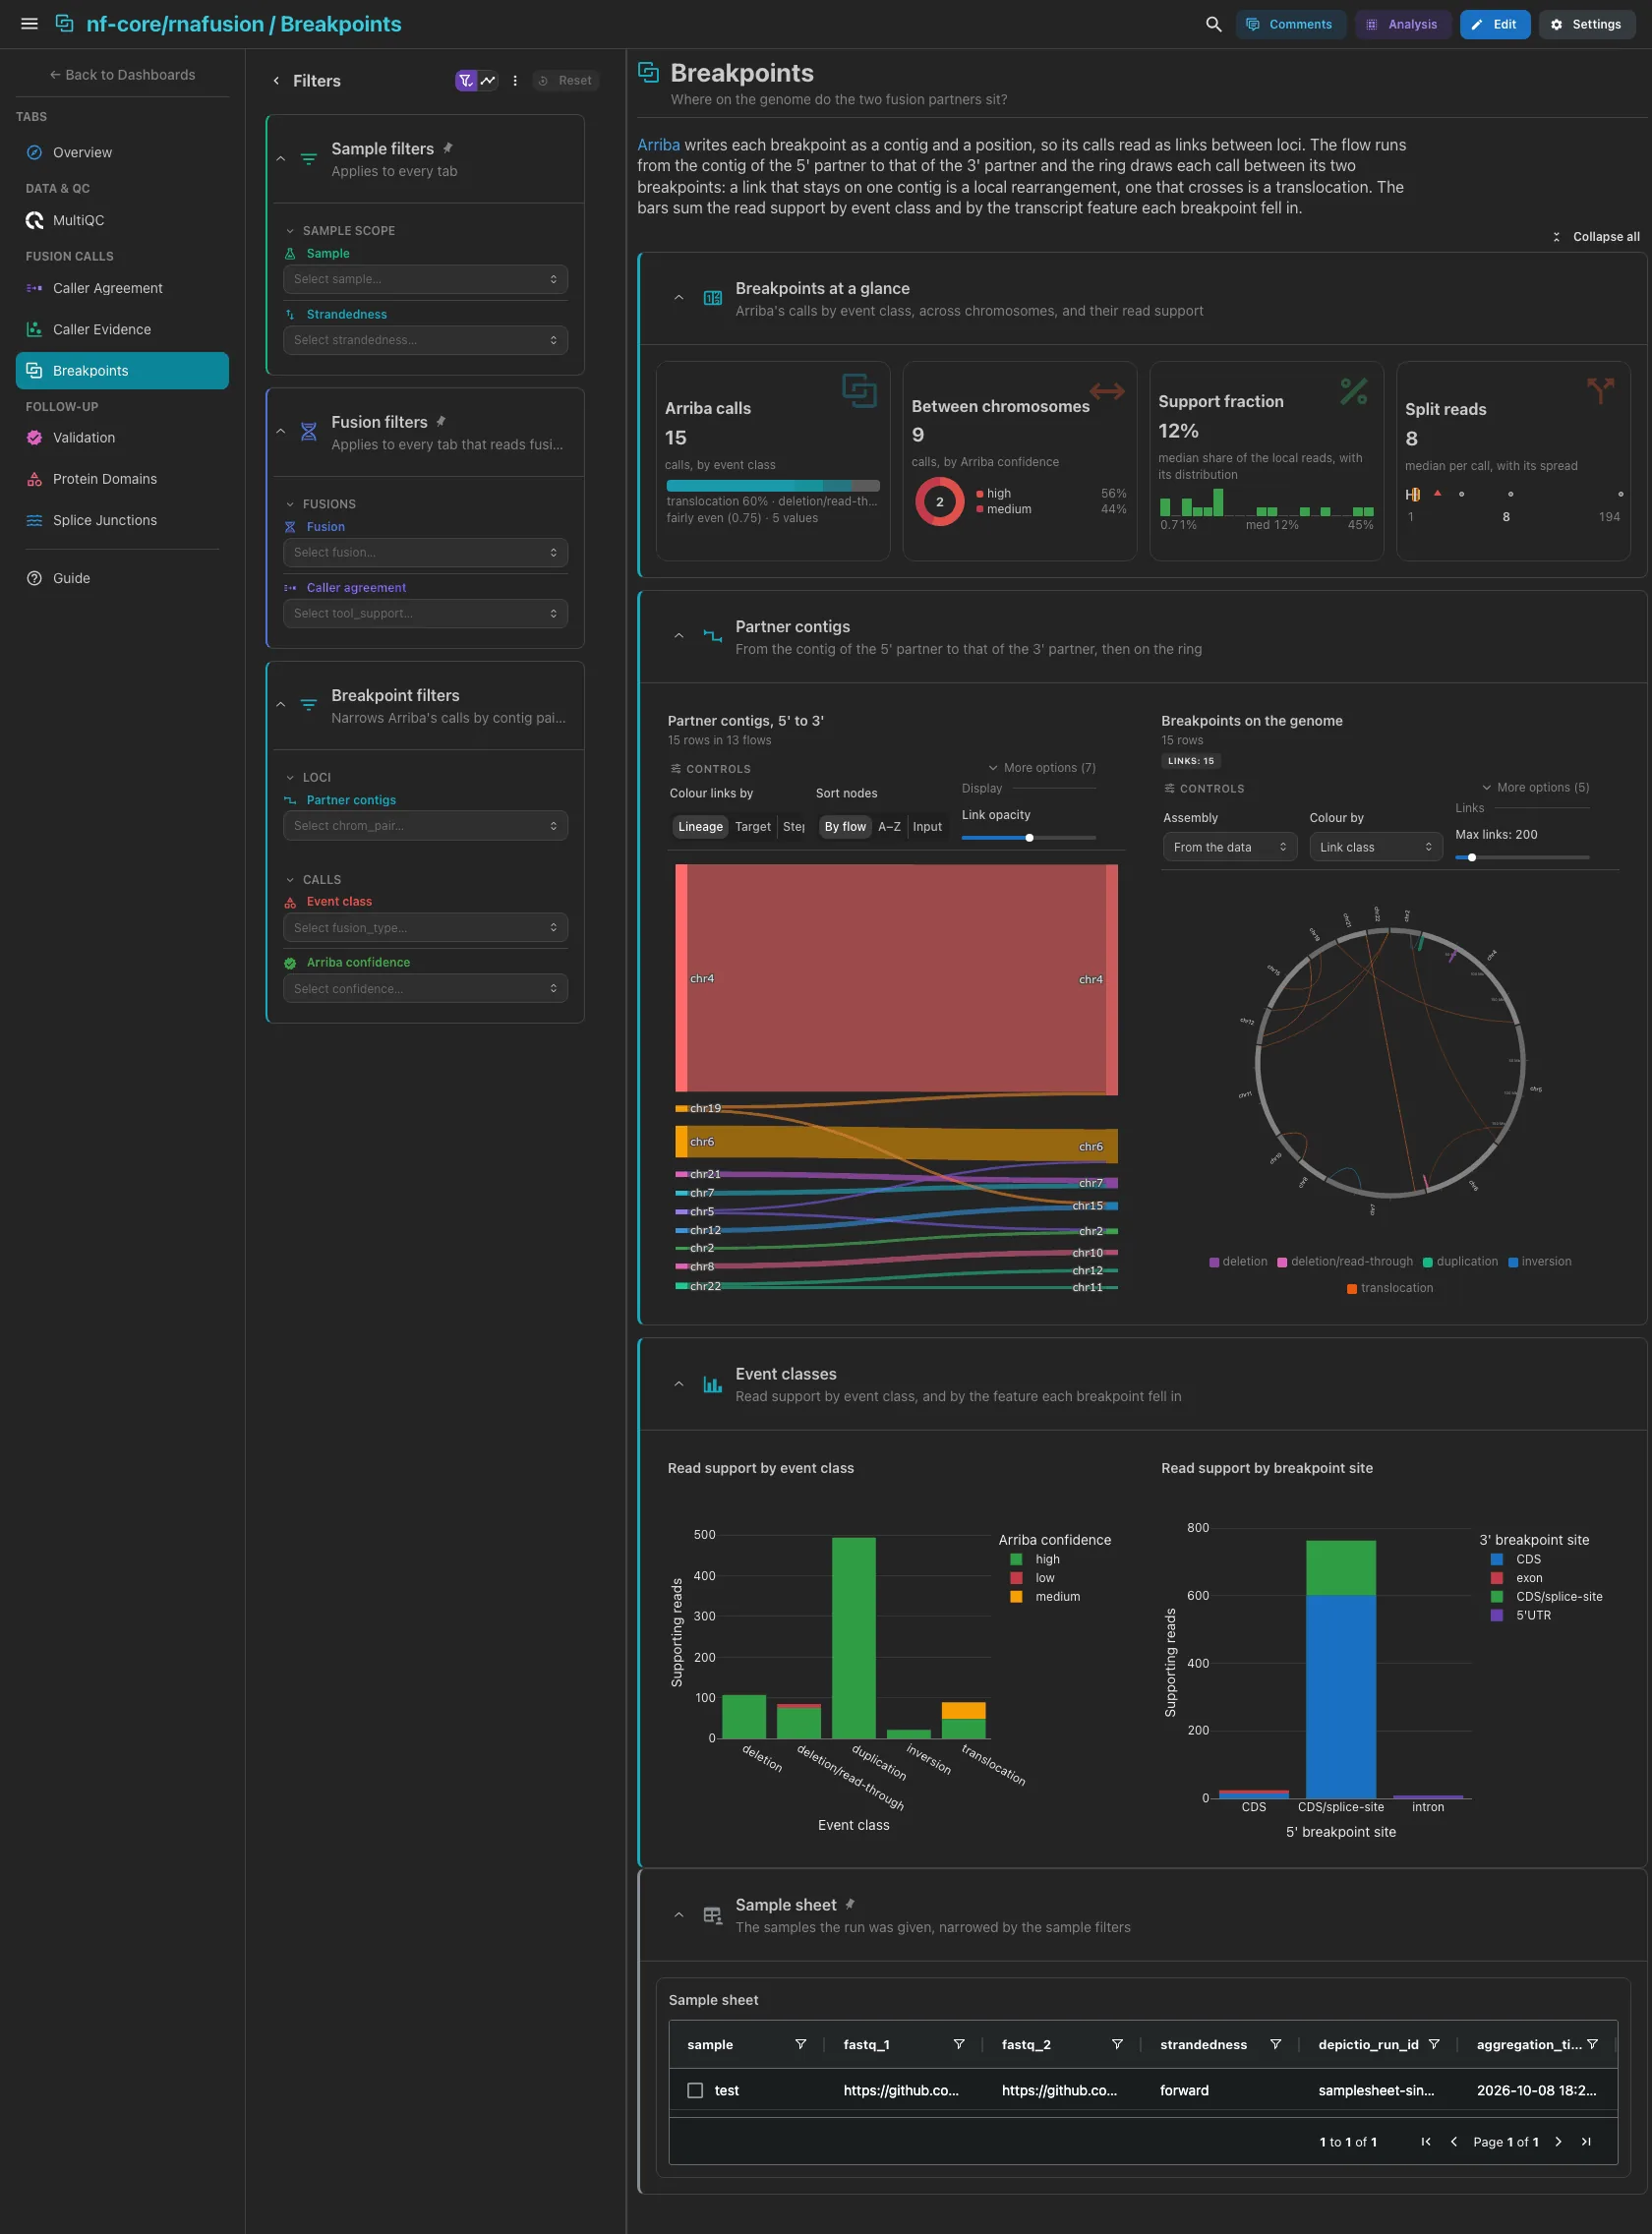
Arriba's calls as loci. Its calls by event class, the calls between chromosomes by confidence, the share of the local reads that support a call and the split reads. Then the flow from the contig of the 5' partner to that of the 3' partner beside the chord ring of the same calls, and the read support by event class and by breakpoint site.
Filters and components
Filters · Partner contigs, Event class and Arriba confidence on
arriba_fusions. They narrow the Arriba calls, not the chord, which the
sample and fusion filters reach.
| Section | What it holds |
|---|---|
| Breakpoints at a glance | 4 cards |
| Partner contigs | 2 advanced visualizations |
| Event classes | Read support by event class, Read support by breakpoint site |
Follow-up · Which calls hold up when the reads are re-aligned?
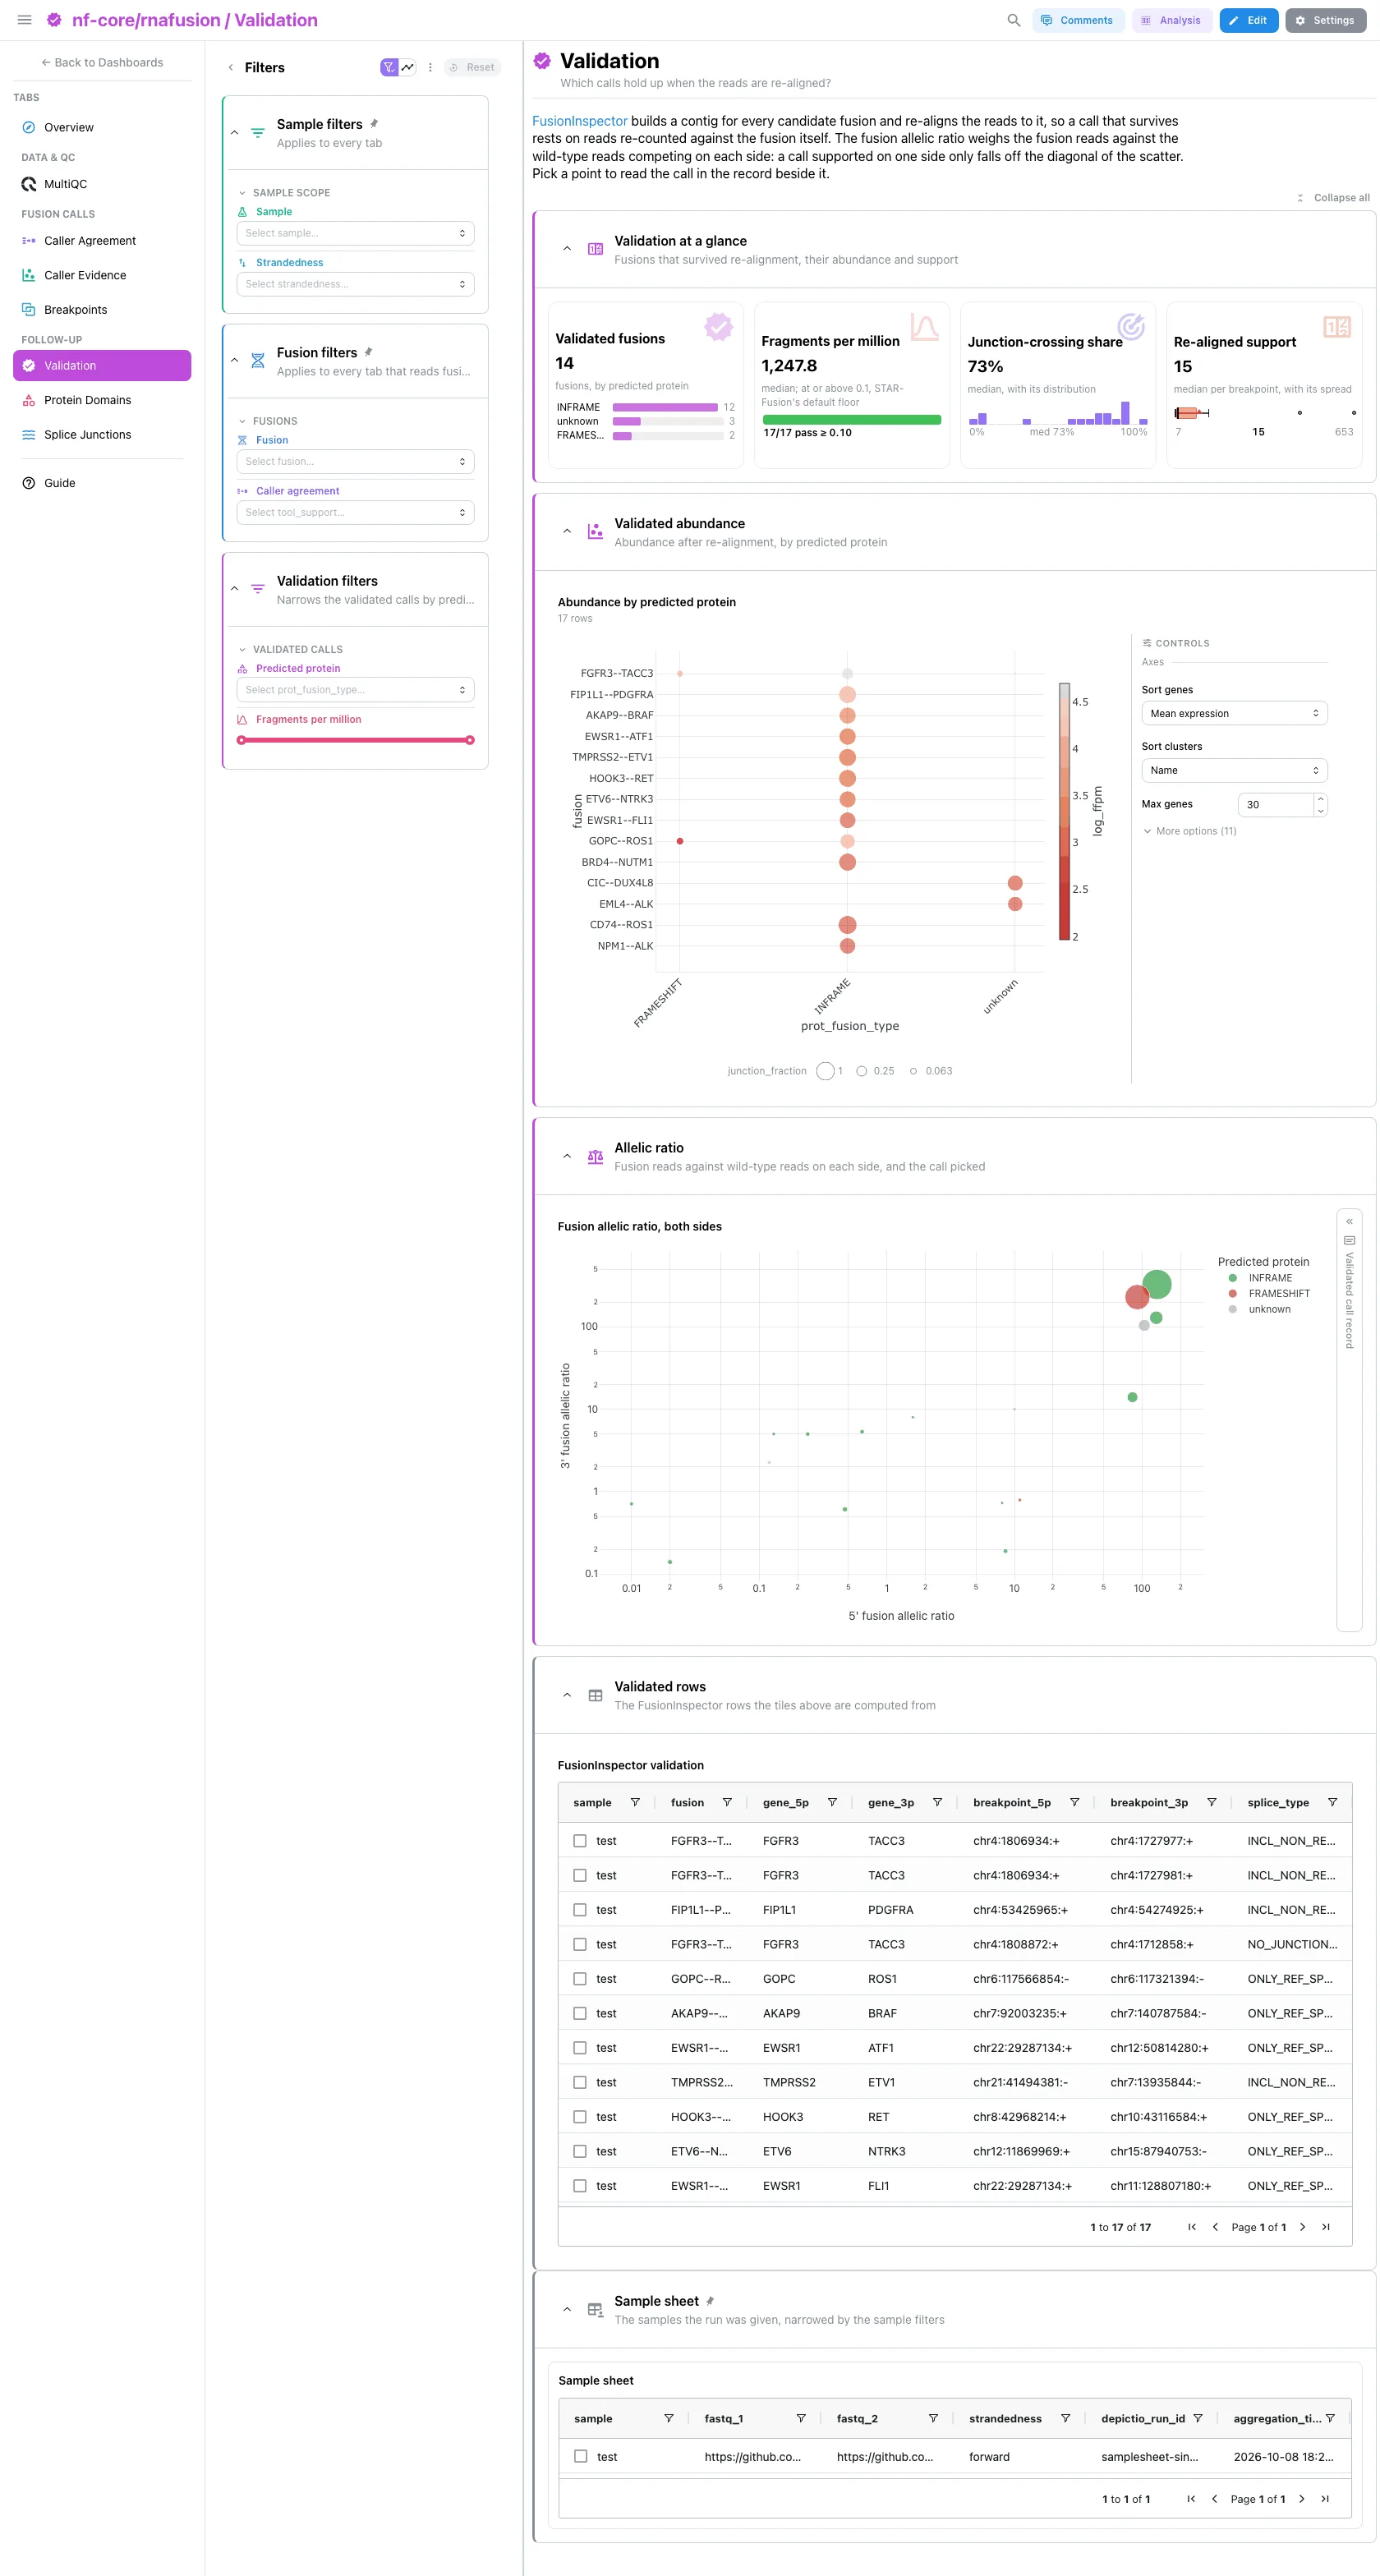
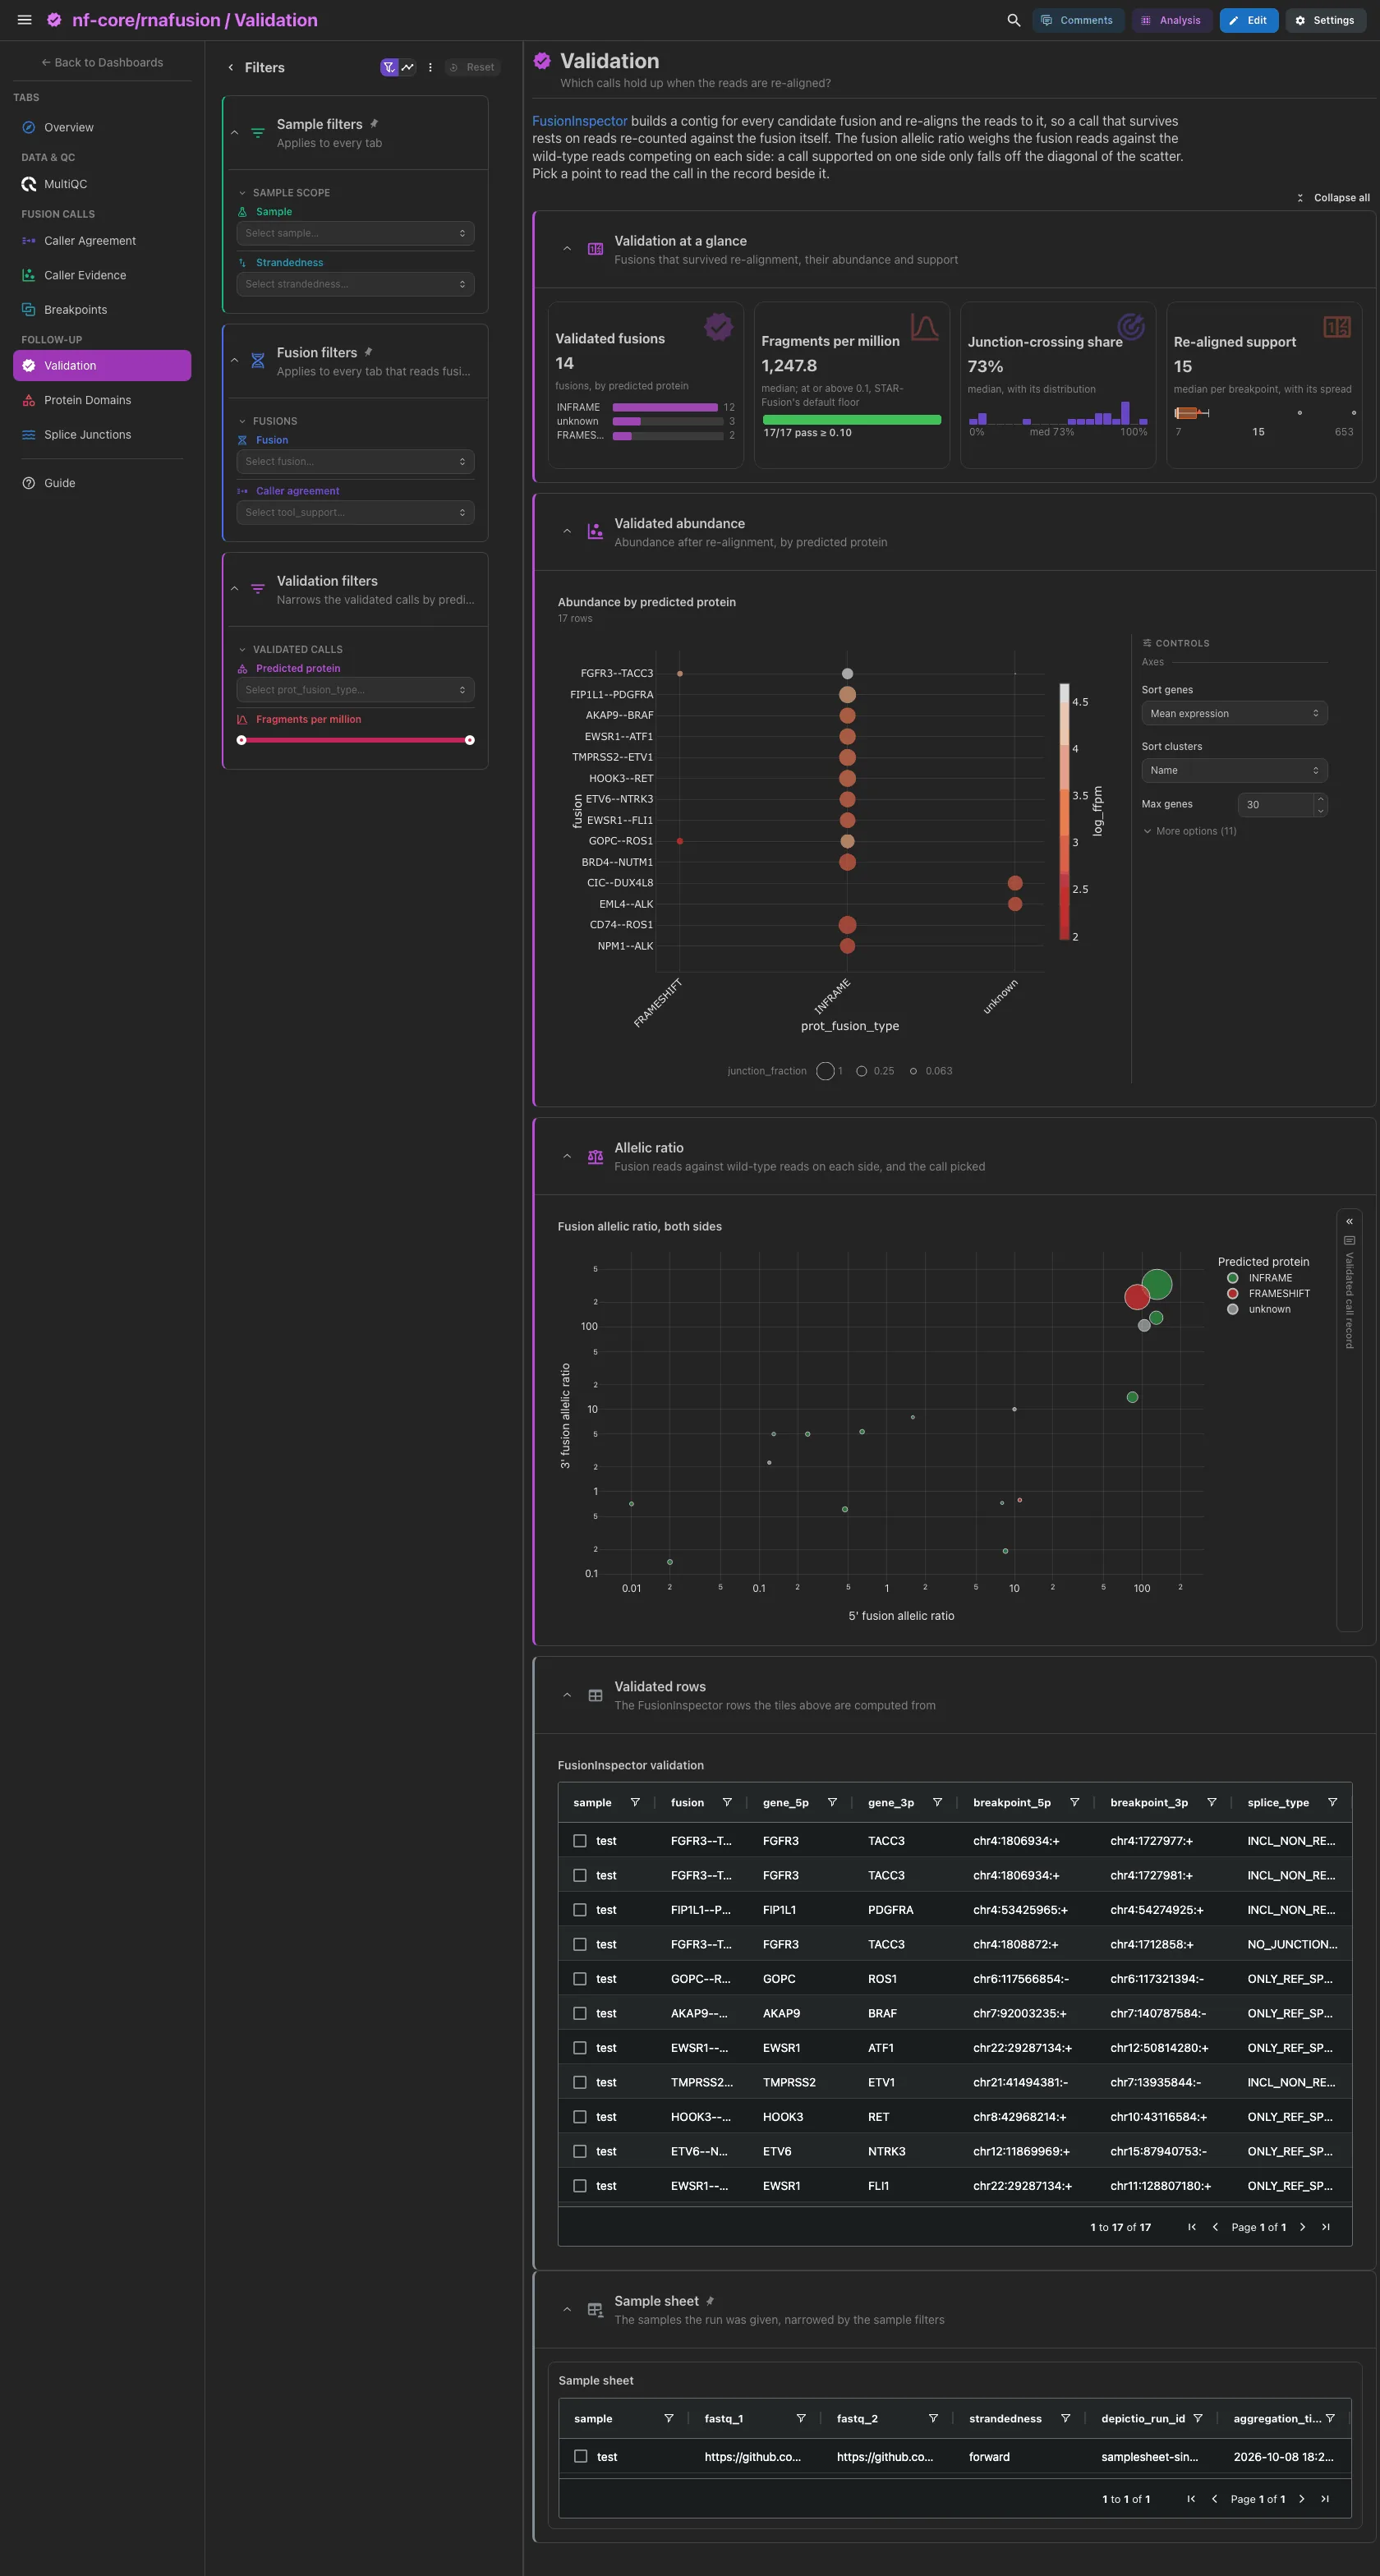
FusionInspector's re-quantified calls. The validated fusions by predicted protein, the median fragments per million against STAR-Fusion's default floor, the share of the support that crosses the junction and the re-aligned support. Then the abundance by predicted protein, and the 5' against the 3' fusion allelic ratio on log axes beside the record of the call you pick: a call supported on one side only falls off the diagonal.
Filters and components
Filters · Predicted protein and a Fragments per million range on
fusioninspector_fusions.
| Section | What it holds |
|---|---|
| Validation at a glance | 4 cards |
| Validated abundance | 1 advanced visualization |
| Allelic ratio | Fusion allelic ratio, both sides + a validated call record card |
| Validated rows (collapsed) | FusionInspector validation |
Follow-up · Which protein domains would each fusion protein keep?
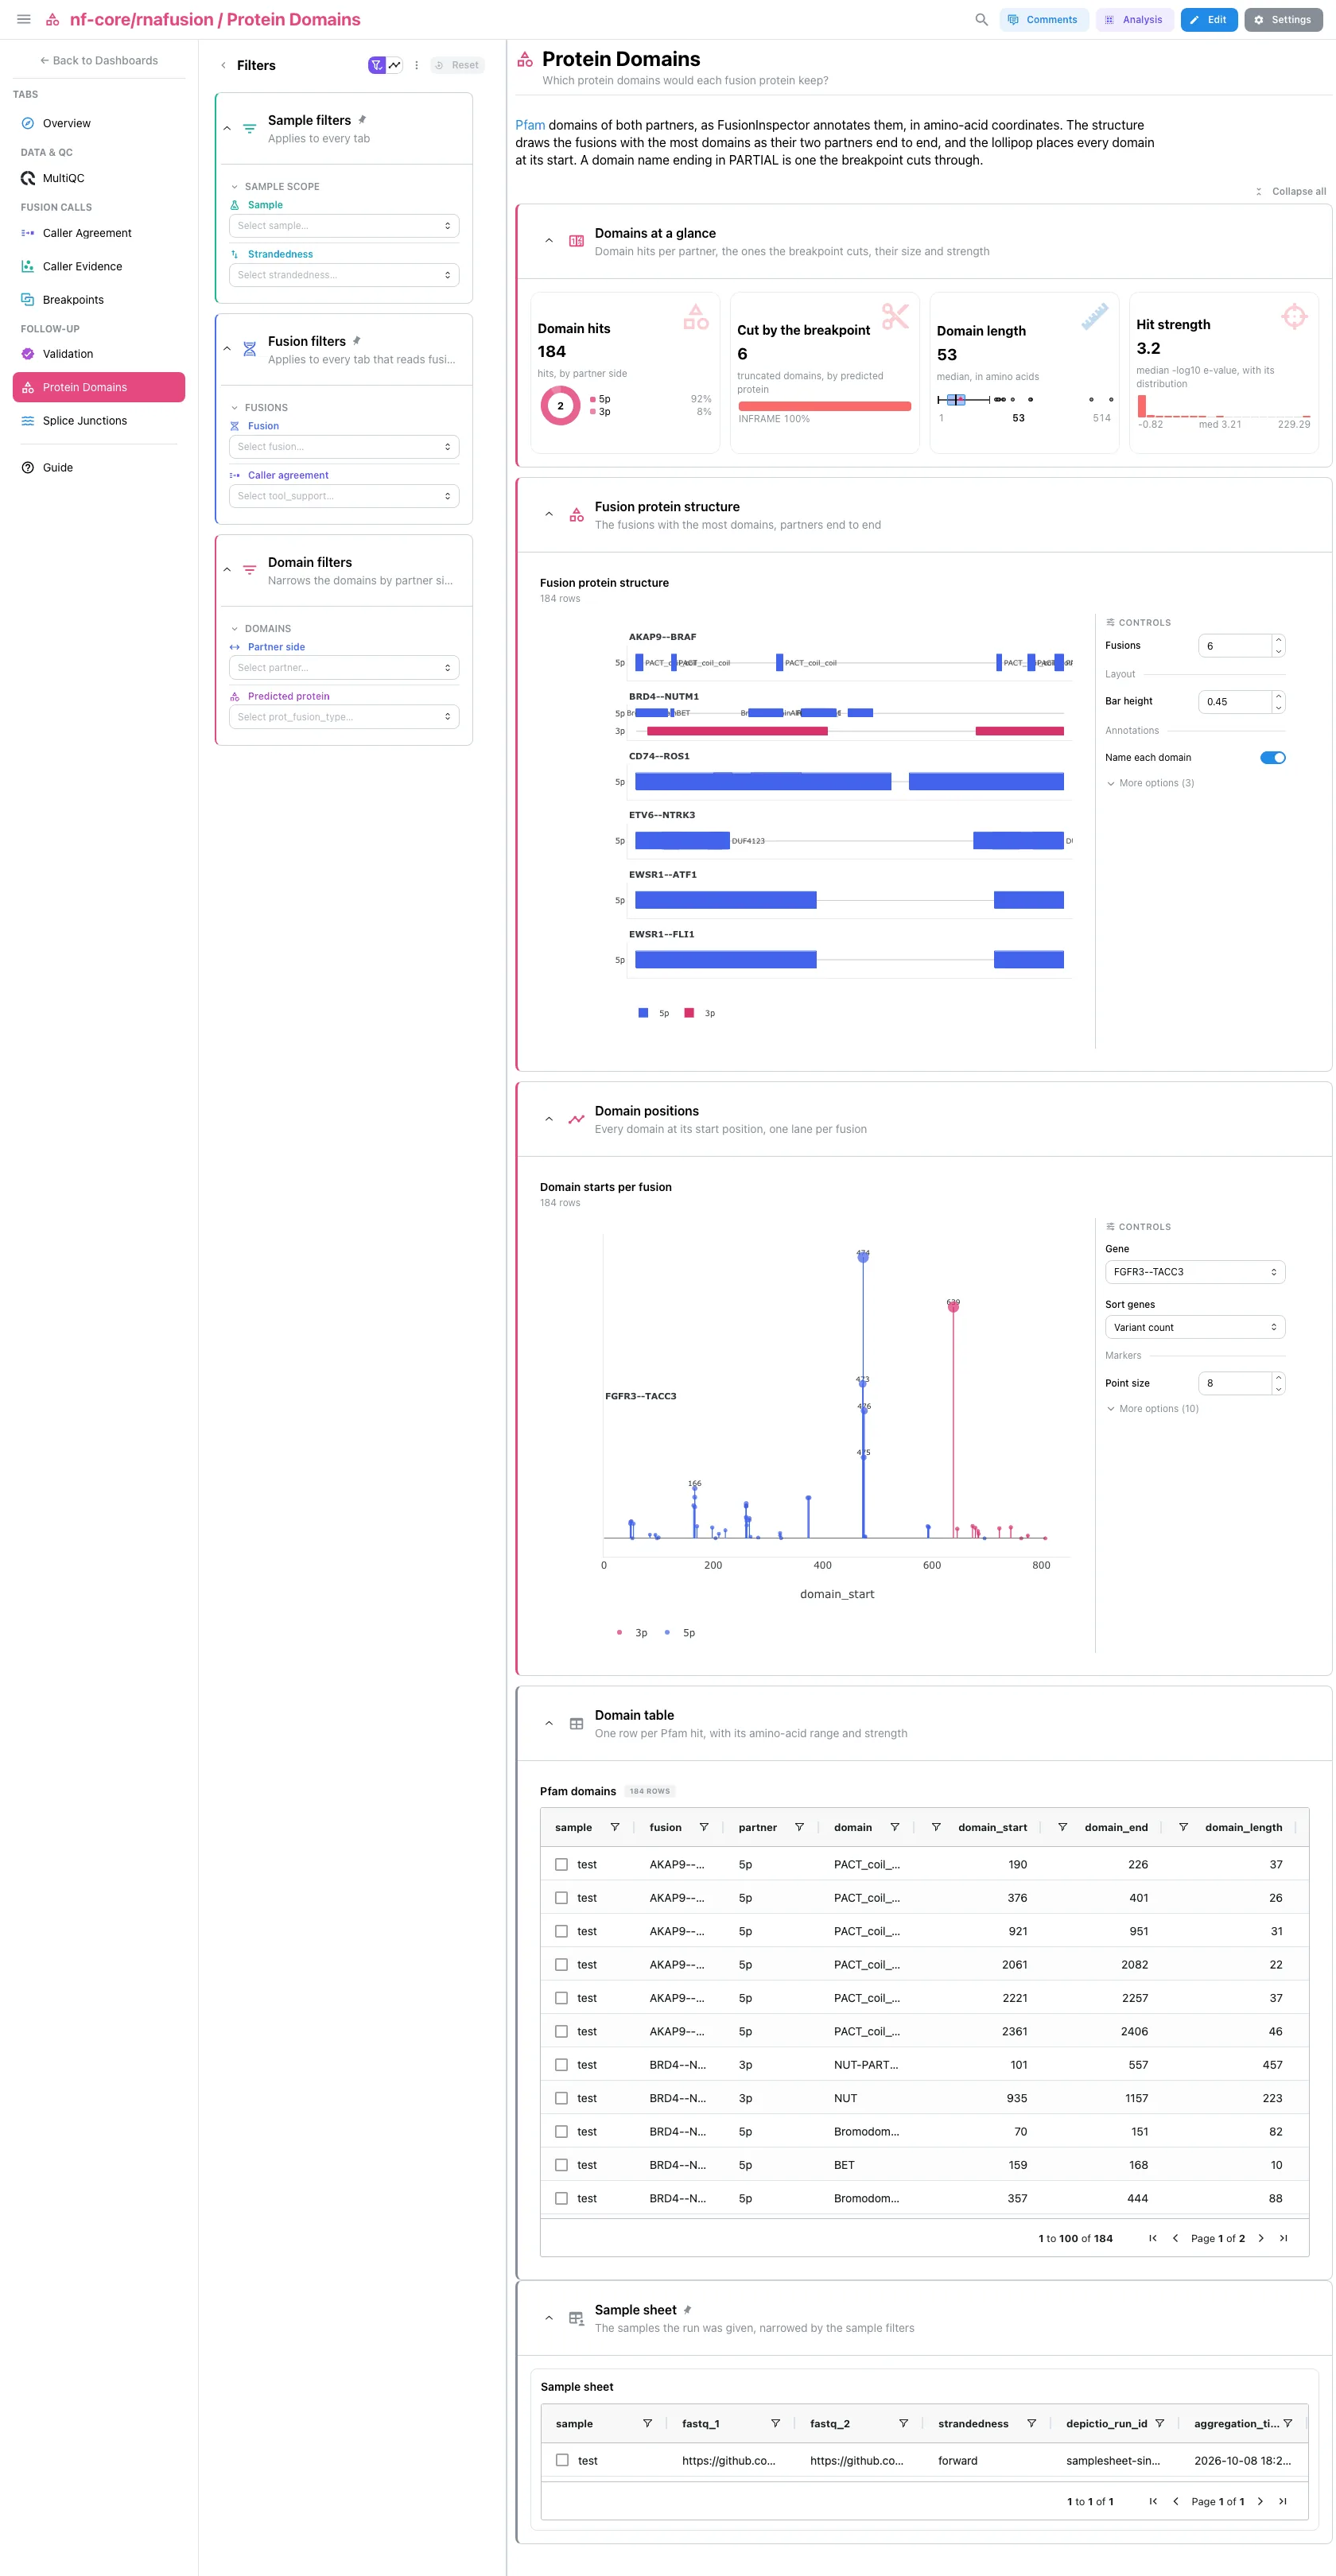
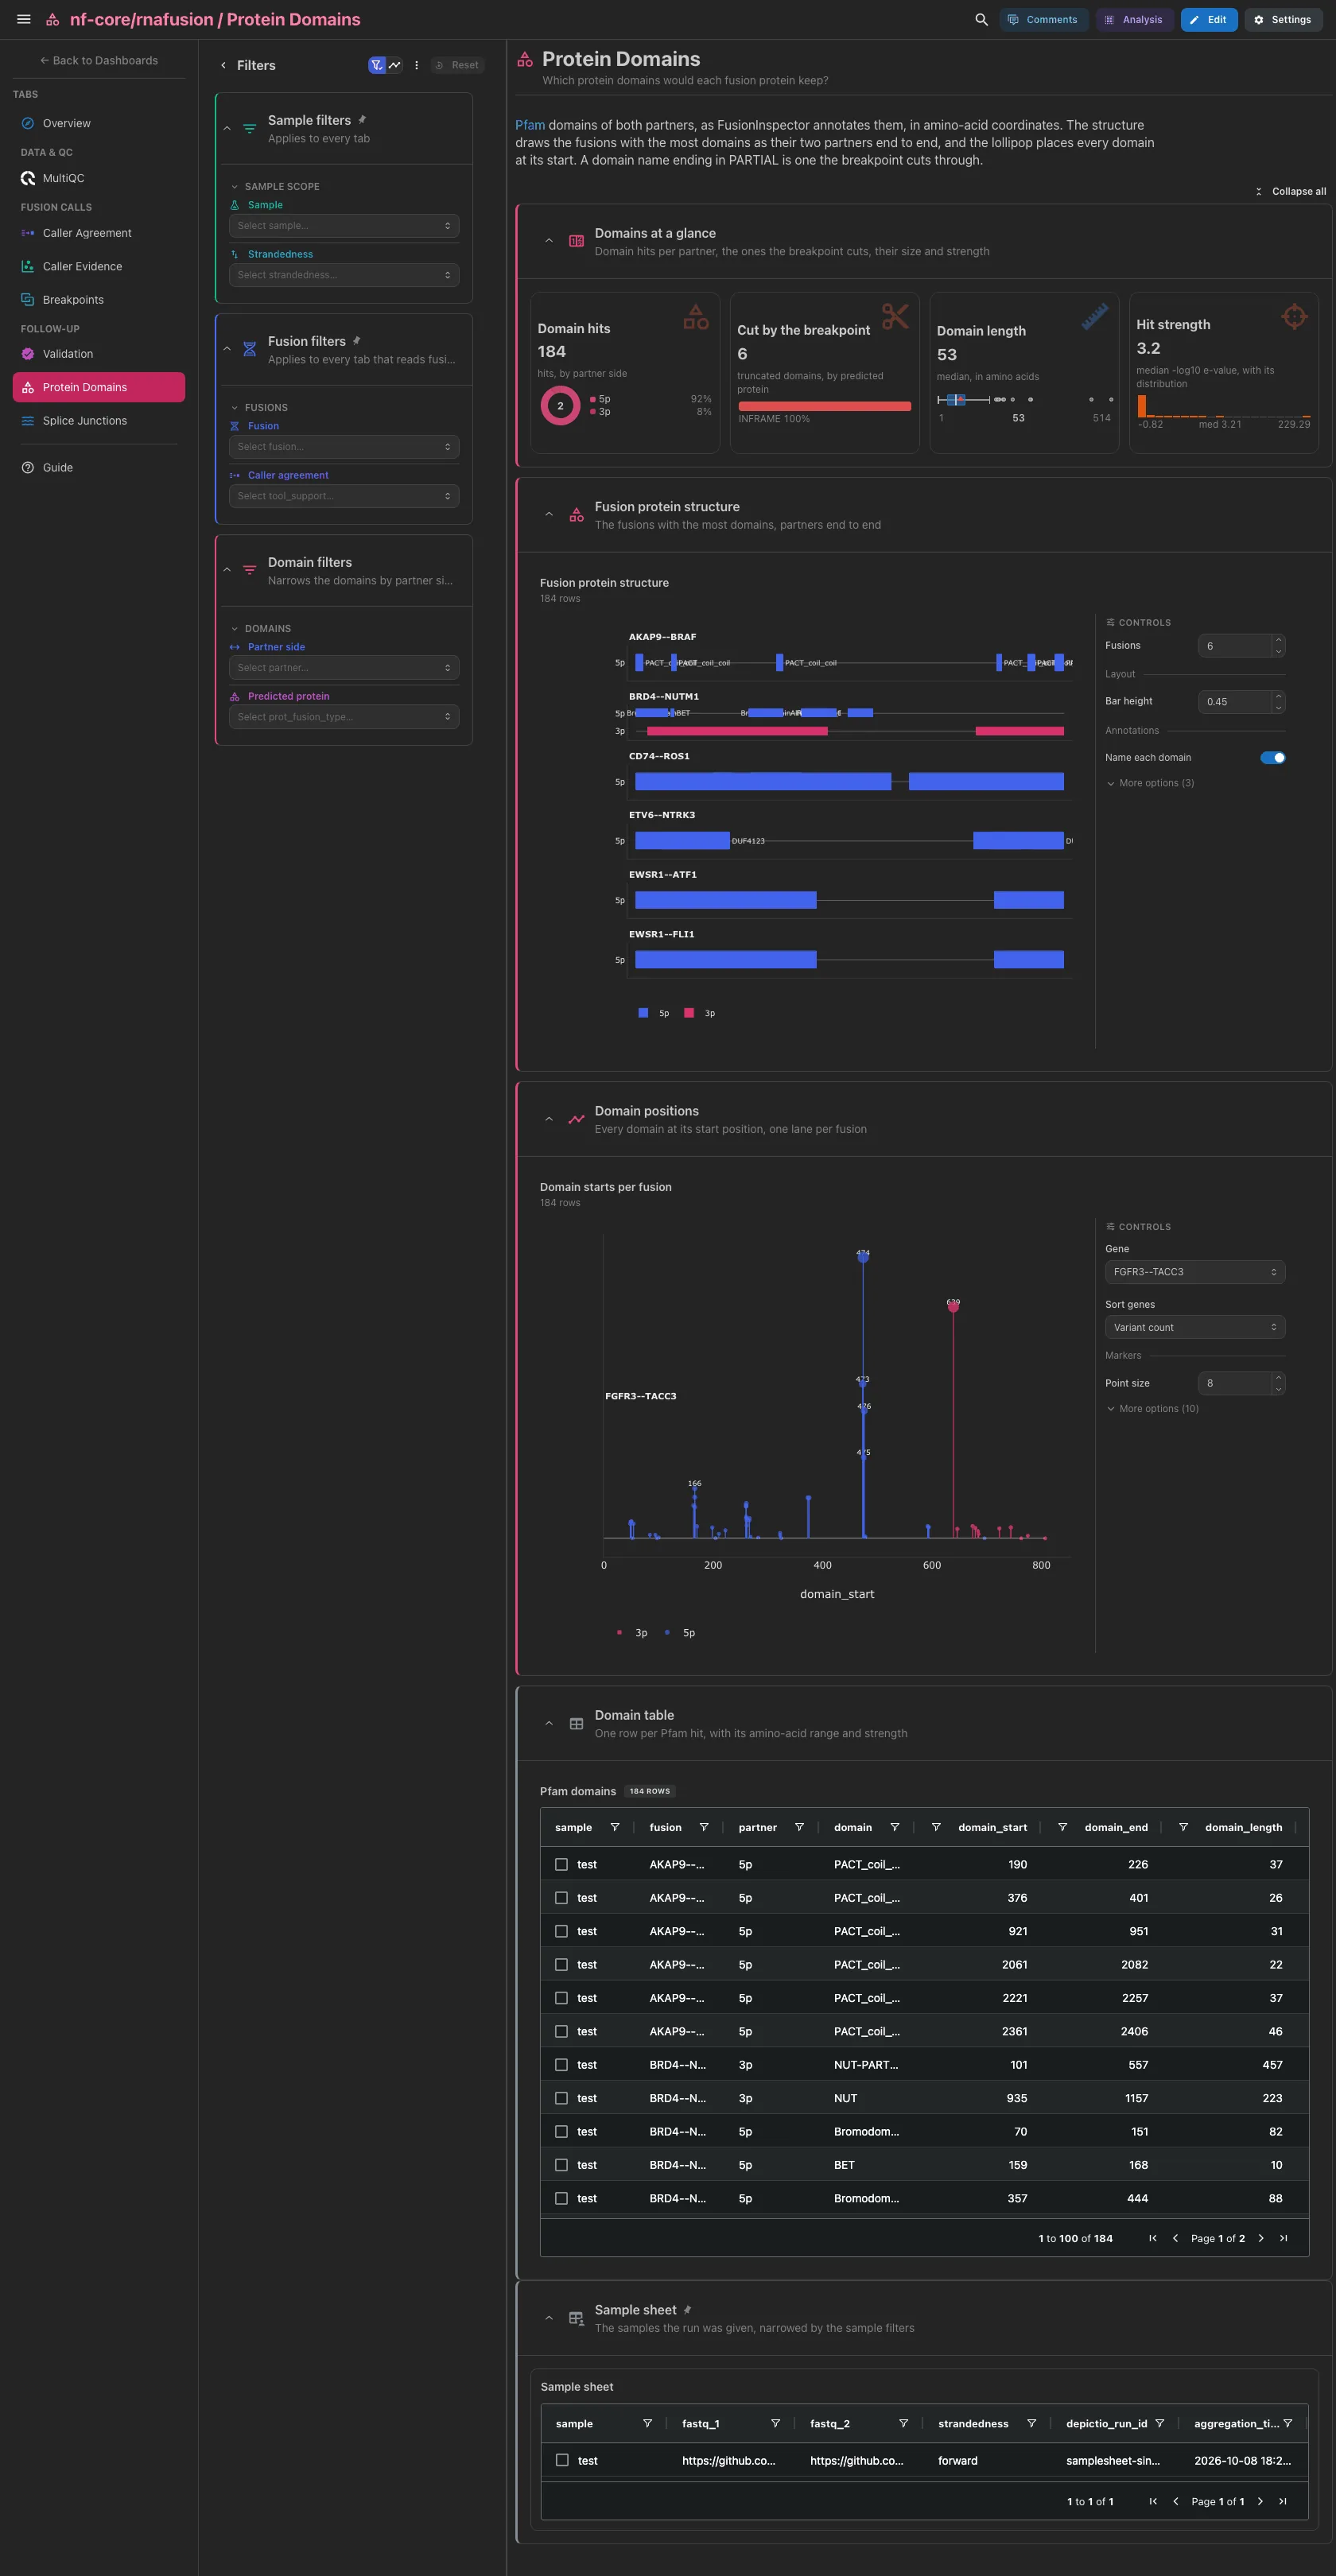
The Pfam domains of both partners. The domain hits by partner side, the hits
the breakpoint cuts through, the domain length and the hit strength. Then the
fusion protein structure, the fusions with the most domains drawn as their
partners end to end, and the lollipop of every domain at its start position. A
domain name ending in PARTIAL is one the breakpoint cuts through.
Filters and components
Filters · Partner side and Predicted protein on
fusion_protein_domains.
| Section | What it holds |
|---|---|
| Domains at a glance | 4 cards |
| Fusion protein structure | 1 advanced visualization |
| Domain positions | 1 advanced visualization |
| Domain table (collapsed) | Pfam domains |
Follow-up · Which splice junctions do the reads support, and how strongly?
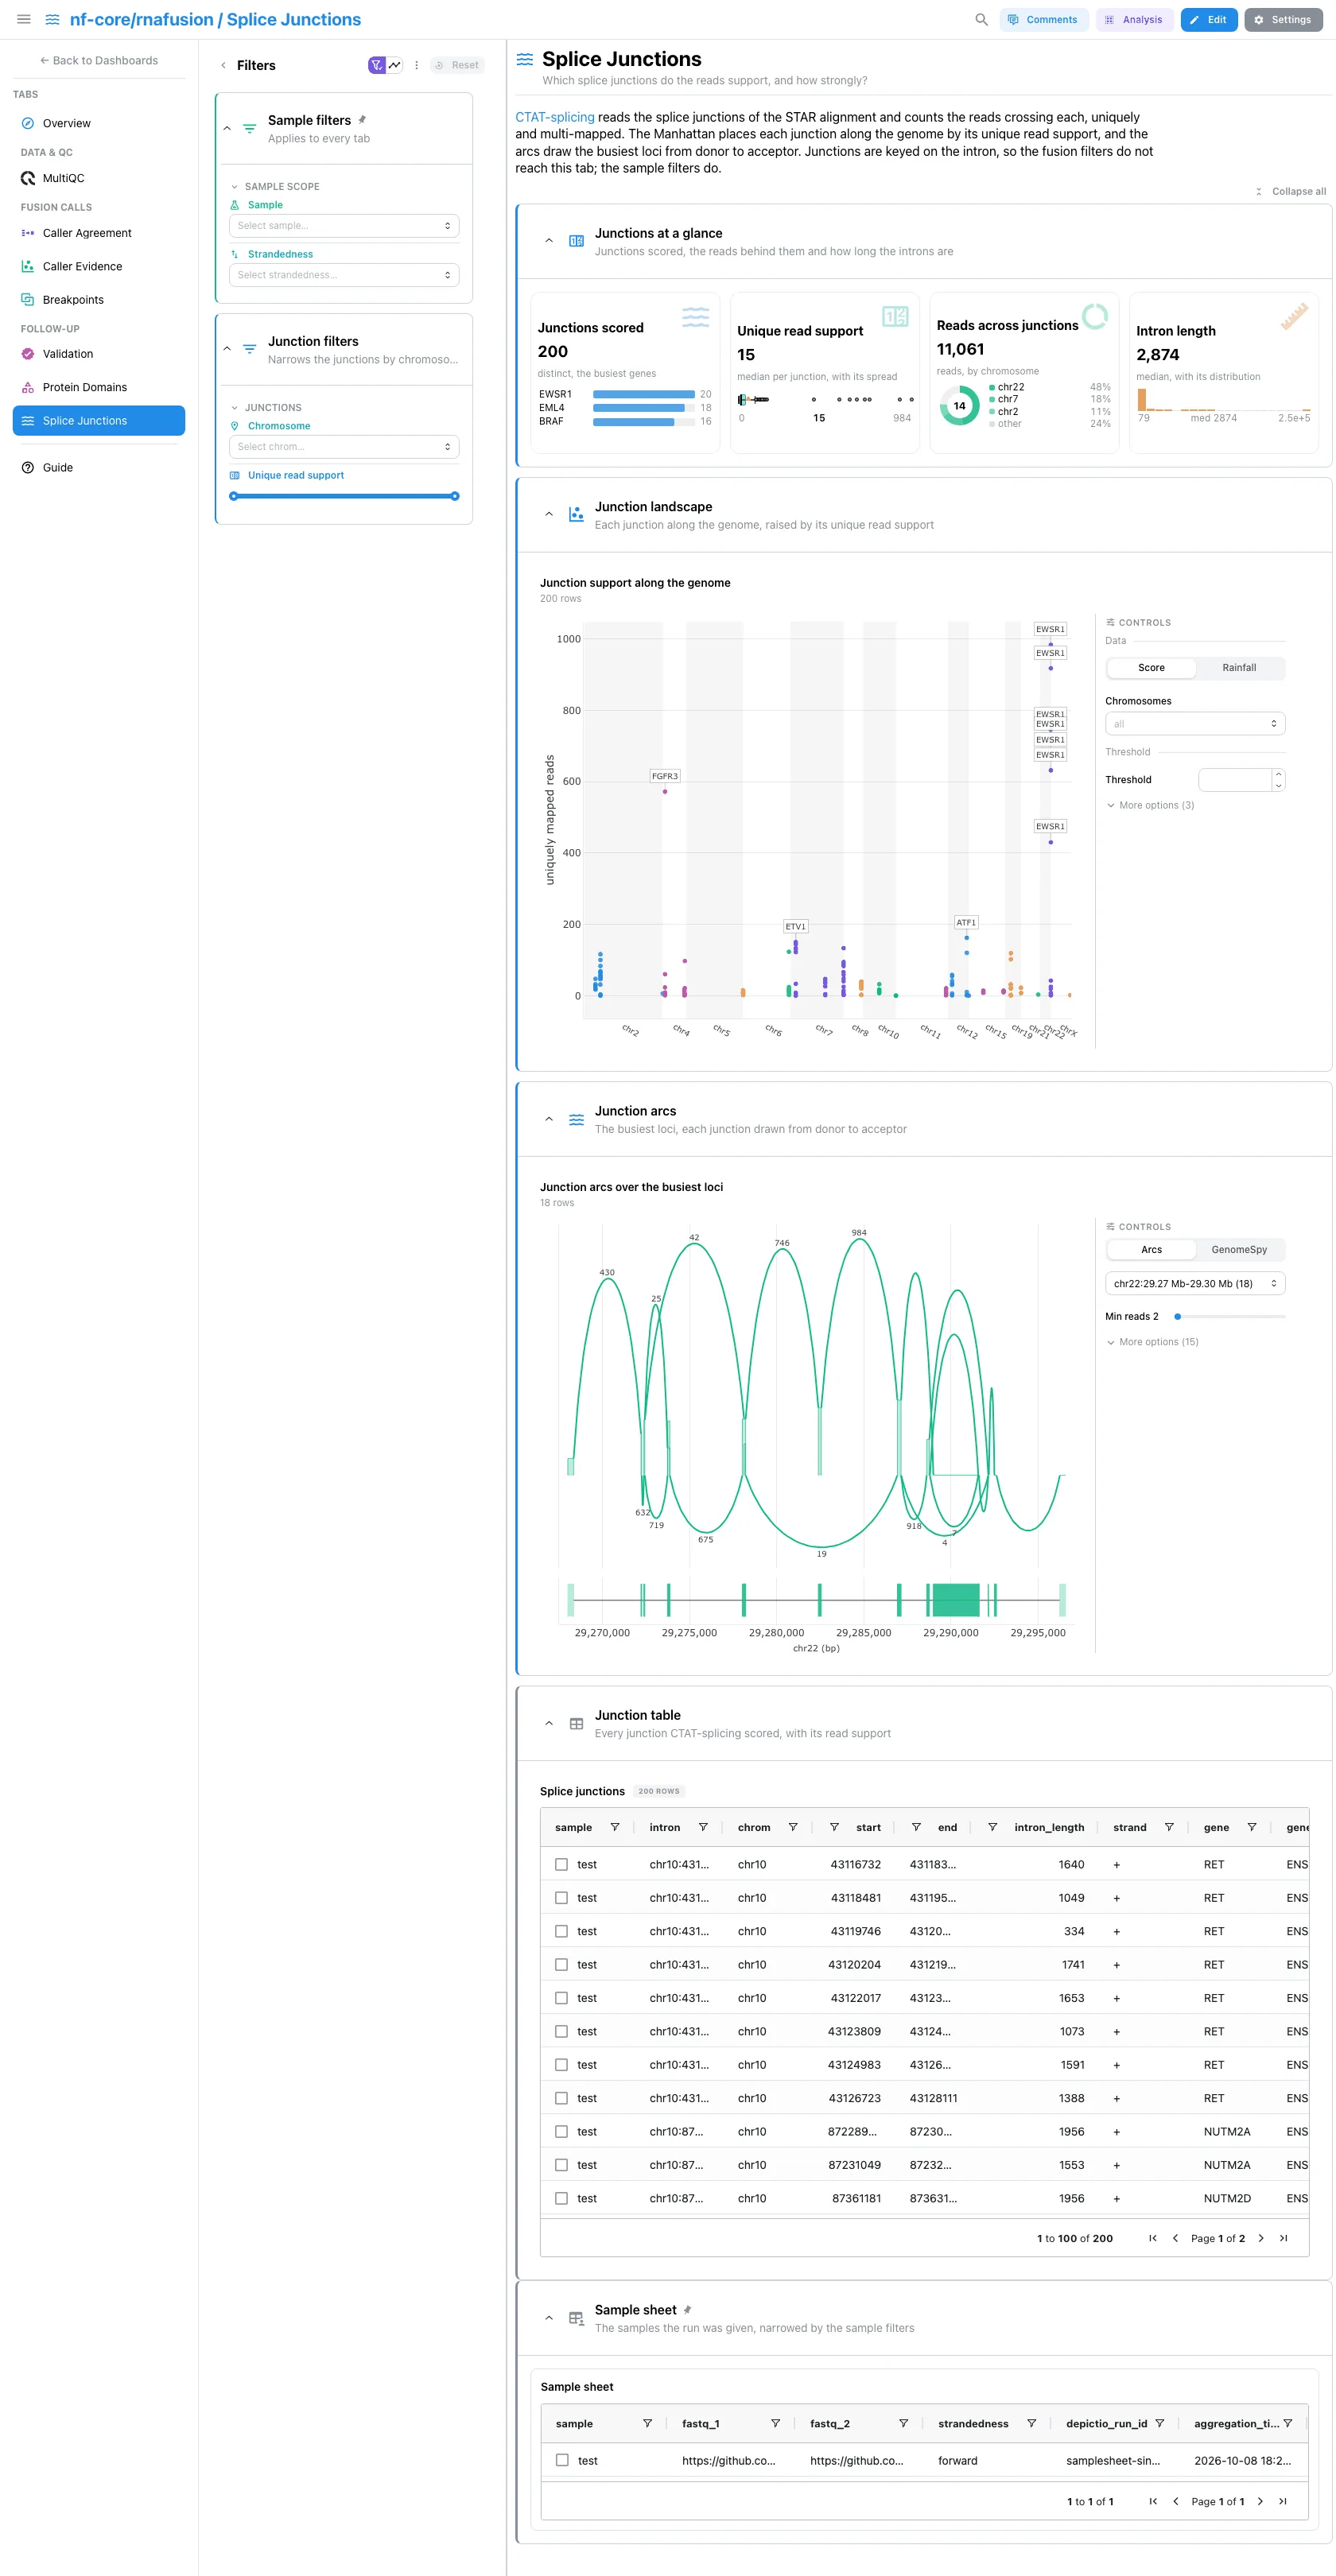
CTAT-splicing's junctions. The distinct junctions ranked by gene, the unique read support, the reads summed over every junction by chromosome and the intron length. Then the Manhattan of junction support along the genome and the junction arcs over the busiest loci.
Filters and components
Filters · Chromosome and a Unique read support range on
splice_junctions.
| Section | What it holds |
|---|---|
| Junctions at a glance | 4 cards |
| Junction landscape | 1 advanced visualization |
| Junction arcs | 1 advanced visualization |
| Junction table (collapsed) | Splice junctions |
Splice junctions are keyed on the intron
CTAT-splicing scores the introns of a gene, so a fusion name has nothing to match against. The fusion filters stay off the Splice Junctions tab on purpose: the sample filters and the tab's own junction filters narrow it.
Fusions select on fusion: the ranked fusion bars, the Arriba against
STAR-Fusion and allelic-ratio scatters, and the consensus, evidence, caller,
FusionInspector and Pfam tables. The sample sheet selects on sample, and the
junction Manhattan and junction table select on gene, which stays inside the
Splice Junctions tab. A pick narrows every tile that reads the same collection or
one linked from it. The partner chords, the flow, the UpSet and the dot plots do
not select.
Running the pipeline
Depictio reads the output of nf-core/rnafusion, it does not run the pipeline. Build the references once, then run the pipeline:
nextflow run nf-core/rnafusion -r 4.1.3 \
  --input samplesheet.csv \
  --genomes_base /path/to/references \
  --tools arriba,starfusion,fusioncatcher,ctatsplicing \
  --outdir results \
  -profile docker
Then point Depictio at the results:
See nf-co.re/rnafusion/usage for full pipeline documentation.
Required data structure
Point depictio ingest at the directory holding the pipeline output. Depictio scans
recursively and matches on file name. The samplesheet is the one file rnafusion
does not publish: put it under input/, or pass --var SAMPLESHEET_FILE=....
<DATA_ROOT>/
├── input/
│   └── samplesheet.csv                                     # --var SAMPLESHEET_FILE, not published by the run
├── pipeline_info/
│   ├── params_<timestamp>.json                             # run parameters and provenance
│   └── *software_versions.yml
├── multiqc/
│   └── multiqc_data/
│       └── multiqc.parquet                                 # FastQC, fastp, STAR, Picard
├── fusionreport/
│   └── <sample>/
│       └── <sample>.fusions.csv                            # the consensus, hub of the dashboard
├── arriba/
│   └── <sample>.arriba.fusions.tsv
├── starfusion/
│   └── <sample>.starfusion.abridged.tsv
├── fusioncatcher/
│   └── <sample>.fusion-genes.txt
├── fusioninspector/
│   └── <sample>/
│       └── <sample>.FusionInspector.fusions.abridged.tsv   # validated calls and Pfam domains
└── ctatsplicing/
    ├── <sample>.introns
    └── <sample>.cancer.introns                             # optional, header-only when nothing matched
Validation runs
The repository ships
download_test_data.sh,
which fetches the subset of nf-core's AWS megatest run that the template needs,
20 files and about 3.9 MB. The run is
s3://nf-core-awsmegatests/rnafusion/results-76ad76e7c39b2ba9edc35aa3602e3dc454d842ec/:
the pipeline's own test profile, a single library spiked with twelve well known
cancer fusions. Its samplesheet is not part of the results, so fetch the one
params.json points at:
DEST=/tmp/rnafusion_test
bash depictio/projects/nf-core/rnafusion/4.1.3/download_test_data.sh "$DEST"
mkdir -p "$DEST/input" && curl -fsSL -o "$DEST/input/samplesheet.csv" \
  https://raw.githubusercontent.com/nf-core/test-datasets/rnafusion/testdata/human/samplesheet_valid.csv
depictio ingest "$DEST" --template nf-core/rnafusion/latest
One synthetic sample
The reference run is a single library, so every quality-control panel has one series and the sample filter can only select all or nothing. The fusions are synthetic: twelve calls score 1.0 and the rest 0.167, so the index reads as two plateaux rather than a ranking. The fusion tabs compare callers, not samples, so they read normally.
Additional resources
- nf-co.re/rnafusion: official pipeline documentation
- nf-co.re/rnafusion/4.1.3/results: AWS test results
- Template System Reference: YAML format, variables, conditionals
- Recipes: how to read, test, and write recipes
Authorship
 weber8thomas
Reviewing a template on your own data, or taking over a role here, is a contribution in itself: the contributing guide says what each one involves.