The sarek template follows a variant-calling run from the reads to the genes the calls land on, and reads the VCFs themselves, so callers are compared call by call and gene by gene rather than only by how many calls each made:
- Overview: the run in four key figures, live findings and four figures, each linked to the tab that explains it
- Data & QC: read, mapping and recalibration panels from the pipeline's own MultiQC report, and the depth over the intervals with an X against Y sex check
- Variant calls: what each caller called and of what kind, how clean each callset looks, and which calls the callers share
- Annotation: SnpEff's consequences recomputed per call, the genes that carry the calls, the coding variants on the protein and its predicted structure, and depth and calls at one region on one axis
The persistent Sample filters (status, patient, sample) sit in the left panel,
and a pick there reaches every per-sample collection and the MultiQC panels
through the sample links.
Concordance is agreement, not truth
Nothing in this template compares a callset against a benchmark truth set: "concordance" means agreement between callers and samples. For a truth-set benchmark, nf-core/variantbenchmarking has its own template.
Structural-variant callers call few SNPs
Manta and TIDDIT report a Ts/Tv of 0.0 in bcftools stats, which is the
caller doing its job. Every Ts/Tv card and filter keeps only ts_tv > 0, so
they do not drag the medians down.
Quick start
The results directory is the only thing you have to pass. The sample hub is built
from the CSV manifests sarek writes under csv/ (patient, sex, status and
the callers run per sample), so the launch samplesheet is not needed. If the
run was aligned to another assembly than hg38, name it so the locus tracks
draw the right axis and gene lane:
| Variable | Default | Role |
|---|---|---|
GENOME |
hg38 |
UCSC name of the assembly (hg38, hg19, mm10): the axis and gene lane of every locus track |
depictio config nextflow --install     # once per machine
nextflow run nf-core/sarek -r 3.11.0 -profile docker --outdir results
No depictio ingest, and no template named: the pipeline ingests its own
output directory when it finishes and resolves this template from its own
manifest. See Nextflow trigger.
Reference
The template reads the native MultiQC report, the per-caller bcftools stats and
VCFtools summaries, mosdepth's coverage files, the called VCFs, and SnpEff's
annotated VCFs, CSV statistics and per-gene tables. The caller and the sample
live only in the directory path (reports/<tool>/<caller>/<sample>/), so raw
scans carry the path into the table and recipes read both off it. sarek runs
mosdepth on the duplicate-marked and on the recalibrated CRAM; the coverage
recipes keep one pass per sample, so no tile counts a sample twice.
Self-adapting layout
The dashboard adapts to whatever the run actually produced: components bound
to pruned or unparsed data collections are hidden, tabs left with no real
visualizations are dropped entirely, and the remaining components are
re-packed so there are no empty rows. A run without SnpEff in --tools
drops the Consequences, Genes and Protein tabs instead of failing to ingest.
Template variables
Variables you provide when running the template: DATA_ROOT is the results directory given to depictio ingest, the others are set with --var NAME=value:
| Variable | Required | Description |
|---|---|---|
DATA_ROOT |
✓ | Root directory of the sarek output (csv/, reports/, variant_calling/, annotation/, multiqc/, pipeline_info/). |
GENOME |
— | UCSC name of the assembly the run was aligned to (hg38, hg19, mm10): the axis and gene lane of every locus track. |
TRACKS_URI |
— | s3:// or https:// folder holding the run's results (the one that holds csv/, variant_calling/, annotation/ and preprocessing/), to read the genome-browser tracks (the callers' VCFs and the CRAMs) in place instead of uploading them from DATA_ROOT. Without it the tracks collection uploads whichever of those files DATA_ROOT holds. |
Data collections
52 data collections — 9 required 43 optional · 20 direct 32 derived.
Origin tells you whether a collection is real pipeline data or a reshape of it: direct = a pipeline output (scanned, or a recipe that reads raw files); derived = a recipe that reshapes one or more direct collections into the layout a visualization needs (no new measurement). Reads shows what produces it: a recipe .py transform, whose name links to its source on GitHub, or a raw file scanned off disk. (A direct collection can still have a recipe — one that merely parses/cleans the raw file; derived means the recipe reshapes another collection.)
| Tag | Origin | Type | Reads | Status |
|---|---|---|---|---|
samples |
direct | Table | recipe nf-core/sarek/samples.py |
required |
pairs |
derived | Table | recipe nf-core/sarek/pairs.py |
optional |
tracks |
direct | genomic_tracks | recipe nf-core/sarek/tracks.py |
required |
multiqc_data |
direct |  MultiQC |
file (?:.*/)?multiqc(?:/[^/]+)?/multiqc_data/multiqc.parquet$ |
required |
bcftools_stats_raw |
direct | Table | file ^(?!.vs)..bcftools_stats.txt$ |
optional |
bcftools_stats_summary |
derived | Table | recipe bcftools/stats_summary.py |
optional |
bcftools_stats_tstv |
derived | Table | recipe bcftools/stats_tstv.py |
optional |
bcftools_stats_sections |
derived | Table | recipe bcftools/stats_sections.py |
optional |
bcftools_substitution_spectrum |
derived | Table | recipe nf-core/sarek/substitution_spectrum.py |
optional |
bcftools_indel_spectrum |
derived | Table | recipe nf-core/sarek/indel_spectrum.py |
optional |
mosdepth_regions_raw |
direct | Table | file .*.regions.bed.gz$ |
required |
mosdepth_regions |
derived | Table | recipe mosdepth/regions.py |
required |
mosdepth_targets |
derived | Table | recipe nf-core/sarek/mosdepth_targets.py |
required |
mosdepth_windows |
derived | Table | recipe nf-core/sarek/mosdepth_windows.py |
required |
mosdepth_summary_raw |
direct | Table | file .*.mosdepth.summary.txt$ |
required |
mosdepth_summary |
derived | Table | recipe mosdepth/summary.py |
required |
mosdepth_xy_sex_check |
direct | Table | recipe mosdepth/xy_sex_check.py |
optional |
vcftools_filter_summary_raw |
direct | Table | file ^(?!.vs)..FILTER.summary$ |
optional |
vcftools_filter_summary |
derived | Table | recipe vcftools/filter_summary.py |
optional |
vcftools_tstv_qual_raw |
direct | Table | file ^(?!.vs)..TsTv.qual$ |
optional |
vcftools_tstv_qual |
derived | Table | recipe vcftools/tstv_qual.py |
optional |
vcf_calls_raw |
direct | Table | file ^(?!._(?:snpEff|VEP).ann.vcf.gz$)(?!..g(?:enome)?.vcf.gz$).*.vcf.gz$ |
optional |
vcf_variants |
derived | Table | recipe nf-core/sarek/vcf_variants.py |
optional |
sv_calls |
derived | Table | recipe nf-core/sarek/sv_calls.py |
optional |
snpeff_ann_vcf_raw |
direct | Table | file ^(?!.vs)._snpEff.ann.vcf.gz$ |
optional |
snpeff_ann_variants |
derived | Table | recipe nf-core/sarek/ann_variants.py |
optional |
snpeff_variant_upset |
derived | Table | recipe nf-core/sarek/caller_overlap.py |
optional |
snpeff_protein_lollipop |
derived | Table | recipe snpeff/protein_lollipop.py |
optional |
protein_genes |
derived | Table | recipe nf-core/sarek/protein_genes.py |
optional |
snpeff_csv_raw |
direct | Table | file ^(?!.vs)._snpEff.csv$ |
optional |
snpeff_csv_stats |
derived | Table | recipe snpeff/csv_stats.py |
optional |
snpeff_genes_raw |
direct | Table | file ^(?!.vs)._snpEff.genes.txt$ |
optional |
snpeff_genes |
derived | Table | recipe snpeff/genes.py |
optional |
snpeff_gene_upset |
derived | Table | recipe snpeff/gene_upset.py |
optional |
snpeff_gene_heatmap |
derived | Table | recipe snpeff/gene_heatmap.py |
optional |
callset_qc |
derived | Table | recipe nf-core/sarek/callset_qc.py |
optional |
snpeff_vcf_files |
direct | indexed_file | file ^(?!.(?:vs|.(?:manta|tiddit).))._snpEff.ann.vcf.gz$ |
optional |
somatic_calls |
derived | Table | recipe nf-core/sarek/somatic_calls.py |
optional |
somatic_vs_germline |
derived | Table | recipe nf-core/sarek/somatic_vs_germline.py |
optional |
patient_call_counts |
derived | Table | recipe nf-core/sarek/patient_call_counts.py |
optional |
somatic_ann_vcf_raw |
direct | Table | file ^.vs._snpEff.ann.vcf.gz$ |
optional |
somatic_variants |
derived | Table | recipe nf-core/sarek/somatic_variants.py |
optional |
somatic_burden |
derived | Table | recipe nf-core/sarek/somatic_burden.py |
optional |
germline_het_sites |
derived | Table | recipe nf-core/sarek/germline_het_sites.py |
optional |
cnvkit_segments_raw |
direct | Table | file .*cnvkit/[/]+/[^/]+.(?:somatic.|germline.)?call.cns$ |
optional |
cnvkit_bins_raw |
direct | Table | file .*cnvkit/[/]+/[^/]+.cnr$ |
optional |
cnv_segments |
derived | Table | recipe nf-core/sarek/cnv_segments.py |
optional |
cnv_summary |
derived | Table | recipe nf-core/sarek/cnv_summary.py |
optional |
msisensorpro_raw |
direct | Table | file (?:.*/)?msisensorpro/([/]+)/\1$ |
optional |
msi |
derived | Table | recipe nf-core/sarek/msi.py |
optional |
ascat_segments |
direct | Table | file .*.cnvs.txt$ |
optional |
ngscheckmate_matches |
direct | Table | file .*_all.txt$ |
optional |
Conditional routes
Rows are data collections; columns are the variables you set or params.json flags auto-detected from the run. Each filled cell is the effect of setting that variable; an empty cell means that variable leaves the collection unchanged. (51 collections are unaffected by any variable — present on every run.)
+ included− removed⇄ repointed
| Data collection | TRACKS_URI |
|---|---|
tracks |
⇄ |
Cross-DC links
50 links — selecting a value in the source collection filters the target. The join column is shown after the source.
| Source · column | Target | Filters | |
|---|---|---|---|
samples · sample_id |
→ | multiqc_data |
Filter every MultiQC panel by the samples picked in the left panel, through sarek's per-tool sample names |
samples · sample_id |
→ | mosdepth_regions |
Filter the coverage track by the samples picked in the left panel |
samples · sample_id |
→ | mosdepth_summary |
Filter the per-contig coverage summary by the samples picked in the left panel |
samples · sample_id |
→ | mosdepth_xy_sex_check |
Filter the sex check by the samples picked in the left panel |
samples · sample_id |
→ | snpeff_variant_upset |
Narrow the caller overlap to the samples picked in the left panel |
samples · sample_id |
→ | bcftools_stats_sections |
Filter the bcftools distributions by the samples picked in the left panel |
samples · sample_id |
→ | vcftools_filter_summary |
Filter the FILTER breakdown by the samples picked in the left panel |
samples · sample_id |
→ | vcftools_tstv_qual |
Filter the quality sweeps by the samples picked in the left panel |
samples · sample_id |
→ | vcf_variants |
Filter the variant calls by the samples picked in the left panel |
samples · sample_id |
→ | sv_calls |
Filter the structural variants by the samples picked in the left panel |
samples · sample_id |
→ | snpeff_ann_variants |
Filter the annotated calls by the samples picked in the left panel |
samples · sample_id |
→ | snpeff_protein_lollipop |
Filter the coding variants by the samples picked in the left panel |
samples · sample_id |
→ | snpeff_csv_stats |
Filter the annotation composition by the samples picked in the left panel |
samples · sample_id |
→ | snpeff_genes |
Filter the per-gene burden by the samples picked in the left panel |
bcftools_stats_summary · caller |
→ | bcftools_stats_sections |
Carry the caller picked on the variant-yield tab over to the bcftools distributions |
bcftools_stats_summary · caller |
→ | vcftools_filter_summary |
Carry the caller picked on the variant-yield tab over to the FILTER breakdown |
bcftools_stats_summary · caller |
→ | vcftools_tstv_qual |
Carry the caller picked on the variant-yield tab over to the quality sweeps |
vcf_variants · caller |
→ | snpeff_ann_variants |
Carry the caller picked on the concordance tab over to the annotated calls |
snpeff_csv_stats · caller |
→ | snpeff_ann_variants |
Carry the caller picked on the consequences tab over to the annotated calls |
snpeff_genes · caller |
→ | snpeff_protein_lollipop |
Carry the caller picked on the genes tab over to the coding variants |
snpeff_genes · gene_name |
→ | snpeff_protein_lollipop |
Open a gene picked in the burden table on the lollipop below it |
samples · sample_id |
→ | bcftools_stats_summary |
Filter the per-caller variant counts by the samples picked in the left panel |
samples · sample_id |
→ | bcftools_stats_tstv |
Filter the per-caller Ts/Tv ratios by the samples picked in the left panel |
bcftools_stats_summary · caller |
→ | bcftools_stats_tstv |
Carry the caller picked on the MultiQC tab over to its Ts/Tv rows |
bcftools_stats_summary · sample |
→ | bcftools_stats_tstv |
Carry a sample selected on the variant counts table over to its Ts/Tv rows |
mosdepth_windows · chrom |
→ | mosdepth_targets |
A region typed or brushed on the depth navigator narrows the per-target depth track |
mosdepth_windows · chrom |
→ | vcf_variants |
A region typed or brushed on the depth navigator narrows the calls track |
samples · sample_id |
→ | mosdepth_windows |
Filter the depth navigator by the samples picked in the left panel |
samples · sample_id |
→ | mosdepth_targets |
Filter the per-target depth track by the samples picked in the left panel |
samples · sample_id |
→ | bcftools_substitution_spectrum |
Filter the substitution spectrum by the samples picked in the left panel |
samples · sample_id |
→ | bcftools_indel_spectrum |
Filter the indel length spectrum by the samples picked in the left panel |
samples · sample_id |
→ | callset_qc |
Filter the callset QC profile by the samples picked in the left panel |
bcftools_stats_summary · caller |
→ | bcftools_substitution_spectrum |
Carry the caller picked on the Variant yield tab over to the substitution spectrum |
bcftools_stats_summary · caller |
→ | bcftools_indel_spectrum |
Carry the caller picked on the Variant yield tab over to the indel length spectrum |
bcftools_stats_summary · caller |
→ | callset_qc |
Carry the caller picked on the Variant yield tab over to the callset QC profile |
samples · sample_id |
→ | tracks |
Show the genome tracks of the samples picked in the left panel |
tracks · sample_id |
→ | samples |
Filter the dashboard by the samples whose tracks are picked in the genome browser |
vcf_variants · sample |
→ | tracks |
Open the genome tracks of the samples a picked call was made in |
samples · sample_id |
→ | pairs |
Filter the pairs by the tumours picked in the left panel |
samples · sample_id |
→ | somatic_calls |
Filter the somatic calls by the tumours picked in the left panel |
samples · sample_id |
→ | somatic_vs_germline |
Filter the pair-against-normal comparison by the tumours picked in the left panel |
samples · sample_id |
→ | somatic_variants |
Filter the merged somatic variants by the tumours picked in the left panel |
samples · sample_id |
→ | somatic_burden |
Filter the mutation burden by the tumours picked in the left panel |
samples · sample_id |
→ | germline_het_sites |
Filter the normal's heterozygous sites by the tumours picked in the left panel |
samples · patient |
→ | patient_call_counts |
Filter the per-patient counts by the patients the left panel keeps |
samples · sample_id |
→ | cnv_segments |
Filter the copy-number profiles by the samples picked in the left panel |
samples · sample_id |
→ | cnv_summary |
Filter the copy-number summaries by the samples picked in the left panel |
samples · sample_id |
→ | msi |
Filter the microsatellite scores by the tumours picked in the left panel |
somatic_calls · sample |
→ | tracks |
Open the genome tracks of the tumour a picked somatic call was made in |
somatic_calls · caller |
→ | somatic_vs_germline |
Carry the caller picked on the Somatic calls tab over to the comparison with the normal |
Recipes
Each recipe reshapes raw pipeline output into a tidy table. The name links to its source; Output lists the validated OUTPUT_SCHEMA columns.
| Recipe | Transforms | Output |
|---|---|---|
bcftools/stats_sections.py |
The distribution blocks of bcftools stats, melted into one long frame. |
sample, caller, section, bin, label, count |
bcftools/stats_summary.py |
Per-sample, per-caller variant record counts from bcftools stats. |
sample, caller, n_records, n_no_alts, n_snps, n_mnps, n_indels, n_others, n_multiallelic_sites, n_multiallelic_snp_sites, snp_fraction, log10_n_records |
bcftools/stats_tstv.py |
Per-sample, per-caller transition/transversion ratio from bcftools stats. |
sample, caller, ts, tv, ts_tv, ts_1st_alt, tv_1st_alt, ts_tv_1st_alt |
mosdepth/regions.py |
Per-target mosdepth depth, binned into a genome-wide coverage track. | chromosome, position, end, value, sample, stage, sample_stage, n_targets |
mosdepth/summary.py |
Per-contig coverage summary written by mosdepth. | sample, stage, scope, chrom, length, bases, mean_depth, min_depth, max_depth |
mosdepth/xy_sex_check.py |
X and Y mean depth per library, and the sex the ratio is consistent with. | sample, stage, x_coverage, y_coverage, xy_ratio, inferred_sex |
nf-core/sarek/ann_variants.py |
One row per annotated germline variant call, read from SnpEff's annotated VCF. | sample, caller, chrom, pos, variant_key, ref, alt, variant_type, qual, filter_status, is_pass, gt, dp, vaf, gene, gene_id, impact, consequence, hgvs_p, aa_pos |
nf-core/sarek/caller_overlap.py |
Which callers make each call: one row per call in a sample, one 0/1 column per caller. | sample, variant_key, n_callers, sample_shared_pct |
nf-core/sarek/callset_qc.py |
One QC profile per callset (sample and caller), for a parallel-coordinates tile. | callset, sample, caller, n_records, snp_fraction, ts_tv, multiallelic_pct, pass_pct, het_hom_ratio, median_dp, median_het_vaf |
nf-core/sarek/cnv_segments.py |
CNVkit copy-number segments and bins, one profile per calling unit. | sample, chrom, start, end, log2, baf, copy_number, segment, label, depth, unit, unit_type, patient, normal, call_source |
nf-core/sarek/cnv_summary.py |
What each copy-number profile adds up to: one row per unit, for the tab's key figures. | unit, unit_type, patient, sample, normal, call_source, n_segments, n_gains, n_losses, covered_mb, gained_mb, lost_mb, altered_mb, fga_pct, gained_pct, lost_pct, contigs, altered_contigs, max_log2, min_log2 |
nf-core/sarek/germline_het_sites.py |
The normal's heterozygous germline sites, read in the tumour: where did a parental copy go? | unit, patient, sample, normal, chrom, chrom_rank, pos, variant_key, ref, alt, normal_vaf, normal_dp, tumour_vaf, tumour_dp, allele_state |
nf-core/sarek/indel_spectrum.py |
Indel length spectrum per callset, from the IDD block of bcftools stats. |
sample, caller, callset, length, indel_class, count, fraction |
nf-core/sarek/mosdepth_targets.py |
Per-target mosdepth depth, unbinned, for the Cohort QC locus section. | chrom, pos, end, depth, sample, stage, sample_stage, target_bp |
nf-core/sarek/mosdepth_windows.py |
The 1 Mb mosdepth windows under the column names the locus section shares. | chrom, pos, end, depth, sample, stage, sample_stage, n_targets, sample_id, depth_capped |
nf-core/sarek/msi.py |
MSIsensor-pro microsatellite instability, one row per tumour/normal pair. | unit, unit_type, patient, sample, normal, total_sites, unstable_sites, msi_score |
nf-core/sarek/pairs.py |
One row per tumour/normal pair of the samplesheet. | pair_id, patient, tumour, normal |
nf-core/sarek/patient_call_counts.py |
Per patient of a tumour/normal pair: distinct germline variants and distinct somatic ones. | patient, call_class, variants |
nf-core/sarek/protein_genes.py |
One row per gene of the coding-variant lollipop: the Protein tab's selector. | gene, variants, positions, calls, shared_pct, samples, callers, high_variants, moderate_variants, worst_impact, median_vaf |
nf-core/sarek/samples.py |
One row per sarek sample, from the CSV manifests sarek publishes under csv/. | sample_id, patient, sex, status, status_label, design, n_callers |
nf-core/sarek/somatic_burden.py |
Mutation burden of each tumour/normal pair: somatic variants per megabase of the target. | unit, patient, sample, normal, basis, basis_kind, variants, snvs, indels, protein_altering, target_mb, per_mb, protein_altering_per_mb |
nf-core/sarek/somatic_calls.py |
One row per somatic call: a tumour/normal pair's, and a tumour called on its own. | unit, unit_type, patient, sample, normal, caller, chrom, pos, ref, alt, variant_key, variant_type, qual, score, filter_status, is_pass, tumour_vaf, tumour_dp, normal_vaf, normal_dp |
nf-core/sarek/somatic_variants.py |
One row per distinct somatic variant of a tumour/normal pair, the callers merged. | unit, patient, sample, normal, chrom, pos, ref, alt, variant_key, variant_type, substitution, callers, n_callers, support, consensus, tumour_vaf, tumour_dp, normal_vaf, normal_dp, normal_class, germline_callers, in_germline, origin, annotated, gene, gene_id, impact, consequence, hgvs_p, aa_pos, priority |
nf-core/sarek/somatic_vs_germline.py |
Each paired somatic call set against the normal's own germline calls. | unit, patient, sample, normal, caller, chrom, pos, ref, alt, variant_key, variant_type, filter_status, is_pass, tumour_vaf, tumour_dp, normal_vaf, normal_dp, normal_vaf_source, germline_callers, in_germline, origin |
nf-core/sarek/substitution_spectrum.py |
SNV substitution spectrum per callset, folded onto the six pyrimidine classes. | sample, caller, callset, substitution_class, mutation_class, count, fraction |
nf-core/sarek/sv_calls.py |
One row per structural-variant record the SV callers (Manta, TIDDIT) wrote. | sample, caller, chrom, pos, end, svtype, svlen, size_bp, qual, filter_status, is_pass, imprecise, primary, mate_chrom, mate_pos, link_chrom, link_pos |
nf-core/sarek/tracks.py |
Genome-browser track manifest: one row per track file the run published. | track_id, sample_id, caller, kind, format, uri, name, category, order |
nf-core/sarek/vcf_variants.py |
One row per germline variant call, read from the caller VCFs themselves. | sample, caller, chrom, pos, variant_key, ref, alt, variant_type, qual, filter_status, is_pass, gt, dp, vaf |
snpeff/csv_stats.py |
The composition sections of SnpEff's CSV summary, melted into one long frame. | sample, caller, section, category, count, percent |
snpeff/gene_heatmap.py |
Gene by callset burden matrix, for a clustered heatmap. | gene_name |
snpeff/gene_upset.py |
Gene-level caller overlap: one row per gene, one 0/1 column per caller. | gene_name |
snpeff/genes.py |
Per-gene variant counts by impact class, from SnpEff's gene effect table. | sample, caller, gene_name, gene_id, biotype, n_high, n_low, n_moderate, n_modifier, n_variants, n_coding |
snpeff/protein_lollipop.py |
Coding variants positioned along their protein, for a lollipop track. | sample, caller, gene, aa_pos, impact, consequence, hgvs_p, ref_aa, variant_key, vaf |
vcftools/filter_summary.py |
How a caller's own FILTER column partitions its calls. | sample, caller, filter_label, n_variants, n_ts, n_tv, ts_tv, is_pass, pct_of_calls |
vcftools/tstv_qual.py |
Transition/transversion ratio as a function of the quality floor. | sample, caller, series, qual_threshold, n_ts_above, n_tv_above, ts_tv_above |
Template variables
Variables you provide when running the template: DATA_ROOT is the results directory given to depictio ingest, the others are set with --var NAME=value:
| Variable | Required | Description |
|---|---|---|
DATA_ROOT |
✓ | Root directory of the sarek output (csv/, reports/, variant_calling/, annotation/, multiqc/, pipeline_info/). |
GENOME |
— | UCSC name of the assembly the run was aligned to (hg38, hg19, mm10): the axis and gene lane of every locus track. |
TRACKS_URI |
— | s3:// or https:// folder holding the run's results (the one that holds csv/, variant_calling/, annotation/ and preprocessing/), to read the genome-browser tracks (the callers' VCFs and the CRAMs) in place instead of uploading them from DATA_ROOT. Without it the tracks collection uploads whichever of those files DATA_ROOT holds. |
Data collections
52 data collections — 9 required 43 optional · 20 direct 32 derived.
Origin tells you whether a collection is real pipeline data or a reshape of it: direct = a pipeline output (scanned, or a recipe that reads raw files); derived = a recipe that reshapes one or more direct collections into the layout a visualization needs (no new measurement). Reads shows what produces it: a recipe .py transform, or a raw file scanned off disk. (A direct collection can still have a recipe — one that merely parses/cleans the raw file; derived means the recipe reshapes another collection.)
| Tag | Origin | Type | Reads | Status |
|---|---|---|---|---|
samples |
direct | Table | recipe nf-core/sarek/samples.py |
required |
pairs |
derived | Table | recipe nf-core/sarek/pairs.py |
optional |
tracks |
direct | genomic_tracks | recipe nf-core/sarek/tracks.py |
required |
multiqc_data |
direct | MultiQC |
file (?:.*/)?multiqc(?:/[^/]+)?/multiqc_data/multiqc.parquet$ |
required |
bcftools_stats_raw |
direct | Table | file ^(?!.vs)..bcftools_stats.txt$ |
optional |
bcftools_stats_summary |
derived | Table | recipe bcftools/stats_summary.py |
optional |
bcftools_stats_tstv |
derived | Table | recipe bcftools/stats_tstv.py |
optional |
bcftools_stats_sections |
derived | Table | recipe bcftools/stats_sections.py |
optional |
bcftools_substitution_spectrum |
derived | Table | recipe nf-core/sarek/substitution_spectrum.py |
optional |
bcftools_indel_spectrum |
derived | Table | recipe nf-core/sarek/indel_spectrum.py |
optional |
mosdepth_regions_raw |
direct | Table | file .*.regions.bed.gz$ |
required |
mosdepth_regions |
derived | Table | recipe mosdepth/regions.py |
required |
mosdepth_targets |
derived | Table | recipe nf-core/sarek/mosdepth_targets.py |
required |
mosdepth_windows |
derived | Table | recipe nf-core/sarek/mosdepth_windows.py |
required |
mosdepth_summary_raw |
direct | Table | file .*.mosdepth.summary.txt$ |
required |
mosdepth_summary |
derived | Table | recipe mosdepth/summary.py |
required |
mosdepth_xy_sex_check |
direct | Table | recipe mosdepth/xy_sex_check.py |
optional |
vcftools_filter_summary_raw |
direct | Table | file ^(?!.vs)..FILTER.summary$ |
optional |
vcftools_filter_summary |
derived | Table | recipe vcftools/filter_summary.py |
optional |
vcftools_tstv_qual_raw |
direct | Table | file ^(?!.vs)..TsTv.qual$ |
optional |
vcftools_tstv_qual |
derived | Table | recipe vcftools/tstv_qual.py |
optional |
vcf_calls_raw |
direct | Table | file ^(?!._(?:snpEff|VEP).ann.vcf.gz$)(?!..g(?:enome)?.vcf.gz$).*.vcf.gz$ |
optional |
vcf_variants |
derived | Table | recipe nf-core/sarek/vcf_variants.py |
optional |
sv_calls |
derived | Table | recipe nf-core/sarek/sv_calls.py |
optional |
snpeff_ann_vcf_raw |
direct | Table | file ^(?!.vs)._snpEff.ann.vcf.gz$ |
optional |
snpeff_ann_variants |
derived | Table | recipe nf-core/sarek/ann_variants.py |
optional |
snpeff_variant_upset |
derived | Table | recipe nf-core/sarek/caller_overlap.py |
optional |
snpeff_protein_lollipop |
derived | Table | recipe snpeff/protein_lollipop.py |
optional |
protein_genes |
derived | Table | recipe nf-core/sarek/protein_genes.py |
optional |
snpeff_csv_raw |
direct | Table | file ^(?!.vs)._snpEff.csv$ |
optional |
snpeff_csv_stats |
derived | Table | recipe snpeff/csv_stats.py |
optional |
snpeff_genes_raw |
direct | Table | file ^(?!.vs)._snpEff.genes.txt$ |
optional |
snpeff_genes |
derived | Table | recipe snpeff/genes.py |
optional |
snpeff_gene_upset |
derived | Table | recipe snpeff/gene_upset.py |
optional |
snpeff_gene_heatmap |
derived | Table | recipe snpeff/gene_heatmap.py |
optional |
callset_qc |
derived | Table | recipe nf-core/sarek/callset_qc.py |
optional |
snpeff_vcf_files |
direct | indexed_file | file ^(?!.(?:vs|.(?:manta|tiddit).))._snpEff.ann.vcf.gz$ |
optional |
somatic_calls |
derived | Table | recipe nf-core/sarek/somatic_calls.py |
optional |
somatic_vs_germline |
derived | Table | recipe nf-core/sarek/somatic_vs_germline.py |
optional |
patient_call_counts |
derived | Table | recipe nf-core/sarek/patient_call_counts.py |
optional |
somatic_ann_vcf_raw |
direct | Table | file ^.vs._snpEff.ann.vcf.gz$ |
optional |
somatic_variants |
derived | Table | recipe nf-core/sarek/somatic_variants.py |
optional |
somatic_burden |
derived | Table | recipe nf-core/sarek/somatic_burden.py |
optional |
germline_het_sites |
derived | Table | recipe nf-core/sarek/germline_het_sites.py |
optional |
cnvkit_segments_raw |
direct | Table | file .*cnvkit/[/]+/[^/]+.(?:somatic.|germline.)?call.cns$ |
optional |
cnvkit_bins_raw |
direct | Table | file .*cnvkit/[/]+/[^/]+.cnr$ |
optional |
cnv_segments |
derived | Table | recipe nf-core/sarek/cnv_segments.py |
optional |
cnv_summary |
derived | Table | recipe nf-core/sarek/cnv_summary.py |
optional |
msisensorpro_raw |
direct | Table | file (?:.*/)?msisensorpro/([/]+)/\1$ |
optional |
msi |
derived | Table | recipe nf-core/sarek/msi.py |
optional |
ascat_segments |
direct | Table | file .*.cnvs.txt$ |
optional |
ngscheckmate_matches |
direct | Table | file .*_all.txt$ |
optional |
Conditional routes
Rows are data collections; columns are the variables you set or params.json flags auto-detected from the run. Each filled cell is the effect of setting that variable; an empty cell means that variable leaves the collection unchanged. (51 collections are unaffected by any variable — present on every run.)
+ included− removed⇄ repointed
| Data collection | TRACKS_URI |
|---|---|
tracks |
⇄ |
Cross-DC links
50 links — selecting a value in the source collection filters the target. The join column is shown after the source.
| Source · column | Target | Filters | |
|---|---|---|---|
samples · sample_id |
→ | multiqc_data |
Filter every MultiQC panel by the samples picked in the left panel, through sarek's per-tool sample names |
samples · sample_id |
→ | mosdepth_regions |
Filter the coverage track by the samples picked in the left panel |
samples · sample_id |
→ | mosdepth_summary |
Filter the per-contig coverage summary by the samples picked in the left panel |
samples · sample_id |
→ | mosdepth_xy_sex_check |
Filter the sex check by the samples picked in the left panel |
samples · sample_id |
→ | snpeff_variant_upset |
Narrow the caller overlap to the samples picked in the left panel |
samples · sample_id |
→ | bcftools_stats_sections |
Filter the bcftools distributions by the samples picked in the left panel |
samples · sample_id |
→ | vcftools_filter_summary |
Filter the FILTER breakdown by the samples picked in the left panel |
samples · sample_id |
→ | vcftools_tstv_qual |
Filter the quality sweeps by the samples picked in the left panel |
samples · sample_id |
→ | vcf_variants |
Filter the variant calls by the samples picked in the left panel |
samples · sample_id |
→ | sv_calls |
Filter the structural variants by the samples picked in the left panel |
samples · sample_id |
→ | snpeff_ann_variants |
Filter the annotated calls by the samples picked in the left panel |
samples · sample_id |
→ | snpeff_protein_lollipop |
Filter the coding variants by the samples picked in the left panel |
samples · sample_id |
→ | snpeff_csv_stats |
Filter the annotation composition by the samples picked in the left panel |
samples · sample_id |
→ | snpeff_genes |
Filter the per-gene burden by the samples picked in the left panel |
bcftools_stats_summary · caller |
→ | bcftools_stats_sections |
Carry the caller picked on the variant-yield tab over to the bcftools distributions |
bcftools_stats_summary · caller |
→ | vcftools_filter_summary |
Carry the caller picked on the variant-yield tab over to the FILTER breakdown |
bcftools_stats_summary · caller |
→ | vcftools_tstv_qual |
Carry the caller picked on the variant-yield tab over to the quality sweeps |
vcf_variants · caller |
→ | snpeff_ann_variants |
Carry the caller picked on the concordance tab over to the annotated calls |
snpeff_csv_stats · caller |
→ | snpeff_ann_variants |
Carry the caller picked on the consequences tab over to the annotated calls |
snpeff_genes · caller |
→ | snpeff_protein_lollipop |
Carry the caller picked on the genes tab over to the coding variants |
snpeff_genes · gene_name |
→ | snpeff_protein_lollipop |
Open a gene picked in the burden table on the lollipop below it |
samples · sample_id |
→ | bcftools_stats_summary |
Filter the per-caller variant counts by the samples picked in the left panel |
samples · sample_id |
→ | bcftools_stats_tstv |
Filter the per-caller Ts/Tv ratios by the samples picked in the left panel |
bcftools_stats_summary · caller |
→ | bcftools_stats_tstv |
Carry the caller picked on the MultiQC tab over to its Ts/Tv rows |
bcftools_stats_summary · sample |
→ | bcftools_stats_tstv |
Carry a sample selected on the variant counts table over to its Ts/Tv rows |
mosdepth_windows · chrom |
→ | mosdepth_targets |
A region typed or brushed on the depth navigator narrows the per-target depth track |
mosdepth_windows · chrom |
→ | vcf_variants |
A region typed or brushed on the depth navigator narrows the calls track |
samples · sample_id |
→ | mosdepth_windows |
Filter the depth navigator by the samples picked in the left panel |
samples · sample_id |
→ | mosdepth_targets |
Filter the per-target depth track by the samples picked in the left panel |
samples · sample_id |
→ | bcftools_substitution_spectrum |
Filter the substitution spectrum by the samples picked in the left panel |
samples · sample_id |
→ | bcftools_indel_spectrum |
Filter the indel length spectrum by the samples picked in the left panel |
samples · sample_id |
→ | callset_qc |
Filter the callset QC profile by the samples picked in the left panel |
bcftools_stats_summary · caller |
→ | bcftools_substitution_spectrum |
Carry the caller picked on the Variant yield tab over to the substitution spectrum |
bcftools_stats_summary · caller |
→ | bcftools_indel_spectrum |
Carry the caller picked on the Variant yield tab over to the indel length spectrum |
bcftools_stats_summary · caller |
→ | callset_qc |
Carry the caller picked on the Variant yield tab over to the callset QC profile |
samples · sample_id |
→ | tracks |
Show the genome tracks of the samples picked in the left panel |
tracks · sample_id |
→ | samples |
Filter the dashboard by the samples whose tracks are picked in the genome browser |
vcf_variants · sample |
→ | tracks |
Open the genome tracks of the samples a picked call was made in |
samples · sample_id |
→ | pairs |
Filter the pairs by the tumours picked in the left panel |
samples · sample_id |
→ | somatic_calls |
Filter the somatic calls by the tumours picked in the left panel |
samples · sample_id |
→ | somatic_vs_germline |
Filter the pair-against-normal comparison by the tumours picked in the left panel |
samples · sample_id |
→ | somatic_variants |
Filter the merged somatic variants by the tumours picked in the left panel |
samples · sample_id |
→ | somatic_burden |
Filter the mutation burden by the tumours picked in the left panel |
samples · sample_id |
→ | germline_het_sites |
Filter the normal's heterozygous sites by the tumours picked in the left panel |
samples · patient |
→ | patient_call_counts |
Filter the per-patient counts by the patients the left panel keeps |
samples · sample_id |
→ | cnv_segments |
Filter the copy-number profiles by the samples picked in the left panel |
samples · sample_id |
→ | cnv_summary |
Filter the copy-number summaries by the samples picked in the left panel |
samples · sample_id |
→ | msi |
Filter the microsatellite scores by the tumours picked in the left panel |
somatic_calls · sample |
→ | tracks |
Open the genome tracks of the tumour a picked somatic call was made in |
somatic_calls · caller |
→ | somatic_vs_germline |
Carry the caller picked on the Somatic calls tab over to the comparison with the normal |
Recipes
Each recipe reshapes raw pipeline output into a tidy table. The name links to its source; Output lists the validated OUTPUT_SCHEMA columns.
| Recipe | Transforms | Output |
|---|---|---|
bcftools/stats_sections.py |
The distribution blocks of bcftools stats, melted into one long frame. |
sample, caller, section, bin, label, count |
bcftools/stats_summary.py |
Per-sample, per-caller variant record counts from bcftools stats. |
sample, caller, n_records, n_no_alts, n_snps, n_mnps, n_indels, n_others, n_multiallelic_sites, n_multiallelic_snp_sites, snp_fraction, log10_n_records |
bcftools/stats_tstv.py |
Per-sample, per-caller transition/transversion ratio from bcftools stats. |
sample, caller, ts, tv, ts_tv, ts_1st_alt, tv_1st_alt, ts_tv_1st_alt |
mosdepth/regions.py |
Per-target mosdepth depth, binned into a genome-wide coverage track. | chromosome, position, end, value, sample, stage, sample_stage, n_targets |
mosdepth/summary.py |
Per-contig coverage summary written by mosdepth. | sample, stage, scope, chrom, length, bases, mean_depth, min_depth, max_depth |
mosdepth/xy_sex_check.py |
X and Y mean depth per library, and the sex the ratio is consistent with. | sample, stage, x_coverage, y_coverage, xy_ratio, inferred_sex |
nf-core/sarek/ann_variants.py |
One row per annotated germline variant call, read from SnpEff's annotated VCF. | sample, caller, chrom, pos, variant_key, ref, alt, variant_type, qual, filter_status, is_pass, gt, dp, vaf, gene, gene_id, impact, consequence, hgvs_p, aa_pos |
nf-core/sarek/caller_overlap.py |
Which callers make each call: one row per call in a sample, one 0/1 column per caller. | sample, variant_key, n_callers, sample_shared_pct |
nf-core/sarek/callset_qc.py |
One QC profile per callset (sample and caller), for a parallel-coordinates tile. | callset, sample, caller, n_records, snp_fraction, ts_tv, multiallelic_pct, pass_pct, het_hom_ratio, median_dp, median_het_vaf |
nf-core/sarek/cnv_segments.py |
CNVkit copy-number segments and bins, one profile per calling unit. | sample, chrom, start, end, log2, baf, copy_number, segment, label, depth, unit, unit_type, patient, normal, call_source |
nf-core/sarek/cnv_summary.py |
What each copy-number profile adds up to: one row per unit, for the tab's key figures. | unit, unit_type, patient, sample, normal, call_source, n_segments, n_gains, n_losses, covered_mb, gained_mb, lost_mb, altered_mb, fga_pct, gained_pct, lost_pct, contigs, altered_contigs, max_log2, min_log2 |
nf-core/sarek/germline_het_sites.py |
The normal's heterozygous germline sites, read in the tumour: where did a parental copy go? | unit, patient, sample, normal, chrom, chrom_rank, pos, variant_key, ref, alt, normal_vaf, normal_dp, tumour_vaf, tumour_dp, allele_state |
nf-core/sarek/indel_spectrum.py |
Indel length spectrum per callset, from the IDD block of bcftools stats. |
sample, caller, callset, length, indel_class, count, fraction |
nf-core/sarek/mosdepth_targets.py |
Per-target mosdepth depth, unbinned, for the Cohort QC locus section. | chrom, pos, end, depth, sample, stage, sample_stage, target_bp |
nf-core/sarek/mosdepth_windows.py |
The 1 Mb mosdepth windows under the column names the locus section shares. | chrom, pos, end, depth, sample, stage, sample_stage, n_targets, sample_id, depth_capped |
nf-core/sarek/msi.py |
MSIsensor-pro microsatellite instability, one row per tumour/normal pair. | unit, unit_type, patient, sample, normal, total_sites, unstable_sites, msi_score |
nf-core/sarek/pairs.py |
One row per tumour/normal pair of the samplesheet. | pair_id, patient, tumour, normal |
nf-core/sarek/patient_call_counts.py |
Per patient of a tumour/normal pair: distinct germline variants and distinct somatic ones. | patient, call_class, variants |
nf-core/sarek/protein_genes.py |
One row per gene of the coding-variant lollipop: the Protein tab's selector. | gene, variants, positions, calls, shared_pct, samples, callers, high_variants, moderate_variants, worst_impact, median_vaf |
nf-core/sarek/samples.py |
One row per sarek sample, from the CSV manifests sarek publishes under csv/. | sample_id, patient, sex, status, status_label, design, n_callers |
nf-core/sarek/somatic_burden.py |
Mutation burden of each tumour/normal pair: somatic variants per megabase of the target. | unit, patient, sample, normal, basis, basis_kind, variants, snvs, indels, protein_altering, target_mb, per_mb, protein_altering_per_mb |
nf-core/sarek/somatic_calls.py |
One row per somatic call: a tumour/normal pair's, and a tumour called on its own. | unit, unit_type, patient, sample, normal, caller, chrom, pos, ref, alt, variant_key, variant_type, qual, score, filter_status, is_pass, tumour_vaf, tumour_dp, normal_vaf, normal_dp |
nf-core/sarek/somatic_variants.py |
One row per distinct somatic variant of a tumour/normal pair, the callers merged. | unit, patient, sample, normal, chrom, pos, ref, alt, variant_key, variant_type, substitution, callers, n_callers, support, consensus, tumour_vaf, tumour_dp, normal_vaf, normal_dp, normal_class, germline_callers, in_germline, origin, annotated, gene, gene_id, impact, consequence, hgvs_p, aa_pos, priority |
nf-core/sarek/somatic_vs_germline.py |
Each paired somatic call set against the normal's own germline calls. | unit, patient, sample, normal, caller, chrom, pos, ref, alt, variant_key, variant_type, filter_status, is_pass, tumour_vaf, tumour_dp, normal_vaf, normal_dp, normal_vaf_source, germline_callers, in_germline, origin |
nf-core/sarek/substitution_spectrum.py |
SNV substitution spectrum per callset, folded onto the six pyrimidine classes. | sample, caller, callset, substitution_class, mutation_class, count, fraction |
nf-core/sarek/sv_calls.py |
One row per structural-variant record the SV callers (Manta, TIDDIT) wrote. | sample, caller, chrom, pos, end, svtype, svlen, size_bp, qual, filter_status, is_pass, imprecise, primary, mate_chrom, mate_pos, link_chrom, link_pos |
nf-core/sarek/tracks.py |
Genome-browser track manifest: one row per track file the run published. | track_id, sample_id, caller, kind, format, uri, name, category, order |
nf-core/sarek/vcf_variants.py |
One row per germline variant call, read from the caller VCFs themselves. | sample, caller, chrom, pos, variant_key, ref, alt, variant_type, qual, filter_status, is_pass, gt, dp, vaf |
snpeff/csv_stats.py |
The composition sections of SnpEff's CSV summary, melted into one long frame. | sample, caller, section, category, count, percent |
snpeff/gene_heatmap.py |
Gene by callset burden matrix, for a clustered heatmap. | gene_name |
snpeff/gene_upset.py |
Gene-level caller overlap: one row per gene, one 0/1 column per caller. | gene_name |
snpeff/genes.py |
Per-gene variant counts by impact class, from SnpEff's gene effect table. | sample, caller, gene_name, gene_id, biotype, n_high, n_low, n_moderate, n_modifier, n_variants, n_coding |
snpeff/protein_lollipop.py |
Coding variants positioned along their protein, for a lollipop track. | sample, caller, gene, aa_pos, impact, consequence, hgvs_p, ref_aa, variant_key, vaf |
vcftools/filter_summary.py |
How a caller's own FILTER column partitions its calls. | sample, caller, filter_label, n_variants, n_ts, n_tv, ts_tv, is_pass, pct_of_calls |
vcftools/tstv_qual.py |
Transition/transversion ratio as a function of the quality floor. | sample, caller, series, qual_threshold, n_ts_above, n_tv_above, ts_tv_above |
Dashboard tabs
One dashboard: the Overview, then nine child tabs in three groups, read as a funnel from the reads to the genes the calls hit and one region of the genome. Each tab below carries the same icon and colour the dashboard gives it, so the page and the app read alike.
| Group | Tabs |
|---|---|
| Data & QC | MultiQC, Coverage |
| Variant calls | Variant yield, Call quality, Caller concordance |
| Annotation | Consequences, Genes, Protein, Locus |
Each child tab opens with a short intro and a strip of four cards, then at most three open sections; tables follow, collapsed. The template has no group column: the sample hub is built from sarek's CSV manifests and carries the patient, sex, status and the callers run per sample. A callset is one caller on one sample. The persistent Sample filters (status, patient, sample) sit in the left panel and narrow every tab through the sample links. The Sample sheet is pinned, collapsed, to the bottom of every child tab. The Locus tab embeds a genome browser that shows depth and reads on one axis.
Germline variant calls, from coverage to the genes they hit.
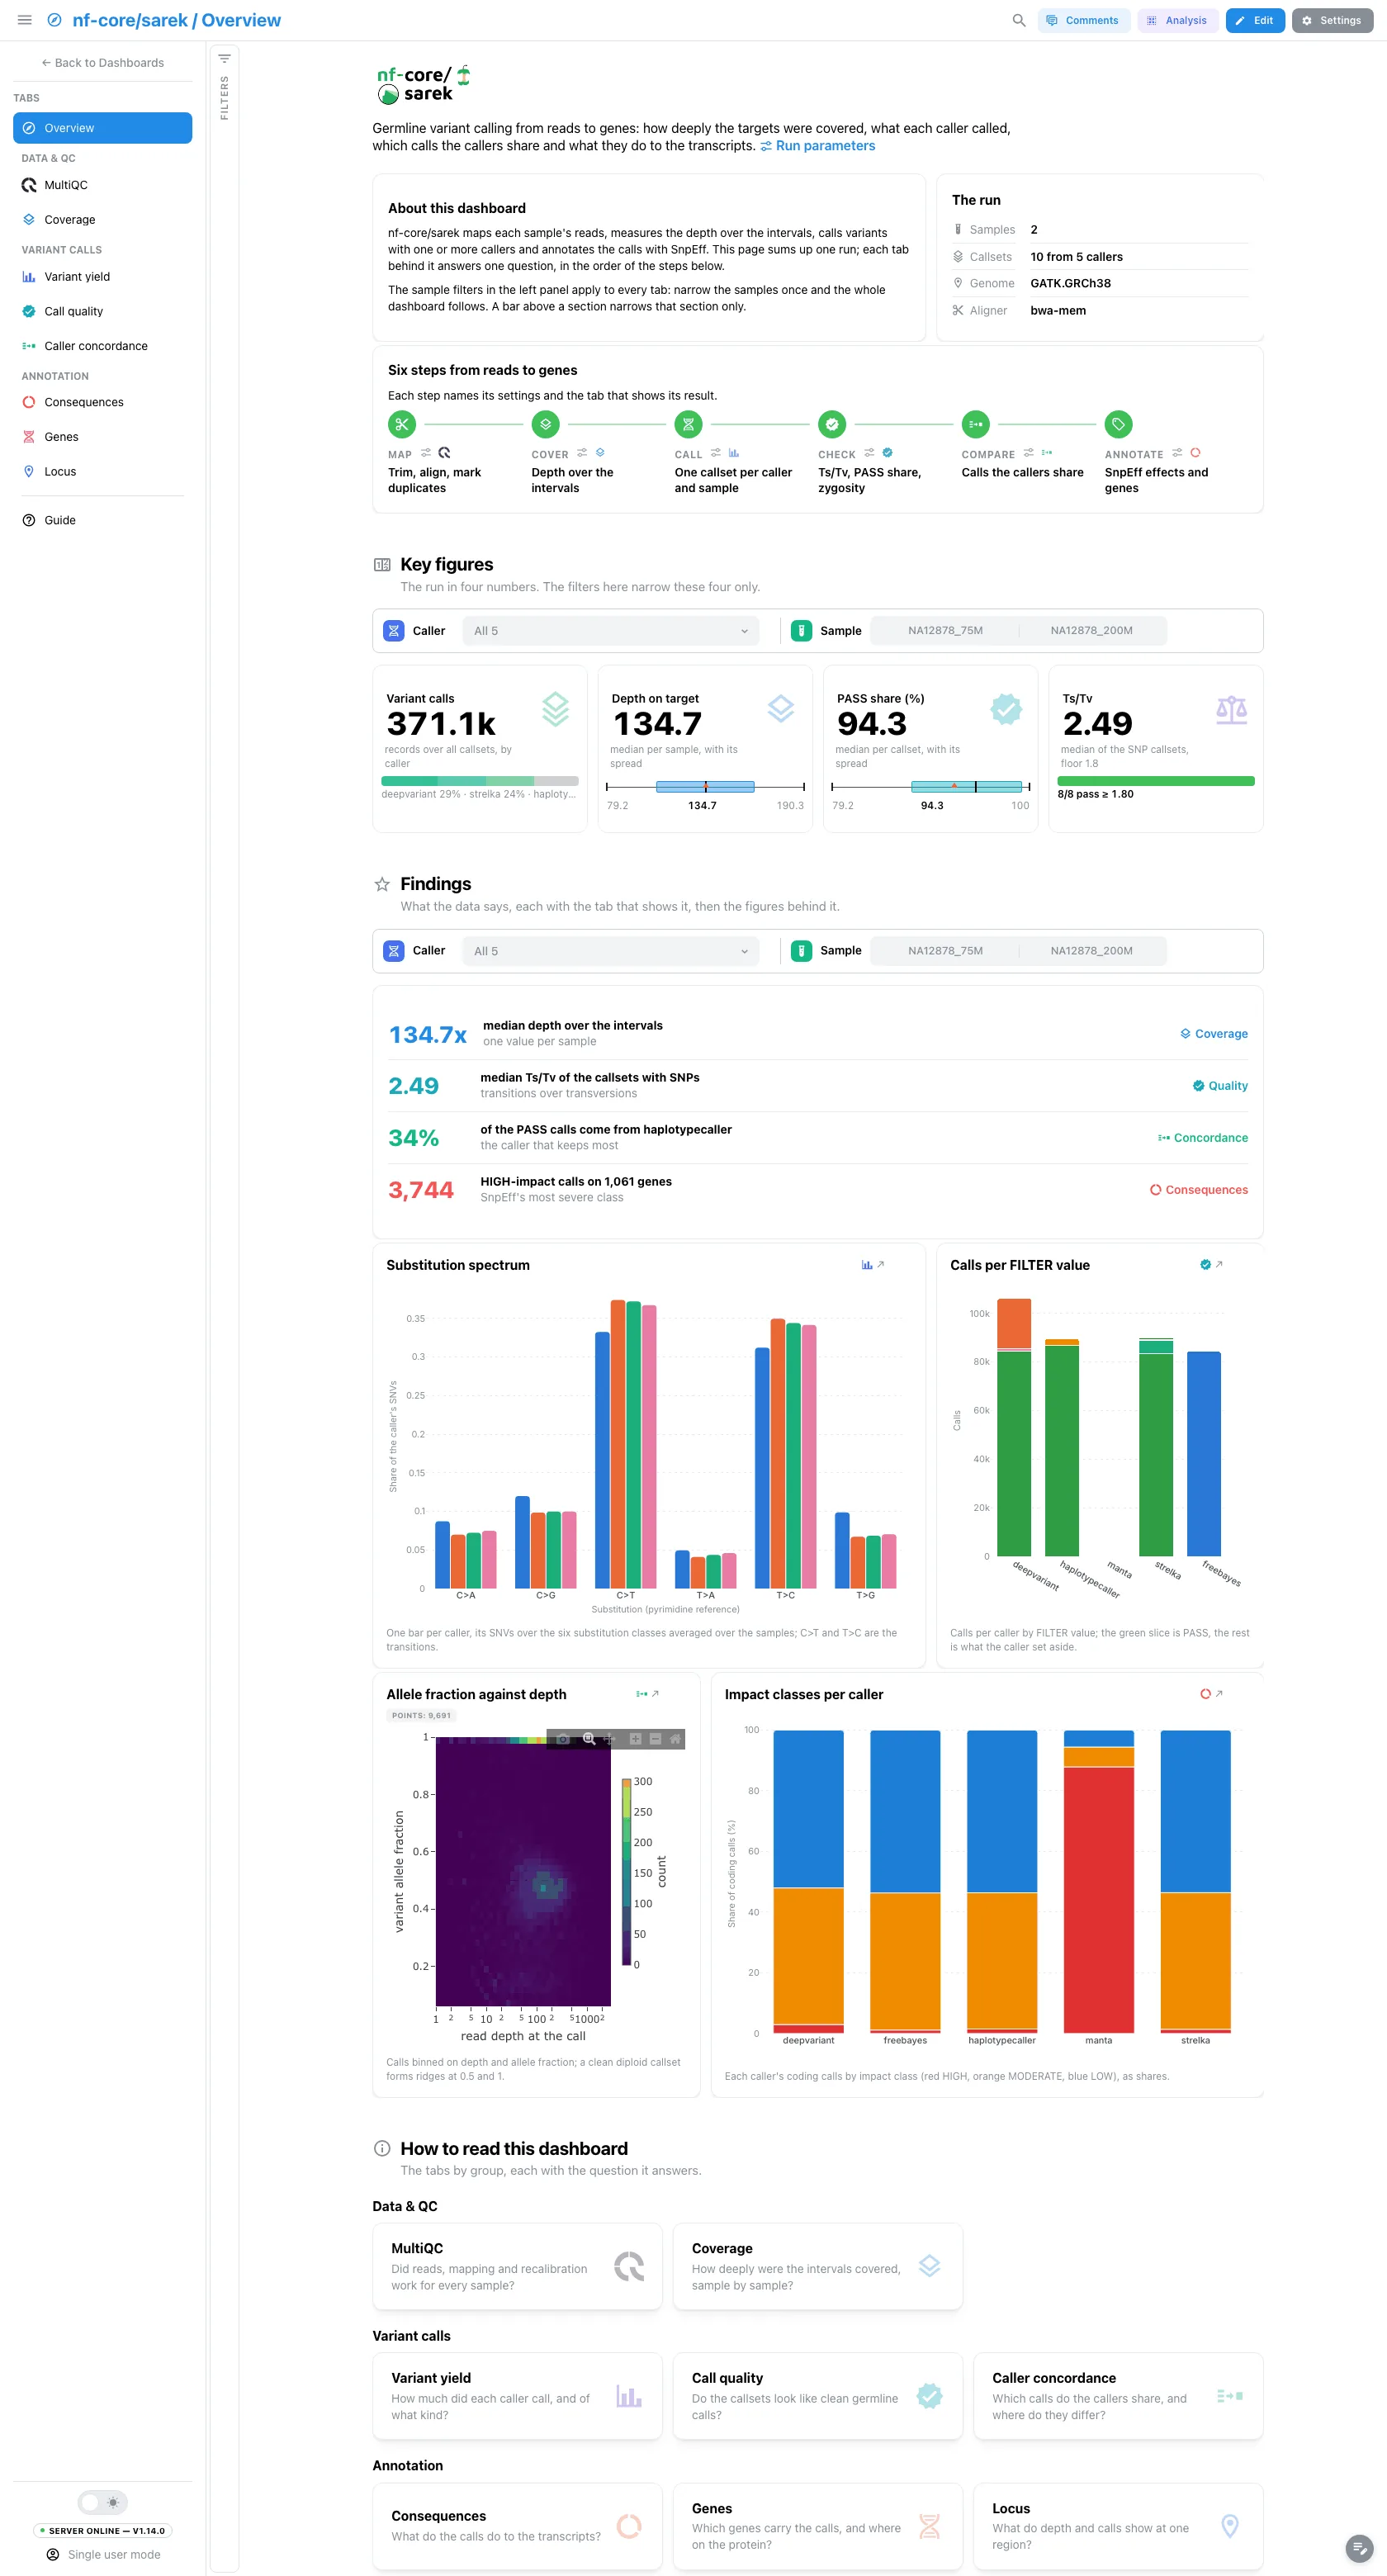
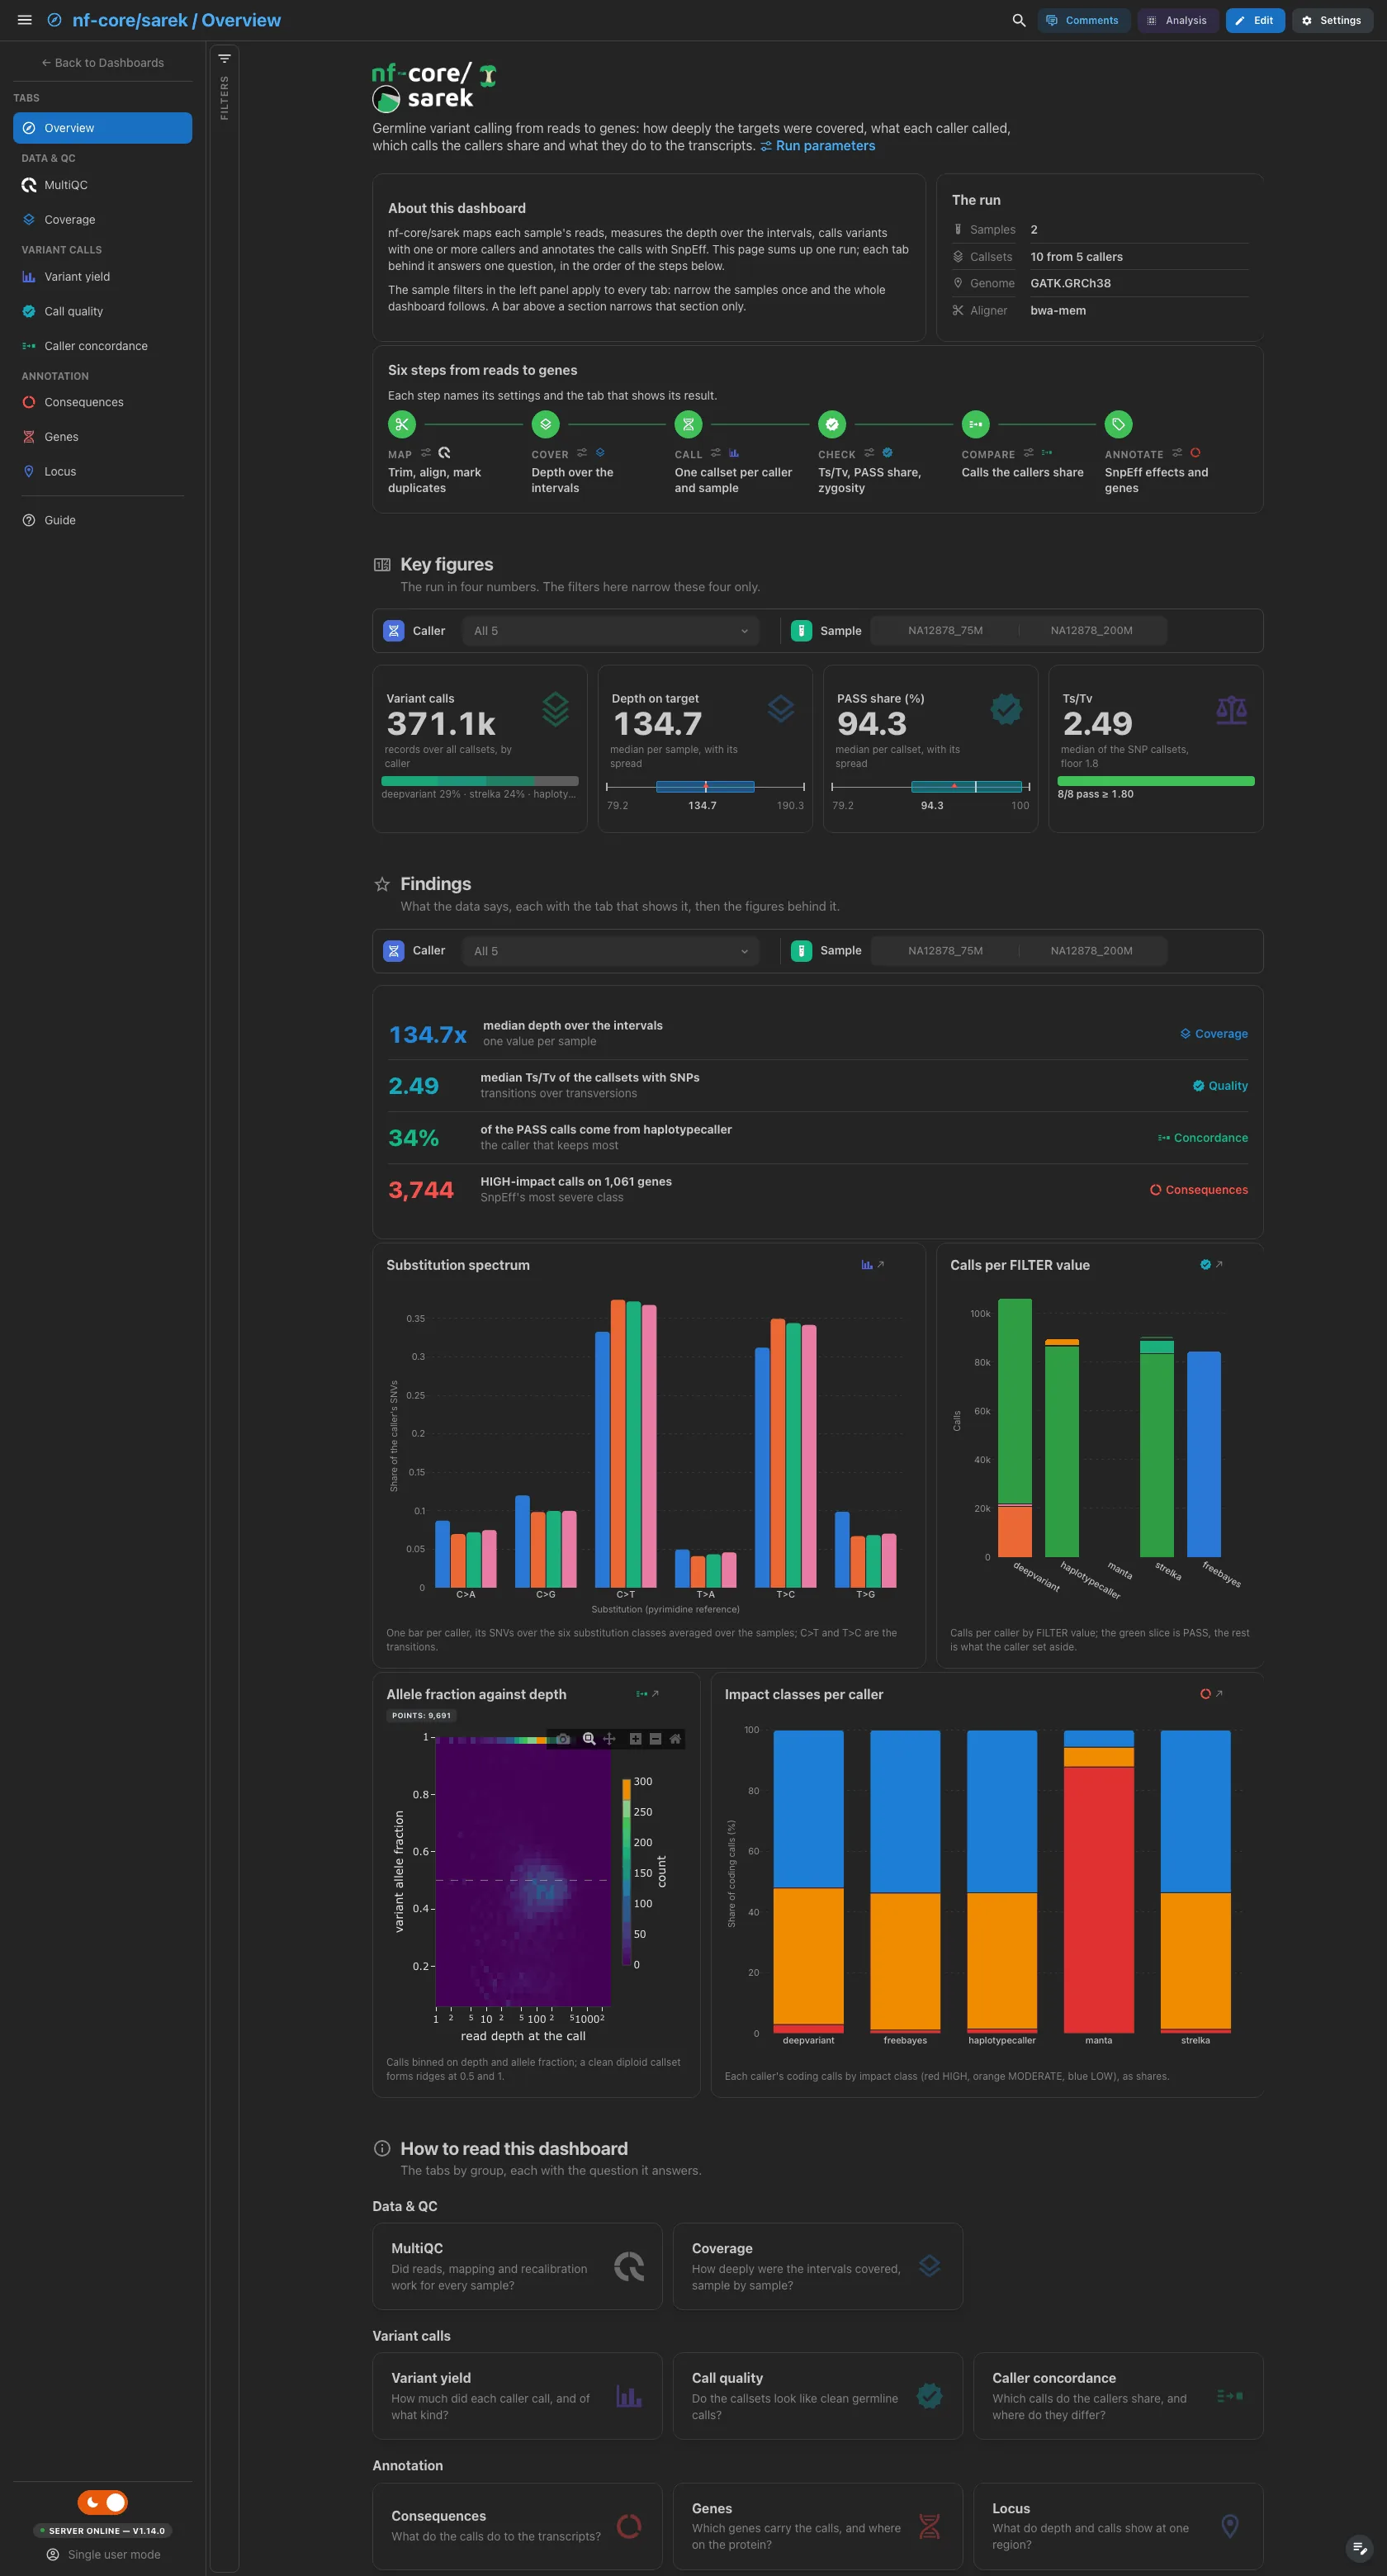
A short hero links the run parameters. About this dashboard says how the two filter levels work, The run lists the samples, the callsets and the callers they come from, the genome and the aligner, and Pipeline walks the six steps from mapping to annotation, each linked to the parameters that drive it and its tab. The findings are live values: they follow the filters, and a run without SnpEff drops the HIGH-impact row and the impact figure. On a run with somatic calls the findings also plot the somatic variants along the genome, and a click on one opens the Locus tab on it.
Filters and components
Filters · the left panel starts collapsed. Key figures and Findings each have their own filter bar (the caller and the sample id): each narrows its own section only.
| Section | What it holds |
|---|---|
| Top | Hero, About this dashboard, The run, Pipeline |
| Key figures | 4 headline cards: variant calls by caller, depth on target, PASS share, Ts/Tv against a 1.8 floor |
| Findings | Live result rows, then 4 figures: the substitution spectrum, the calls per FILTER value, allele fraction against depth and the impact classes per caller |
| How to read this dashboard | The tabs by group, each with its question |
Data & QC · Did reads, mapping and recalibration work for every sample?
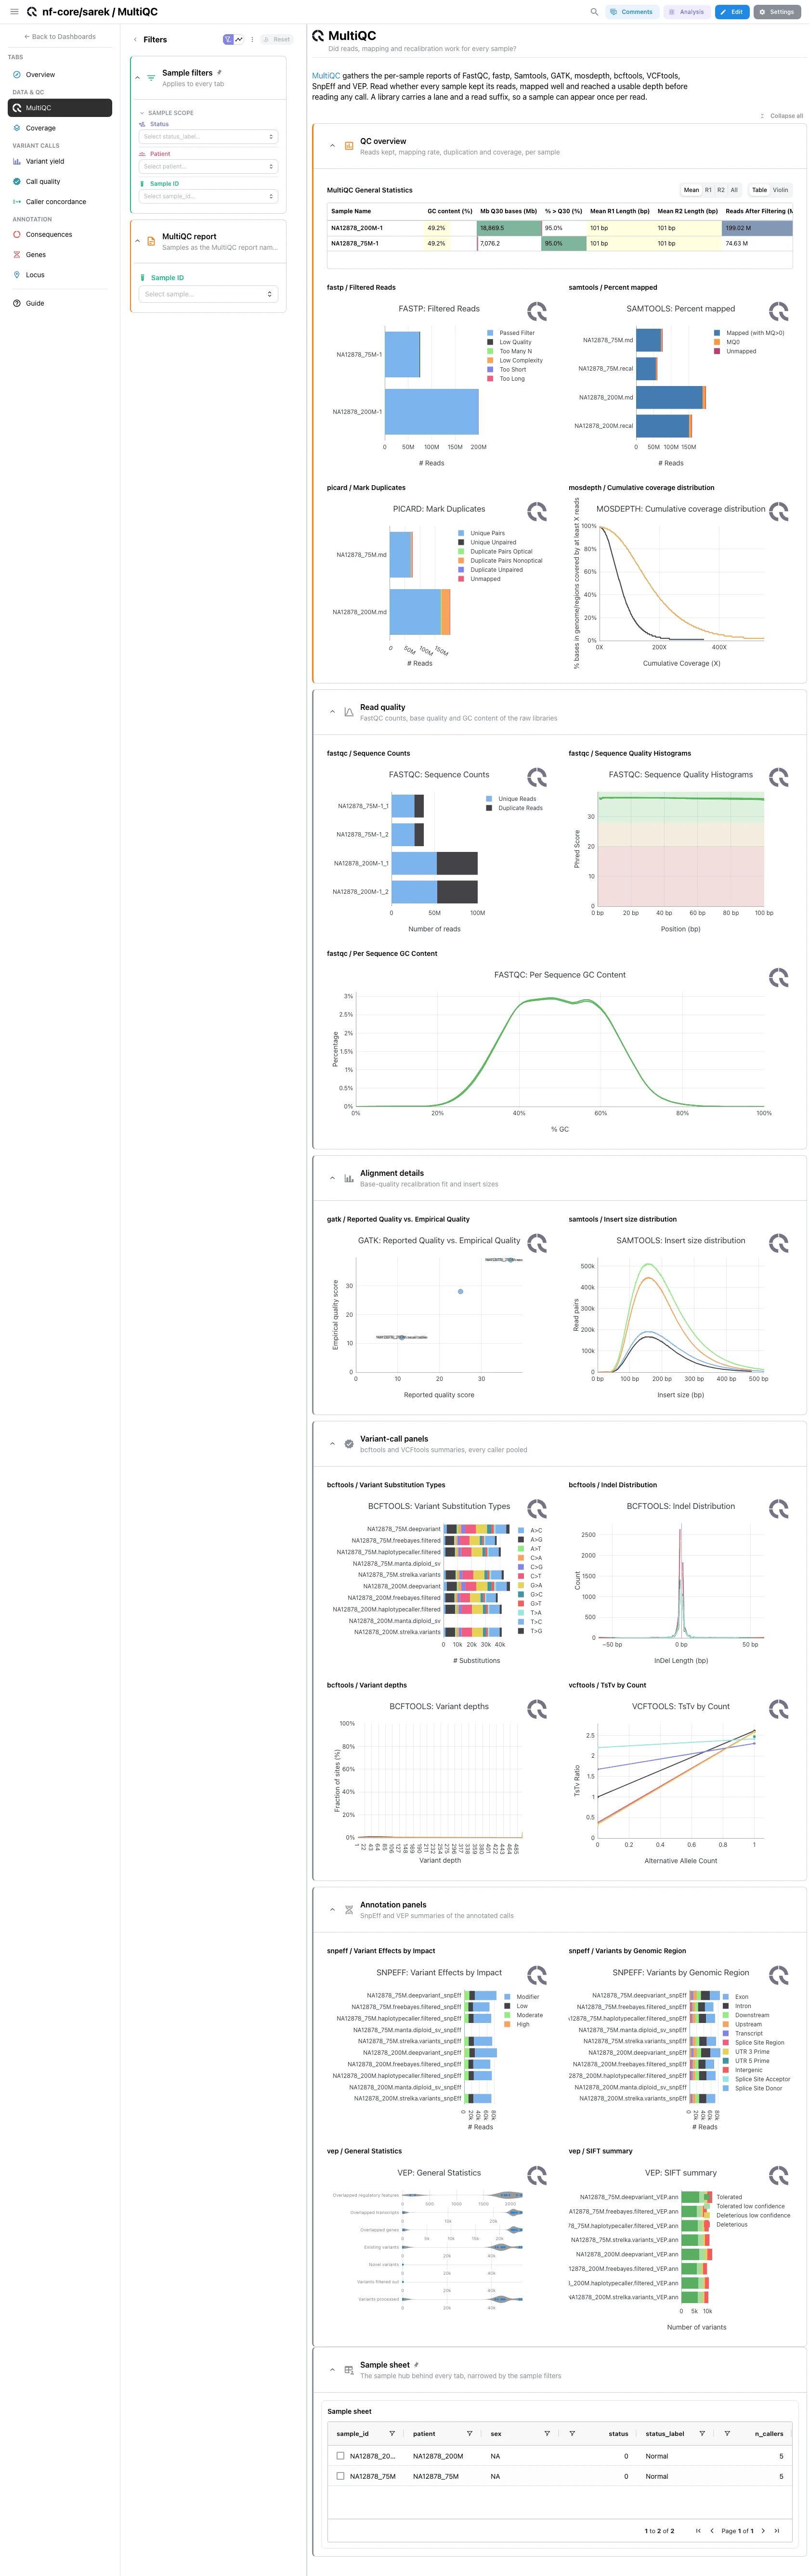
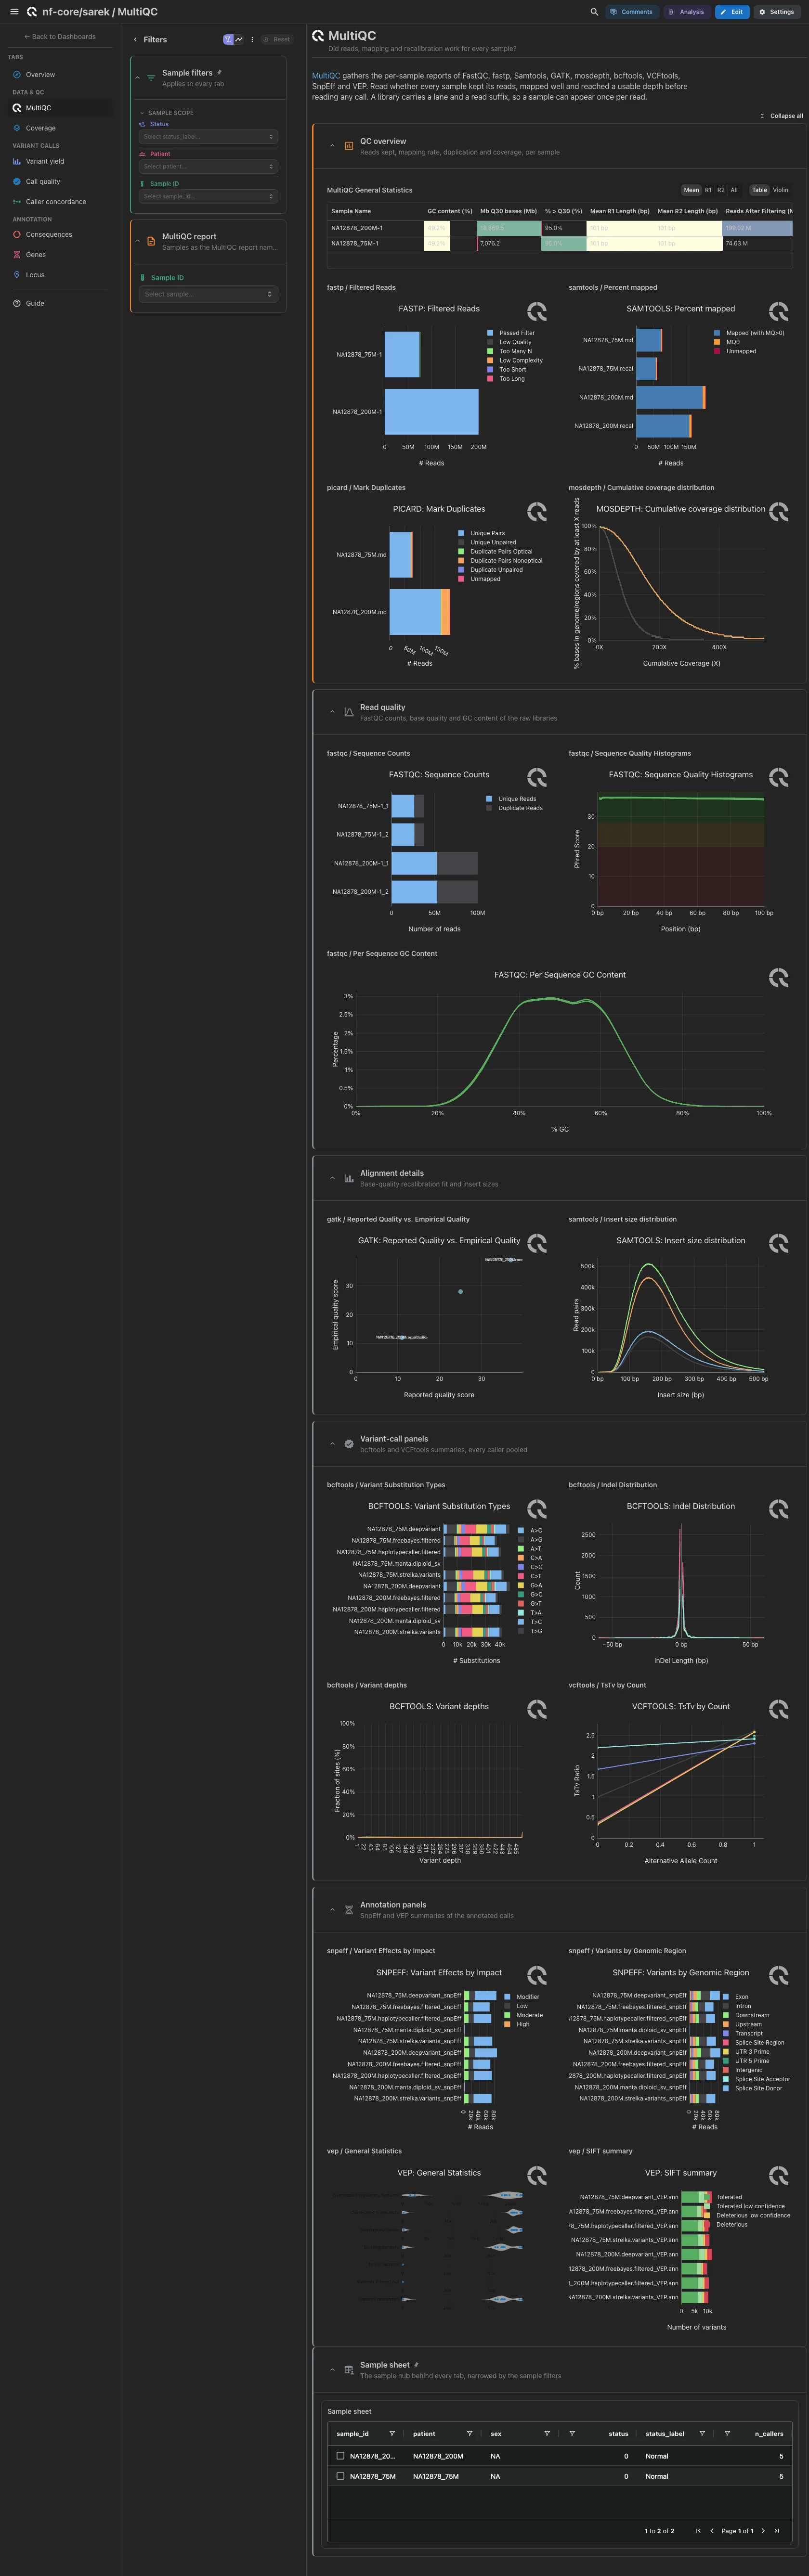
MultiQC panels only, from the run's native report. Open: general statistics, fastp filtered reads, Samtools percent mapped, MarkDuplicates and the mosdepth cumulative coverage. Collapsed: the FastQC panels, the BQSR fit and insert sizes, the bcftools and VCFtools panels with every caller pooled, and the SnpEff and VEP panels. A library carries a lane and a read suffix in the report, so a sample can appear once per read.
Filters and components
Filters · the pinned sample filters narrow its panels.
| Section | What it holds |
|---|---|
| QC overview | 5 MultiQC panels |
| Read quality (collapsed) | 3 MultiQC panels |
| Alignment details (collapsed) | 2 MultiQC panels |
| Variant-call panels (collapsed) | 4 MultiQC panels |
| Annotation panels (collapsed) | 4 MultiQC panels |
Data & QC · How deeply were the intervals covered, sample by sample?
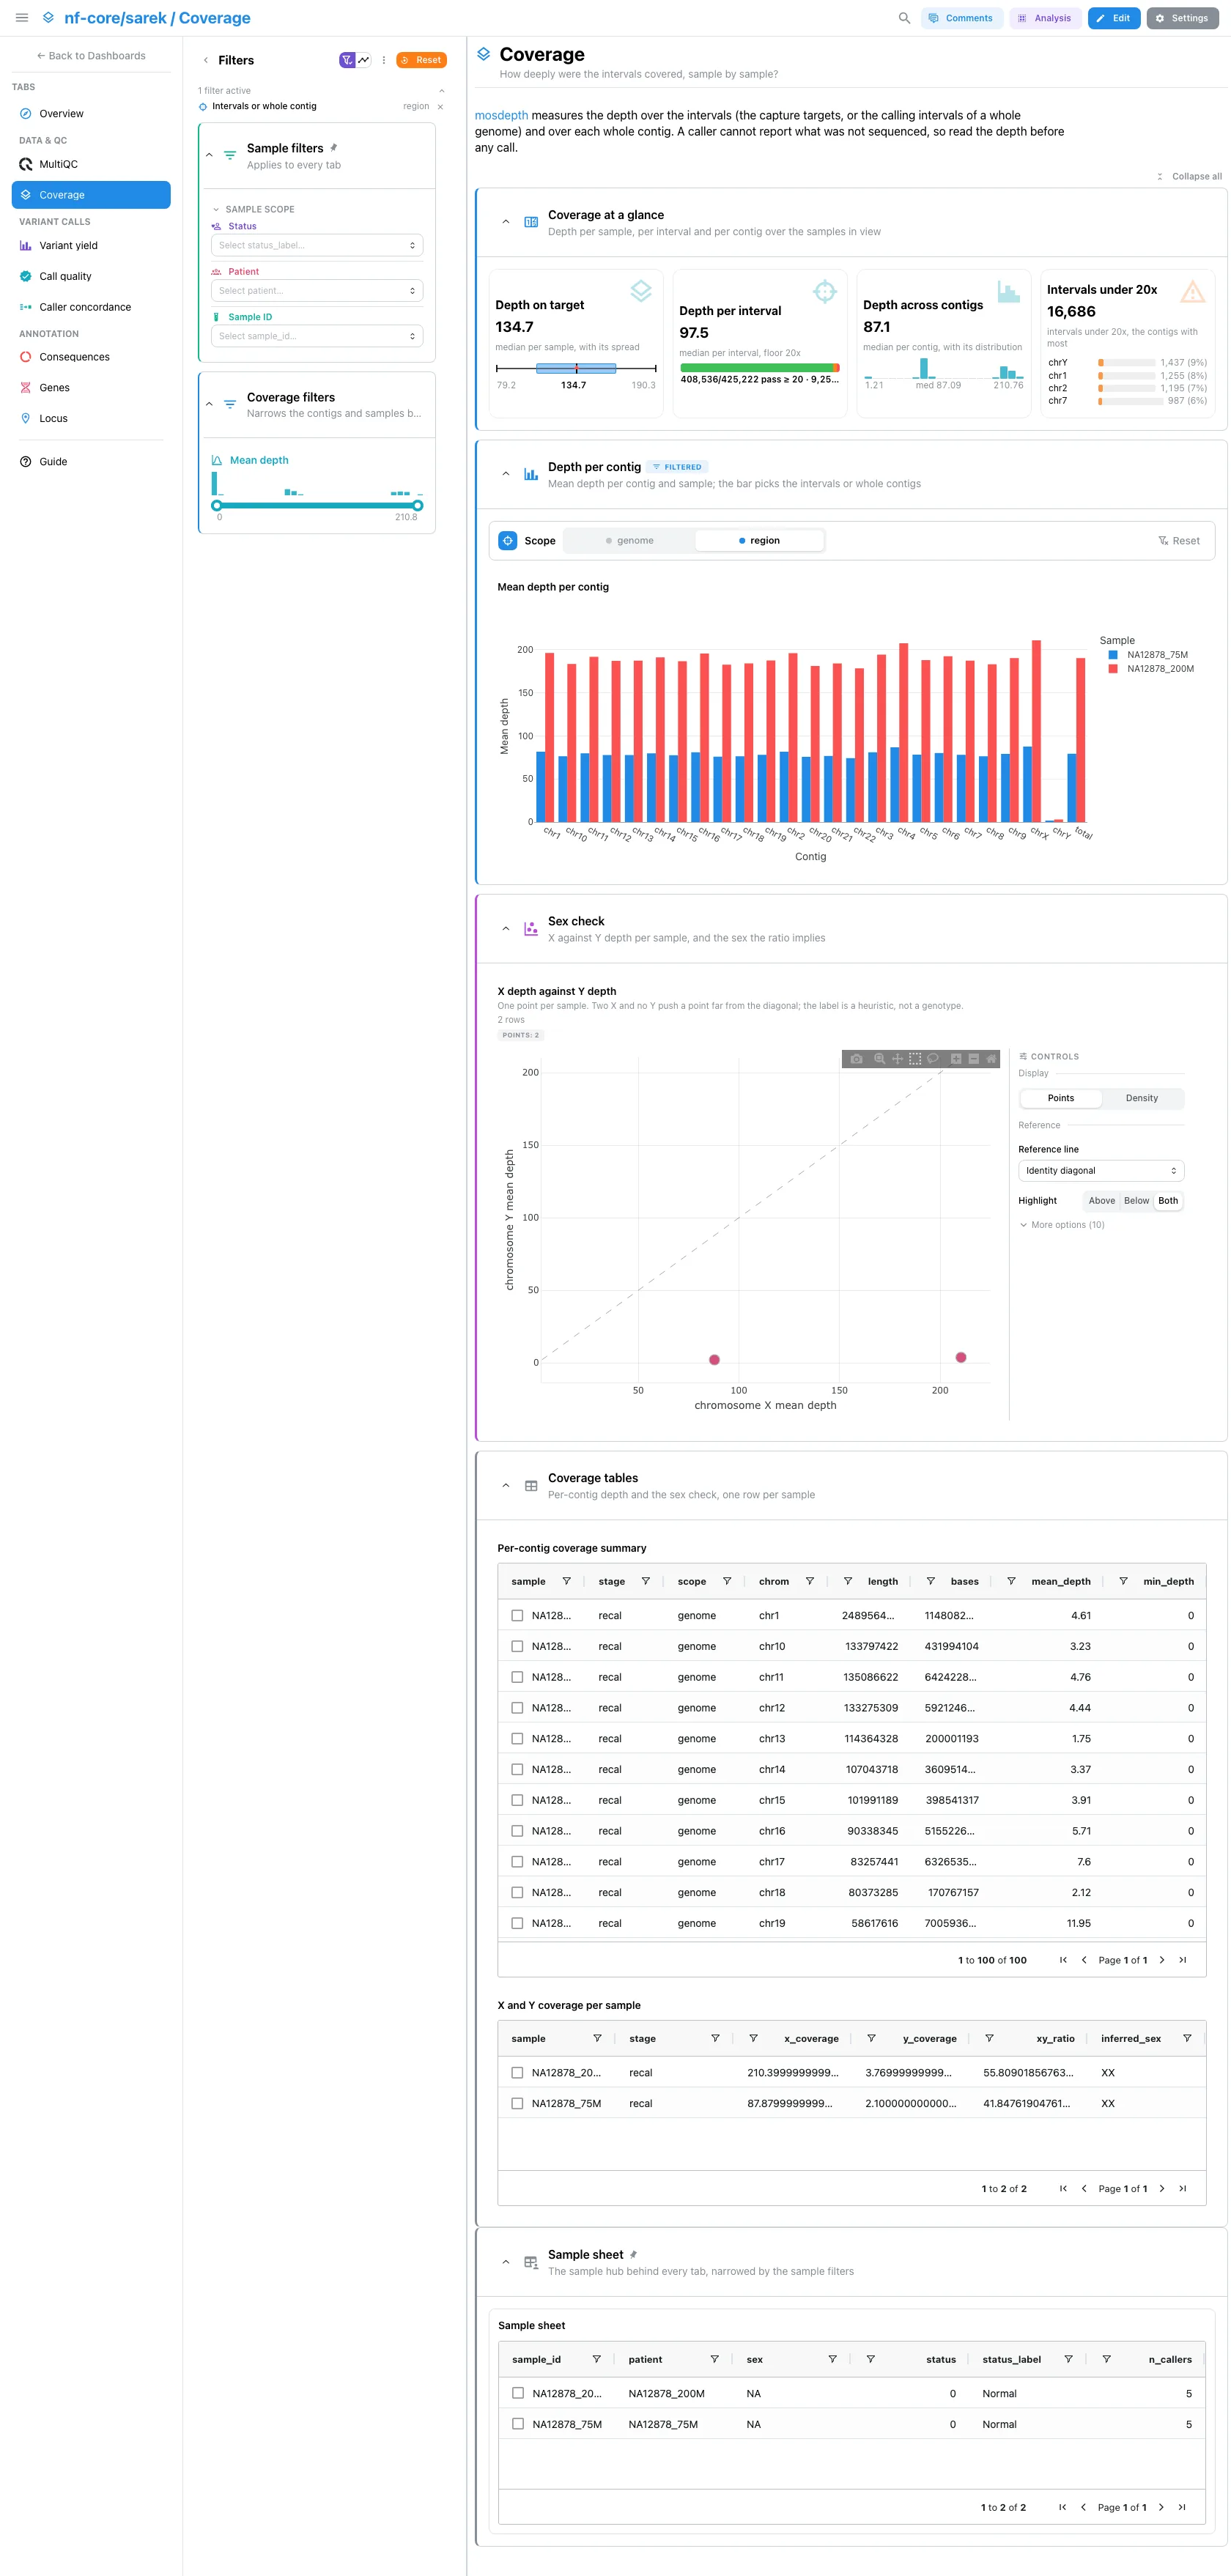
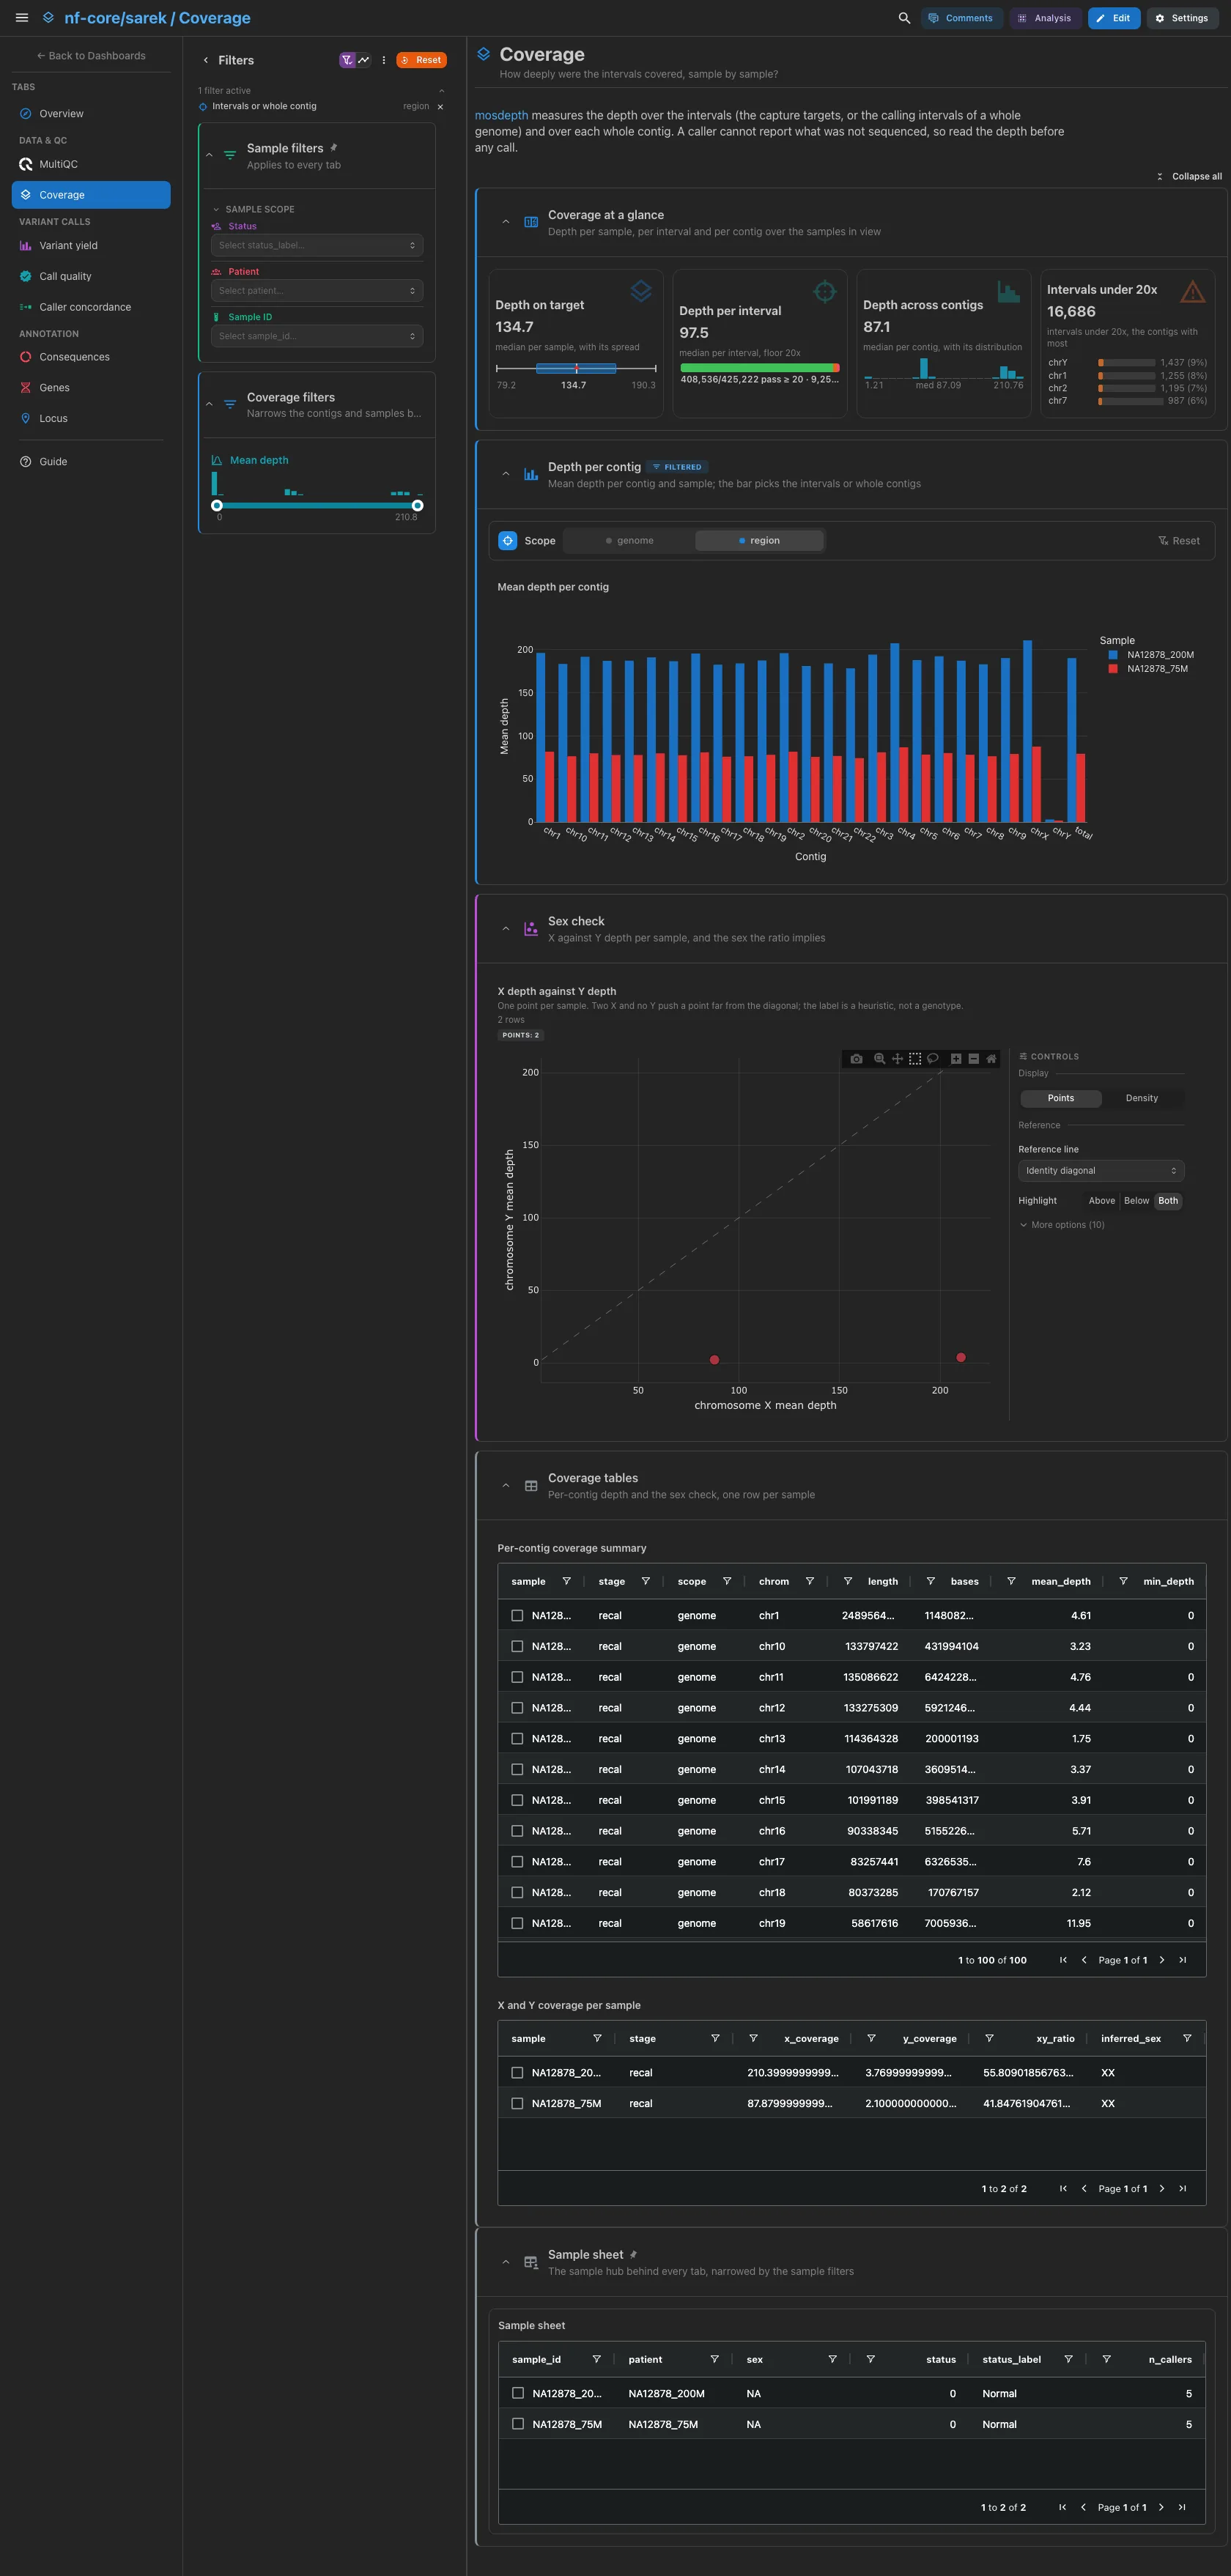
mosdepth's depth over the intervals (the capture targets, or the calling intervals of a whole genome) and over each contig. The depth on target per sample, the median depth of an interval against a 20x floor, the depth across contigs and the intervals under 20x, with the contigs that have most. Then the mean depth per contig, one bar per sample and contig, with a bar above it that switches between the intervals and the whole contig (it opens on the intervals), and the X against Y depth scatter, a heuristic sex check. The per-contig and sex-check tables are collapsed.
Filters and components
Filters · a Mean depth range on mosdepth_summary. Depth per
contig has its own bar, Intervals or whole contig. There is no contig
or scope picker in the left panel: it would empty the Depth on target
card, which reads mosdepth's total row of the intervals.
| Section | What it holds |
|---|---|
| Coverage at a glance | 4 cards |
| Depth per contig | Mean depth per contig, with its own filter bar |
| Sex check | 1 advanced visualization |
| Coverage tables (collapsed) | Per-contig coverage summary, X and Y coverage per sample |
Variant calls · How much did each caller call, and of what kind?
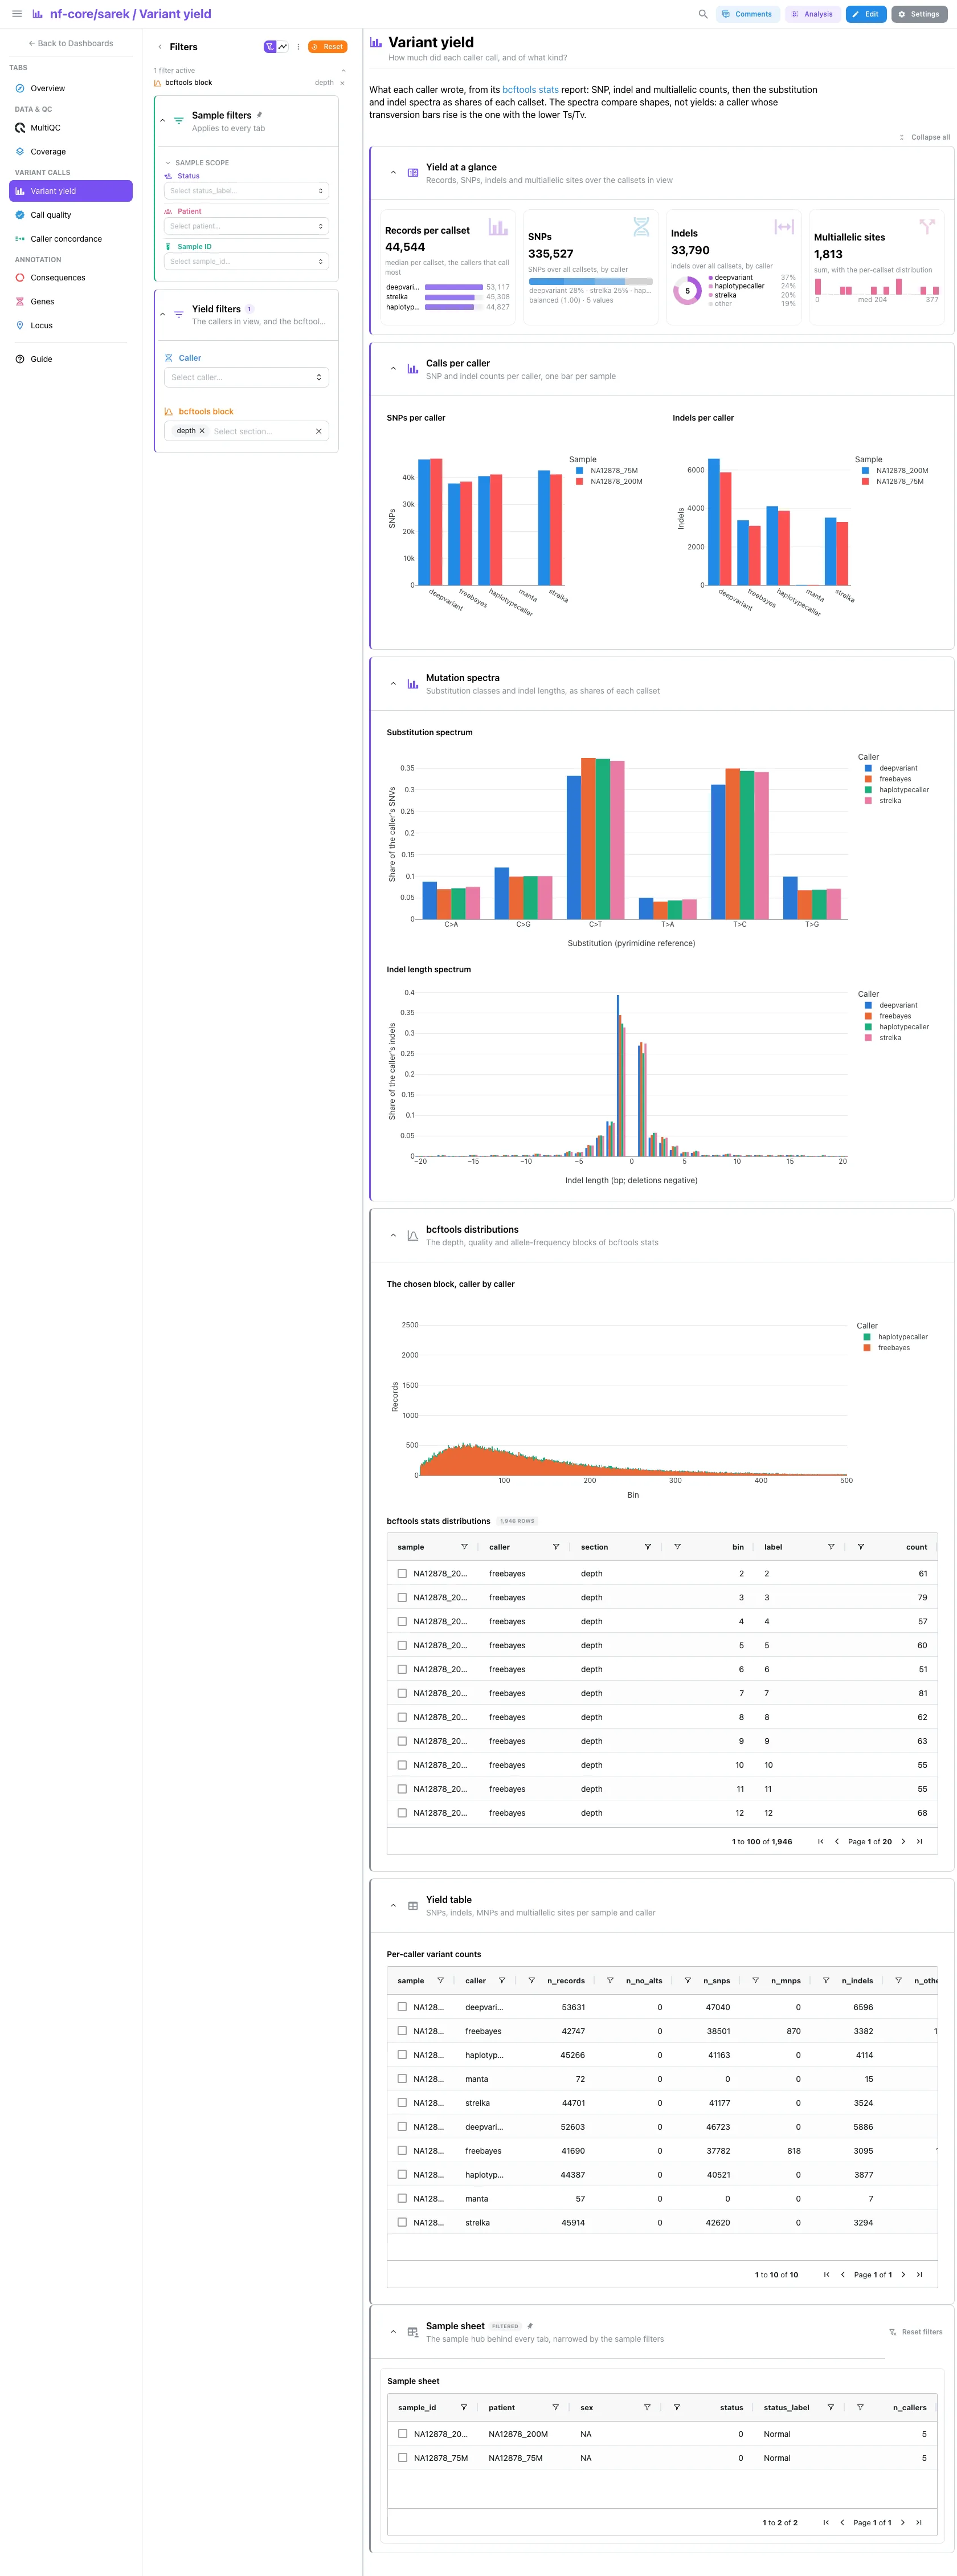
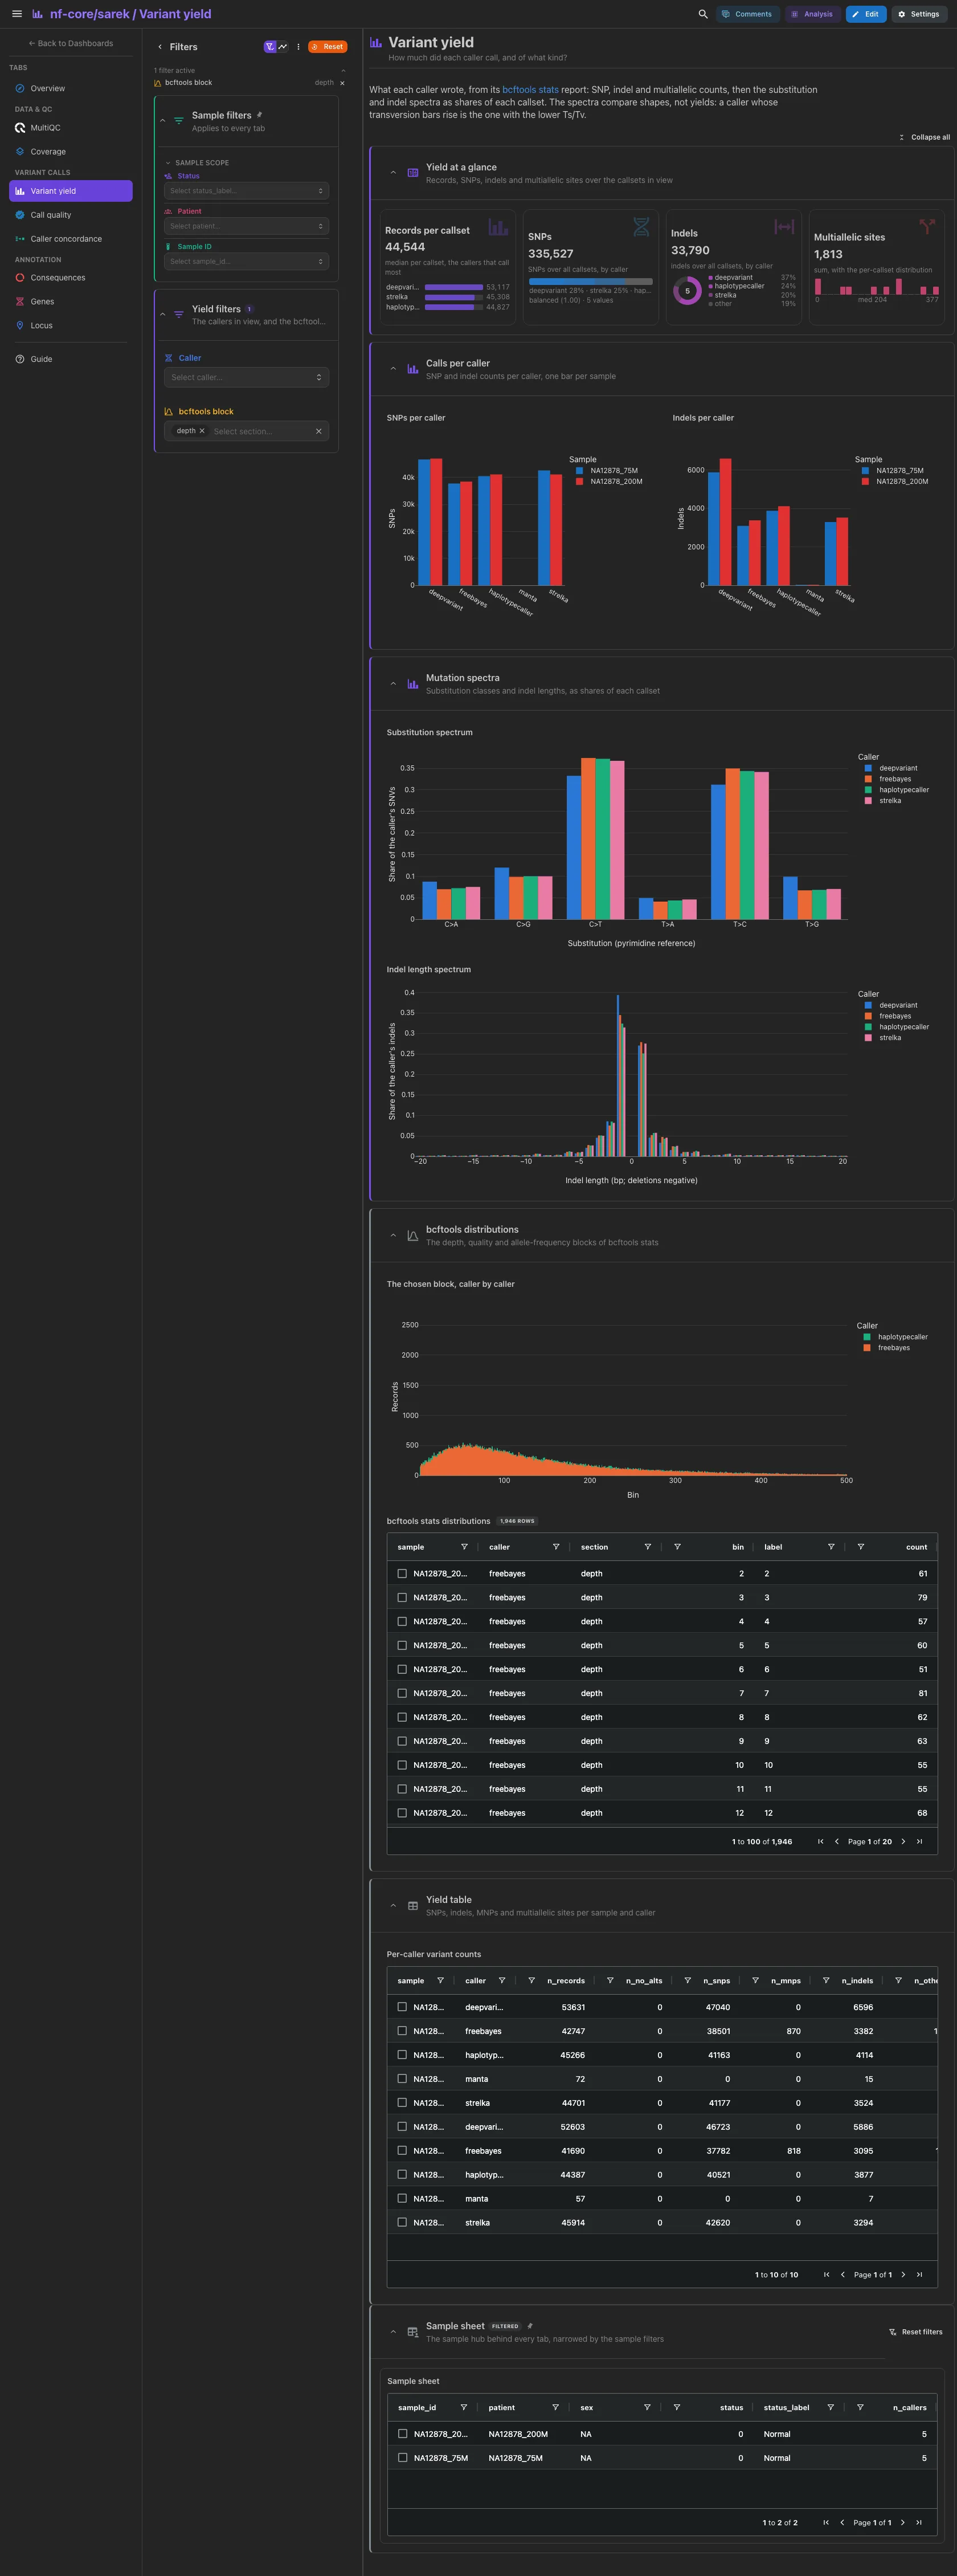
Each caller's own bcftools stats report. The median records per callset, ranked by caller (a structural-variant caller writes orders of magnitude fewer), the SNPs and the indels split by caller, and the multiallelic sites. Then SNPs and indels per caller, one bar per sample, and the substitution and indel length spectra, one bar per caller with its callsets' shares averaged. The spectra compare shapes, not yields: a caller whose transversion bars rise is the one with the lower Ts/Tv. The bcftools distribution blocks and the per-caller count table are collapsed.
Filters and components
Filters · Caller on bcftools_stats_summary, and a bcftools
block picker on bcftools_stats_sections that chooses the block the
collapsed distribution draws (it opens on depth).
| Section | What it holds |
|---|---|
| Yield at a glance | 4 cards |
| Calls per caller | SNPs per caller, Indels per caller |
| Mutation spectra | Substitution spectrum, Indel length spectrum |
| bcftools distributions (collapsed) | The chosen block, caller by caller, bcftools stats distributions |
| Yield table (collapsed) | Per-caller variant counts |
Variant calls · Do the callsets look like clean germline calls?
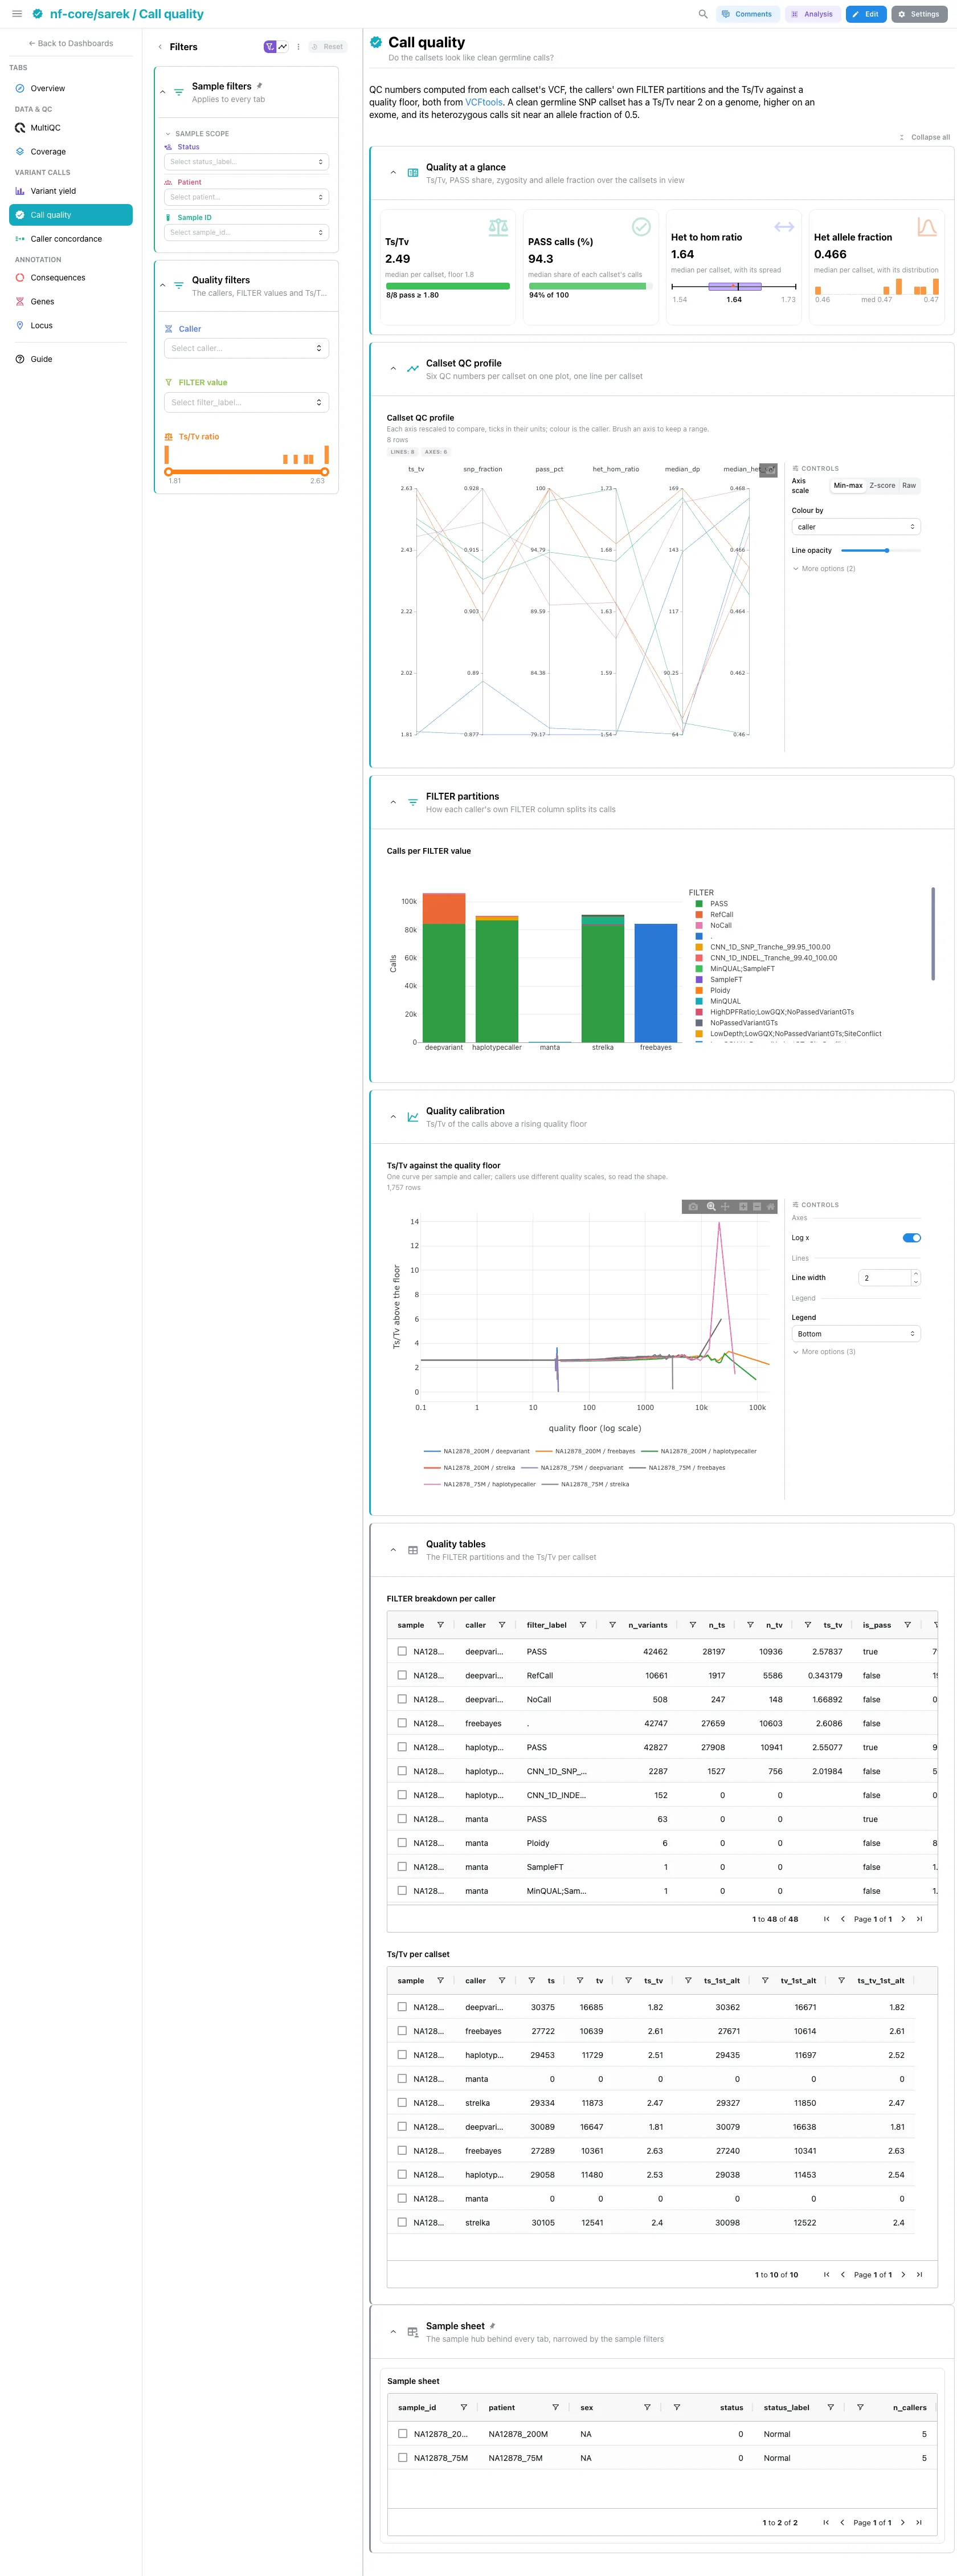
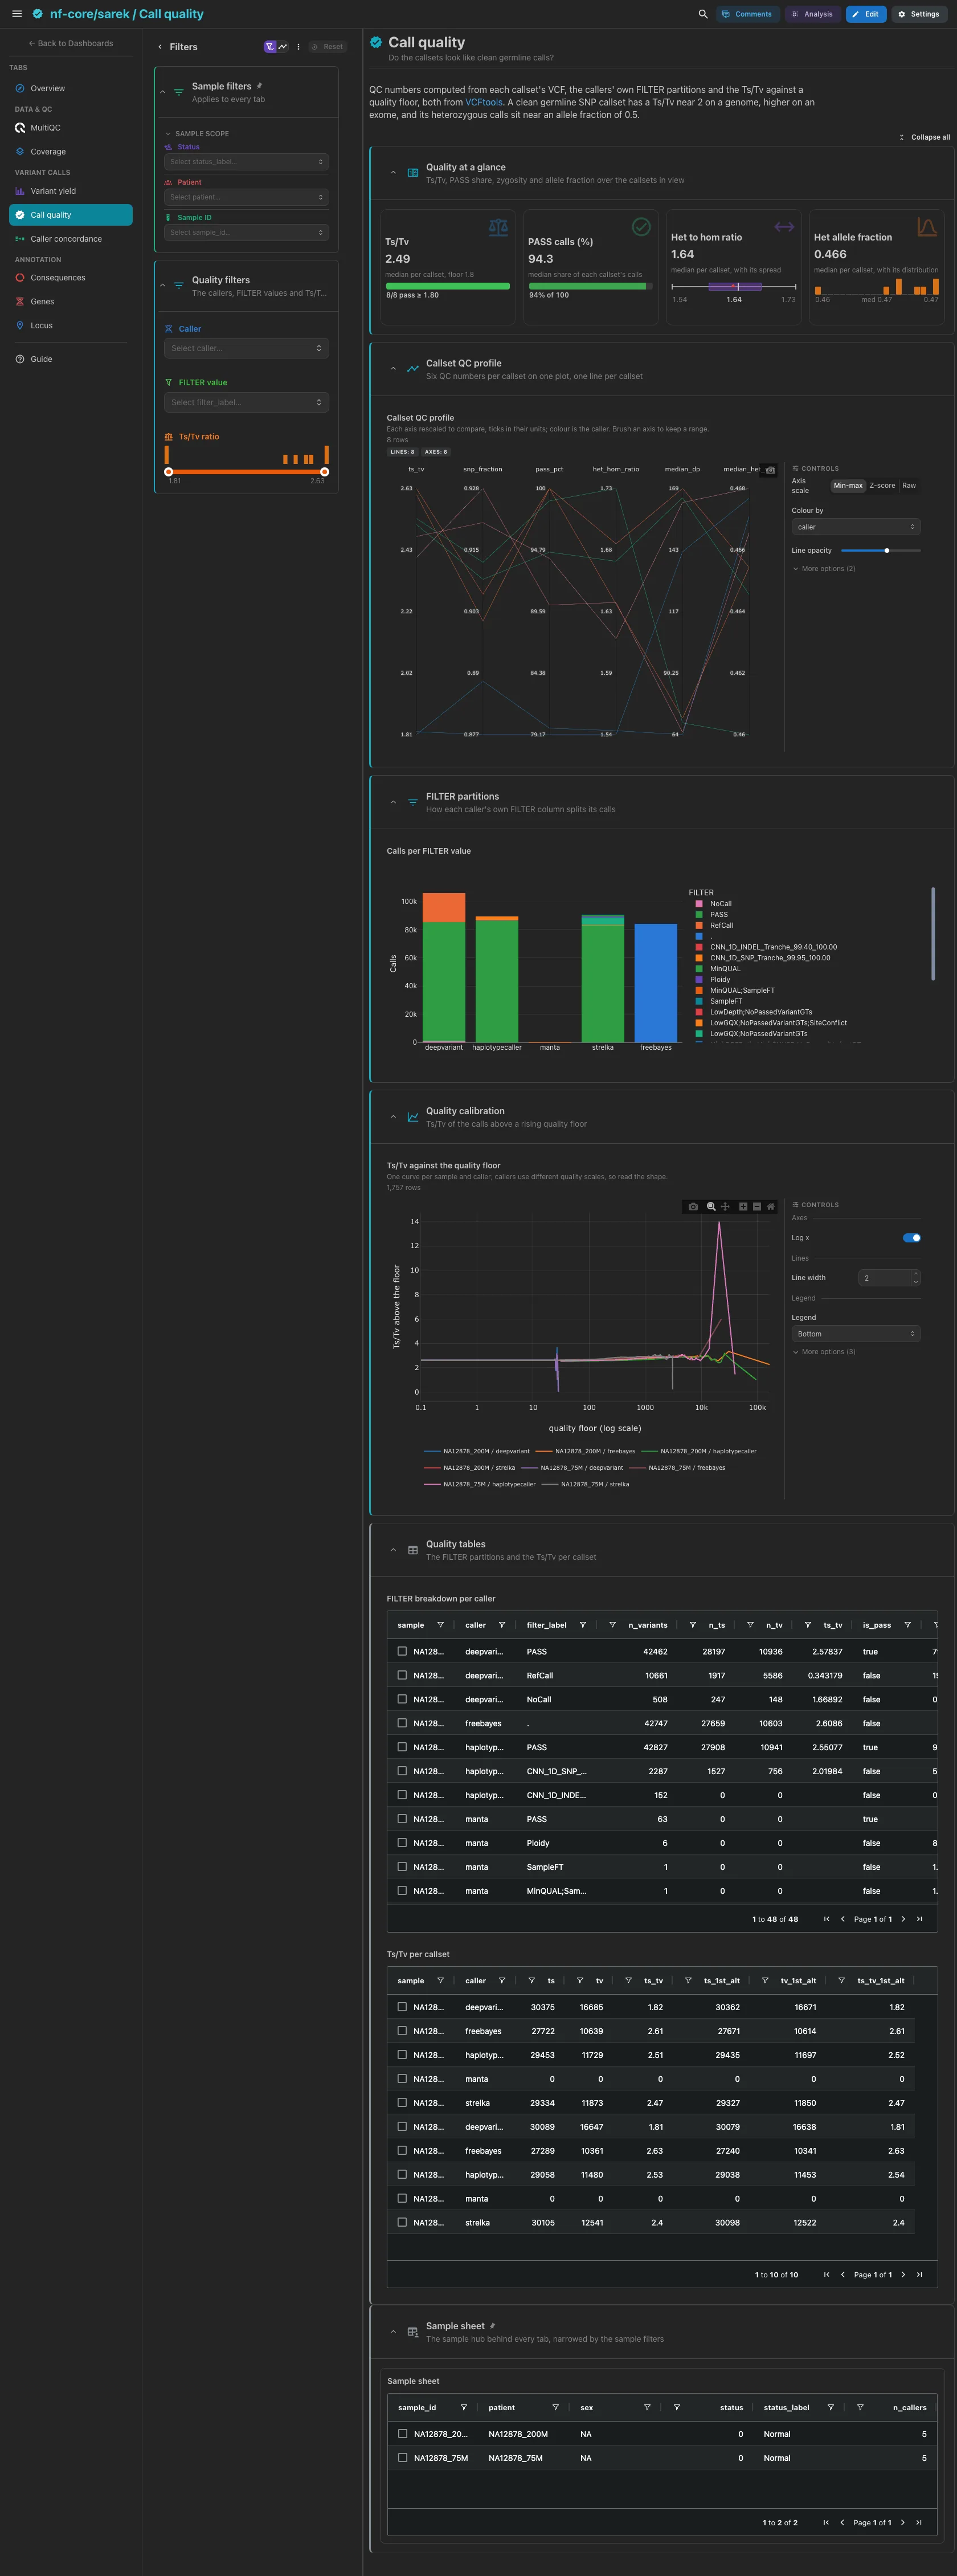
QC numbers computed from each callset's VCF. The median Ts/Tv against a 1.8 floor, the PASS share, the het to hom ratio and the allele fraction of heterozygous calls. Then the callset QC profile, six numbers per callset on parallel axes coloured by caller, the calls per FILTER value per caller, with PASS in green, and the Ts/Tv above a rising quality floor on a log axis, because callers write QUAL on scales a thousand-fold apart. A clean germline SNP callset has a Ts/Tv near 2 on a genome, higher on an exome, and its heterozygous calls sit near an allele fraction of 0.5. The FILTER breakdown and the Ts/Tv per callset are collapsed.
Filters and components
Filters · Caller and a Ts/Tv ratio range on callset_qc, and
FILTER value on vcftools_filter_summary.
| Section | What it holds |
|---|---|
| Quality at a glance | 4 cards |
| Callset QC profile | 1 advanced visualization |
| FILTER partitions | Calls per FILTER value |
| Quality calibration | 1 advanced visualization |
| Quality tables (collapsed) | FILTER breakdown per caller, Ts/Tv per callset |
Without VCFtools
A run that skipped VCFtools has no FILTER partitions, no quality sweep and
no FILTER value filter here, and the Overview drops its FILTER figure.
Variant calls · Which calls do the callers share, and where do they differ?
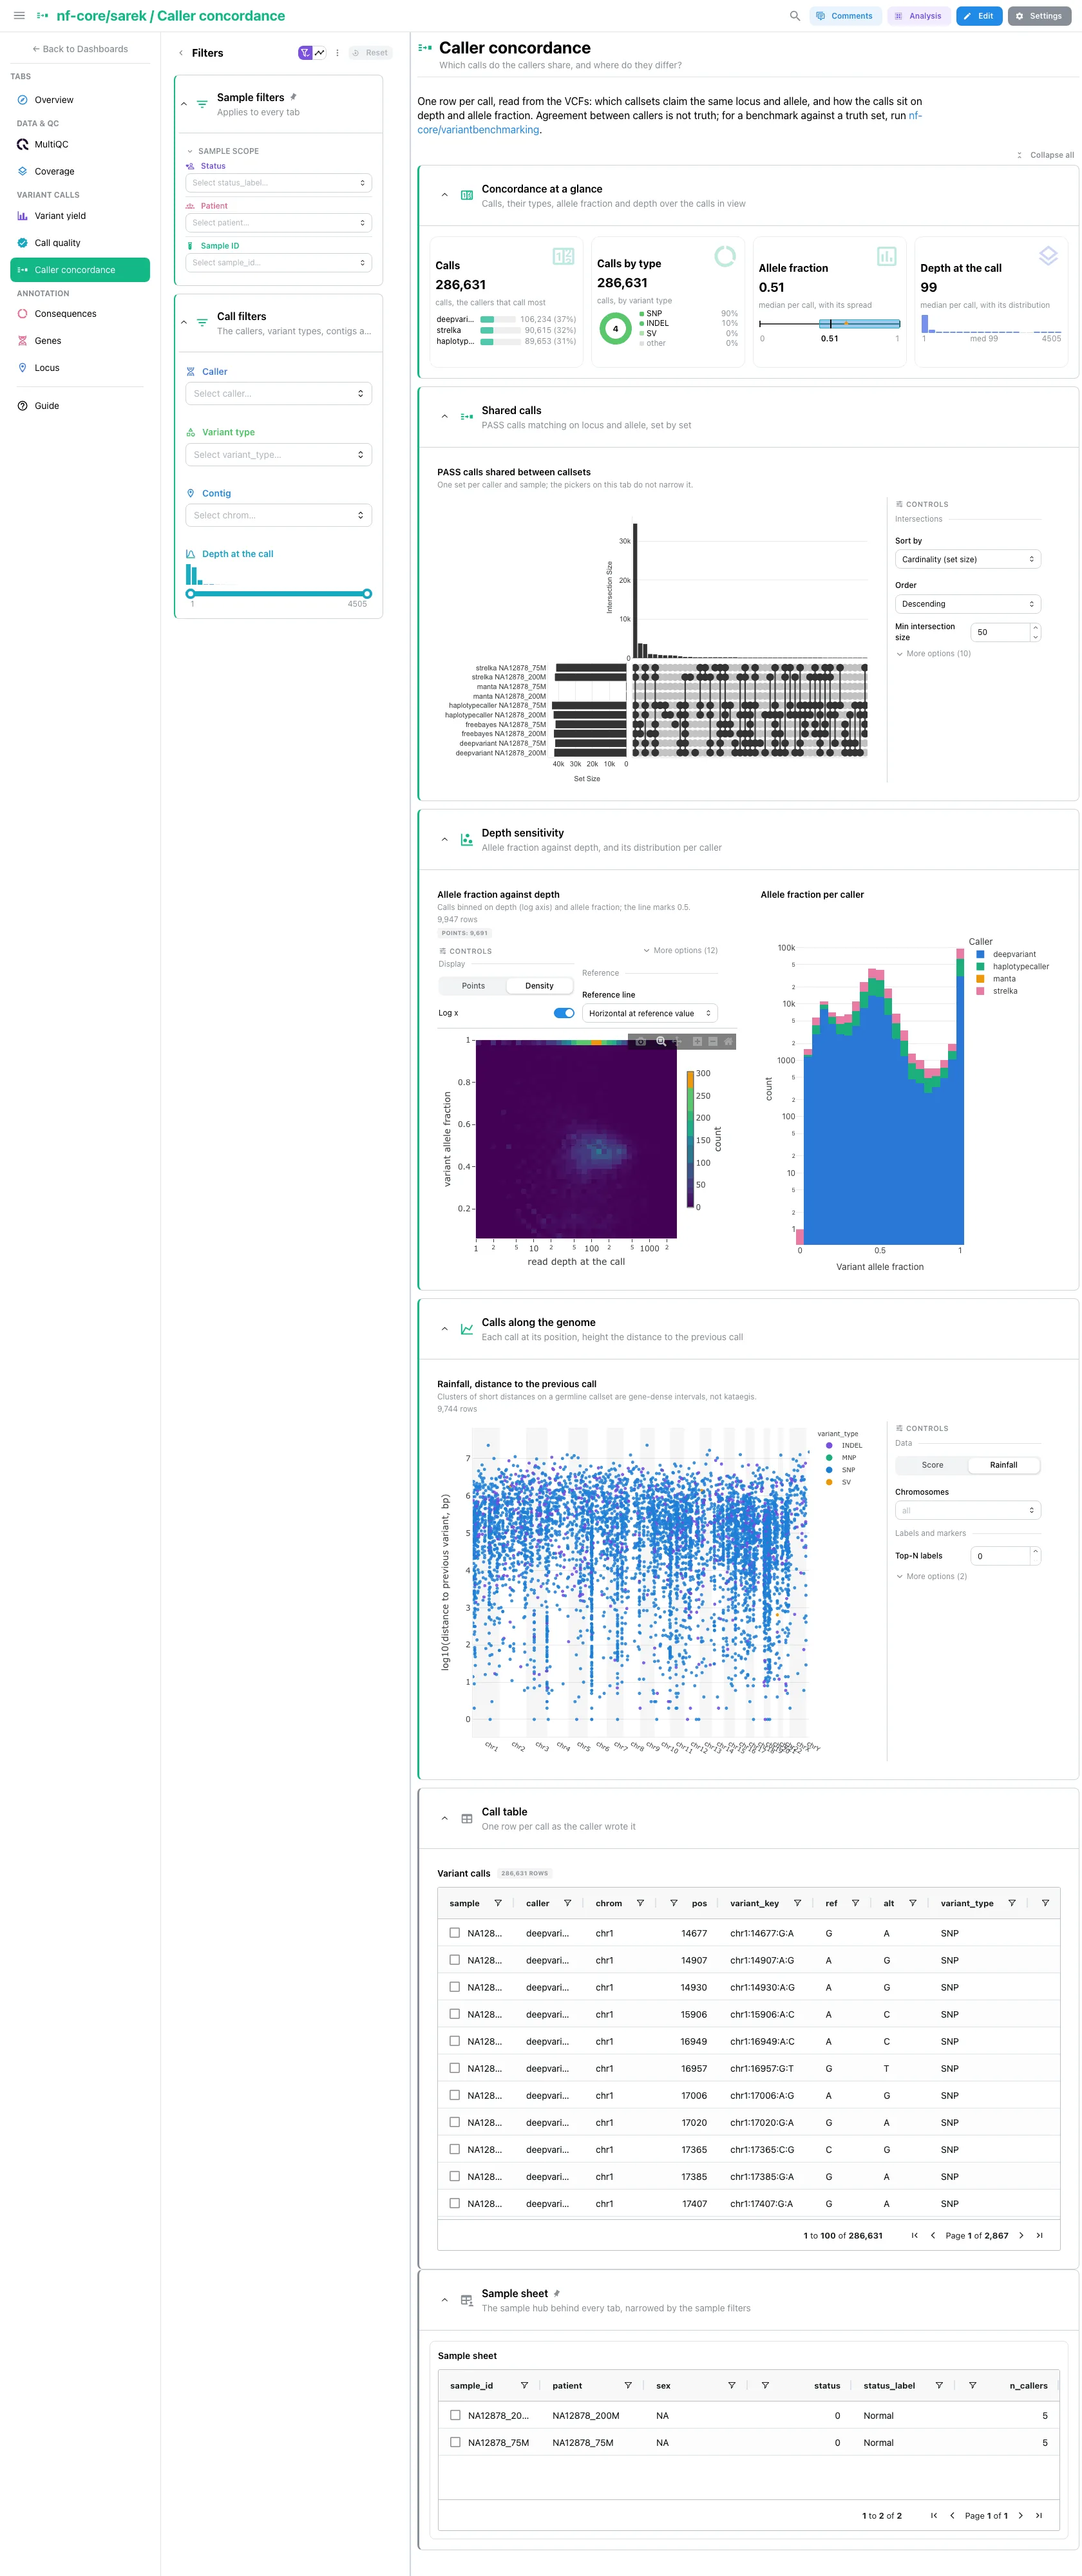
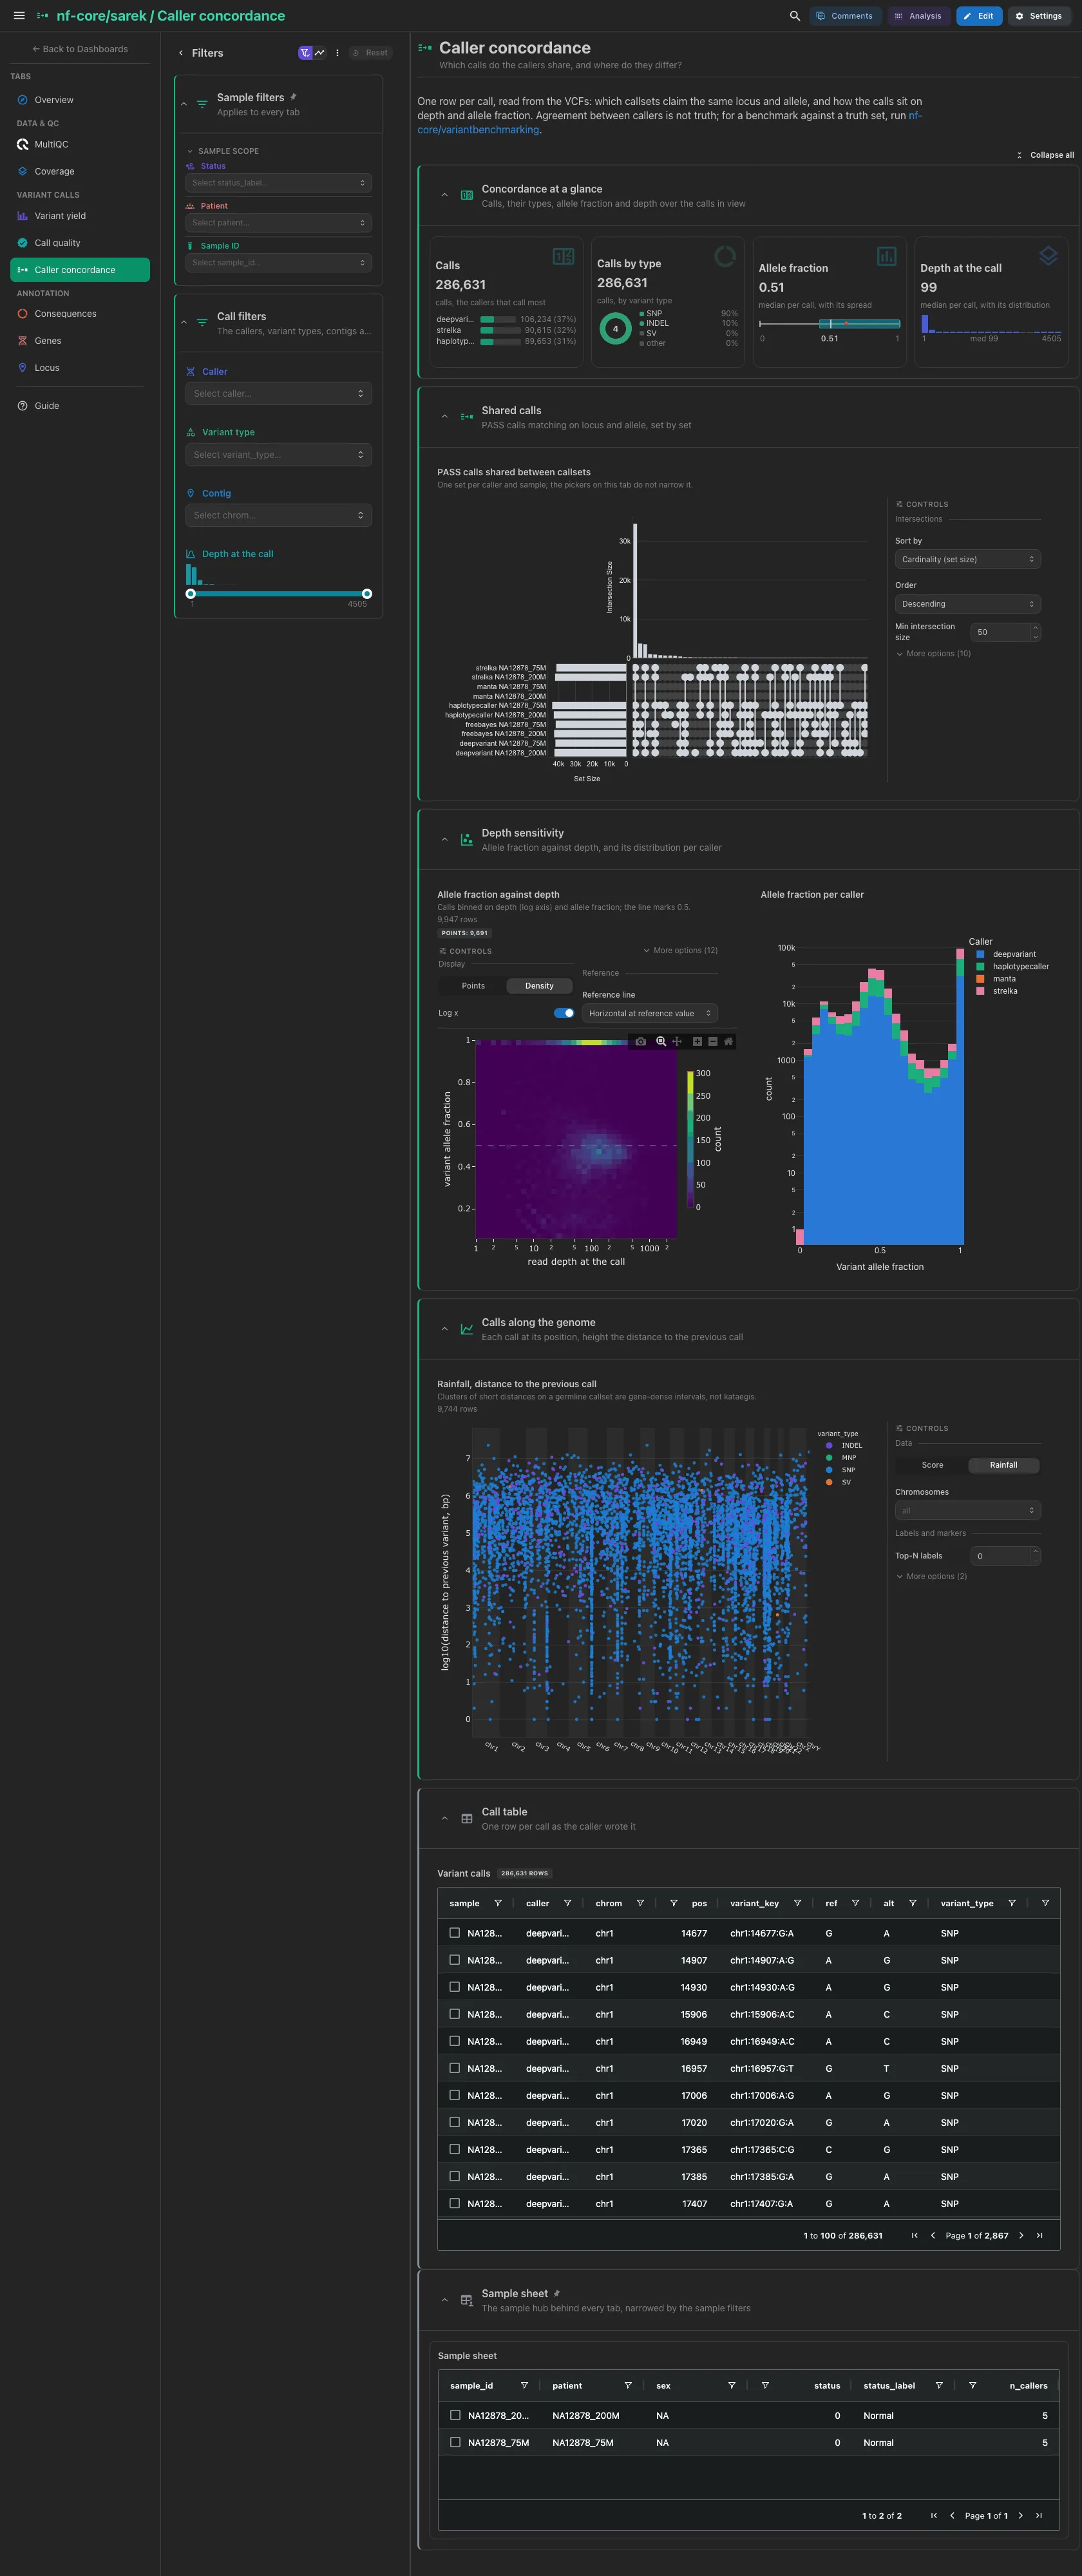
One row per call, read from the VCFs. The calls ranked by caller, the calls by variant type, the allele fraction and the depth at the call. Then the UpSet of PASS calls shared between callsets, matched on locus and allele (fixed: the pickers on this tab do not narrow it), allele fraction against depth as a density beside its histogram per caller (a clean diploid callset forms ridges at 0.5 and 1), and the rainfall of the calls along the genome, each at its distance to the previous call. The call table is collapsed. Agreement between callers is not truth.
Filters and components
Filters · Caller, Variant type, Contig and a Depth at the
call range on vcf_variants.
| Section | What it holds |
|---|---|
| Concordance at a glance | 4 cards |
| Shared calls | 1 advanced visualization |
| Depth sensitivity | 1 advanced visualization, Allele fraction per caller |
| Calls along the genome | 1 advanced visualization |
| Call table (collapsed) | Variant calls |
Annotation · What do the calls do to the transcripts?
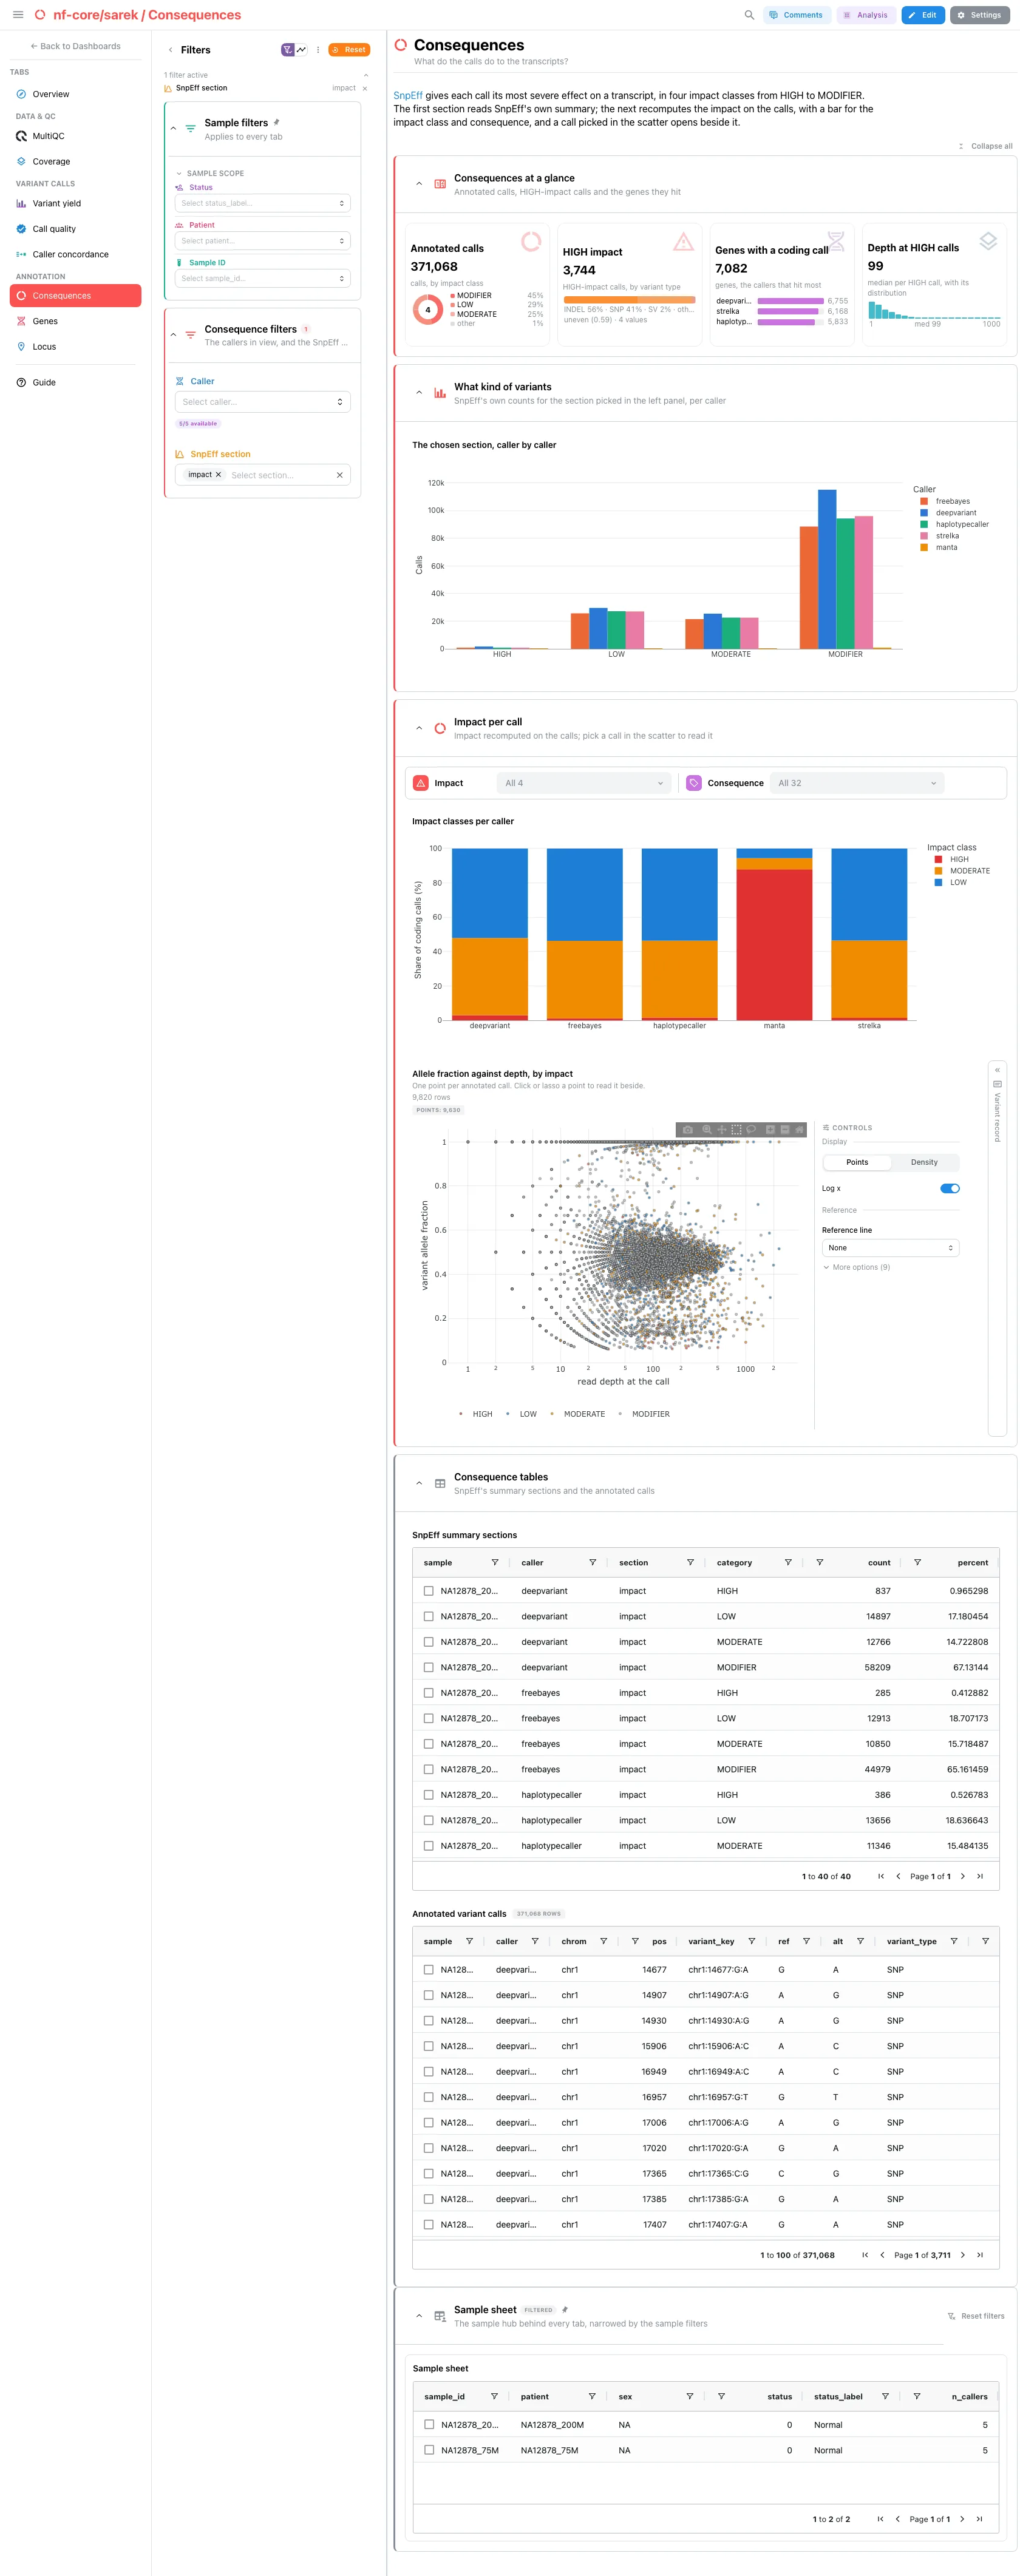
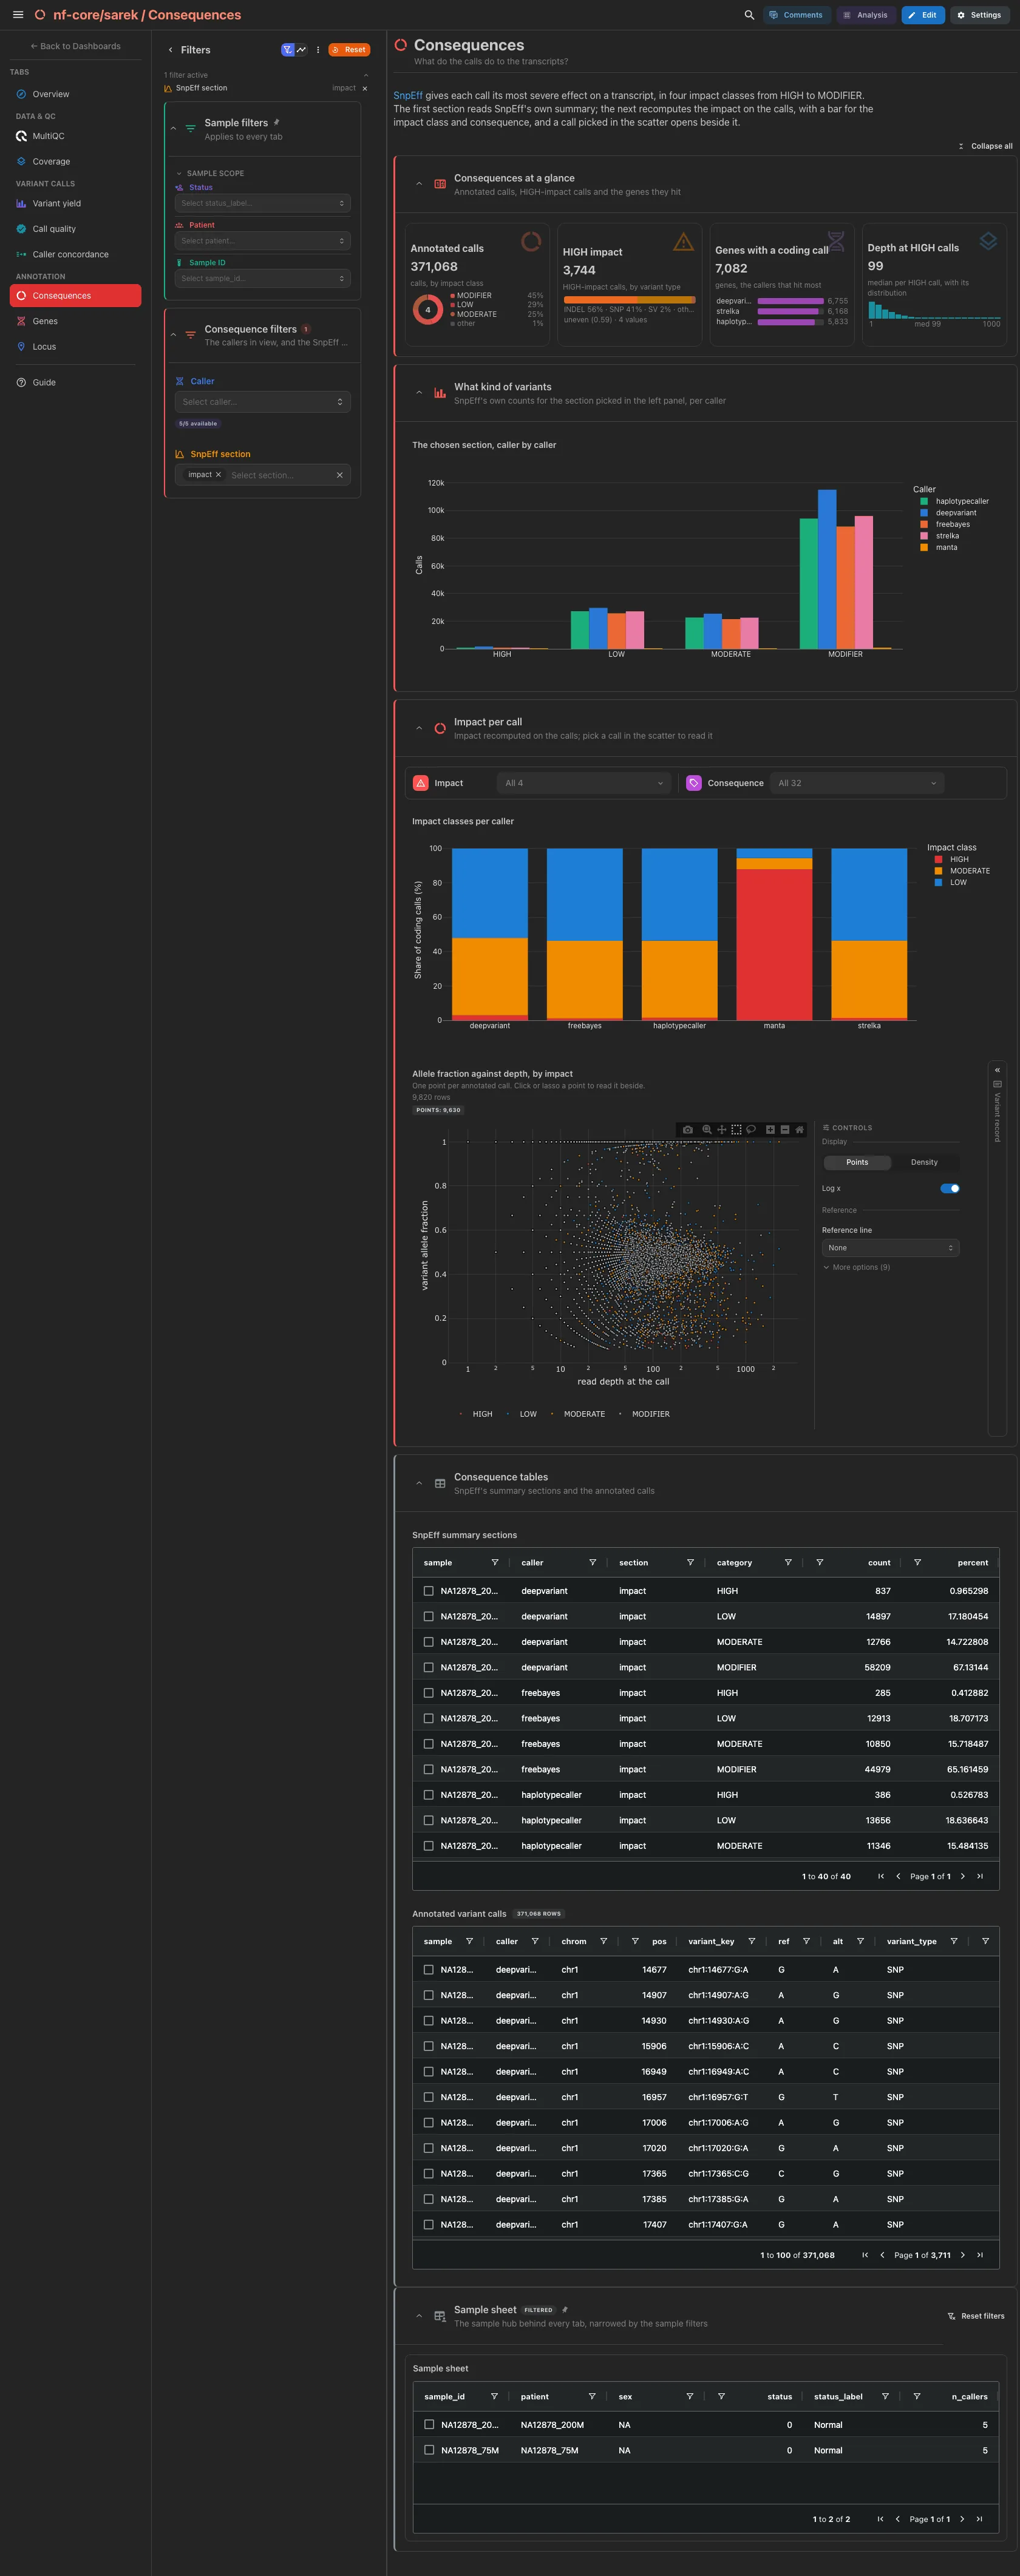
SnpEff gives each call its most severe effect on a transcript, in four impact classes. The annotated calls by impact class, the HIGH-impact calls by variant type, the genes with a HIGH or MODERATE call and the depth at HIGH-impact calls. Then SnpEff's own counts for the summary section picked in the left panel (opening on impact), caller by caller, and the impact recomputed on the calls: the impact classes per caller as shares (MODIFIER left out), and the allele fraction against depth scatter coloured by impact, with the record of the picked call beside it. The SnpEff summary and the annotated calls are collapsed.
Filters and components
Filters · Caller on snpeff_ann_variants and SnpEff section on
snpeff_csv_stats. Impact per call has its own bar, Impact class
and Consequence, rather than the left panel, because three cards pin
an impact class.
| Section | What it holds |
|---|---|
| Consequences at a glance | 4 cards |
| What kind of variants | The chosen section, caller by caller |
| Impact per call | Impact classes per caller, then 2 advanced visualizations: the impact scatter and the Variant record, with its own filter bar |
| Consequence tables (collapsed) | SnpEff summary sections, Annotated variant calls |
Annotation · Which genes carry the calls, and which do the callers share?
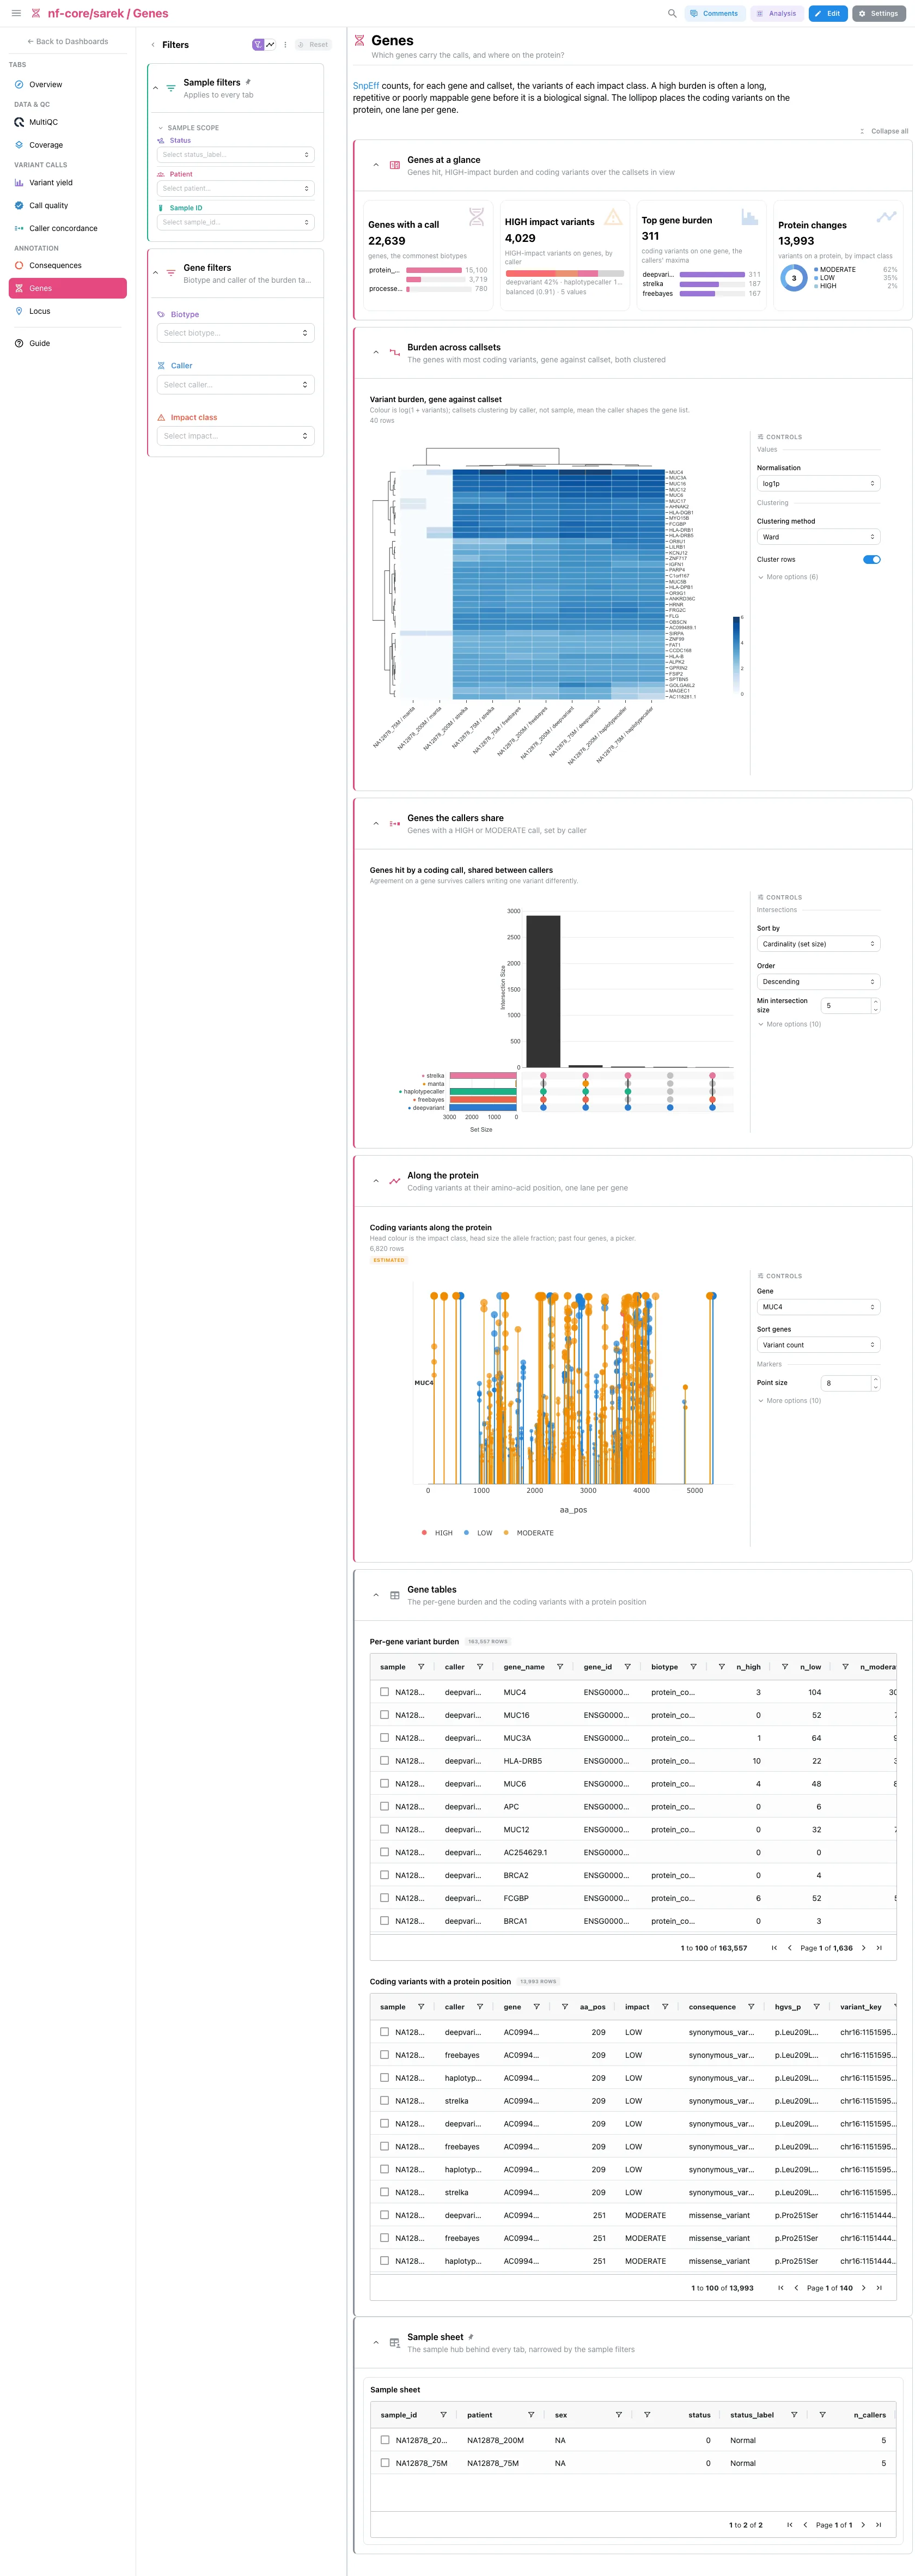
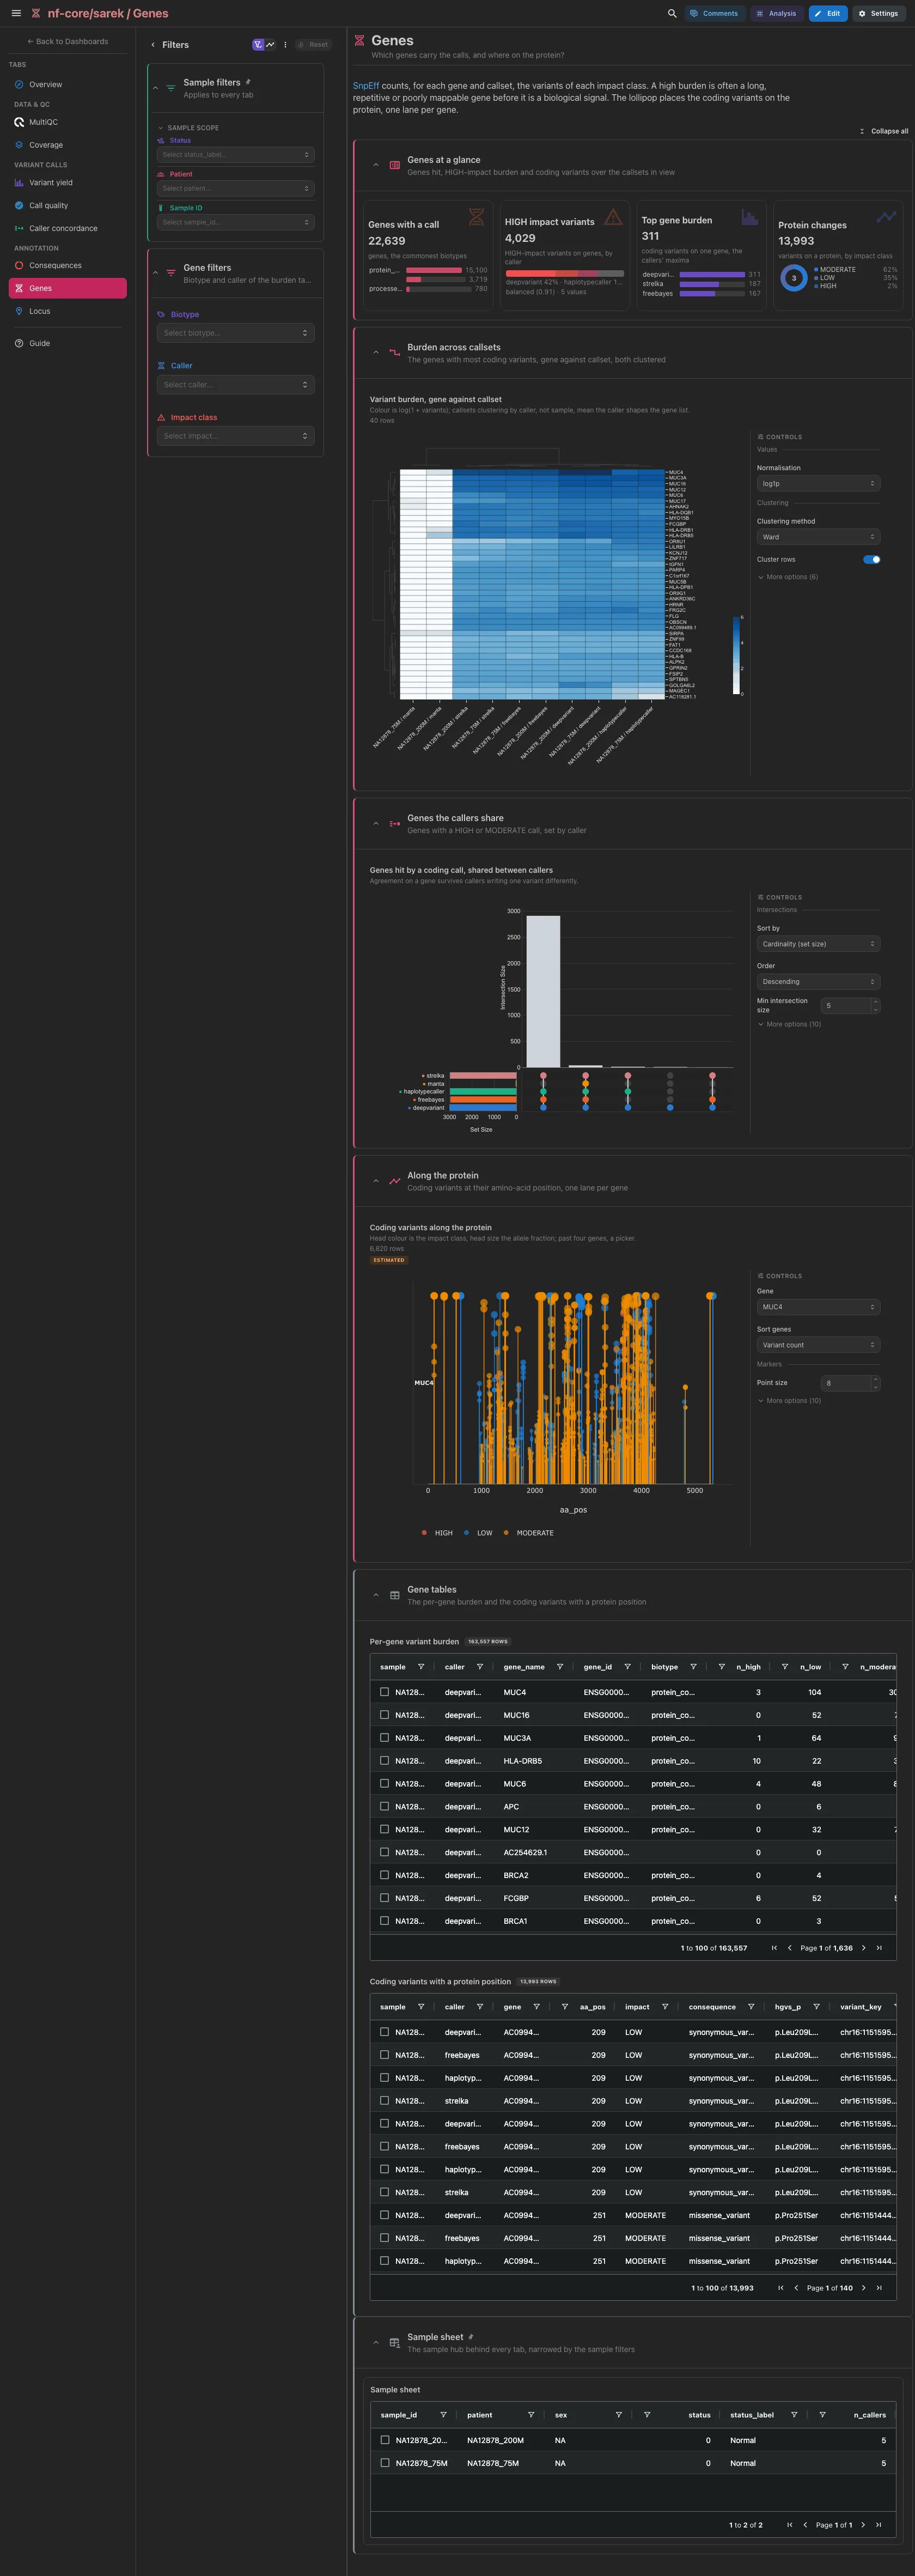
SnpEff's per-gene counts. The genes with a call by biotype, the HIGH-impact variants by caller, the top gene burden (the most HIGH or MODERATE variants on one gene, the callers' maxima) and the protein changes by impact class. Then the gene by callset burden heatmap, coloured by log(1 + variants) so one long gene does not wash out the rest, and the UpSet of genes the callers share (fixed). A high burden is often a long, repetitive or poorly mappable gene before it is a biological signal. The per-gene burden table is collapsed.
Filters and components
Filters · Biotype and Caller on snpeff_genes.
| Section | What it holds |
|---|---|
| Genes at a glance | 4 cards |
| Burden across callsets | 1 advanced visualization |
| Genes the callers share | 1 advanced visualization |
| Gene table (collapsed) | Per-gene variant burden |
Annotation · Where on the protein do the coding variants sit?
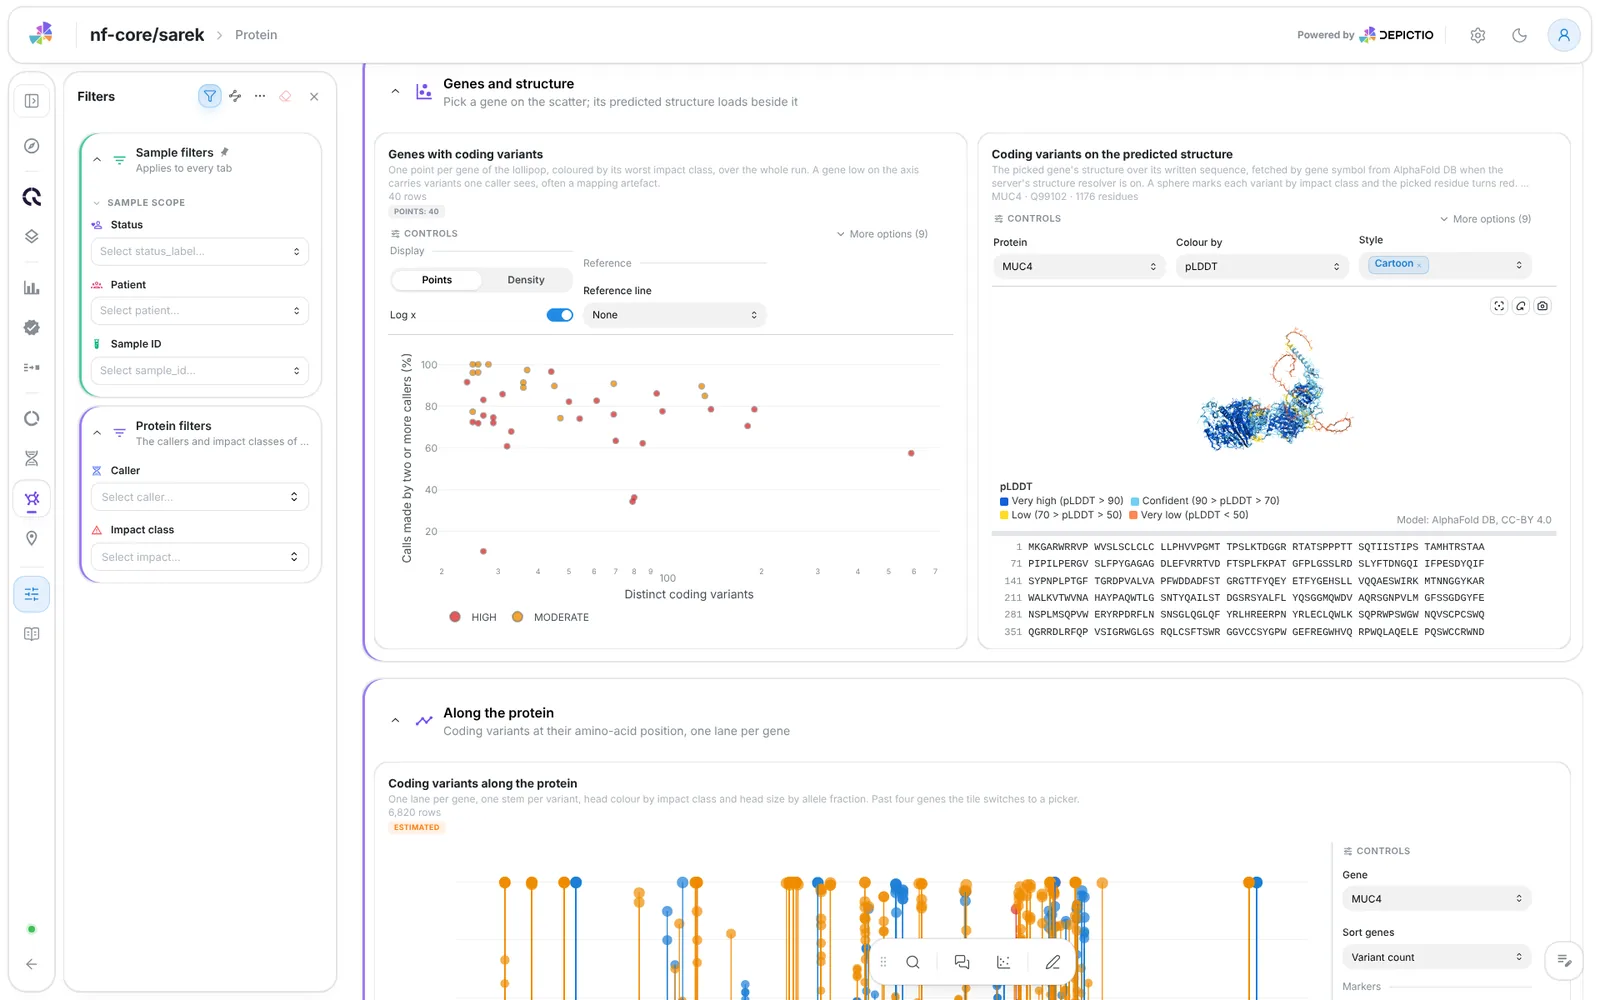
Only variants whose protein change SnpEff could compute appear here. The genes on the protein view (a bar by the worst impact class on each), the coding calls by caller, the median share of a gene's calls that two or more callers made and the allele fraction. Then a scatter of the genes, distinct coding variants on a log axis against the share of calls two or more callers made, coloured by the worst impact class: the gene you pick loads its predicted structure beside it, over its written sequence, with the same variants as spheres on their residues, coloured by impact class. Then the lollipop, one lane per gene, narrowed to the picked gene. The coding variants with a protein position are collapsed. A gene low on the scatter carries variants one caller sees, which is often a mapping or repeat artefact.
Filters and components
Filters · Caller and Impact class on snpeff_protein_lollipop.
The scatter and two of the cards read a per-gene summary of the whole run,
so the sample and caller pickers do not narrow them; a gene picked on the
scatter does.
| Section | What it holds |
|---|---|
| Protein at a glance | 4 cards |
| Genes and structure | 2 advanced visualizations: the gene scatter and the coding variants on the predicted structure |
| Along the protein | 1 advanced visualization |
| Coding variant table (collapsed) | Coding variants with a protein position |
Structure resolver
The structure tile looks the gene up in AlphaFold DB, which needs the structure resolver on the server; without it the tile says so and the rest of the tab works.
Annotation · What do depth and calls show at one region?
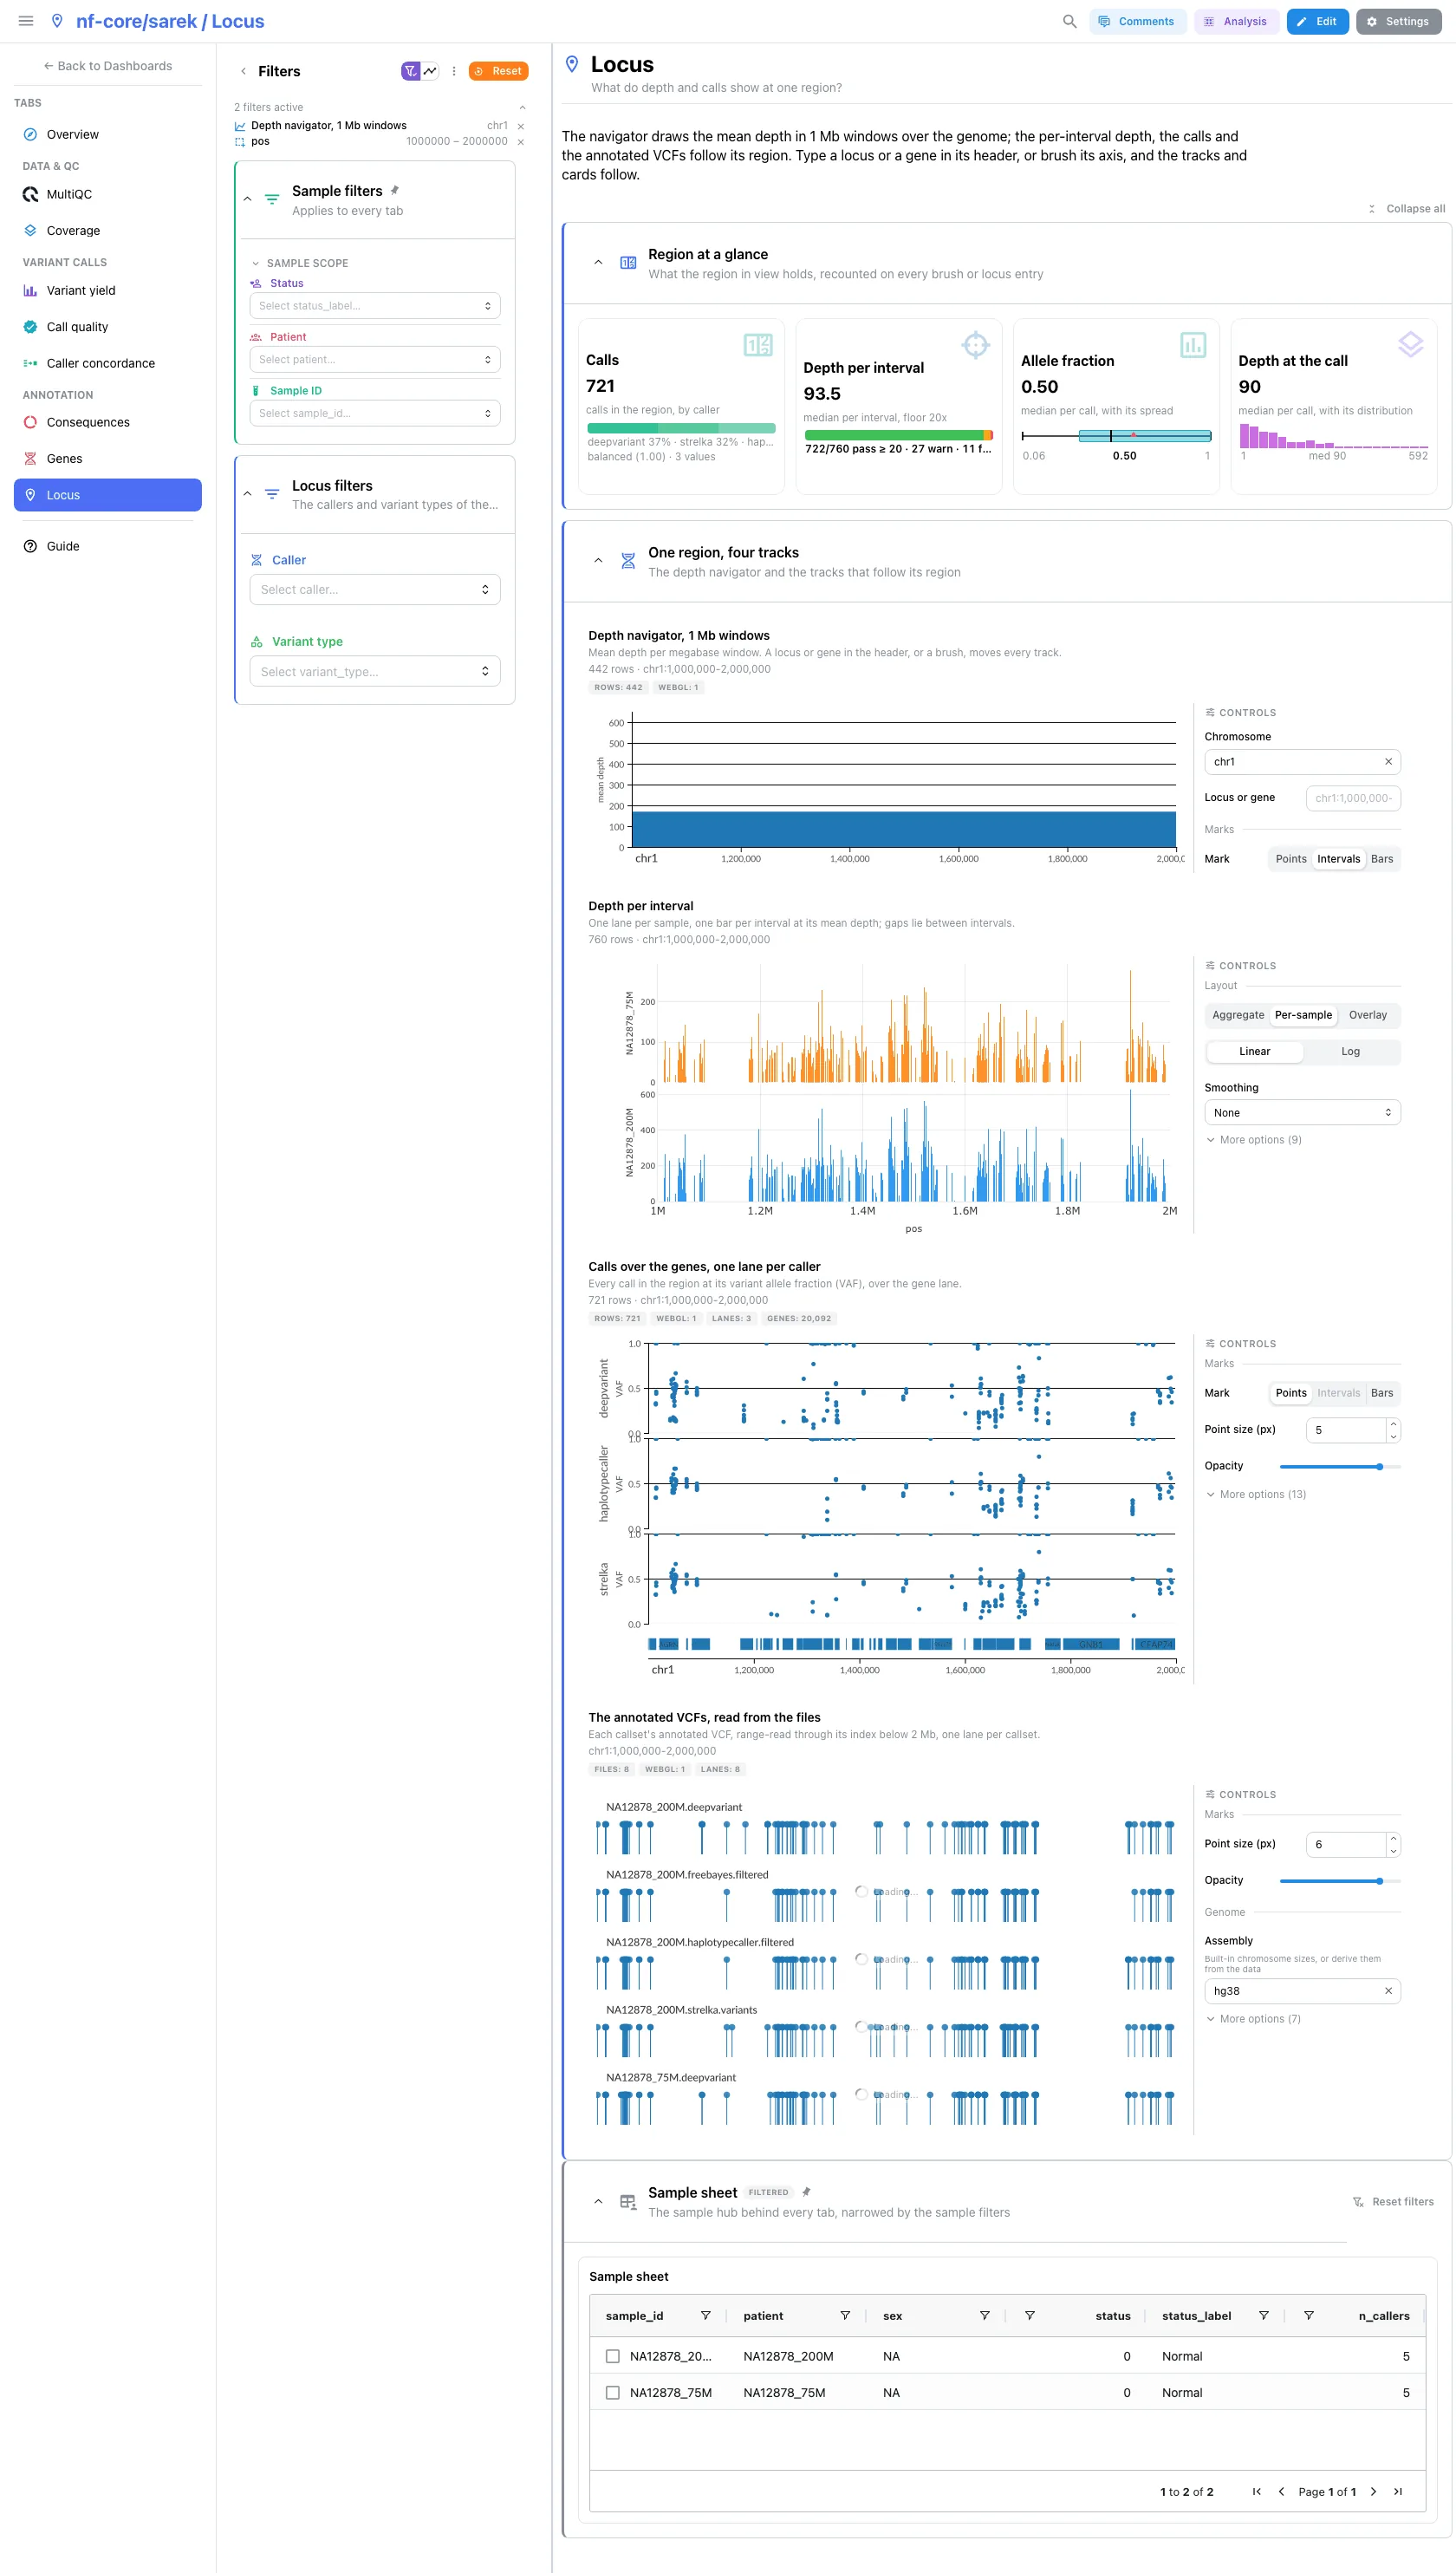
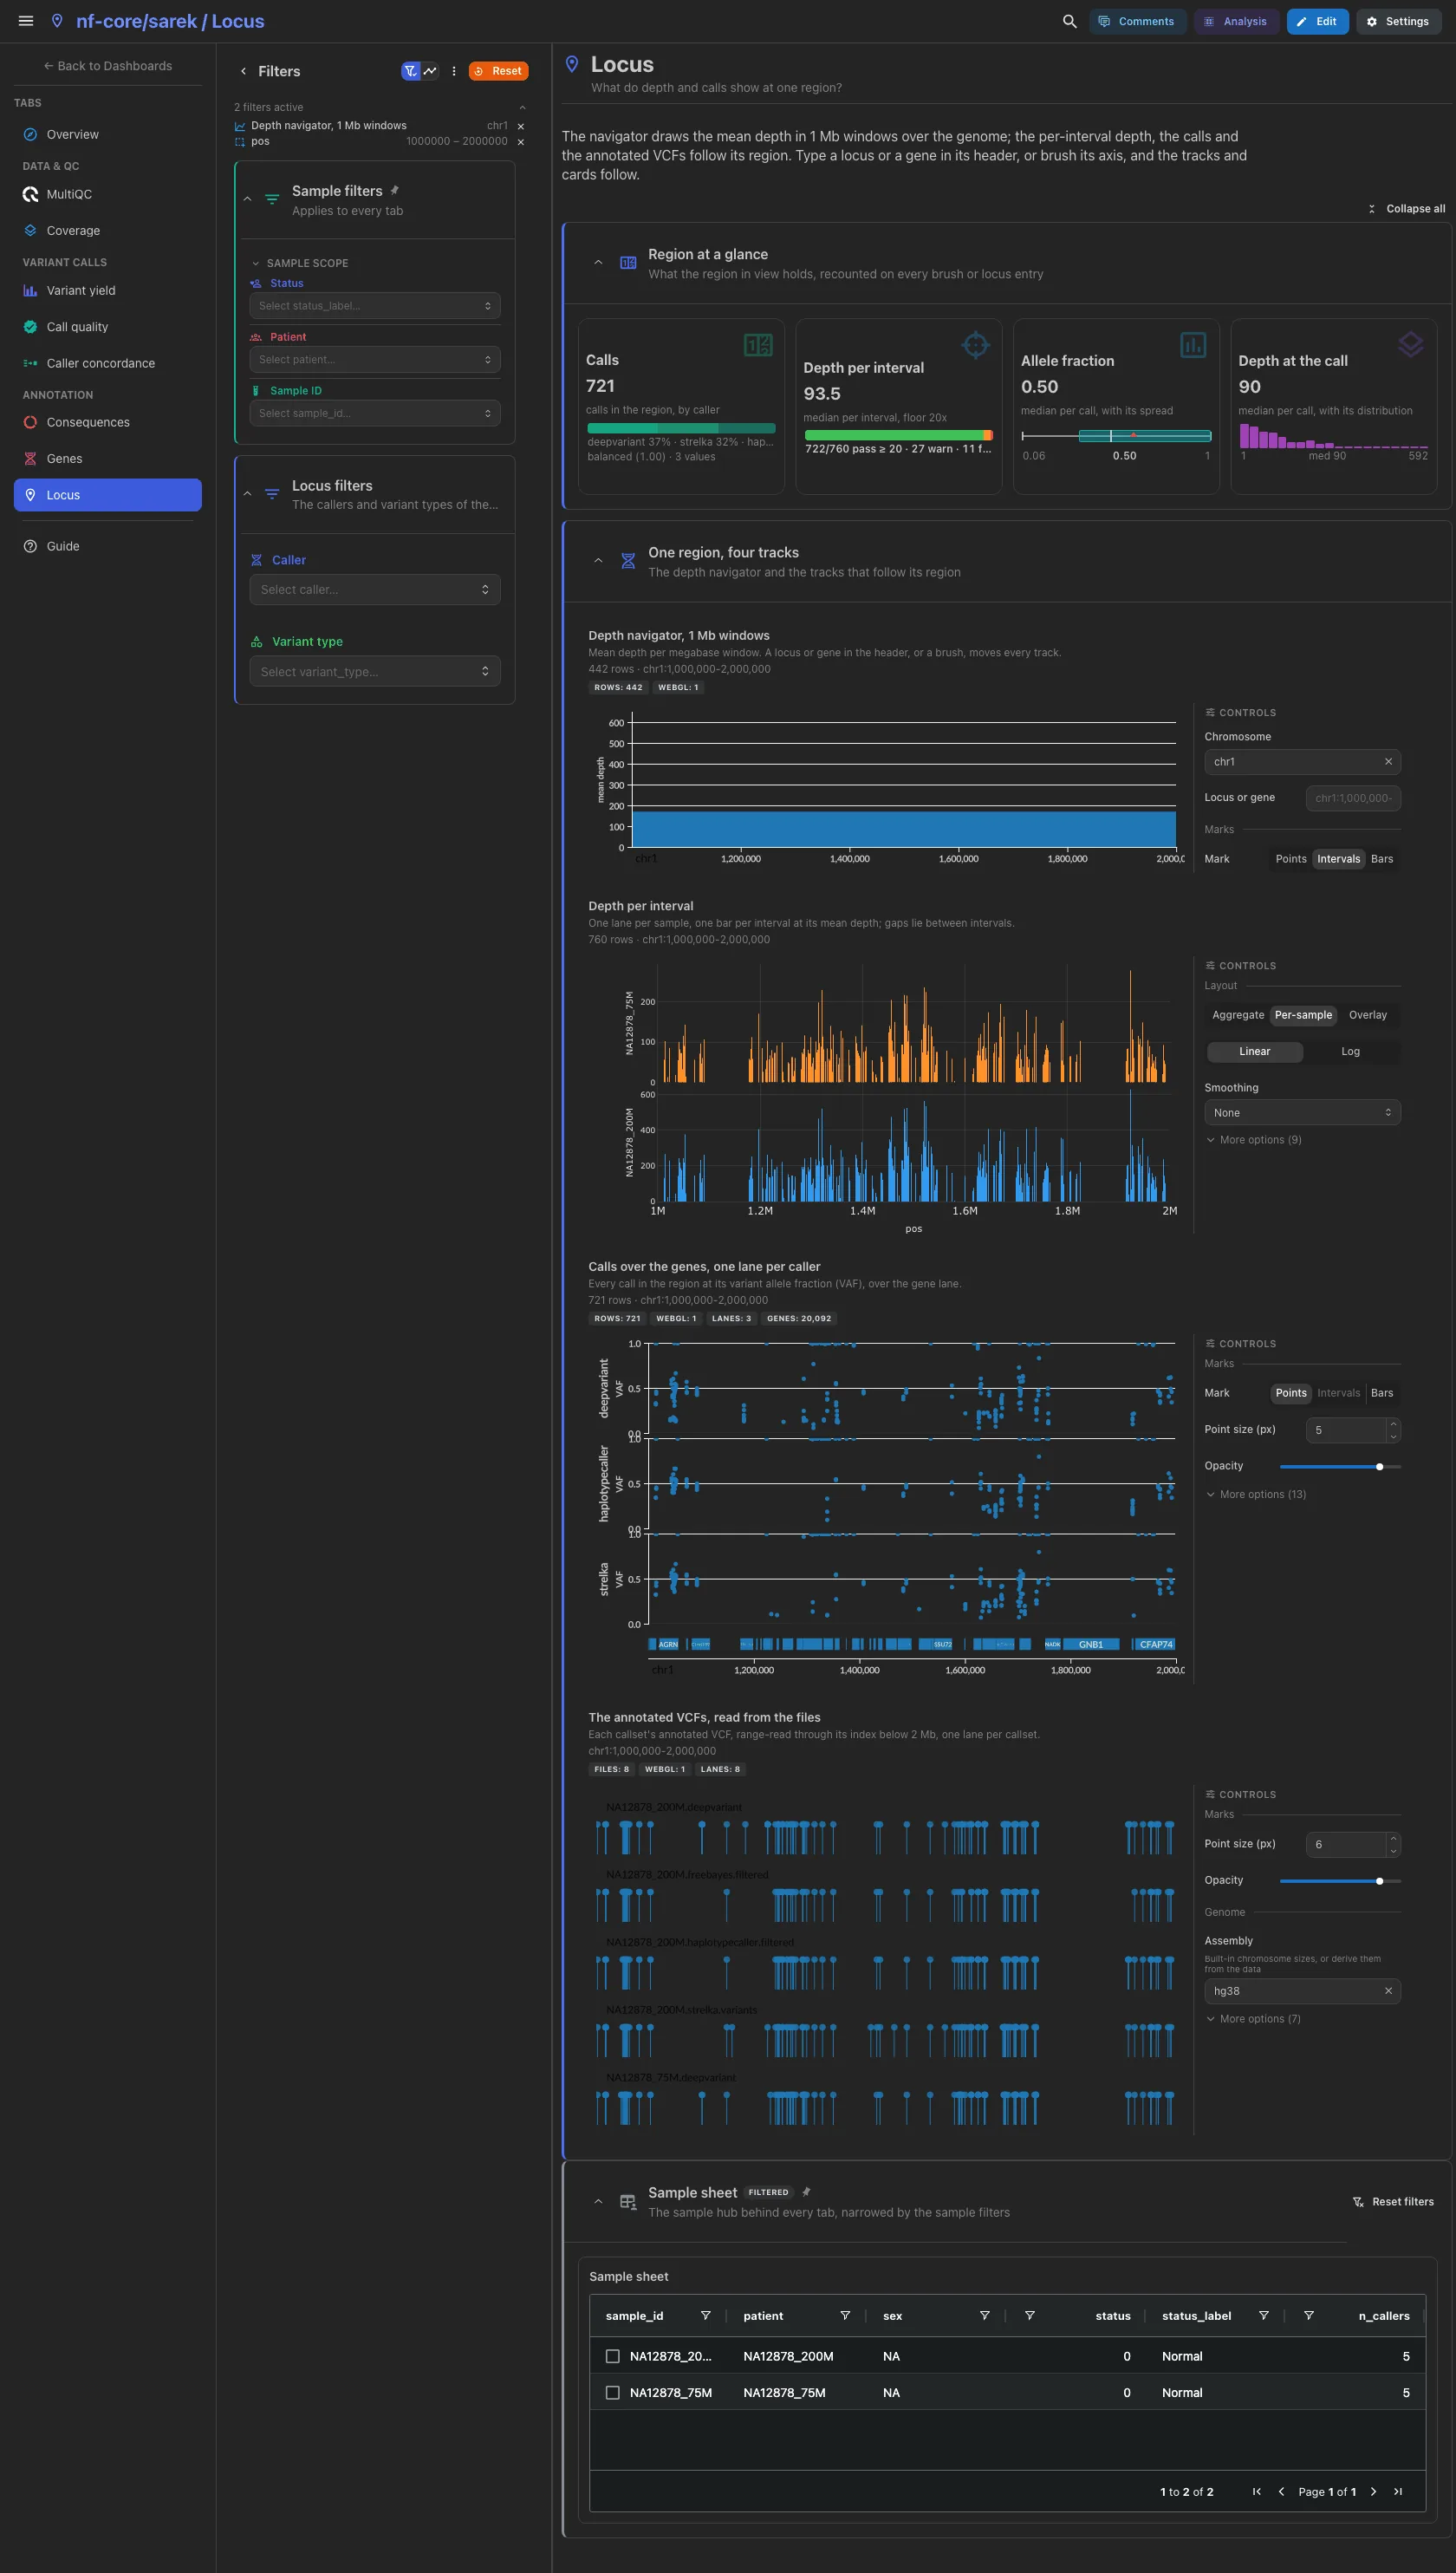
The locus tab stacks four tracks on one {GENOME} axis. The depth navigator,
the mean depth in 1 Mb windows, drives the others: a typed locus or gene, or a
brush on its axis, moves the depth per interval, the calls over the gene lane
(one lane per caller) and the annotated VCFs, range-read from their files
below 2 Mb. It opens on chr1:1,000,000-2,000,000. The four cards (calls by
caller, depth per interval, allele fraction, depth at the call) are recounted
on the region in view.
Filters and components
Filters · Caller and Variant type on vcf_variants, for the call
track and the cards.
| Section | What it holds |
|---|---|
| Region at a glance | 4 cards |
| One region, four tracks | 4 advanced visualizations: the depth navigator, the depth per interval, the calls over the genes and the annotated VCFs |
Tables and point views select on their entity column: the sample sheet on
sample_id; the contig, sex-check, FILTER and distribution tables and the
sex-check scatter on sample; the bcftools and SnpEff summary tables on
caller; the rainfall plot, the impact scatter and the call tables on
variant_key; the per-gene table on gene_name, which reaches the protein
lollipop, and the gene scatter on Protein on gene, which moves the structure and
the lollipop to that gene. A pick narrows the other tiles of its collection and follows the
project links to the collections downstream of it. The variant record on
Consequences shows the call picked in the scatter beside it.
Running the pipeline
Depictio reads the output of nf-core/sarek, it does not run the pipeline. Run the pipeline first, with the callers you want to compare and SnpEff among the tools:
nextflow run nf-core/sarek -r 3.11.0 \
  --input samplesheet.csv \
  --genome GATK.GRCh38 \
  --tools haplotypecaller,deepvariant,strelka,freebayes,manta,snpeff \
  --outdir results -profile docker
Then point Depictio at the results. sarek 3.11.0 ships a MultiQC parquet, so no reprocess step is needed:
See nf-co.re/sarek/usage for full pipeline documentation.
Required data structure
Point depictio ingest at the directory holding the pipeline output. Depictio scans
recursively and matches on file name; the caller and sample directories under
reports/, variant_calling/ and annotation/ are read off the path.
<DATA_ROOT>/
├── csv/*.csv                                  # the hub: sarek's resume manifests
├── pipeline_info/
│   ├── params_*.json
│   └── *software*versions*.yml
├── multiqc/multiqc_data/multiqc.parquet       # native, no reprocess
├── reports/
│   ├── bcftools/<caller>/<sample>/*.bcftools_stats.txt
│   ├── vcftools/<caller>/<sample>/*.{TsTv.qual,FILTER.summary}   # optional
│   ├── mosdepth/<sample>/*.{mosdepth.summary.txt,regions.bed.gz}
│   └── snpeff/<caller>/<sample>/*_snpEff.{csv,genes.txt}         # optional
├── variant_calling/<caller>/<sample>/*.vcf.gz # one VCF per sample and caller
└── annotation/<caller>/<sample>/
    └── *_snpEff.ann.vcf.gz{,.tbi}             # optional; the index feeds the locus track
gVCFs are not read. The somatic outputs (ASCAT, CNVkit, MSIsensor-pro, NGSCheckMate) are declared optional so a somatic run ingests, but no tile binds them yet.
Validation runs
The template was validated against the AWS megatest of the 3.10.0 release,
results-8ccac7ad37b05dd792447763bf9671b719824587, on its
test_full_germline_ncbench_agilent/ profile: one NA12878 exome sequenced at two
depths, five germline callers (DeepVariant, FreeBayes, HaplotypeCaller, Manta,
Strelka) and both annotators. The screenshots above come from that run. The 3.11.0
release publishes a run folder of the same layout, and a bump check against it
found every path the template reads unchanged. megatest.yaml lists the tables-only subset the template needs, plus the
per-caller VCFs and their SnpEff twins:
bash depictio/projects/nf-core/sarek/3.11.0/download_test_data.sh /tmp/sarek_test
depictio ingest /tmp/sarek_test --template nf-core/sarek/latest
Do not pass --project when ingesting: the dashboard is attached to the
project by name, so renaming it breaks a later depictio dashboard import.
Re-ingesting accumulates dashboards, so delete the project before repeating a run.
Additional resources
- nf-co.re/sarek: official pipeline documentation
- nf-co.re/sarek/3.11.0/results: AWS test results
- Template System Reference: YAML format, variables, conditionals
- Recipes: how to read, test, and write recipes
Authorship
 weber8thomas
Reviewing a template on your own data, or taking over a role here, is a contribution in itself: the contributing guide says what each one involves.