The rnasplice template follows an nf-core/rnasplice run from the reads to the splicing calls of up to five tests:
- Overview: the run in four key figures, live findings and four figures, each linked to the tab that explains it
- Data & QC: the MultiQC report (FastQC, Trim Galore, STAR, samtools, featureCounts and Salmon), and whether the replicates of each condition sit together on their Salmon expression
- Splicing: where the five tests agree per gene, then exon usage (DEXSeq, edgeR), transcript usage (DEXSeq DTU) and local events (rMATS, SUPPA2)
Two persistent filter sections sit in the left panel: Sample filters (the
group, then the sample) apply to every tab, and Splicing filters (one contrast,
then genes) to every splicing tab. The contrast sheet is linked to every
splicing collection, so one contrast pick scopes every splicing tab.
MultiQC 1.18 writes no parquet
rnasplice 1.0.4 pins MultiQC 1.18, and Depictio reads only
multiqc.parquet (MultiQC 1.31 and later). Rebuild it from the tool outputs
before ingesting:
One sign for every tool, every tool optional
Effects are oriented treatment minus control across all five tools, so a contrast and its mirror give mirrored effects; rnasplice often lists both, so pick one. A run that skips a tool drops its collection, and with it the tool's cards, figures, filters, Overview row and figure; a tab left without data is dropped. The cross-tool gene table is always built, so Tool Agreement stays, and its UpSet shows an empty set for the skipped tool.
Quick start
The results directory is the only thing you have to pass: the validated sample sheet
always carries condition, which GROUP_COL defaults to. Add a design table
with more factors, name the assembly the event loci link to in UCSC, or read
the pseudo-alignment route:
depictio config nextflow --install     # once per machine
nextflow run nf-core/rnasplice -r 1.0.4 -profile docker --outdir results
No depictio ingest, and no template named: the pipeline ingests its own
output directory when it finishes and resolves this template from its own
manifest. See Nextflow trigger.
The calls are thresholded by variables with generic defaults: SPLICING_FDR
(0.05) on every tool's adjusted p-value, SUPPA2's empirical p-value included,
MIN_DPSI (0.1) on the PSI change of rMATS and SUPPA2 events, and
RMATS_MIN_READS (10) mean junction reads per replicate an rMATS event needs in
both conditions.
Reference
The template reads the MultiQC report, the validated sample and contrast sheets,
the merged Salmon gene TPMs and the result tables of the five splicing tools. A
pipeline-local splicing_genes recipe joins the tools into one row per gene,
linked on gene_id to every tool collection, so the Gene filter of the left
panel and the agreement filter of Tool Agreement reach the per-tool tabs. 42 of
its 62 tiles carry a use: catalog reference, so a tile says where its panel
comes from.
Self-adapting layout
The dashboard adapts to whatever the run actually produced: components bound to pruned or unparsed data collections are hidden, tabs left with no real visualizations are dropped entirely, and the remaining components are re-packed so there are no empty rows.
Template variables
Variables you provide when running the template: DATA_ROOT is the results directory given to depictio ingest, the others are set with --var NAME=value:
| Variable | Required | Description |
|---|---|---|
DATA_ROOT |
✓ | Root directory of one rnasplice run (multiqc/, pipeline_info/, contrastsheet/, star_salmon/ and/or salmon/) |
METADATA_FILE |
— | Optional design table (TSV or CSV): sample id in the first column, one column per factor. Adds the design factors to the sample hub and colours the sample space; pruned when absent. |
METADATA_ID_COL |
— | Design-table sample id column (links join on it). Auto-detected as the first column; defaults to 'sample'. |
GROUP_COL |
— | Design column the group filter, cards and colouring read. Auto-detected as the first annotation column of METADATA_FILE, else the sample sheet's condition. |
GROUP_COL_DISPLAY |
— | Title-cased GROUP_COL for display; auto-populated with METADATA_FILE. |
QUANT_ROUTE |
— | Quantification route the expression, DEXSeq DTU and SUPPA2 collections read: star_salmon (default) or salmon (pseudo-alignment). |
GENOME |
— | UCSC assembly name the event loci link out to (the genome the run aligned to). |
SPLICING_FDR |
— | Significance cut-off on the adjusted p-values of every splicing tool (SUPPA2: its empirical p-value). |
MIN_DPSI |
— | Minimal absolute change in percent spliced-in (0 to 1) for an rMATS or SUPPA2 event to be called. |
RMATS_MIN_READS |
— | Mean junction reads per replicate an rMATS event needs in both conditions to be kept. |
Data collections
13 data collections — 6 required 7 optional · 10 direct 3 derived.
Origin tells you whether a collection is real pipeline data or a reshape of it: direct = a pipeline output (scanned, or a recipe that reads raw files); derived = a recipe that reshapes one or more direct collections into the layout a visualization needs (no new measurement). Reads shows what produces it: a recipe .py transform, whose name links to its source on GitHub, or a raw file scanned off disk. (A direct collection can still have a recipe — one that merely parses/cleans the raw file; derived means the recipe reshapes another collection.)
| Tag | Origin | Type | Reads | Status |
|---|---|---|---|---|
multiqc_data |
direct |  MultiQC |
file (?:.*/)?multiqc(?:/[^/]+)?/multiqc(?:_report)?_data/multiqc.parquet$ |
required |
metadata |
direct | Table | file {METADATA_FILE} |
optional |
samples |
derived | Table | recipe nf-core/rnasplice/samples.py |
required |
contrasts |
direct | Table | file contrastsheet.valid.csv$ |
required |
sample_pca |
direct | Table | recipe salmon/sample_pca.py |
required |
expression_heatmap |
direct | Table | recipe salmon/top_variable_genes.py |
required |
dexseq_exon_genes |
direct | Table | recipe dexseq/exon_genes.py |
optional |
edger_genes |
direct | Table | recipe edger/diffsplice_genes.py |
optional |
dexseq_dtu |
direct | Table | recipe dexseq/dtu.py |
optional |
rmats_events |
direct | Table | recipe rmats/events.py |
optional |
event_junctions |
derived | Table | recipe nf-core/rnasplice/event_junctions.py |
optional |
suppa_events |
direct | Table | recipe suppa/local_events.py |
optional |
splicing_genes |
derived | Table | recipe nf-core/rnasplice/splicing_genes.py |
required |
Conditional routes
Rows are data collections; columns are the variables you set or params.json flags auto-detected from the run. Each filled cell is the effect of setting that variable; an empty cell means that variable leaves the collection unchanged. (12 collections are unaffected by any variable — present on every run.)
+ included− removed⇄ repointed
| Data collection | METADATA_FILE |
|---|---|
metadata |
+ |
Cross-DC links
17 links — selecting a value in the source collection filters the target. The join column is shown after the source.
| Source · column | Target | Filters | |
|---|---|---|---|
samples · sample |
→ | multiqc_data |
Filter the MultiQC panels by sample selection |
samples · sample |
→ | sample_pca |
Filter the sample space by sample selection |
metadata · {METADATA_ID_COL} |
→ | samples |
Filter the sample hub by design-table selection |
metadata · {METADATA_ID_COL} |
→ | multiqc_data |
Filter the MultiQC panels by design-table selection |
metadata · {METADATA_ID_COL} |
→ | sample_pca |
Filter the sample space by design-table selection |
contrasts · contrast |
→ | splicing_genes |
Keep the cross-tool gene table on the picked contrast |
contrasts · contrast |
→ | dexseq_exon_genes |
Keep DEXSeq exon usage on the picked contrast |
contrasts · contrast |
→ | edger_genes |
Keep edgeR diffSpliceDGE on the picked contrast |
contrasts · contrast |
→ | dexseq_dtu |
Keep DEXSeq transcript usage on the picked contrast |
contrasts · contrast |
→ | rmats_events |
Keep the rMATS events on the picked contrast |
contrasts · contrast |
→ | suppa_events |
Keep the SUPPA2 events on the picked contrast |
splicing_genes · gene_id |
→ | dexseq_exon_genes |
Carry the cross-tool gene selection onto DEXSeq exon usage |
splicing_genes · gene_id |
→ | edger_genes |
Carry the cross-tool gene selection onto edgeR diffSpliceDGE |
splicing_genes · gene_id |
→ | dexseq_dtu |
Carry the cross-tool gene selection onto DEXSeq transcript usage |
splicing_genes · gene_id |
→ | rmats_events |
Carry the cross-tool gene selection onto the rMATS events |
splicing_genes · gene_id |
→ | suppa_events |
Carry the cross-tool gene selection onto the SUPPA2 events |
splicing_genes · gene_id |
→ | event_junctions |
Carry the cross-tool gene selection onto the sashimi of the rMATS events |
Recipes
Each recipe reshapes raw pipeline output into a tidy table. The name links to its source; Output lists the validated OUTPUT_SCHEMA columns.
| Recipe | Transforms | Output |
|---|---|---|
dexseq/dtu.py |
DEXSeq differential transcript usage (DTU), one row per contrast and transcript. | contrast, gene_id, transcript_id, base_mean, log2fc, pvalue, padj, neg_log10_padj, gene_padj, significant, gene_significant, direction |
dexseq/exon_genes.py |
DEXSeq differential exon usage, summarised per contrast and gene. | contrast, gene_id, bins_tested, bins_significant, top_bin, log2fc, abs_log2fc, bin_padj, padj, neg_log10_padj, significant, direction |
edger/diffsplice_genes.py |
edgeR diffSpliceDGE differential exon usage, one row per contrast and gene. |
contrast, gene_id, chrom, strand, exons, exons_significant, top_exon, log2fc, abs_log2fc, f_stat, fdr, simes_fdr, neg_log10_fdr, significant, direction |
nf-core/rnasplice/event_junctions.py |
STAR splice junctions around the called rMATS events, per gene and condition. | gene_id, gene_name, condition, chrom, start, end, strand, reads |
nf-core/rnasplice/samples.py |
The nf-core/rnasplice sample hub: one row per sample, every design column. | sample, condition, read_type, strandedness, runs |
nf-core/rnasplice/splicing_genes.py |
Cross-tool differential splicing per gene: which tools call each gene. | contrast, gene_id, gene_name, dexseq_exon, dexseq_dtu, edger, rmats, suppa, tools_tested, tools_significant, tools, dexseq_exon_padj, dexseq_exon_log2fc, dexseq_dtu_padj, edger_fdr, edger_log2fc, rmats_events_significant, rmats_max_abs_dpsi, rmats_min_fdr, suppa_events_significant, suppa_max_abs_dpsi, suppa_min_pvalue |
rmats/events.py |
rMATS differential alternative splicing events, all five event types stacked. | contrast, event_id, event_type, gene_id, gene_name, chrom, strand, start, end, locus, psi_treatment, psi_control, dpsi, abs_dpsi, pvalue, fdr, neg_log10_fdr, reads_treatment, reads_control, significant, direction |
salmon/sample_pca.py |
Sample PCA of a merged Salmon TPM matrix, plus the per-sample library summary. | sample_id, dim_1, dim_2, group, genes_detected, genes_expressed, median_tpm |
salmon/top_variable_genes.py |
Top variable genes of a merged Salmon TPM matrix, for ComplexHeatmap. | gene_name |
suppa/local_events.py |
SUPPA2 differential splicing of local events, one row per contrast and event. | contrast, event_id, event_type, gene_id, chrom, strand, start, end, dpsi, abs_dpsi, pvalue, neg_log10_pvalue, significant, direction |
Dashboard tabs
One dashboard: the Overview, then six child tabs in two groups, read as a funnel from the run to the genes whose splicing changes between conditions. Each tab below carries the same icon and colour the dashboard gives it, so the page and the app read alike.
| Group | Tabs |
|---|---|
| Data & QC | MultiQC, Sample Space |
| Splicing | Tool Agreement, Exon Usage, Transcript Usage, Splicing Events |
Each child tab opens with a short intro and a strip of four cards, then at most three open sections; tables and details follow, collapsed. Two persistent filter sections sit in the left panel: the Sample filters (the group, then the sample) apply to every tab, and the Splicing filters (one contrast, then genes) to every splicing tab, through the contrast and gene links; MultiQC and Sample Space carry no contrast and leave them out. Pick one contrast first: rnasplice often runs a contrast and its mirror, and a gene called in both counts twice. The Sample sheet section (the samples and the contrasts) is pinned, collapsed, to the bottom of every child tab.
Bulk RNA-seq, from reads to the genes whose splicing changes between conditions.
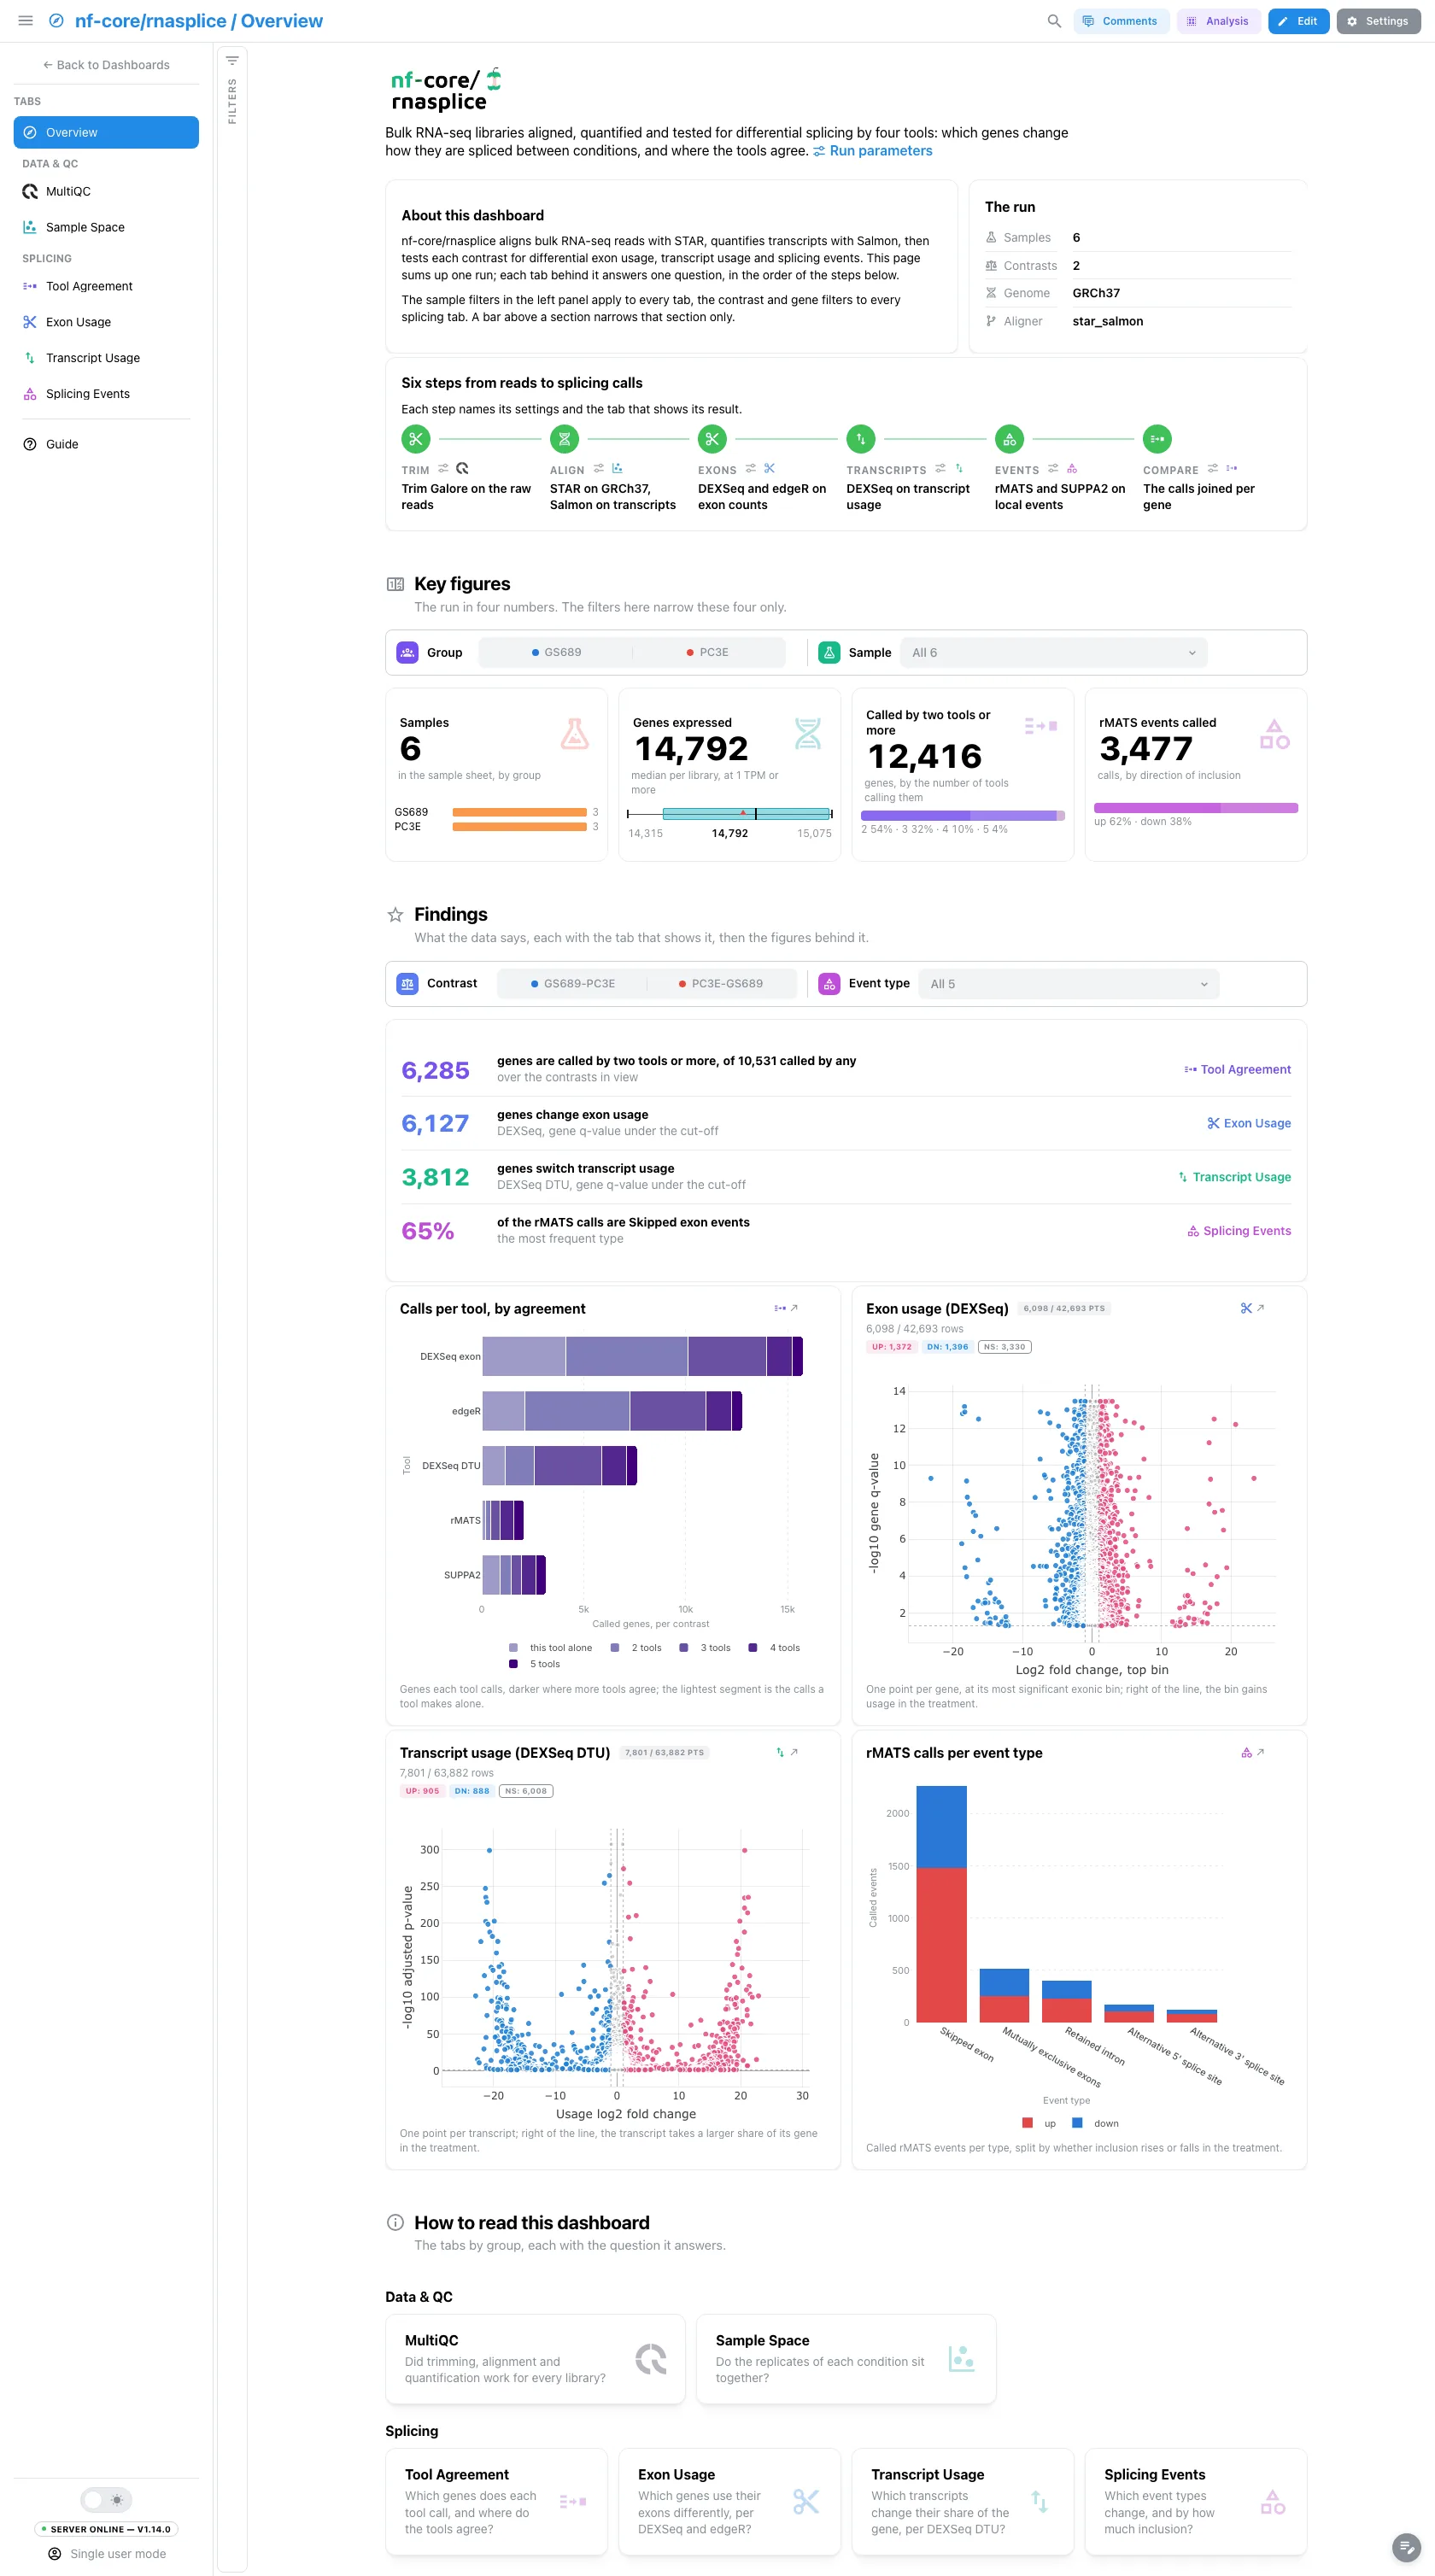
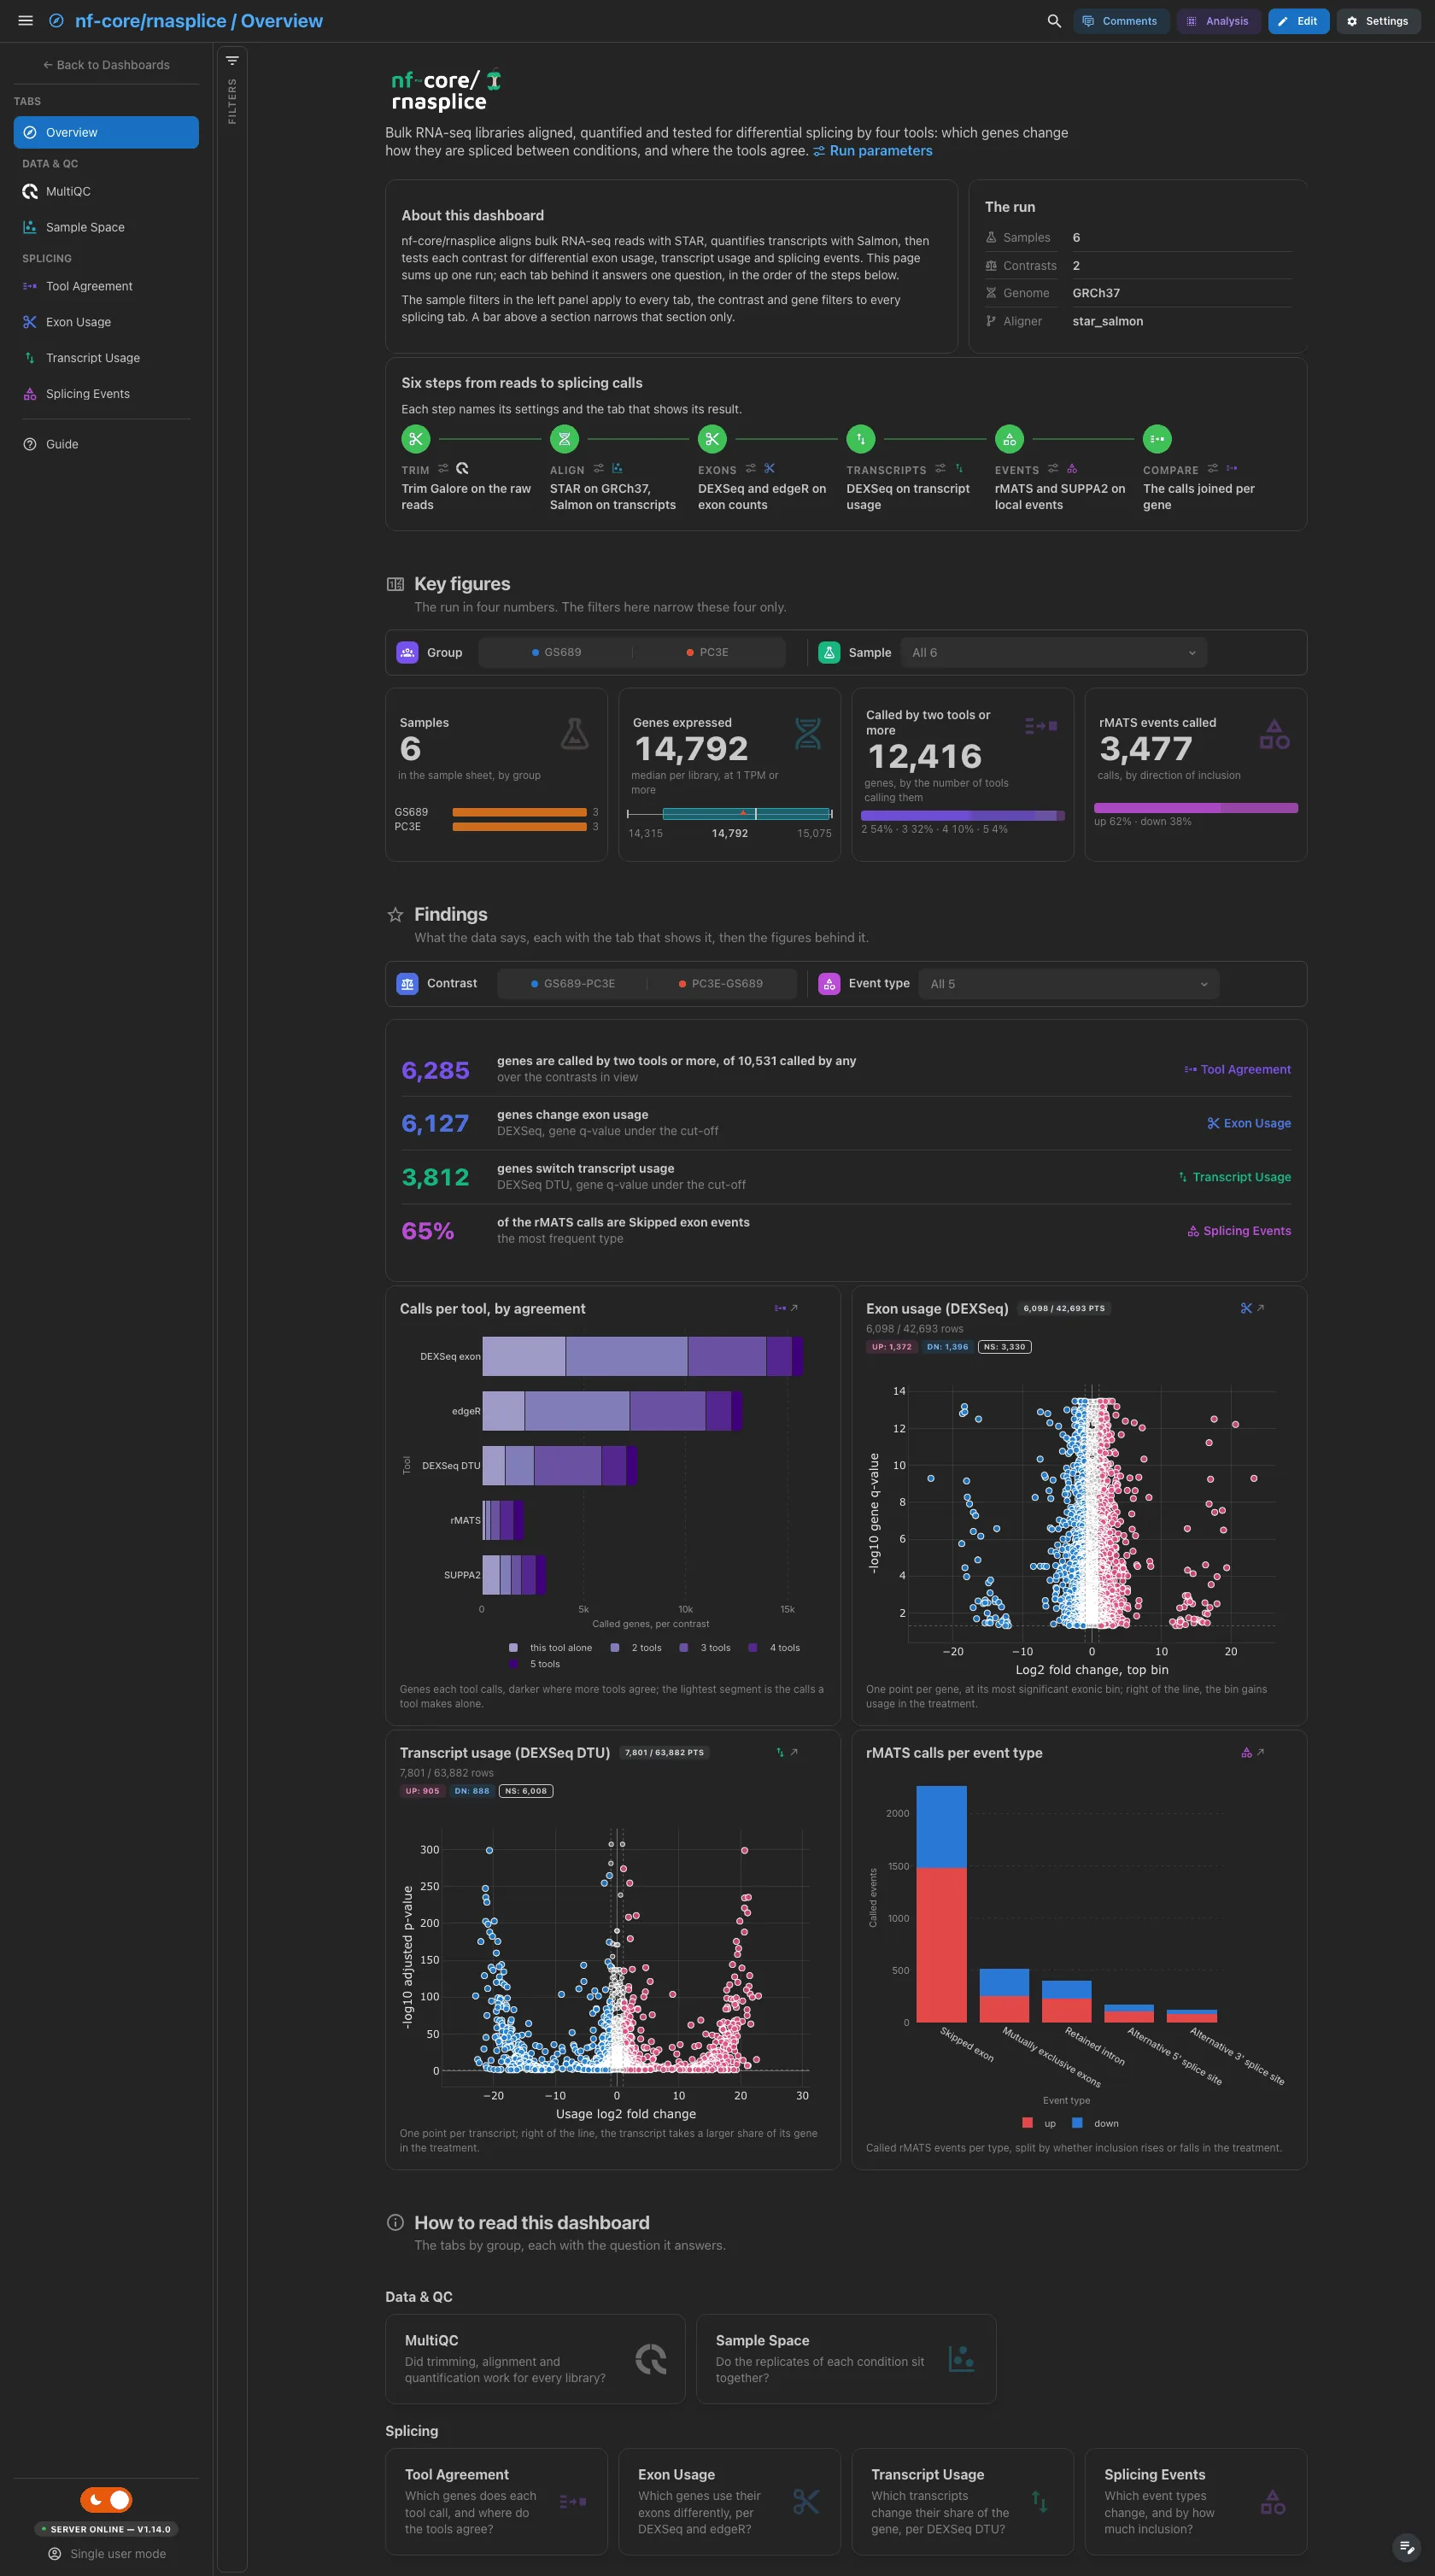
A short hero links the run parameters. About this dashboard says what the dashboard shows and how the filters work, The run lists the samples, the contrasts, the genome and the aligner, and Pipeline walks the six steps from trimming to the cross-tool comparison, each linked to its settings and its tab. The findings are live values: they follow the filters, and a tool the run skipped takes its row and figure with it. The two volcanoes among the figures answer different questions: one point per gene at its most significant exonic bin, against one point per transcript.
Filters and components
Filters · the left panel starts collapsed. Key figures has its own filter bar (the group and the sample), Findings another (the contrast and the rMATS event type): each narrows its own section only. The splicing cards also follow the contrast and gene filters of the left panel.
| Section | What it holds |
|---|---|
| Top | Hero, About this dashboard, The run, Pipeline |
| Key figures | 4 headline cards: samples by group, genes expressed, genes called by two tools or more, rMATS events called |
| Findings | Live result rows, then 4 figures: each tool's calls by agreement, the DEXSeq exon usage volcano, the DEXSeq DTU transcript volcano and the called rMATS events per type |
| How to read this dashboard | The tabs by group, each with its question |
Data & QC · Did trimming, alignment and quantification work for every library?
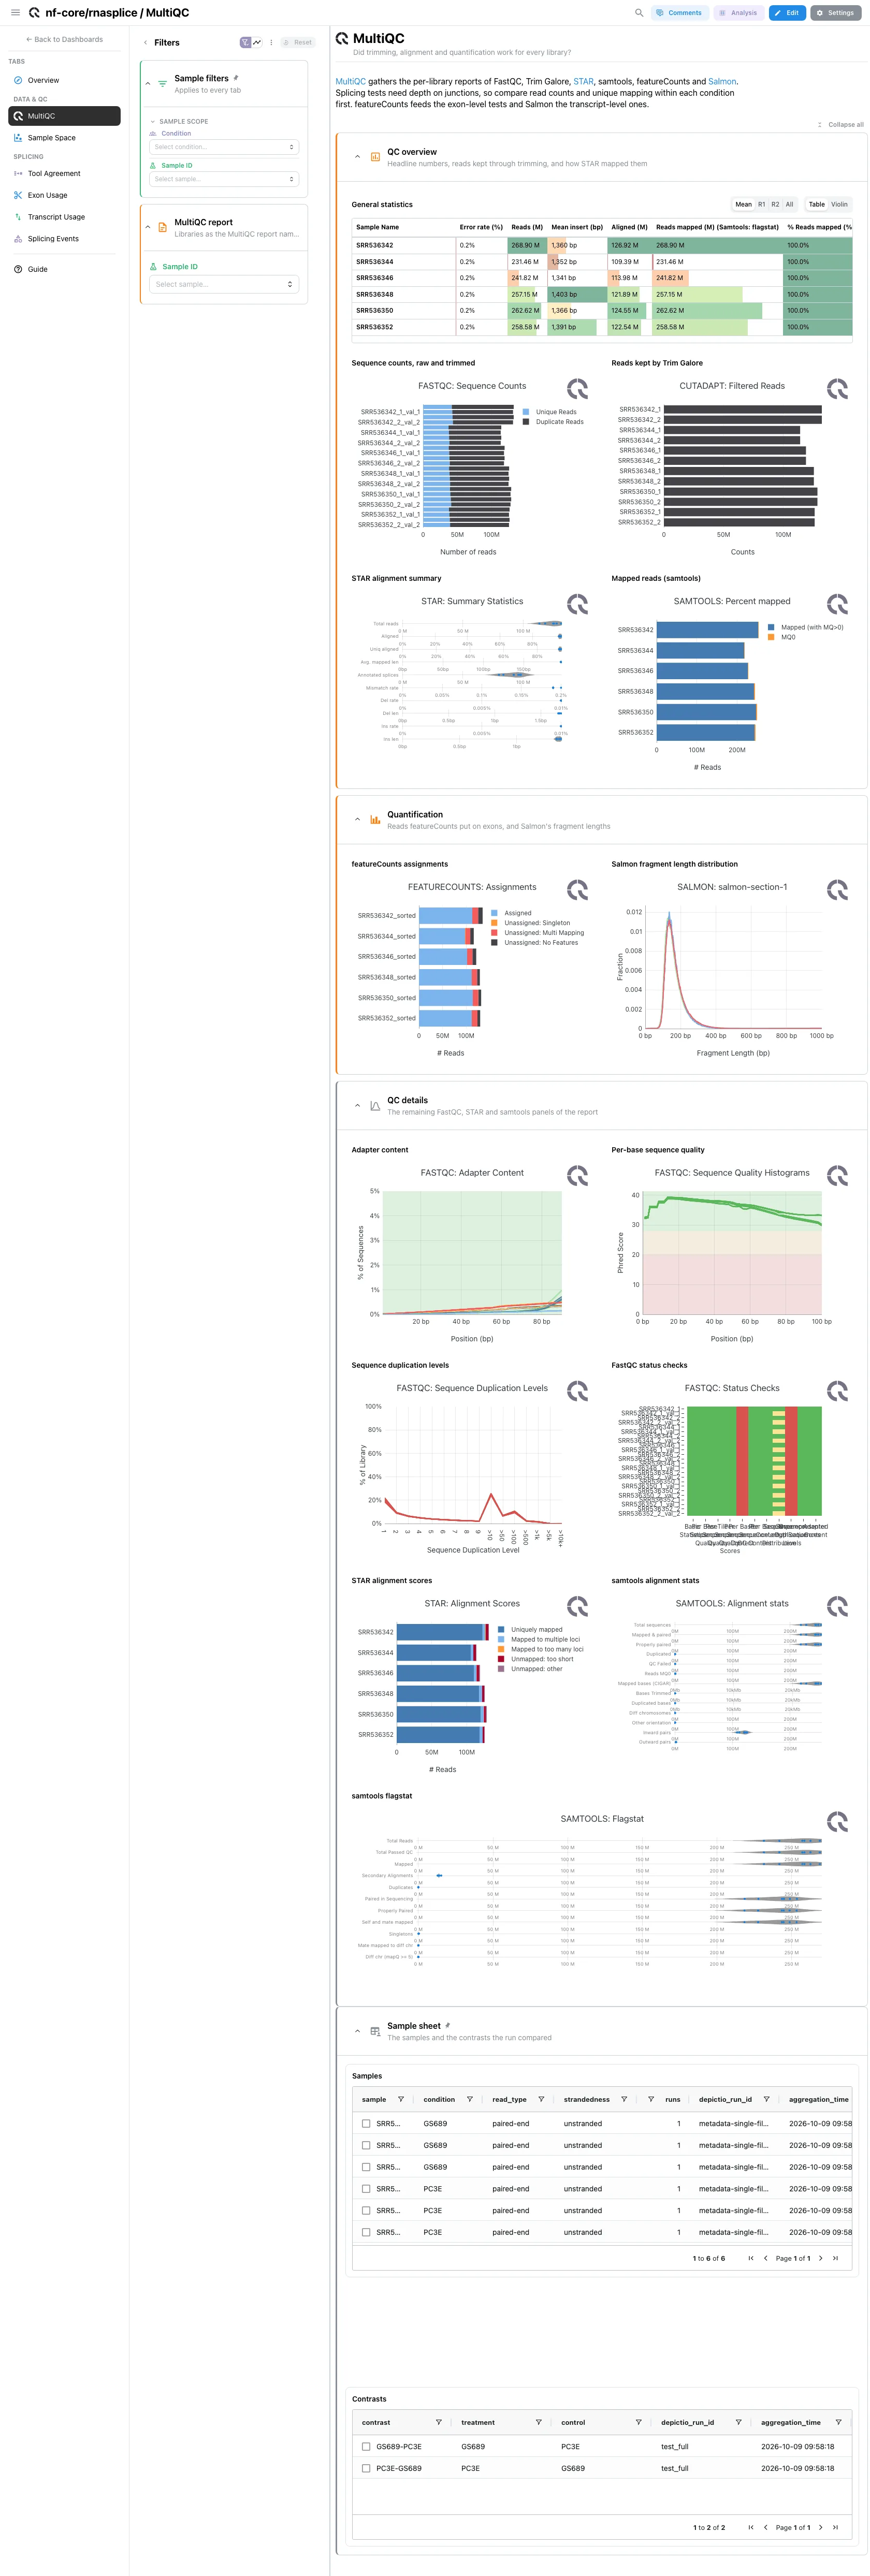
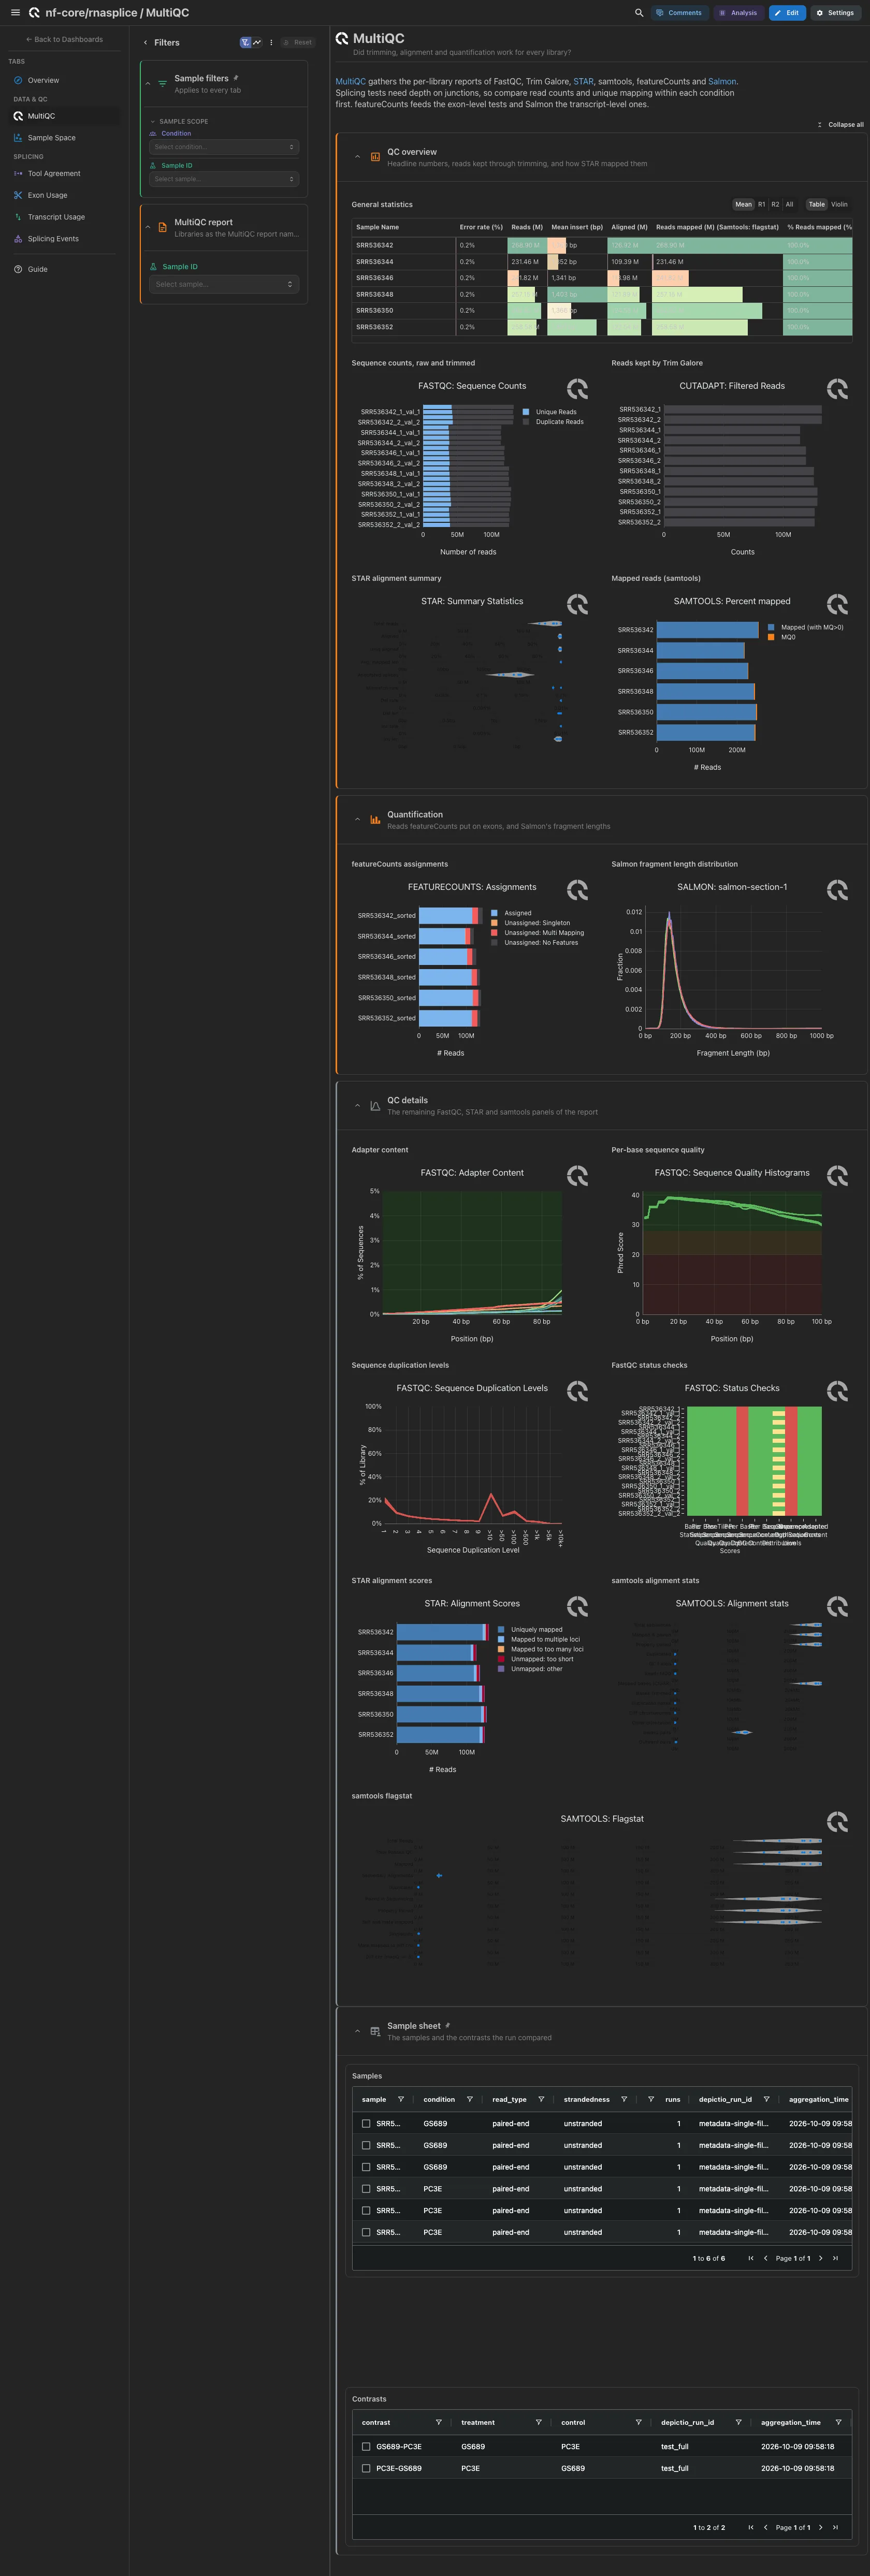
MultiQC panels only, no card strip. Open: general statistics, FastQC sequence counts beside the reads Trim Galore kept, STAR's summary beside samtools' percent mapped, then featureCounts assignments (the exon-level tests' input) beside Salmon's fragment lengths (the transcript-level tests' input). Splicing tests need depth on junctions, so compare read counts and unique mapping within each condition first. FastQC's adapter content, quality, duplication and status, STAR's alignment scores and samtools' stats and flagstat are collapsed.
Filters and components
Filters · Sample ID, read from the MultiQC report, whose library
names carry read suffixes.
| Section | What it holds |
|---|---|
| QC overview | 5 MultiQC panels |
| Quantification | 2 MultiQC panels |
| QC details (collapsed) | 7 MultiQC panels |
Data & QC · Do the replicates of each condition sit together?
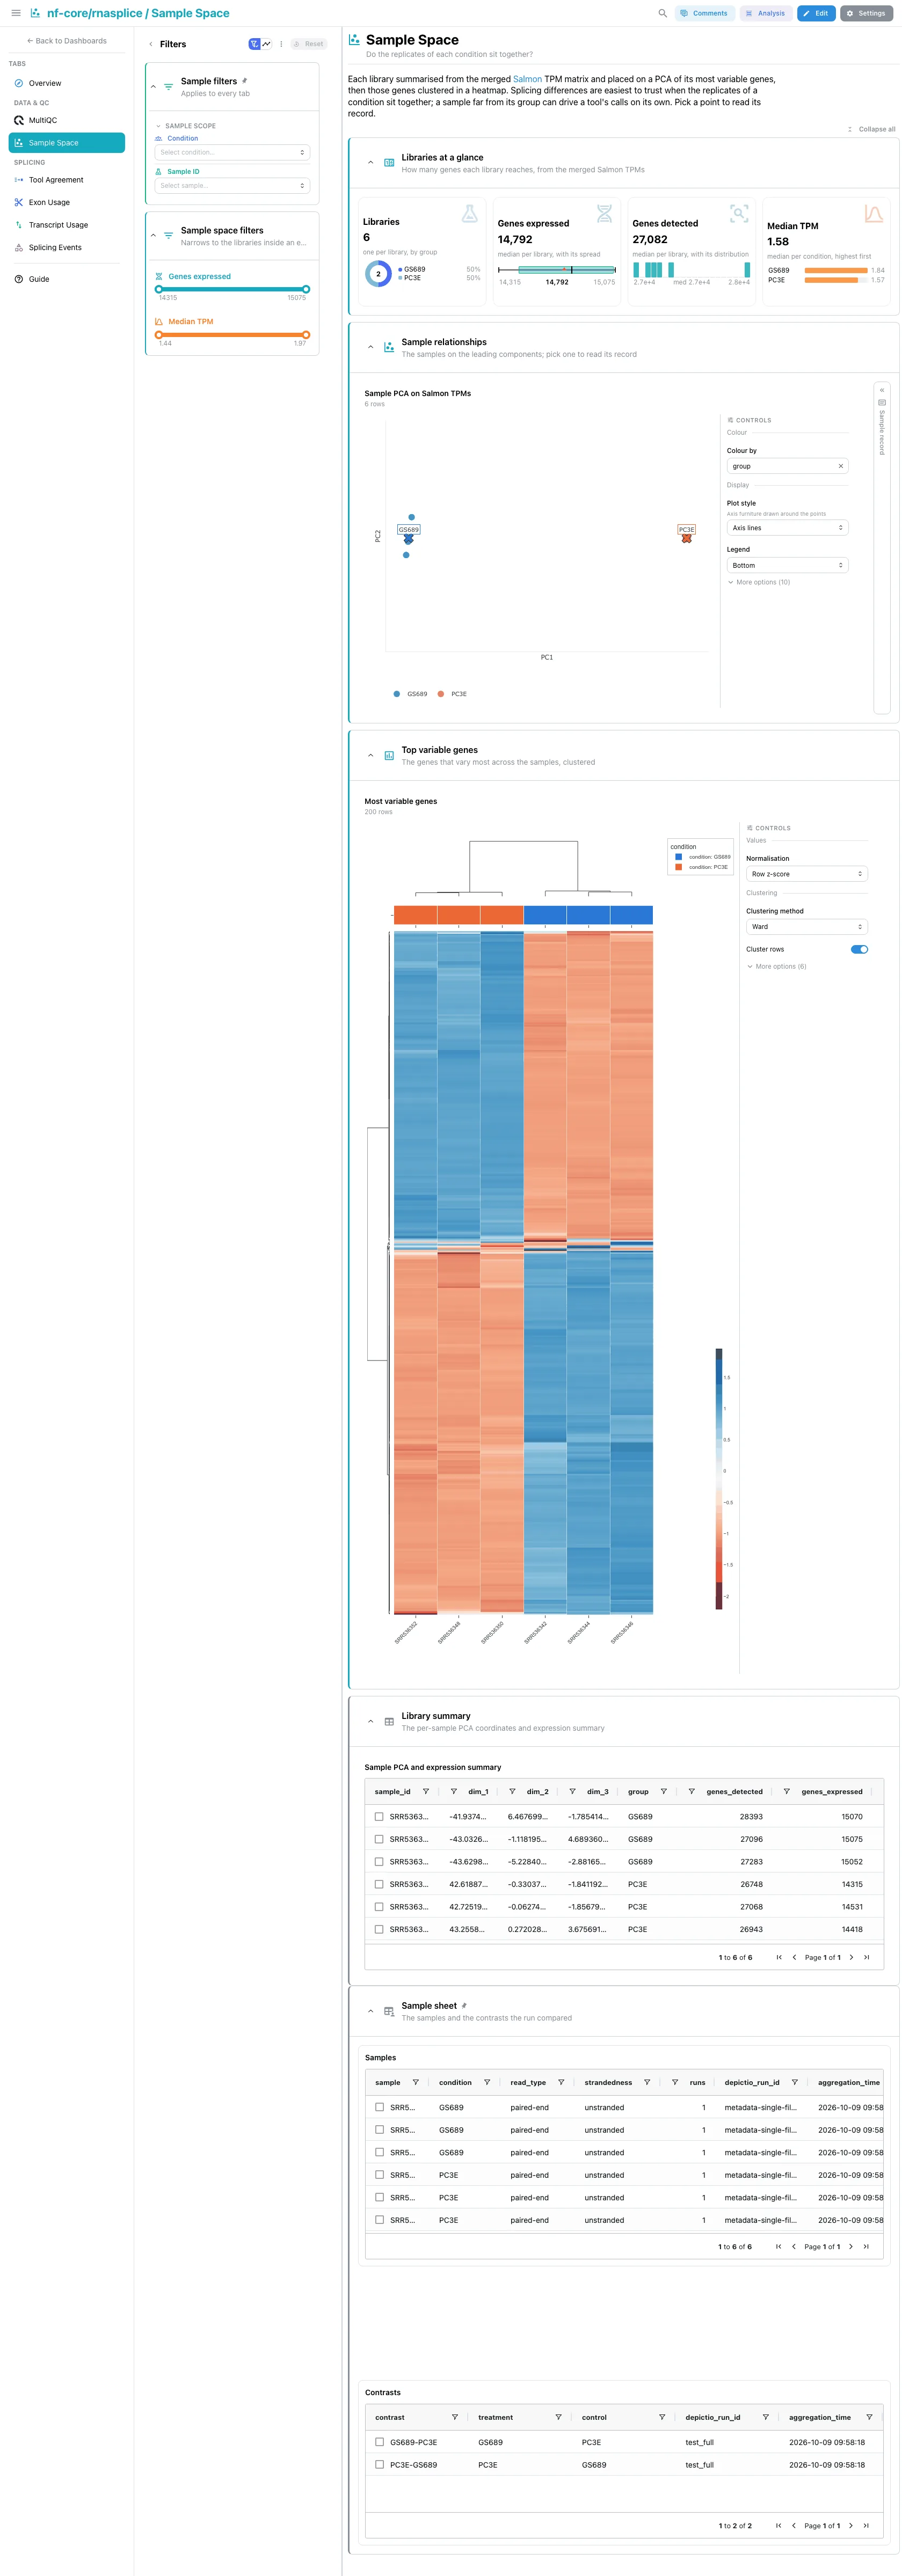
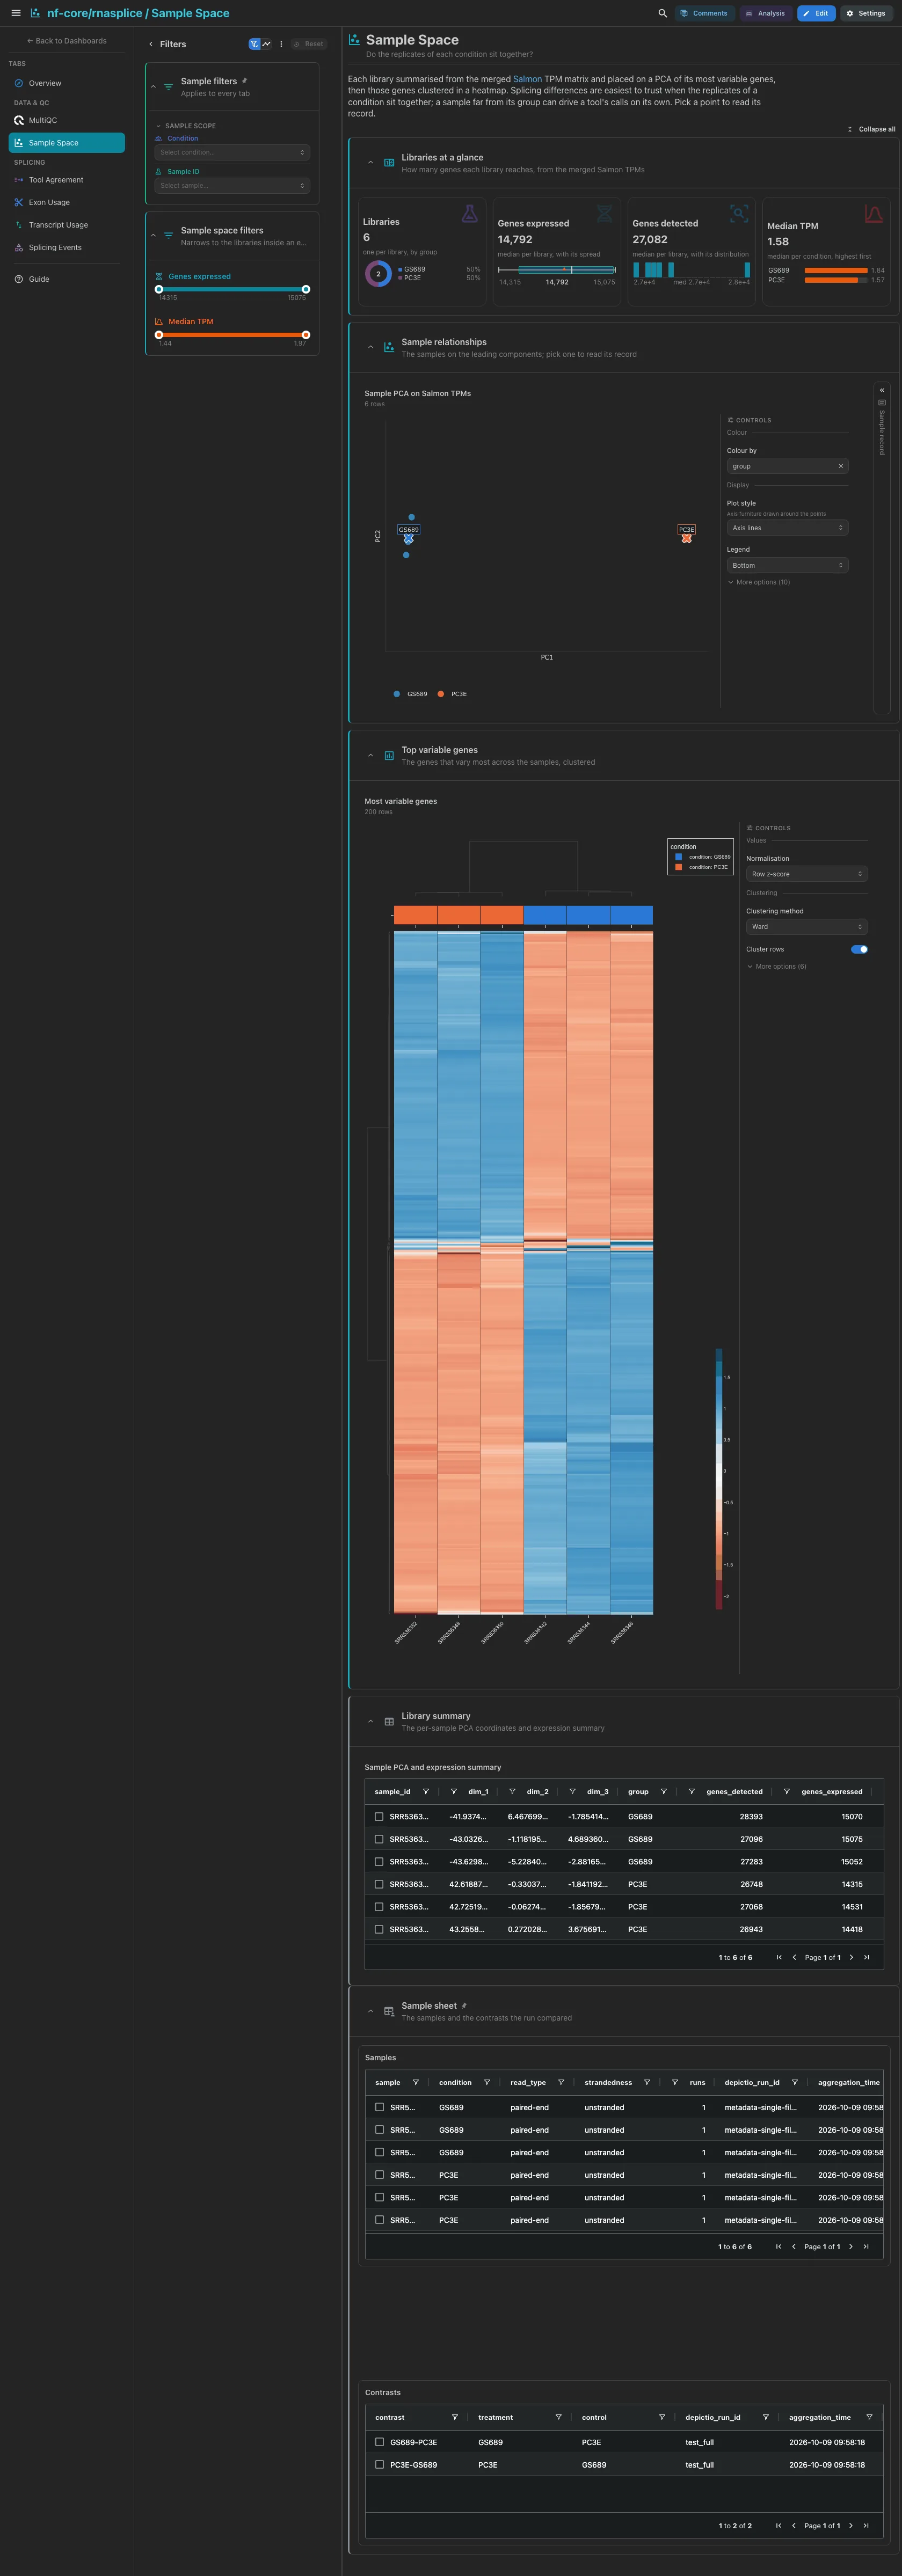
The libraries in the merged Salmon TPM matrix by group, the median genes expressed and detected per library, and the median TPM ranked by condition. Then the PCA on the TPMs, with a centroid per group, beside the sample record it fills on a pick, and the most variable genes as a clustered, row z-scored heatmap. Replicates of a condition should sit together: a sample far from its group can drive a tool's calls on its own. The per-sample summary table is collapsed.
Filters and components
Filters · Genes expressed and Median TPM ranges on sample_pca.
| Section | What it holds |
|---|---|
| Libraries at a glance | 4 cards |
| Sample relationships | 1 advanced visualization + a sample record card |
| Top variable genes | 1 advanced visualization |
| Library summary (collapsed) | Sample PCA and expression summary |
Splicing · Which genes does each tool call, and where do the tools agree?
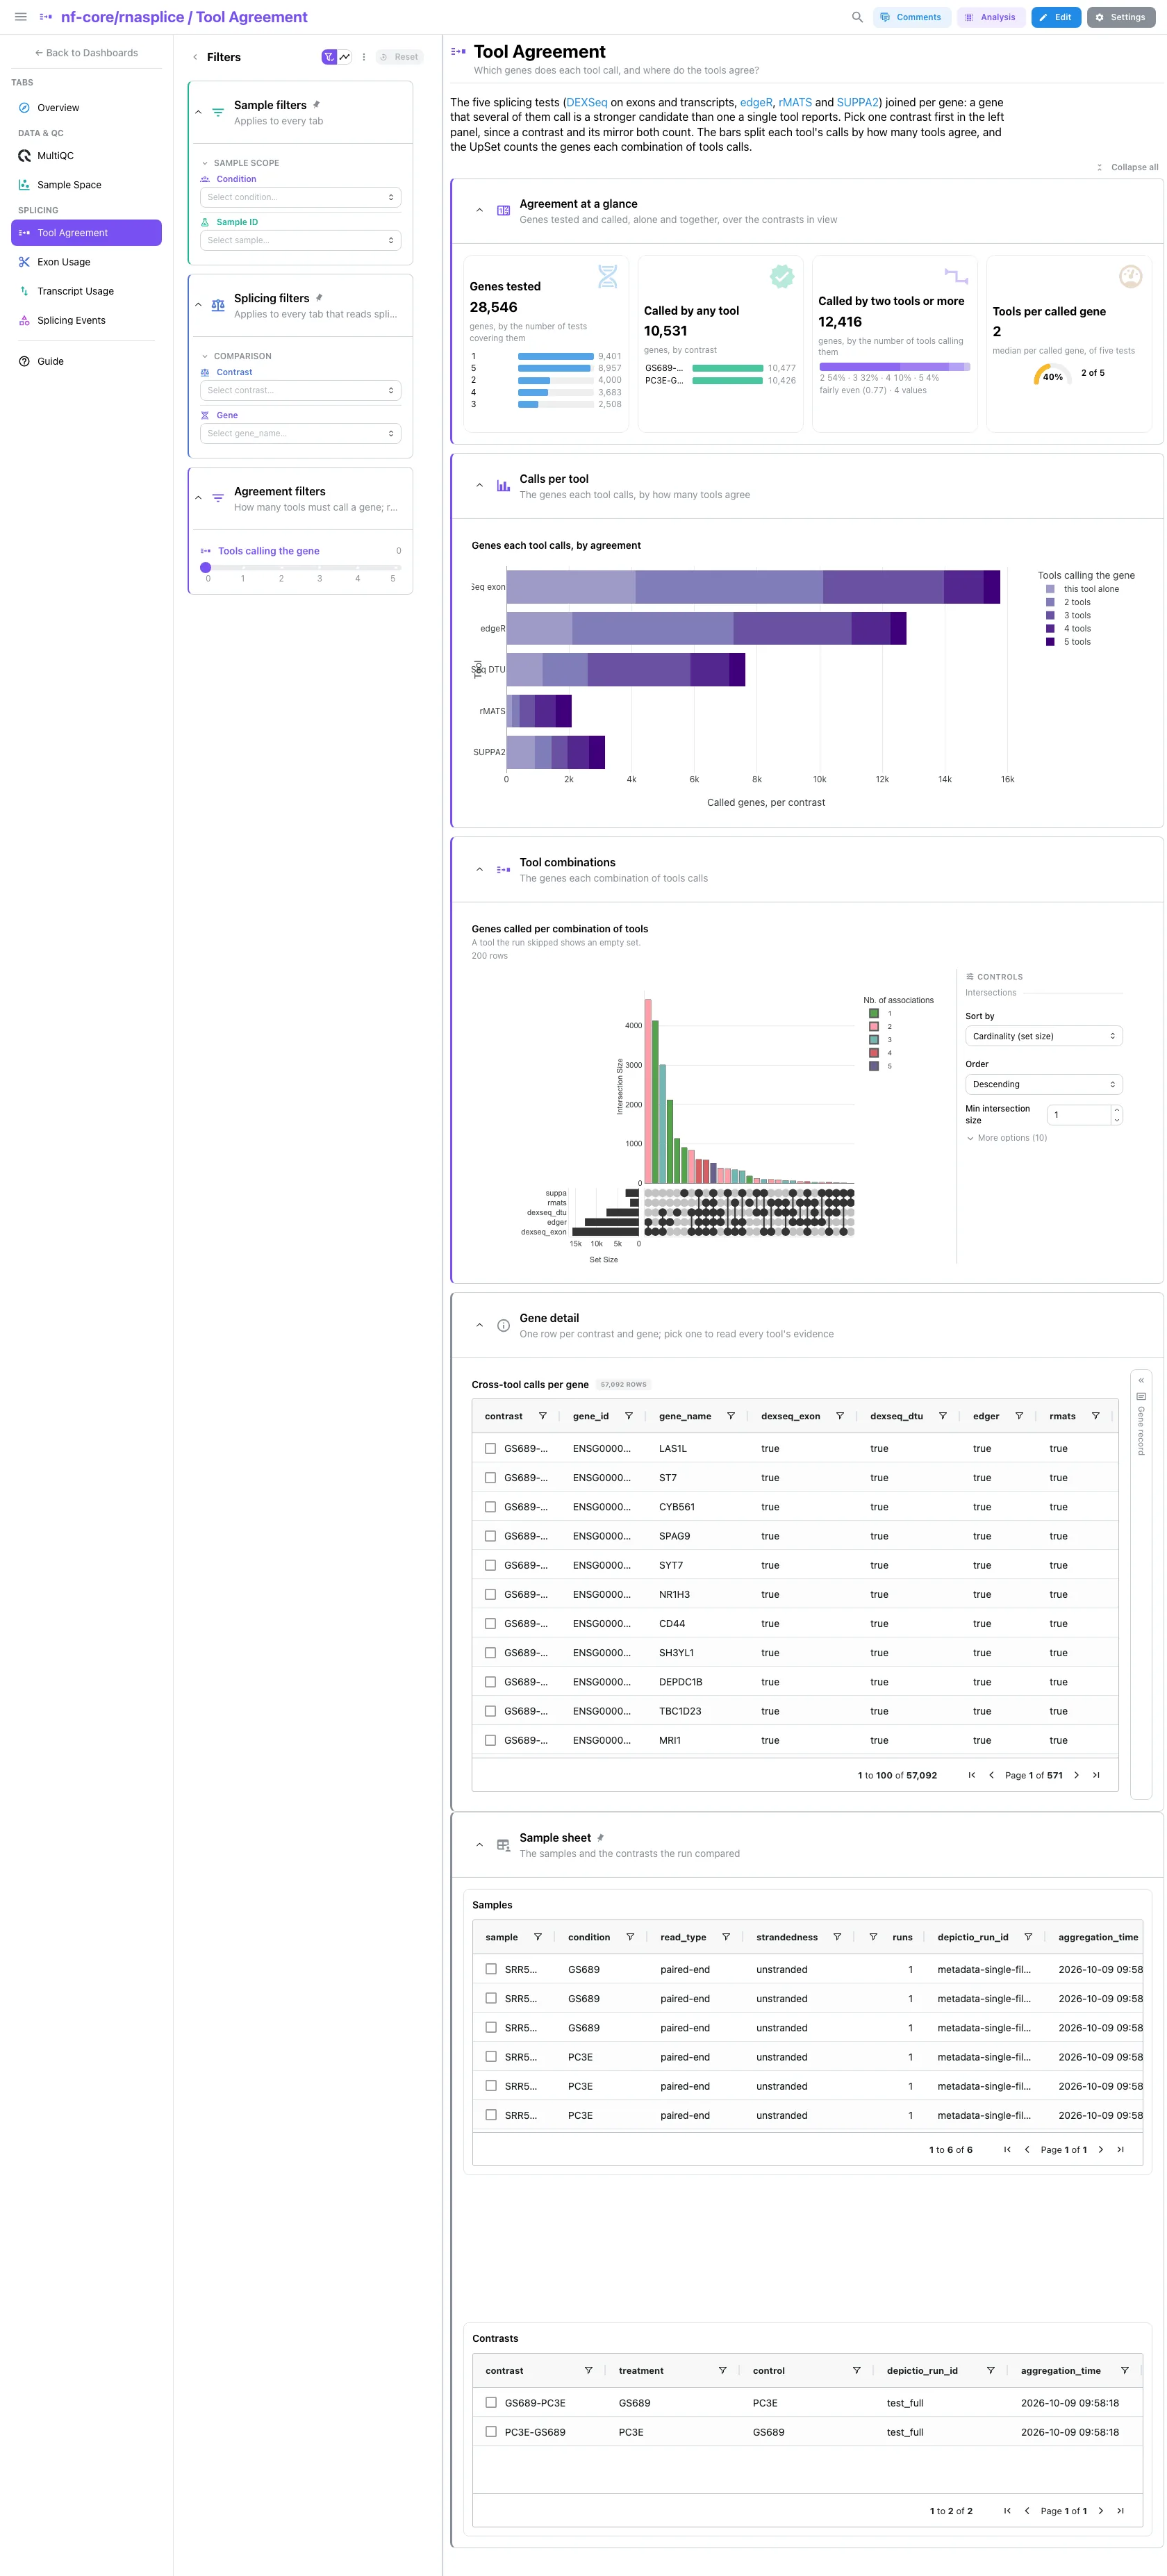
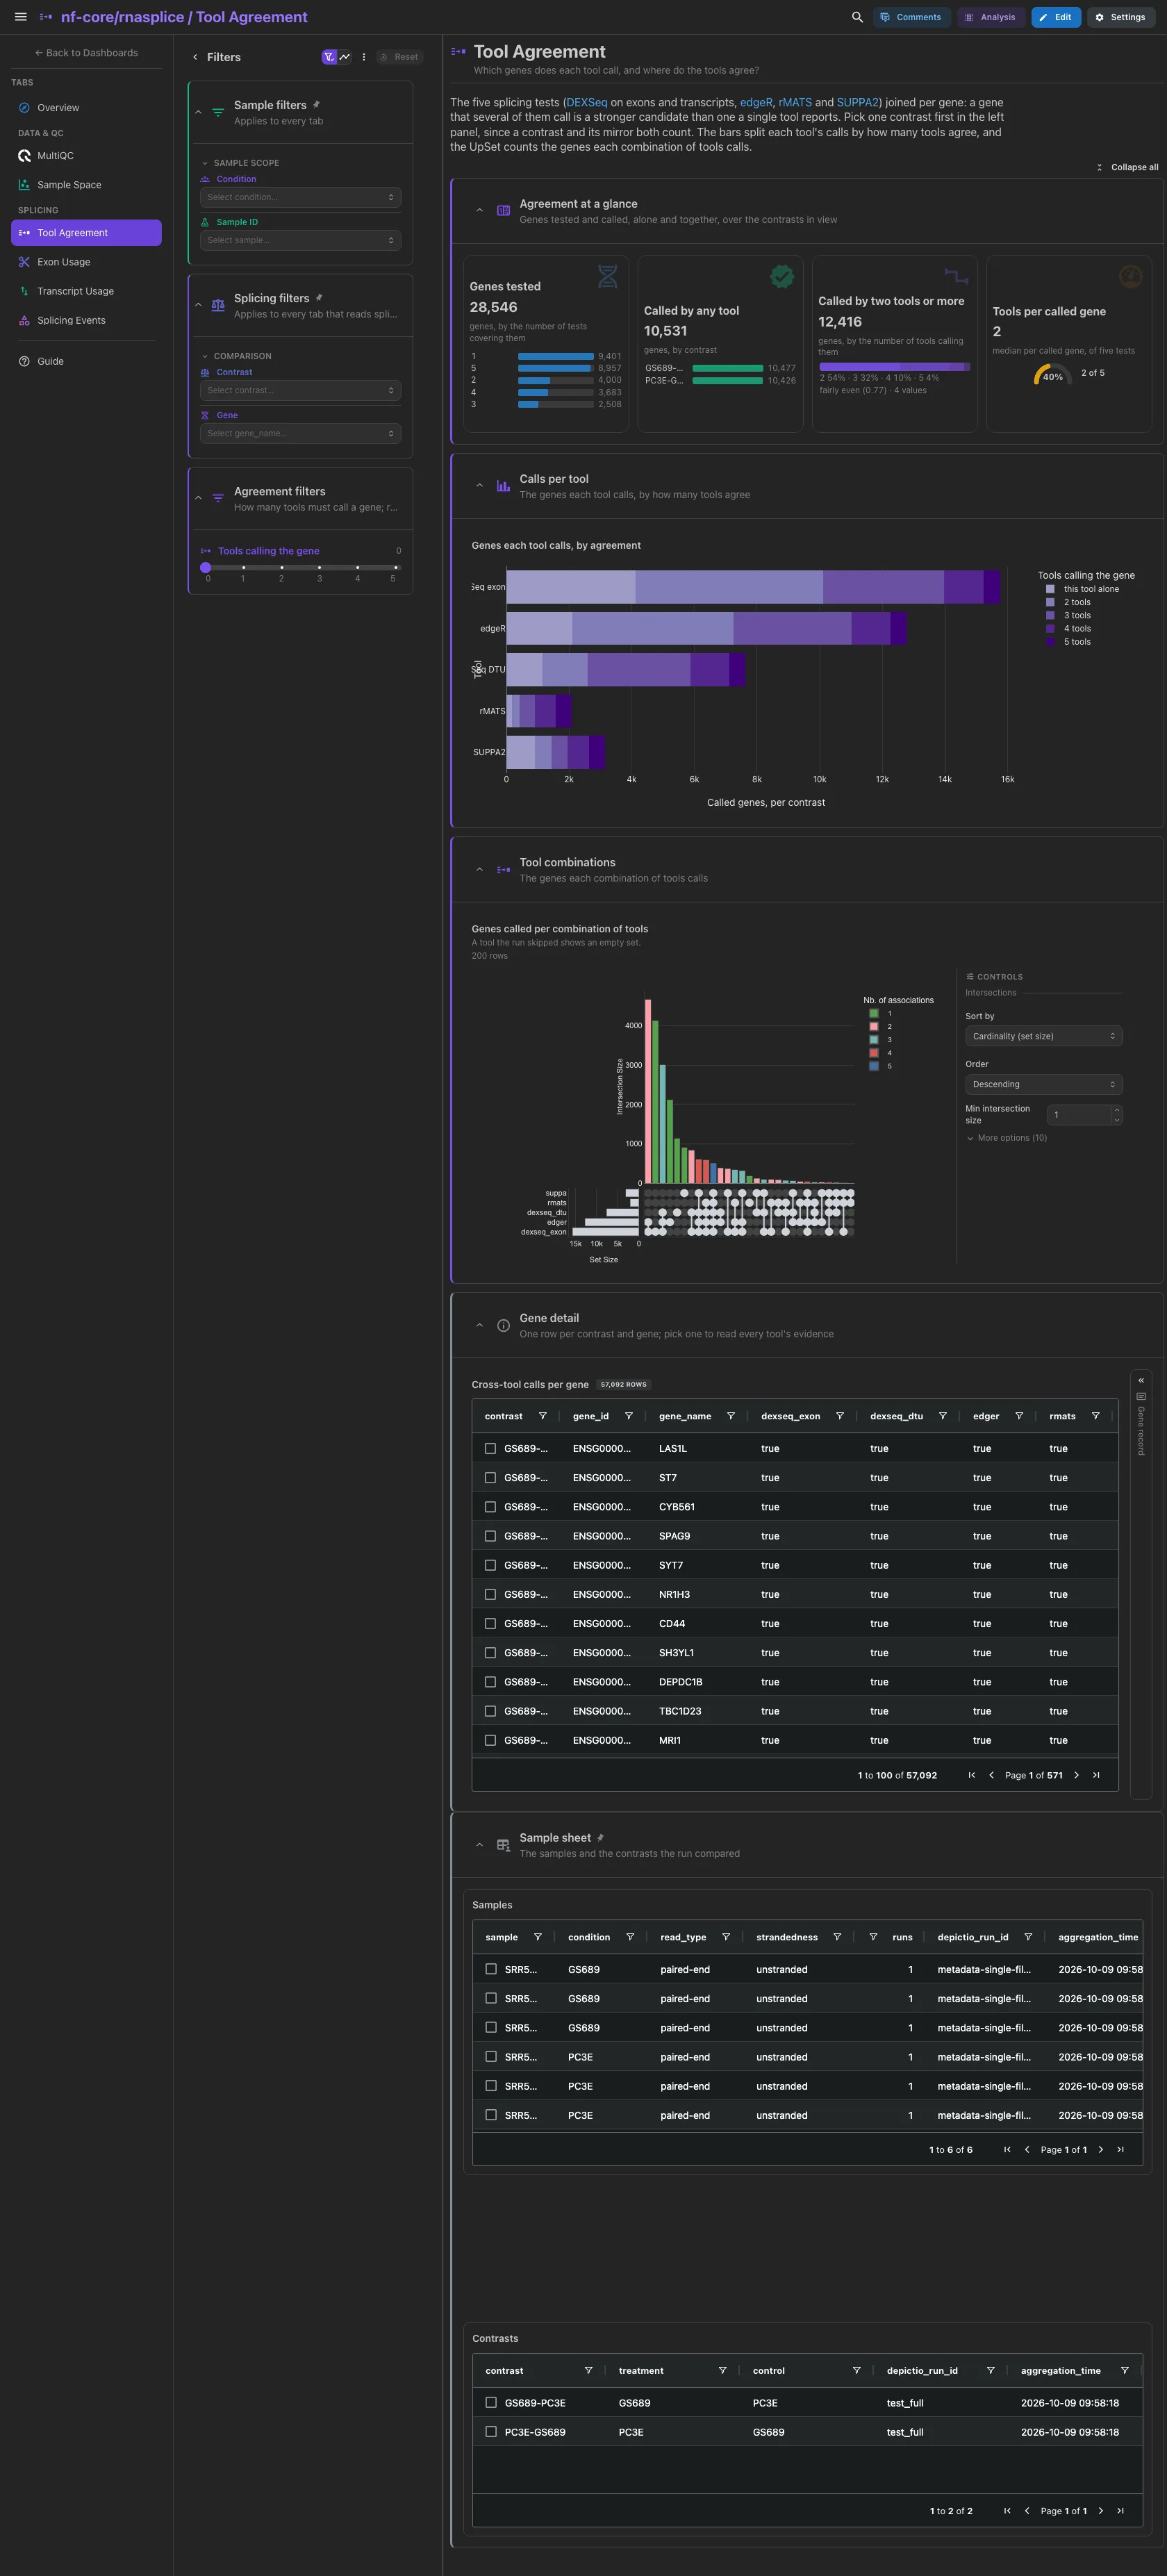
The five splicing tests joined per gene: a gene several of them call is a stronger candidate than one a single test reports. The genes tested, the genes called by any test (by contrast), the genes called by two or more, and the median number of tests calling a called gene on a 0 to 5 gauge. Then each test's calls as a bar, stacked by how many tests call the gene, and the UpSet of called genes across the five tests; a test the run skipped shows an empty set. The cross-tool table with the gene record card beside it (each test's call and strongest evidence, the gene id linked to Ensembl) is collapsed.
Filters and components
Filters · a Tools calling the gene slider on splicing_genes, which
reaches the per-tool tabs through the gene links.
| Section | What it holds |
|---|---|
| Agreement at a glance | 4 cards |
| Calls per tool | Genes each tool calls, by agreement |
| Tool combinations | 1 advanced visualization |
| Gene detail (collapsed) | Cross-tool calls per gene + a gene record card |
Splicing · Which genes use their exons differently, per DEXSeq and edgeR?
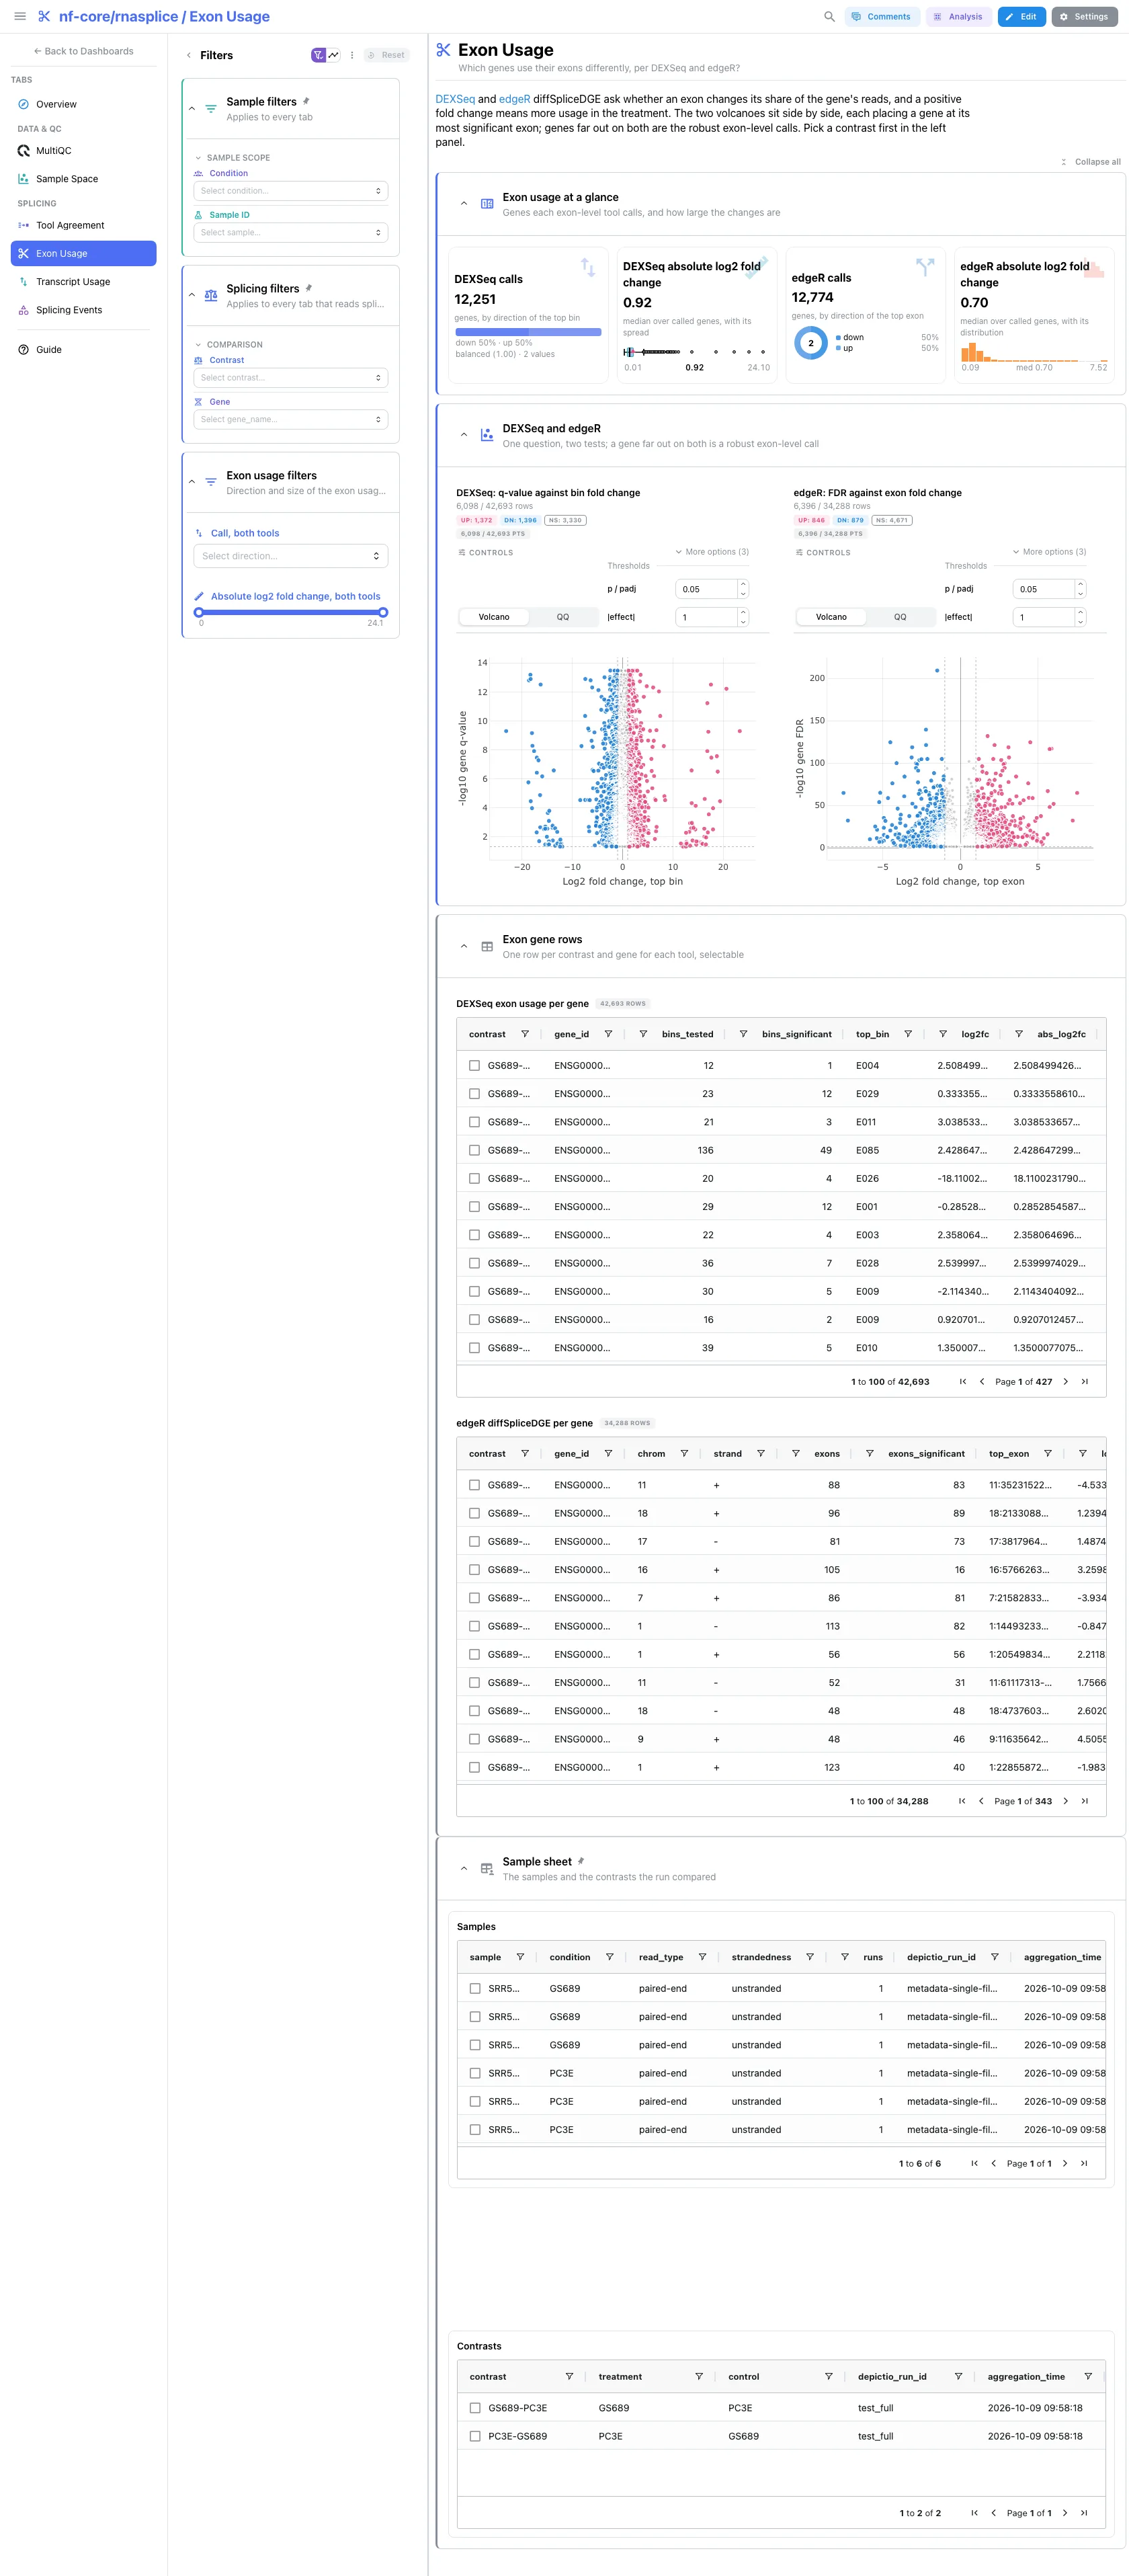
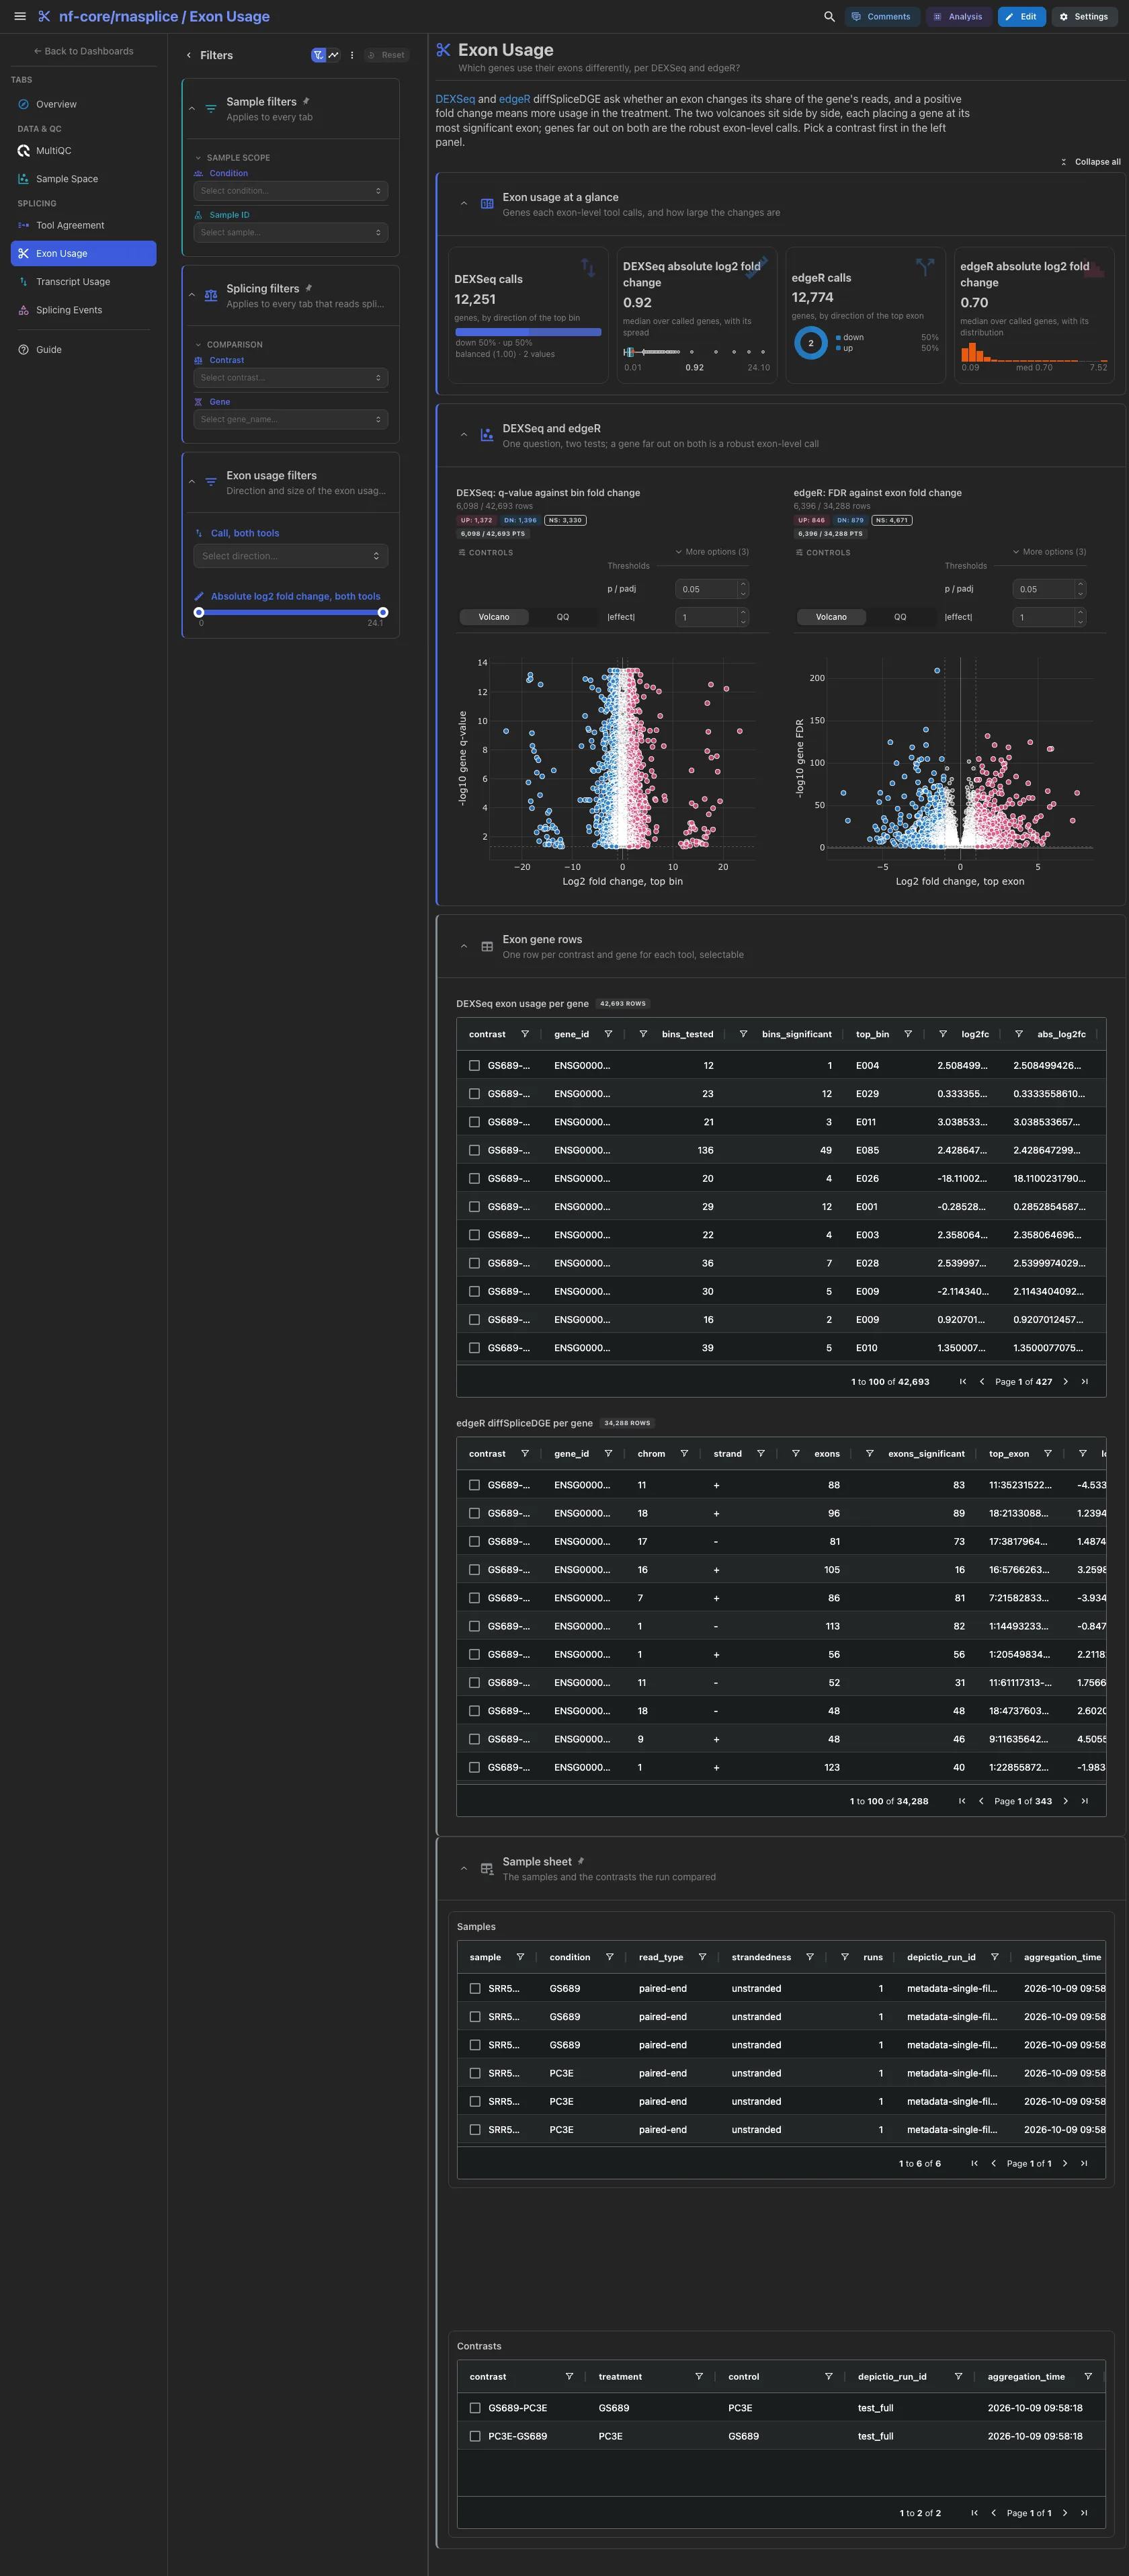
The DEXSeq calls by the direction of the gene's top bin, their absolute fold
change, the edgeR calls by direction and their absolute fold change. Then the
two gene volcanoes side by side in one section: the DEXSeq gene q-value
against the fold change of the most significant bin, and the edgeR
diffSpliceDGE gene F-test FDR against the fold change of the most
significant exon. Two tests of one question, so a gene far out on both is the
robust exon-level call. Both are unlabelled, since both name genes by id. The
two per-gene tables are collapsed.
Filters and components
Filters · Call, both tools on edger_genes and an Absolute log2
fold change, both tools range on dexseq_exon_genes. Each narrows both
tools, since a filter reaches every collection with its column.
| Section | What it holds |
|---|---|
| Exon usage at a glance | 4 cards |
| DEXSeq and edgeR | 2 advanced visualizations |
| Exon gene rows (collapsed) | DEXSeq exon usage per gene, edgeR diffSpliceDGE per gene |
Splicing · Which transcripts change their share of the gene, per DEXSeq DTU?
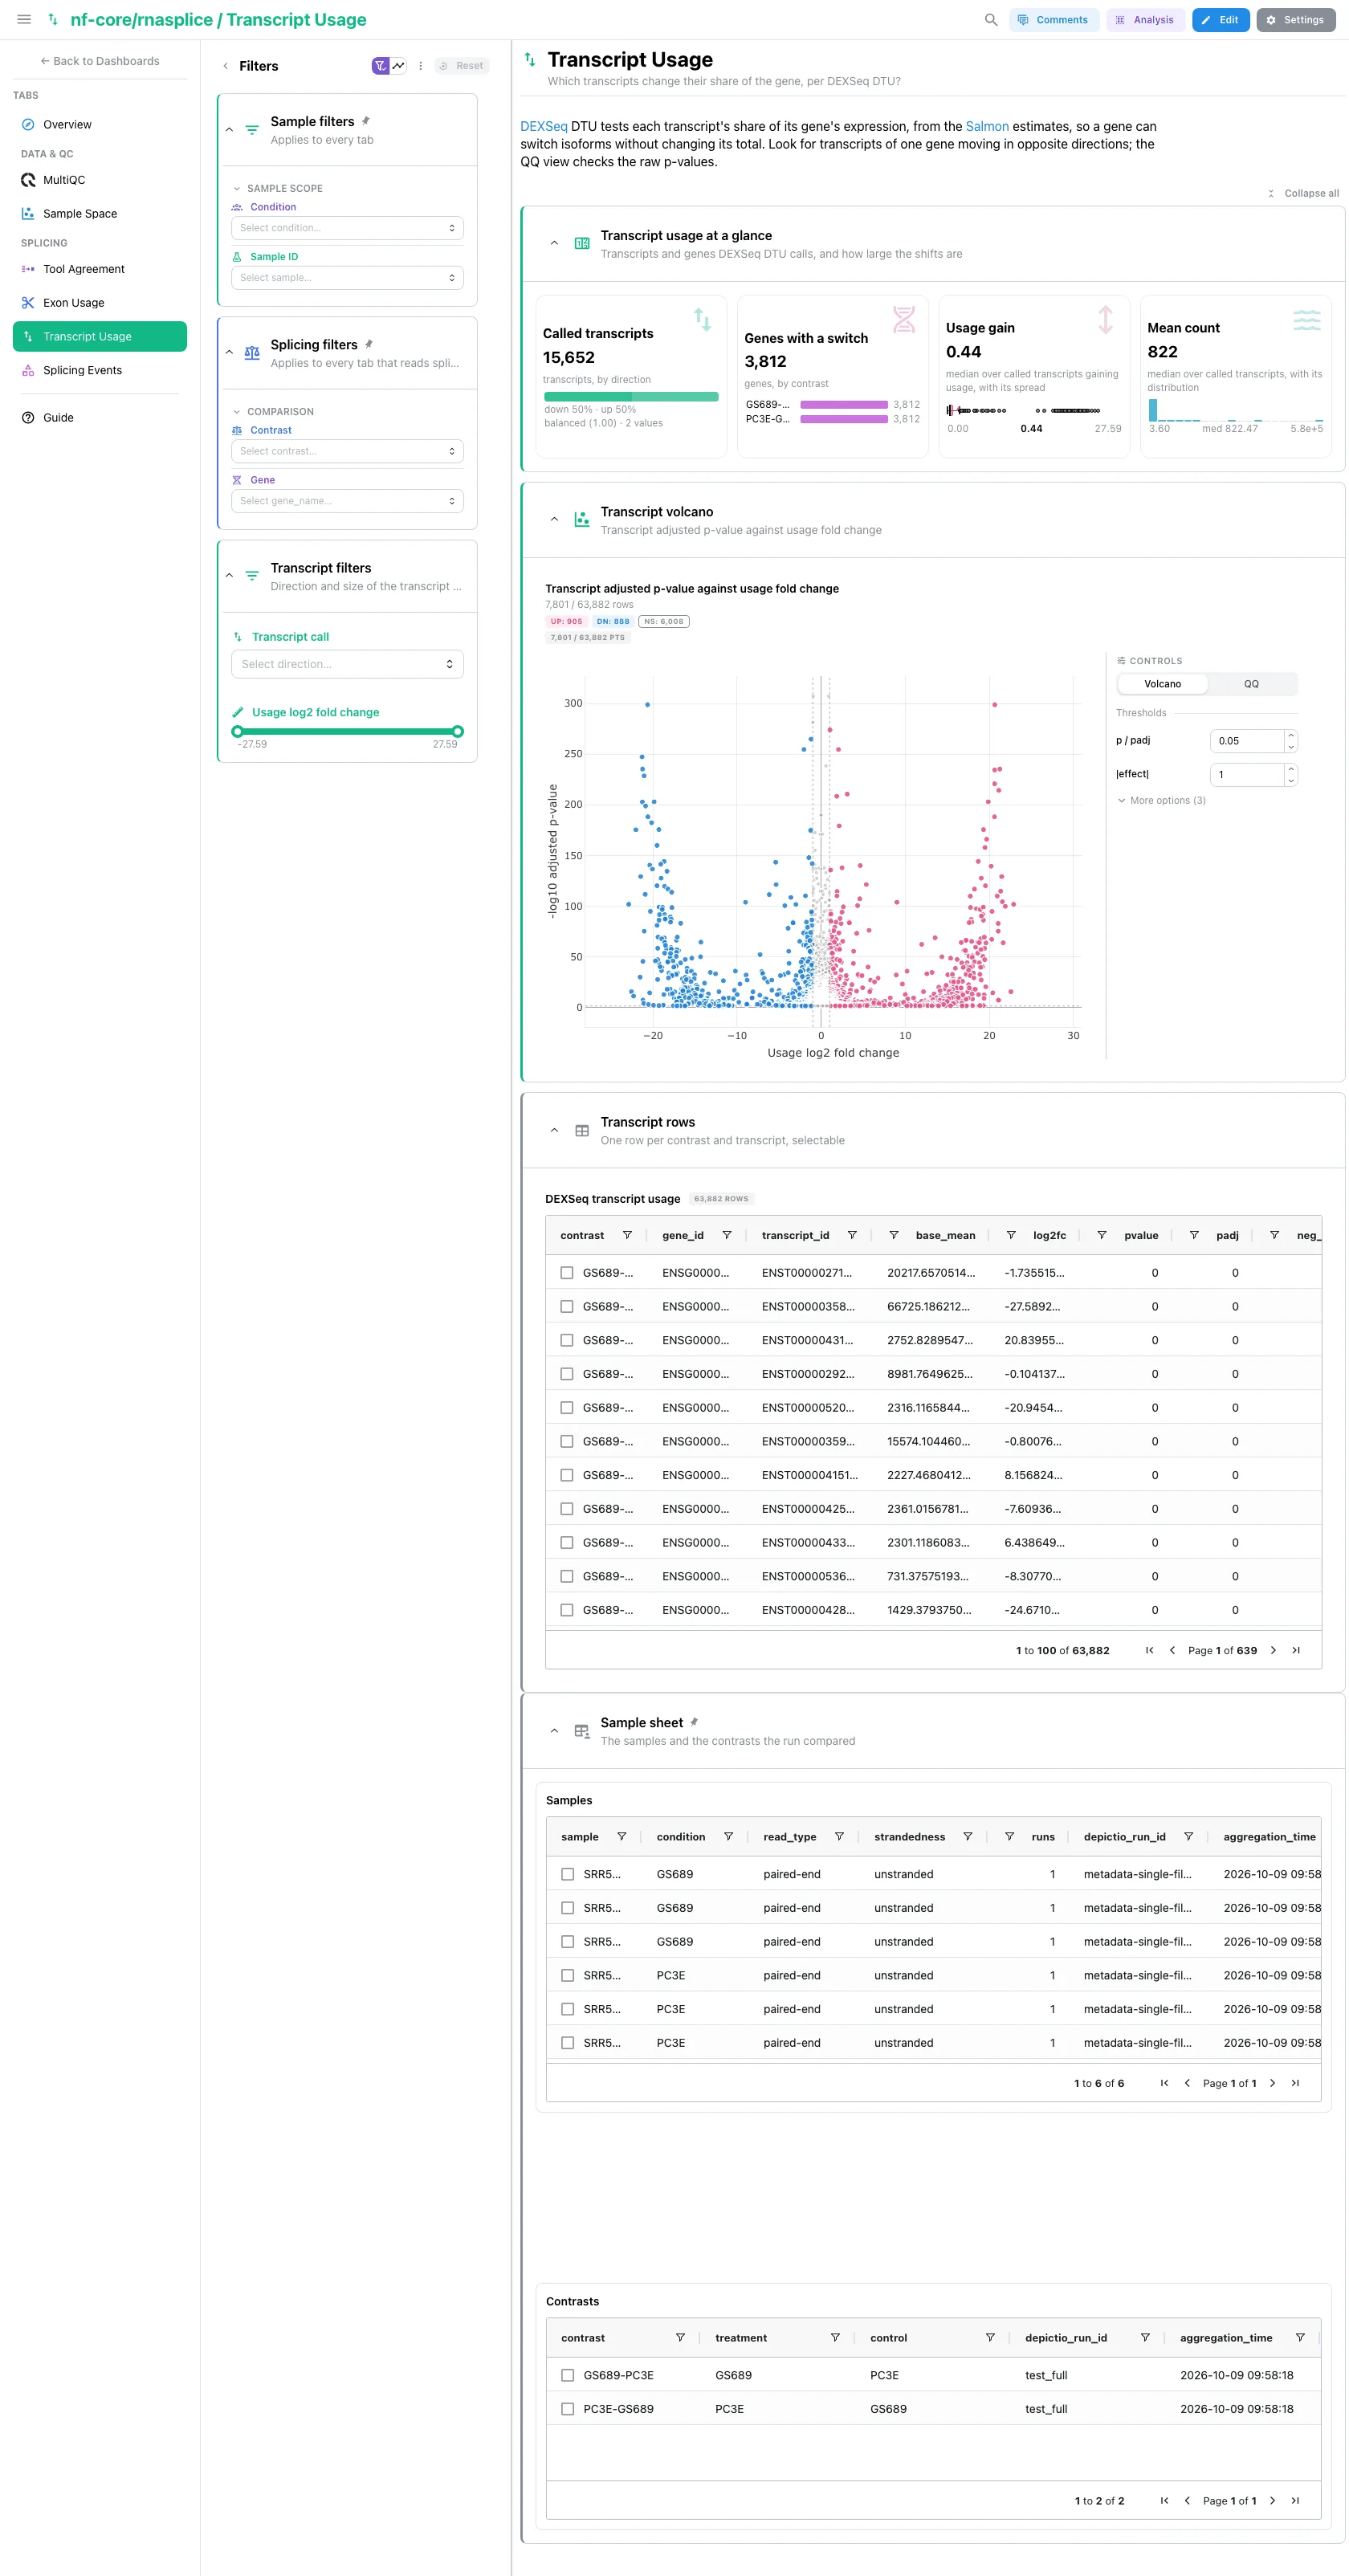
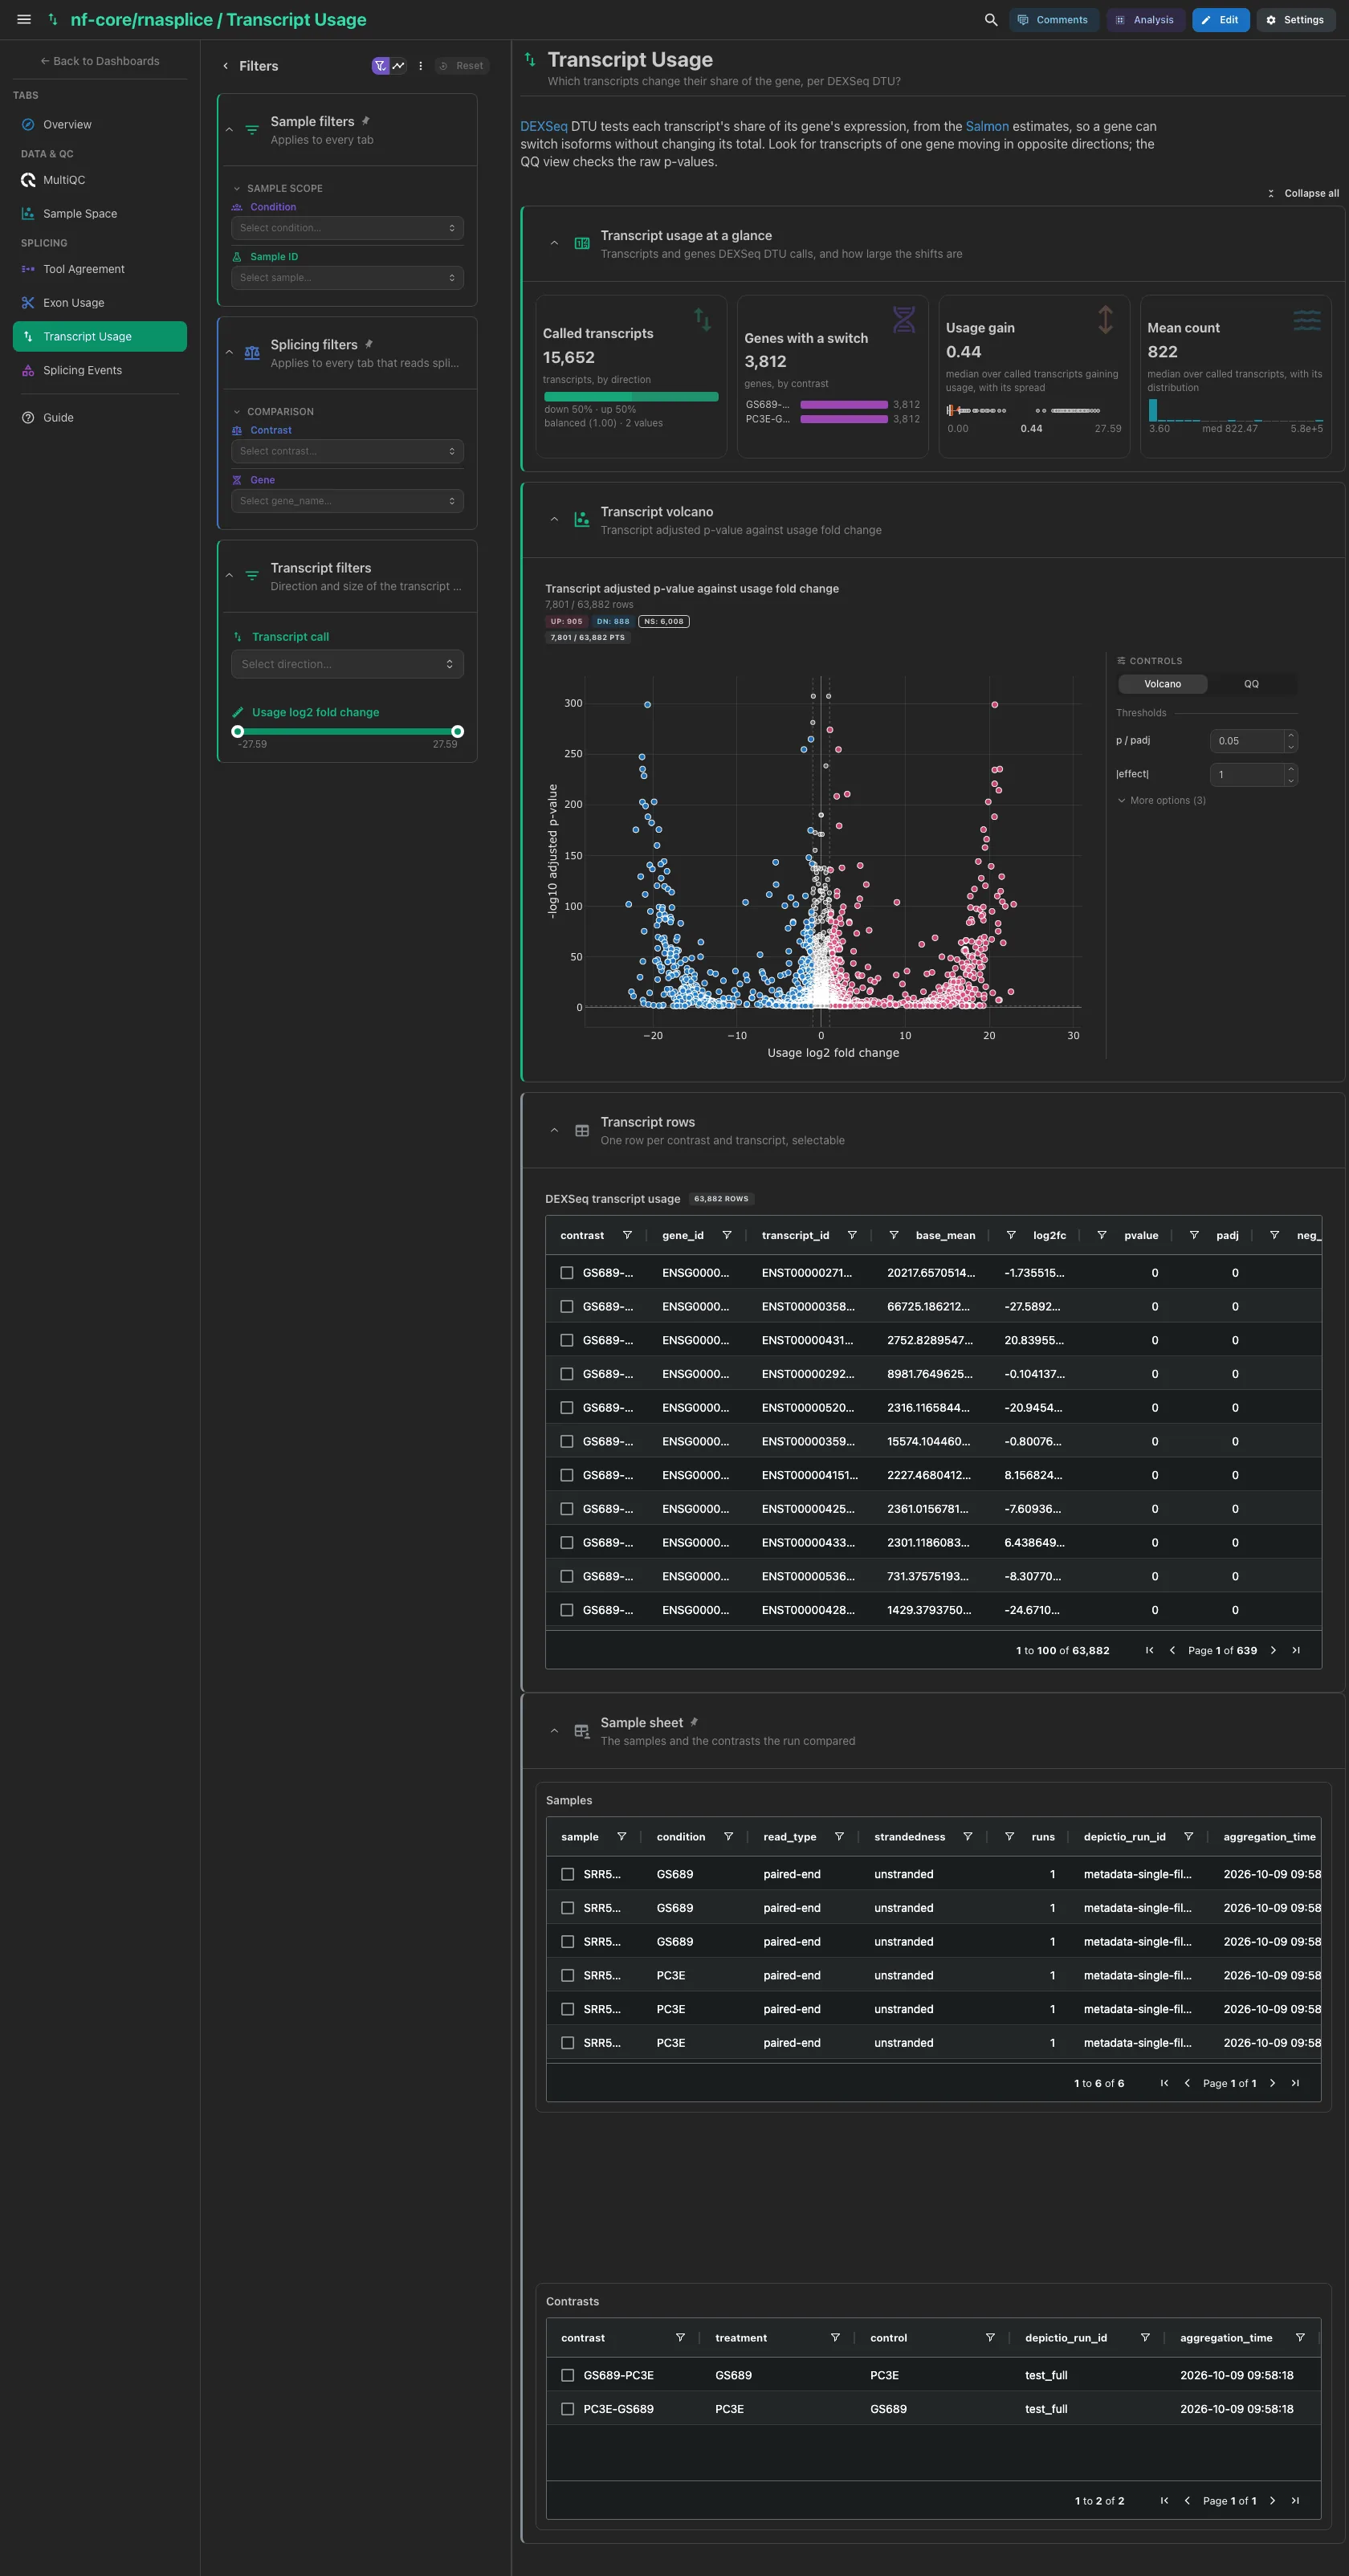
DEXSeq DTU tests each transcript's share of its gene on the Salmon estimates
of the chosen QUANT_ROUTE, so a gene can switch isoforms without changing
its total. The called transcripts by direction, the genes with a switch by
contrast, the usage gain of the called transcripts that rise (over both
directions the median sits at 0) and their mean count. Then the DTU volcano,
unlabelled, its View switch drawing a QQ plot of the raw p-values. Look for
transcripts of one gene moving in opposite directions. The transcript table
is collapsed.
Filters and components
Filters · Transcript call and a Usage log2 fold change range on
dexseq_dtu.
| Section | What it holds |
|---|---|
| Transcript usage at a glance | 4 cards |
| Transcript volcano | 1 advanced visualization |
| Transcript rows (collapsed) | DEXSeq transcript usage |
Splicing · Which event types change, and by how much inclusion?
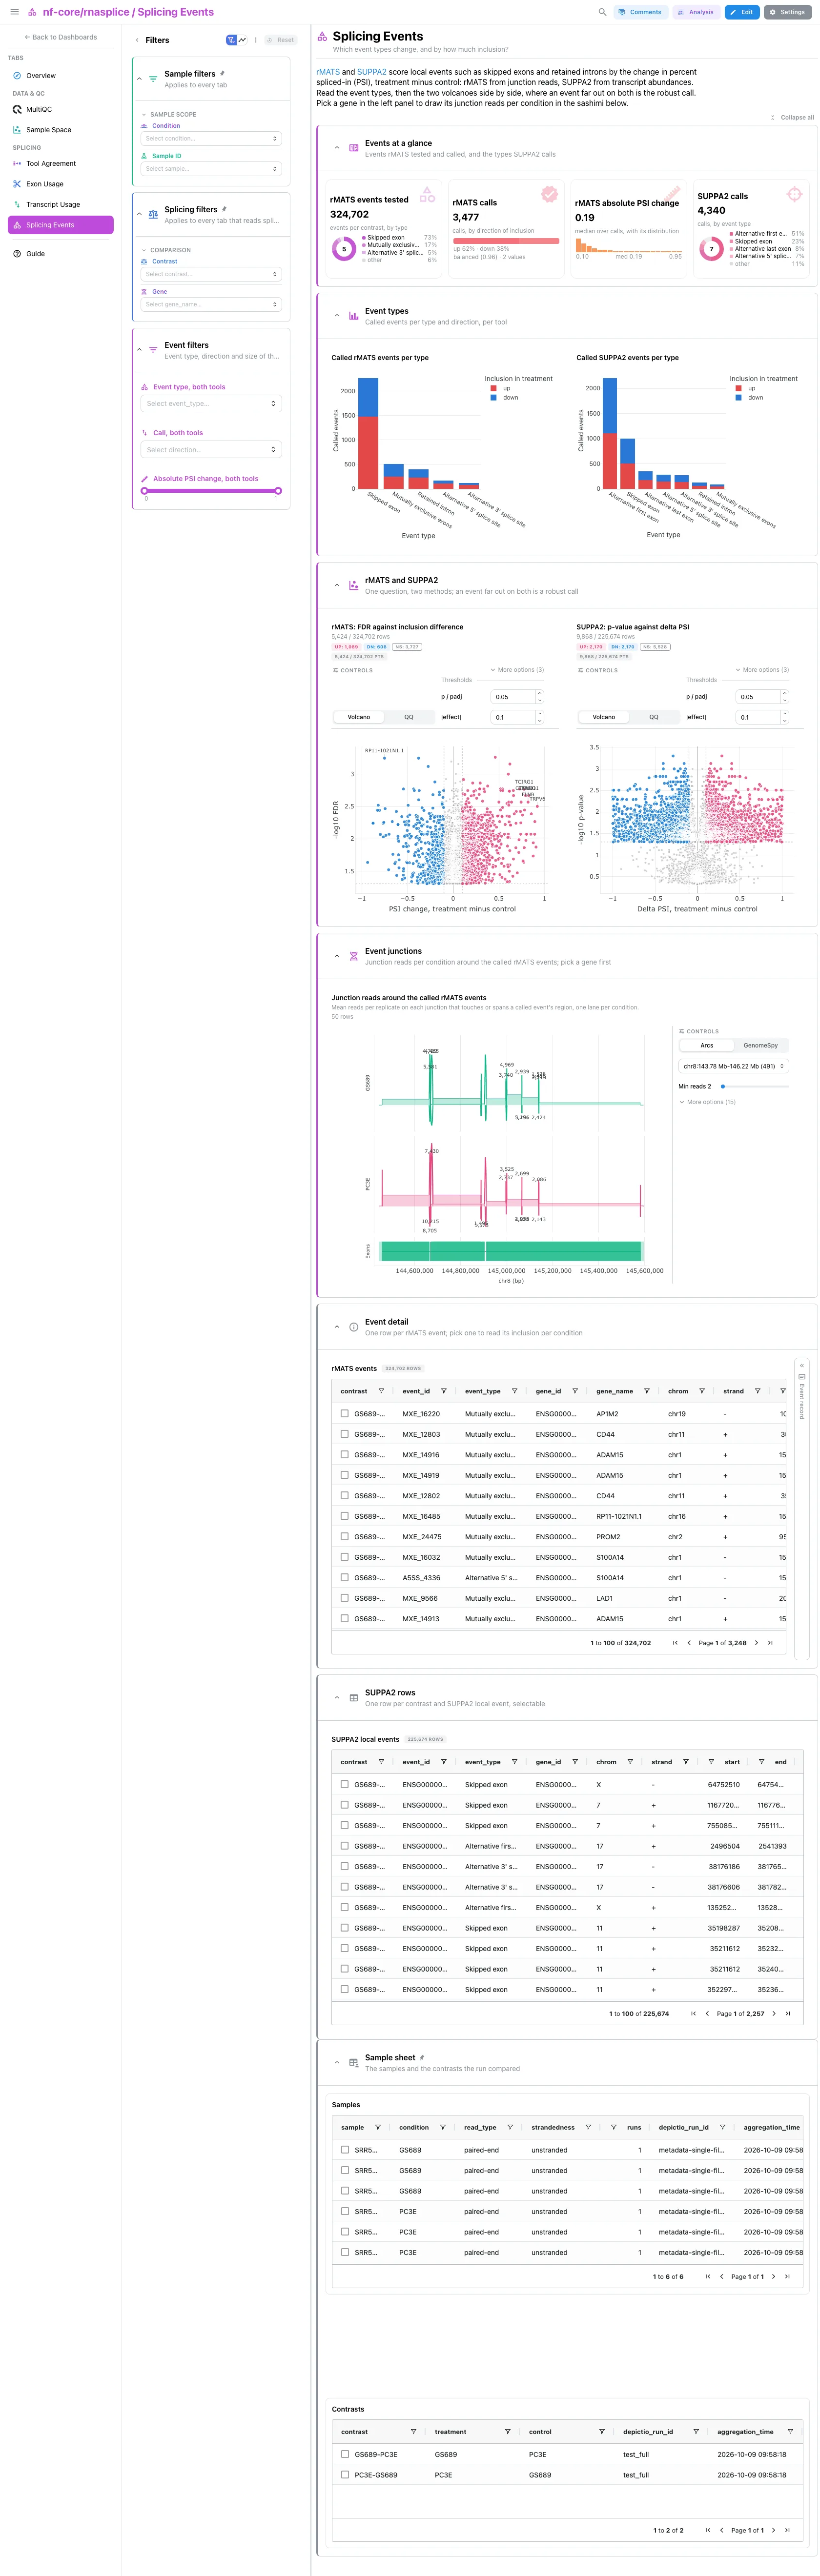
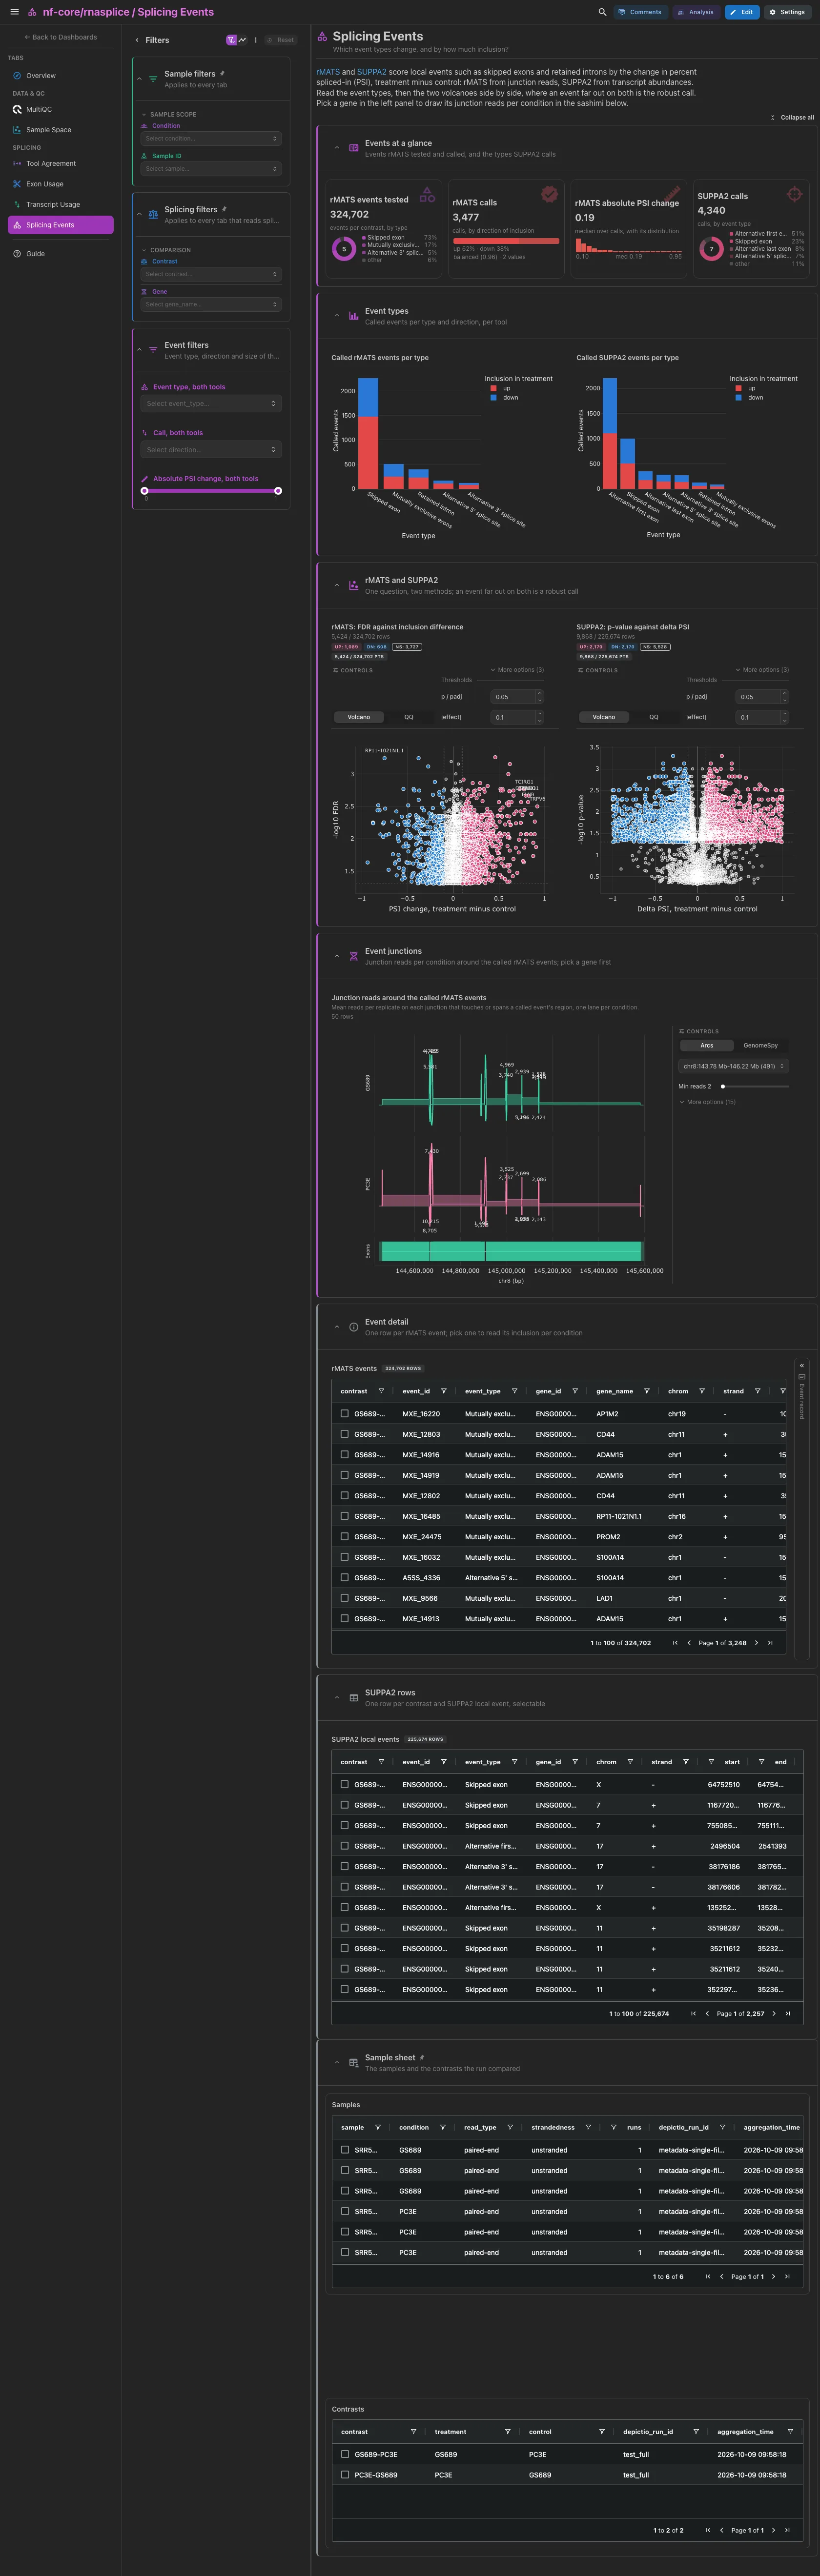
The rMATS events tested by type, the rMATS calls by direction of inclusion,
their absolute PSI change and the SUPPA2 calls by type. Then the called
events per type and direction for each tool, and the rMATS and SUPPA2
volcanoes side by side, each with a QQ view: one question, two methods
(junction reads against transcript abundances); only rMATS is labelled, with
gene symbols. Then a sashimi of the junctions around the called rMATS events,
one lane per condition: a gene picked in the left panel draws its locus,
otherwise it opens on the busiest cluster. The rMATS event table with its event record card (the locus linked to UCSC on
GENOME) and the SUPPA2 event table are collapsed.
Filters and components
Filters · Event type, both tools and an Absolute PSI change, both
tools range on suppa_events, and Call, both tools on
rmats_events. Each narrows both tools.
| Section | What it holds |
|---|---|
| Events at a glance | 4 cards |
| Event types | Called rMATS events per type, Called SUPPA2 events per type |
| rMATS and SUPPA2 | 2 advanced visualizations |
| Event junctions | 1 advanced visualization |
| Event detail (collapsed) | rMATS events + an event record card |
| SUPPA2 rows (collapsed) | SUPPA2 local events |
The sashimi needs rMATS and STAR
A run that skipped rMATS, or has no STAR junction tables (pseudo-alignment only), has no Event junctions section.
Tables select rows and the PCA selects points: the samples and contrasts tables
on sample and contrast, the sample summary and the PCA on sample_id, the
cross-tool, exon and transcript tables on gene_id, the rMATS and SUPPA2 event
tables on event_id. A pick narrows the other tiles of its collection and follows
the project links to the collections downstream of it. The three record cards
wait for a pick: the sample record reads the PCA, the gene record the cross-tool
table, the event record the rMATS table. The sashimi follows the Gene filter of
the left panel; an event picked in the rMATS table does not narrow it, since its
rows are per gene.
Running the pipeline
Depictio reads the output of nf-core/rnasplice, it does not run the
pipeline. Run the pipeline first, with a contrast sheet and the splicing tools
you want (each has its own switch: --dexseq_exon, --edger_exon,
--dexseq_dtu, --rmats, --suppa):
nextflow run nf-core/rnasplice -r 1.0.4 \
  --input samplesheet.csv \
  --contrasts contrastsheet.csv \
  --genome GRCh38 \
  --outdir results -profile docker
Then rebuild the MultiQC parquet and point Depictio at the results:
python -m depictio.dev_scripts.multiqc_reprocess --src results/ --dest results/multiqc/multiqc_data
depictio ingest results/ --template nf-core/rnasplice/latest --var GENOME=hg38
See nf-co.re/rnasplice/usage for full pipeline documentation.
Required data structure
Point depictio ingest at the directory holding the pipeline output. Depictio scans
recursively and matches on file name. <route> is star_salmon or salmon, the
value of QUANT_ROUTE.
<DATA_ROOT>/
├── pipeline_info/
│   ├── samplesheet.valid.csv                  # the hub: sample and condition
│   └── params_*.json
├── contrastsheet/contrastsheet.valid.csv      # contrast, treatment, control
├── multiqc/multiqc_data/
│   └── multiqc.parquet                        # rebuilt with multiqc_reprocess
├── <route>/
│   ├── tximport/salmon.merged.gene_tpm.tsv    # sample PCA and heatmap
│   ├── dexseq_dtu/results/dexseq/{DEXSeqResults,perGeneQValue}.*.tsv
│   └── suppa/diffsplice/per_local_event/*_local_diffsplice.dpsi
└── star_salmon/                               # alignment-based tools
    ├── dexseq_exon/results/{DEXSeqResults,perGeneQValue}.*.csv
    ├── edger/contrast_*.usage.*.csv
    ├── rmats/*/rmats_post/*.MATS.JCEC.txt
    └── log/*.SJ.out.tab                       # STAR junctions, the Splicing Events sashimi
METADATA_FILE is optional: a TSV or CSV with the sample id in the first column
and one column per design factor, whose first annotation column then becomes
GROUP_COL. The MultiQC reprocess also needs the FastQC zips, Trim Galore
reports, STAR logs, samtools stats, featureCounts summaries and Salmon folders
of the run.
Validation runs
The AWS megatest prefix for rnasplice is a truncated sync with no splicing
output, so the template was validated on an EMBL cluster run of the release's
test_full profile instead: six samples in two conditions, a contrast and its
mirror, both quantification routes and all five splicing tools enabled, aligned
to GRCh37 (hence GENOME=hg19 for the UCSC links). The screenshots above come
from that run, with the design table vendored under input/metadata.tsv.
megatest.yaml has no pinned results_sha and lists the tables-only subset of
a run the template needs, so a usable S3 run can be pinned later without
rewriting it. Until then the download script resolves the latest published
prefix, which holds no splicing tables: to reproduce the full dashboard, run the
test_full profile yourself, then rebuild the parquet and ingest with the
vendored design table:
python -m depictio.dev_scripts.multiqc_reprocess --src <outdir> --dest <outdir>/multiqc/multiqc_data
depictio ingest <outdir> --template nf-core/rnasplice/latest \
  --var METADATA_FILE=depictio/projects/nf-core/rnasplice/1.0.4/input/metadata.tsv \
  --var GENOME=hg19
Do not pass --project when ingesting: the dashboard is attached to the
project by name, so renaming it breaks a later depictio dashboard import.
Re-ingesting accumulates dashboards, so delete the project before repeating a run.
Additional resources
- nf-co.re/rnasplice: official pipeline documentation
- nf-co.re/rnasplice/1.0.4/results: AWS test results (truncated for this release)
- Template System Reference: YAML format, variables, conditionals
- Recipes: how to read, test, and write recipes
Authorship
 weber8thomas
Reviewing a template on your own data, or taking over a role here, is a contribution in itself: the contributing guide says what each one involves.